infomesh
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 6 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
🕸️ Fully decentralized P2P search engine for LLMs — no API key, no billing, forever free. MCP-native web search via Kademlia DHT + libp2p + FTS5. Production stable ✅ → pip install infomesh

InfoMesh
Fully Decentralized P2P Search Engine for LLMs
No credit card. No hosted API key required. No per-query fees.







Quick Start • Why InfoMesh • Features • What's New • Architecture • Security • Credits • Contributing • Docs
[!TIP]
P2P Bootstrap Configuration
InfoMesh currently bundles one bootstrap node in Azure East US. With the optionalp2pdependencies installed, your node attempts to connect on startup; availability and reachability are not guaranteed. To add more peers manually:infomesh peer add /ip4/<IP>/tcp/4001/p2p/<PEER_ID> infomesh peer test
💡 Why InfoMesh?
The Problem
Every AI assistant needs real-time web access — but that access is gated behind expensive, proprietary search APIs:
| Type | Typical Cost | Limitation |
|---|---|---|
| LLM-bundled web search | Hidden in token cost | Locked to one vendor's API, no standalone access |
| Custom search API | ~$3–5 / 1,000 queries | API key + billing account required, rate-limited |
| AI search SaaS | ~$0.01–0.05 / query | SaaS dependency, monthly usage caps |
| Search scraping proxy | ~$50+/month | Fragile, breaks on upstream changes |
| InfoMesh | $0 in software/query fees | You provide hardware and connectivity; crawl and resource limits apply |
This creates a paywall barrier for independent AI developers, open-source assistants, and researchers. Small projects and local LLMs simply cannot afford real-time web search.
The prices above are illustrative examples, not current provider quotations. Actual pricing, free tiers, logging policies, and limits vary by provider and deployment.
The Solution
I started building AI agents and quickly hit a wall: there was no free web search API.
Every provider wanted a credit card, a billing account, or a monthly subscription — just to let an AI agent look something up on the web. That felt wrong.
So I built InfoMesh — a decentralized search engine where the community is the infrastructure:
- No central server — every participant is both a crawler and a search node.
- No per-query cost — contribute crawling, earn search credits. The more you give, the more you can search.
- No vendor lock-in — standard MCP protocol integration, works offline with your local index.
- No central query collection — local-only queries stay on your node; distributed search sends the query to participating peers. Local diagnostics may include query text.
InfoMesh does not compete with existing commercial search providers. Those companies serve human search at massive scale with ads-based monetization. InfoMesh provides minimal, sufficient search capabilities for AI assistants — for free, via MCP — democratizing real-time web access without per-query billing.
I just wanted my AI agent to search the web without reaching for my wallet. If you've felt the same way, InfoMesh is for you.
🆓 Free. Every Interface. No Exceptions.
| How you use it | Cost | Example |
|---|---|---|
| MCP (AI assistants) | Free | Claude, VS Code Copilot, any MCP client calls search() — zero API fees |
| CLI (terminal) | Free | uv run infomesh search "python asyncio" — local results and available peers; latency depends on the workload |
| Python package (code) | Free | from infomesh.index.local_store import LocalStore — embed search in your app |
| Local API (HTTP) | Free | curl localhost:8080/search?q=... — REST endpoint when the local admin API is running |
No hosted API key or billing account is required. Operators may enable API-key authentication; crawl rates, credit accounting, and resource limits still apply. There are no rate limits tied to dollar payments.
You run a node, you contribute to the network, and search is free — forever.
InfoMesh vs Other Web Search MCP Servers
Looking for a free web search MCP server? Here's how InfoMesh compares to common alternatives:
| Feature | InfoMesh | API-based MCP servers | Scraper-based MCP servers | Meta-search engines |
|---|---|---|---|---|
| Free tier | No per-query billing; credit/resource limits apply | Limited (1,000–2,000/mo typical) | Unlimited (no API) | Unlimited |
| API key | Optional operator-configured authentication | ✅ Required (signup needed) | ❌ Not required | ❌ Not required |
| Decentralized | ✅ Fully P2P | ❌ Centralized | ❌ Centralized | ❌ Single instance |
| Offline search | ✅ Local index works offline | ❌ | ❌ | ❌ |
| Privacy | Local-only queries stay local; distributed queries contact peers | ⚠️ Logged by provider | Varies | ✅ Self-hosted |
| Self-hosted | ✅ You own everything | ❌ | ❌ | ✅ Docker required |
| Crawl your own URLs | ✅ crawl_url() tool |
❌ | ❌ | ❌ |
| Full page fetch | ✅ fetch_page() tool |
Varies | ❌ | ❌ |
| Install | pip install infomesh |
Varies | Varies | Docker Compose |
| Open source | ✅ MIT | Varies | Varies | Varies |
InfoMesh combines decentralized peer search, offline local search, no required hosted API key, and crawling/indexing of your own content without per-query billing.
🔐 Safe by Design — Layered Defenses for Your Node
Most search engines ask you to trust them. InfoMesh asks you to trust math.
There is no central InfoMesh query-collection server. Local-only searches stay on your machine; distributed searches send queries to peers, and network participation can publish or replicate indexed content. Local sessions, analytics, and diagnostic logs may retain information, so self-hosting is not a guarantee of zero query retention.
Contribute to the network → earn credits → search without per-query fees, subject to resource and crawl limits.
That's the entire deal. No catch.
How InfoMesh Layers Its Security
| 🔑 | Ed25519 Cryptographic Identity | Nodes use Ed25519 keys. Signed v2 exchanges bind the signer to the libp2p peer identity; legacy v1 compatibility is not authenticated v2 traffic. Credit entry signing is optional. Key rotation is available through infomesh keys rotate; protect private keys and distinguish application keys from the transport identity. |
| 🔏 | Signed Content Attestation | Published source attestations bind SHA-256(raw_response) and SHA-256(extracted_text) to a signing identity. Verification detects changes to the signed evidence; it does not establish the truth of the source page. Local-only crawling does not guarantee network publication. |
| 🌳 | Merkle Tree Integrity | Merkle membership proofs verify document hashes against a particular root. Altered evidence fails verification against that root; a valid proof does not establish source truth or guarantee that every peer stores the entire index. |
| 🔍 | Random Audits | Replica/source audit maintenance runs approximately hourly, subject to available peers and evidence. Replica corruption can produce a trust failure; changed web content is inconclusive, not automatic proof of cheating. Three recorded consecutive audit failures trigger isolation. |
| 🛡️ | Sybil Attack Defense | Local Proof-of-Work generation and subnet admission limits raise participation costs. Generation time depends on hardware and randomness; these mechanisms do not guarantee prevention of mass identities. The default subnet limit is 3 nodes per /24 admission bucket. |
| 🌐 | Eclipse Attack Defense | Bootstrap discovery, peer exchange, and subnet limits help diversify connectivity. At least 3 independent reachable bootstrap peers is a deployment goal, not a bundled guarantee: the current node list contains one peer. These defenses do not eliminate eclipse attacks. |
| 🚫 | DHT Poisoning Defense | Per-keyword publication limits (10/hr/node), signed new publications, and content-hash checks constrain ingress. Legacy unsigned read hints remain unverified, and a valid signature does not establish content truth. |
| 🔒 | Encrypted Transport | libp2p Noise transport protects peer traffic in transit. Receiving peers still process query text and results; transport encryption is not anonymity or protection from a compromised endpoint. |
| 🕵️ | No Central Query Logging | DHT discovery uses keyword keys, but peer search requests include the original query. Local sessions and diagnostics can retain query information, and remote peer logging is outside your control. Use local-only search when queries must not be sent to peers. |
| 🧮 | Credit Proof Verification | Entries recorded with a signing key can be included in verifiable Merkle proofs; unsigned entries do not acquire this guarantee. Farming detection and a 24hr probation policy help identify abuse but do not make self-reported contribution infallible. |
Unified Trust Score
Every peer earns a continuously updated trust score based on behavior, not identity:
Trust = 0.15 × uptime + 0.25 × contribution + 0.40 × audit_pass_rate + 0.20 × summary_quality
| Tier | Score | What Happens |
|---|---|---|
| 🟢 Trusted | ≥ 0.8 | Highest trust grade; search cost is determined separately by contribution tier |
| 🔵 Normal | 0.5 – 0.8 | Standard operation |
| 🟡 Suspect | 0.3 – 0.5 | Low trust grade; inspect audit evidence and isolation state |
| 🔴 Untrusted | < 0.3 | Network isolation after 3× consecutive failures |
Compliance Built In
| Regulation | How InfoMesh Handles It |
|---|---|
| robots.txt | Strictly enforced — no exceptions, automatic blocklist |
| DMCA | Authorized signed notices with durable exclusion and peer relays; no delivery deadline is guaranteed for unreachable peers |
| GDPR | Distributed deletion records, right-to-be-forgotten support |
| Copyright | Full text stored as cache only; search returns snippets with attribution |
Bottom line: InfoMesh uses cryptography, audits, and contribution incentives to reduce reliance on a central provider. Local-only search keeps queries local; peer search and publication share data with other nodes. There are no per-query fees, but operating limits and trust assumptions still apply.
🚀 Quick Start
Install & Run (Two Steps — No Git Required)
All you need is a Linux terminal (Ubuntu, Debian, etc.).
No prior Python or developer experience required.
Step 1 — Install uv (Python package manager, one-time setup):
curl -LsSf https://astral.sh/uv/install.sh | sh
After this finishes, close and reopen your terminal (or run source ~/.bashrc).
This ensures the uv and uvx commands are available.
Step 2 — Run InfoMesh:
uvx infomesh status
uvx automatically downloads and runs InfoMesh — no git clone, no pip install, and no manually managed virtual environment. InfoMesh requires Python 3.12+.
The first run downloads dependencies; subsequent runs reuse the cached tool environment.
Try It Out
# Crawl a webpage and index it
uvx infomesh crawl https://docs.python.org/3/library/asyncio.html --depth 0

# Search locally, and peers when P2P dependencies are available
uvx infomesh search "asyncio"

# View the node dashboard (works over SSH too)
uvx infomesh dashboard --text
--depth 0 limits this example to one page; omitting it follows links according to the crawl configuration (unlimited depth by default). The base package does not include P2P. After installing the native prerequisites, use uvx --from 'infomesh[p2p]' infomesh search "asyncio" for peer search. An empty local index needs a successful crawl or import before it can return local results.
Install Permanently (Optional)
If you use InfoMesh regularly, install it as a persistent tool so you don't need the uvx prefix:
uv tool install infomesh

# Now run directly:
infomesh status
infomesh crawl https://example.com
infomesh search "example"
infomesh dashboard --text
Connect to Your AI Assistant (MCP)
Add InfoMesh as an MCP server in VS Code (Copilot), Claude Desktop, Cursor, or Windsurf — no hosted API key is required by default. Operators can enable authentication with INFOMESH_API_KEY.
Claude Desktop / Cursor / Windsurf use the following mcpServers format:
{
  "mcpServers": {
    "infomesh": {
      "command": "uvx",
      "args": ["infomesh", "mcp"]
    }
  }
}
VS Code (Copilot) uses a servers root in .vscode/mcp.json instead:
{
  "servers": {
    "infomesh": {
      "type": "stdio",
      "command": "uvx",
      "args": ["infomesh", "mcp"]
    }
  }
}
Your AI assistant can now crawl and search your local index via MCP without per-query billing. To enable peer search, prepare the P2P prerequisites and replace args with ["--from", "infomesh[p2p]", "infomesh", "mcp"]. The base examples above do not install P2P dependencies.
From Source (Contributors / Developers)
If you want to contribute code or run from source:
System Prerequisites
The P2P optional dependency (libp2p) includes C extensions (fastecdsa, coincurve, pynacl) that may require native build tools. These are needed for P2P installs such as uv tool install 'infomesh[p2p]' and for the repository's development dependencies, which also include libp2p.
Linux (Debian / Ubuntu):
sudo apt-get update && sudo apt-get install -y build-essential python3-dev libgmp-dev
macOS:
brew install gmp
# Xcode Command Line Tools must also be installed
Windows: Use WSL2 (recommended) or install Visual Studio Build Tools + GMP.
Note: The base package (
uv tool install infomesh, oruv sync --no-devfrom source) does not need P2P build dependencies. Plainuv syncincludes thedevgroup by default, so this repository's normal contributor setup does need them.
Clone & Run
# Clone and install with dev dependencies
git clone https://github.com/dotnetpower/infomesh.git
cd infomesh
uv sync

# Start InfoMesh with the TUI dashboard
uv run infomesh start

# Or run headless (servers / CI)
uv run infomesh start --no-dashboard
Docker
docker build -t infomesh .
docker run -d --name infomesh \
  -p 4001:4001 -p 8080:8080 \
  -v infomesh-data:/data \
  infomesh
Verify It Works
# Search your local index and peers
uvx infomesh search "python asyncio tutorial"

# Check node status
uvx infomesh status

# Crawl a specific URL on demand
uvx infomesh crawl https://docs.python.org/3/

# Export your index as a portable snapshot
uvx infomesh index export backup.zst
Examples
Ready-to-run Python scripts are available in the examples/ directory:
# Local search
uv run python examples/basic_search.py "python tutorial"

# Crawl → index → search pipeline
uv run python examples/crawl_and_search.py https://docs.python.org/3/

# Programmatic MCP client
uv run python examples/mcp_client.py "async programming"
See examples/README.md for the full list.
✨ Features
Core Capabilities
| Feature | Description |
|---|---|
| 🌐 Fully Decentralized | No central server. Every node is both a hub and a participant — cooperative tit-for-tat architecture |
| 🤖 LLM-First Design | Pure text API via MCP, optimized for AI consumption. No browser UI needed |
| 🔍 Dual Search | Keyword search (SQLite FTS5 + BM25) and optional semantic vector search (ChromaDB) |
| 🕷️ Smart Crawler | Async crawling with robots.txt compliance, politeness delays, and 3-layer deduplication |
| 📡 P2P Network | libp2p-based with Kademlia DHT, mDNS local discovery, and encrypted transport |
| 💾 Offline-Capable | Your local index works without internet — search your crawled knowledge anytime |
| 🏆 Credit Incentives | Earn credits by crawling and serving peers. More contribution = more search quota |
| 🔐 Content Integrity | SHA-256 content hashes, Ed25519 source attestations, random audits, and Merkle proof support |
| 🤏 zstd Compression | Stored document content and index snapshots use zstandard; P2P framing is not universally compressed |
| 📊 Console Dashboard | Beautiful Textual TUI with 6 tabs: Overview, Crawl, Search, Network, Credits, Settings |
| 🌏 CJK Search | Native Chinese/Japanese/Korean tokenization with bigram/trigram expansion |
| 📡 RSS Monitoring | Opt-in RSS/Atom feed polling with priority-based scheduling (crawl.rss_enabled) |
| 🖥️ JS Rendering | Optional Playwright for SPA/React pages (headless Chromium) |
| 📈 Implicit Feedback | LLM-native quality signals (fetch/skip/cite) for ranking improvement |
| 🩺 Diagnostics | infomesh doctor checks health; infomesh bench measures performance |
| 🔌 Plugin System | Extensible hook-based API for custom crawlers, rankers, and tokenizers |
| 🌐 Web Dashboard | Browser-based dashboard at localhost:8080/dashboard with 5 tabs |
MCP Integration — Free Web Search for AI Assistants
Most commercial search APIs charge per query or require a paid subscription.
InfoMesh exposes 5 consolidated MCP tools without per-query billing — no hosted API key is required by default; operator-configured authentication and resource limits still apply:
| Tool | Description |
|---|---|
web_search(query, ...) |
Unified search — P2P + local, RAG, explain, answer extraction. CJK auto-detect |
fetch_page(url) |
Full extracted text for a URL (cached or live, max 100KB) |
crawl_url(url, depth, force) |
Crawl a URL and add to the index (60/hr rate limit) |
fact_check(claim, top_k) |
Cross-reference claims against indexed sources |
status() |
Node status: index size, peers, credits, analytics |
Legacy tool names (
search,search_local,network_stats, etc.) are still accepted for backward compatibility.
Configure in VS Code / Copilot / Claude Desktop / Cursor
This example is for Claude Desktop and Cursor. VS Code / Copilot requires the servers format shown in Connect to Your AI Assistant. These base-package examples use the local index; the same section explains how to enable P2P.
{
  "mcpServers": {
    "infomesh": {
      "command": "uvx",
      "args": ["infomesh", "mcp"]
    }
  }
}
Optional Add-ons
# Vector search with ChromaDB + sentence-transformers
pip install 'infomesh[vector]'

# Local LLM summarization via Ollama
pip install 'infomesh[llm]'

# JavaScript rendering for SPA pages (Playwright)
pip install 'infomesh[browser]'

# Chinese/Japanese/Korean tokenization (jieba)
pip install 'infomesh[cjk]'

# Everything
pip install 'infomesh[all]'
These commands install dependencies, not every runtime prerequisite. Vector search, local LLMs, and JS rendering must also be enabled/configured; JS rendering needs Playwright browser binaries, and local summarization needs an available model/runtime.
CLI Commands
infomesh start                  # Start node (auto-prompts starter index download)
infomesh start --background     # Headless mode (no dashboard)
infomesh start --role crawler   # DMZ crawler-only node
infomesh search "query"         # Search local index + peers
infomesh search --local "query" # Search local index only
infomesh crawl https://...      # Crawl a URL
infomesh dashboard              # Interactive TUI dashboard
infomesh doctor                 # System diagnostics (10 checks)
infomesh bench                  # Performance benchmarks
infomesh feedback stats         # Implicit search quality signals
infomesh feedback top-urls      # Highest-quality URLs by feedback
infomesh feeds import subs.opml # Import RSS/Atom feeds from OPML
infomesh index import --starter # Download community starter index
infomesh mcp                    # Start MCP server (stdio)
infomesh mcp --http --port 8081 # Start MCP server (HTTP)
🆕 What's New in v0.2.0
The v0.2.0 feature milestone recorded in CHANGELOG.md groups 100+ features across search intelligence, RAG support, security, observability, and developer experience. This historical milestone label is not the current package version: this checkout declares 0.1.15. The highlights below include optional capabilities and library utilities, not a guarantee that every feature is enabled in every runtime path:
Search Intelligence
| Feature | Description |
|---|---|
| 🧠 NLP Query Processing | Stop-word removal (9 languages), synonym expansion, natural language parsing |
| ✏️ Did-you-mean | Edit-distance spelling correction when no results found |
| 📊 Search Facets | Domain, language, and date-range facet counts per query |
| 🎯 Result Clustering | Groups results by domain for organized browsing |
| 🔦 Snippet Highlighting | Query terms highlighted in result snippets |
| 🧹 Smart Deduplication | Jaccard similarity-based near-duplicate removal |
| 🔍 Search Explain | Transparent score breakdowns for every result |
RAG & Answer Extraction
| Feature | Description |
|---|---|
| 📚 RAG Output | Chunked, source-attributed context windows for LLM consumption |
| 💡 Answer Extraction | Direct answers with confidence scores and source URLs |
| ✅ Fact Checking | Cross-reference claims against multiple indexed sources |
| 🏷️ Entity Extraction | Identifies persons, organizations, URLs, emails |
| 🛡️ Toxicity Filtering | Content safety scoring for search results |
Crawler Enhancements
| Feature | Description |
|---|---|
| 📄 PDF Extraction | Text extraction from crawled PDF documents |
| 🏗️ Structured Data | JSON-LD, OpenGraph, and meta tag parsing |
| 🌍 Language Detection | Script + word-frequency detection (9 languages) |
| 📡 RSS/Atom Feeds | Auto-discovery and parsing of feeds |
| 📝 Content Diffing | Change detection between crawl versions |
| 💻 Code Blocks | Extracts <pre><code> with language detection |
| 📊 Table Extraction | HTML tables → structured data (CSV/dict) |
Security & API
| Feature | Description |
|---|---|
| 🔑 API Key Management | Create, validate, revoke, rotate keys |
| 👥 Role-Based Access | Admin/Reader/Crawler permission matrix |
| 📋 Audit Logging | SQLite-backed audit logging utilities; coverage depends on the enabled call paths |
| 🔒 Webhook Signatures | HMAC-SHA256 payload verification |
| 📊 Prometheus Metrics | /metrics endpoint for monitoring |
| 📖 OpenAPI Spec | Auto-generated OpenAPI 3.1 at /openapi-spec |
Developer Experience
| Feature | Description |
|---|---|
| 🐍 Python SDK | InfoMeshClient with sync/async search, crawl, suggest |
| 🔌 Plugin System | Register custom plugins with lifecycle hooks |
| 🦜 LangChain | InfoMeshRetriever integration |
| 🦙 LlamaIndex | InfoMeshReader integration |
| 🏗️ Haystack | InfoMeshDocumentStore integration |
| ⎈ Helm Chart | Kubernetes deployment with configurable resources |
| 🐳 Docker Compose | Multi-container setup with volumes |
See CHANGELOG.md for the complete list of changes.
🏗️ Architecture
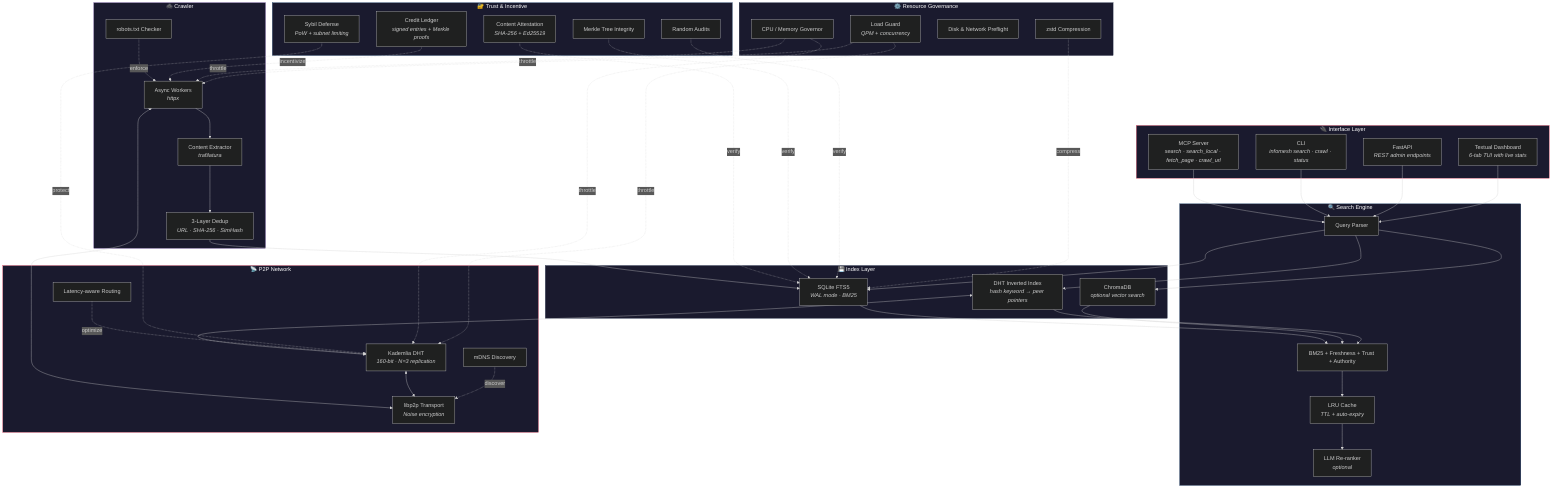
Tech Stack
| Layer | Technology | Why |
|---|---|---|
| Language | Python 3.12+ | Modern async, type hints, match/case, StrEnum |
| P2P Network | libp2p (py-libp2p) | Battle-tested P2P stack with Kademlia DHT, Noise encryption |
| DHT | Kademlia | XOR-distance routing; the current py-libp2p backend normalizes routing keys with 256-bit SHA-256 |
| Crawling | httpx + trafilatura | Best async HTTP + highest-accuracy content extraction |
| Keyword Search | SQLite FTS5 | Zero-install, embedded, BM25 out of the box |
| Vector Search | ChromaDB (optional) | Semantic / embedding search with all-MiniLM-L6-v2 |
| MCP Server | mcp-python-sdk | Standard protocol for LLM tool integration |
| Admin API | FastAPI | Local health, status, config endpoints |
| Serialization | msgpack | Binary message encoding; speed and size relative to JSON depend on the payload |
| Compression | zstandard | Level-tunable, dictionary mode for similar documents |
| Dashboard | Textual | Rich TUI with tabs, sparklines, EQ visualization, BGM |
| Local LLM | ollama / llama.cpp | On-node summarization (Qwen 2.5, Llama 3.x, Gemma 3) |
| Logging | structlog | Structured, machine-parseable logs |
| Packaging | uv | Python dependency, environment, and build management; speedups depend on the workload |
Search Flow (Target Latency: ~1 second)
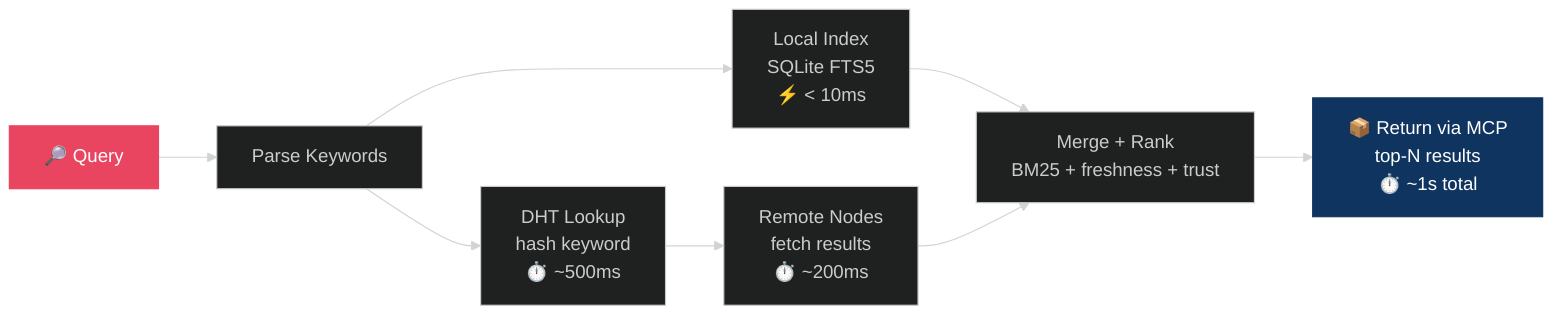
🔒 Security & Trust
InfoMesh is designed with a zero-trust assumption — every peer is potentially adversarial. The system provides multiple layers of defense:
Content Integrity
| Mechanism | Description |
|---|---|
| Content Attestation | Published source attestations bind SHA-256(raw_response) + SHA-256(extracted_text) to a signing identity; local-only crawling does not guarantee publication |
| Merkle Tree | Index-wide integrity proofs with membership verification — anyone can audit any document's inclusion |
| Random Audits | Approximately hourly replica/source checks, subject to peer availability; replica corruption can penalize trust, while changed source content is inconclusive |
| P2P Credit Verification | Merkle proofs for entries recorded with a signing key; unsigned entries are excluded from signed proofs |
Network Security
| Threat | Defense |
|---|---|
| Sybil Attack | Local Proof-of-Work generation (hardware-dependent duration) + default maximum of 3 nodes per /24 admission bucket; not a guarantee against mass identities |
| Eclipse Attack | Bootstrap discovery + subnet limits + peer refresh; ≥3 independent reachable peers is a deployment goal, not the current bundled default |
| DHT Poisoning | Per-keyword publish rate limit (10/hr/node) + signed publications + content hash verification |
| Credit Farming | 24hr probation for new nodes + statistical anomaly detection + raw HTTP hash audits |
| Man-in-the-Middle | All P2P transport encrypted via libp2p Noise protocol |
Key Management
- Ed25519 key pairs stored in
~/.infomesh/keys/ - Key rotation:
infomesh keys rotate— rotates application signing keys and saves a dual-signed revocation record locally; it does not rotate the separate libp2p transport key - Peer identity: the libp2p transport uses a peer ID derived from its own public key; the application signing-key identifier is a separate identity
Current propagation limitation: rotation writes .bin records, while the startup publisher scans .json files. Do not rely on automatic DHT revocation propagation from this command until that integration mismatch is corrected.
Unified Trust Score
Every peer has a continuously updated trust score:
Trust = 0.15 × uptime + 0.25 × contribution + 0.40 × audit_pass_rate + 0.20 × summary_quality
| Tier | Score | Treatment |
|---|---|---|
| Trusted | ≥ 0.8 | Highest trust grade; search cost follows the separate contribution tier |
| Normal | 0.5 – 0.8 | Standard operation |
| Suspect | 0.3 – 0.5 | Low trust grade; inspect audit evidence and isolation state |
| Untrusted | < 0.3 | Network isolation after 3× consecutive audit failures |
🏢 Enterprise Readiness
InfoMesh includes features for production-oriented deployments, but the current package is classified as Alpha. Validate your environment and the runtime conformance limits before production use:
Split Deployment (DMZ / Private Network)
Enterprise environments can separate crawlers from indexers across network zones:
┌─────────── DMZ ──────────────┐       ┌──────── Private Network ────────┐
│                              │       │                                 │
│  infomesh start --role crawler ───────▶  infomesh start --role search │
│  (crawls the public web)     │  P2P  │  (indexes + serves queries)    │
│                              │ auth  │                                 │
│  infomesh start --role crawler ───────▶  infomesh start --role search │
│                              │       │                                 │
└──────────────────────────────┘       └─────────────────────────────────┘
Three node roles:
| Role | Components | Use Case |
|---|---|---|
full (default) |
Crawler + Indexer + Search | Single-node or simple deployments |
crawler |
Crawler only, forwards pages to indexers | DMZ nodes with internet access |
search |
Indexer + Search only, accepts submissions | Private network, no internet needed |
Configuration example (~/.infomesh/config.toml):
# DMZ Crawler node
[node]
role = "crawler"
listen_address = "0.0.0.0"

[network]
index_submit_peers = ["/ip4/10.0.0.1/tcp/4001/p2p/<INDEXER_1_PEER_ID>", "/ip4/10.0.0.2/tcp/4001/p2p/<INDEXER_2_PEER_ID>"]
# Private Search/Index node
[node]
role = "search"
listen_address = "10.0.0.1"

[network]
peer_acl = ["<CRAWLER_1_PEER_ID>", "<CRAWLER_2_PEER_ID>"]
Replace each placeholder with the corresponding node's actual libp2p peer ID. Index submissions require complete peer multiaddrs and authenticated v2 acknowledgments; bare IP/TCP addresses or legacy HTTP destinations are not supported.
CLI usage:
# Start as DMZ crawler
infomesh start --role crawler --seeds tech-docs

# Start as private indexer
infomesh start --role search --no-dashboard
Operational
- Resource Governor — CPU/memory thresholds, I/O priority, and bandwidth controls with 4 preset profiles (
minimal,balanced,contributor,dedicated). Dynamic throttling responds to sampled system load and process RSS; this is not a hard memory cap or a guarantee against the OS OOM-killer - Long-Run Resilience —
StartupLock+ PID cmdline validation prevent duplicate node processes for the same data directory;infomesh stopissues SIGTERM and waits for graceful shutdown before clearing the PID file - Runtime Heartbeat — Long-running
_serveworkers writeruntime_status.jsonevery 10 s; the admin API exposes the latest heartbeat, degrade level, throttle factor, and process memory via/health?detail=1,/status, and/metrics - Pre-flight Checks — Disk space and network connectivity verified before startup
- Load Guard — QPM (queries per minute) + concurrency limiting to prevent node overload
- WAL Mode SQLite — Safe concurrent reads during dashboard refresh without locking crawl writes
- Structured Logging — All library code uses
structlogwith machine-parseable output - Docker Support —
Dockerfilewith volume mounts for persistent data; production readiness still requires deployment-specific validation
Configurable
- TOML Configuration (
~/.infomesh/config.toml) with environment variable overrides (INFOMESH_CRAWL_MAX_CONCURRENT=20) - Value Validation — Selected configuration values are validated or clamped with structured warnings; validation is field-specific, not a guarantee for every value
- Dashboard Settings — Common settings are editable via the TUI Settings tab; advanced fields still require configuration-file or CLI changes
- Energy-aware Scheduling — LLM-heavy tasks preferentially scheduled during configured off-peak hours (1.5× credit multiplier)
Compliance
- robots.txt strictly enforced — respects all crawl directives
- DMCA Takedown — Authorized signed notices persist exclusions and relay obligations; delivery to unreachable peers cannot be guaranteed within 24 hours
- GDPR — Distributed deletion records for personal data; right-to-be-forgotten support
- Content Attribution — AI-generated summaries labeled with
content_hash+ source URL - Paywall Detection —
fetch_page()detects and respects paywalled content - Terms of Use — Clear TERMS_OF_USE.md covering crawler behavior and data handling
Scale
- Designed for thousands of nodes with Kademlia DHT routing
- 3-layer deduplication prevents index bloat (URL normalization → SHA-256 exact → SimHash near-duplicate)
- zstd-compressed snapshots for efficient index sharing between nodes
- Common Crawl data import for bootstrapping large indexes
💰 Earning Credits
Credits are the incentive mechanism that keeps the network healthy. They are tracked locally per node — no blockchain, no central ledger.
How Credits Work
Credits Earned = Σ (Weight × Quantity × TimeMultiplier)
Earning Actions
| Action | Weight | Category | How to Earn |
|---|---|---|---|
| Crawling | 1.0 /page | Base | Just run InfoMesh — it auto-crawls from seed URLs |
| Query Processing | 0.5 /query | Base | Other peers route search queries through your node |
| Document Hosting | 0.1 /hr | Base | Passive — your indexed documents serve the network |
| Network Uptime | 0.5 /hr | Base | Keep your node running. That's it |
| LLM Summarization | 1.5 /page | LLM | Enable local LLM to auto-summarize crawled content |
| LLM for Peers | 2.0 /request | LLM | Serve summarization requests from other nodes |
| PR — docs/typo | 1,000 /merged PR | Bonus | Fix a typo or improve documentation |
| PR — bug fix | 10,000 /merged PR | Bonus | Fix a bug with tests |
| PR — feature | 50,000 /merged PR | Bonus | Implement a new feature |
| PR — major | 100,000 /merged PR | Bonus | Core architecture or major feature |
PR rows are ledger action weights, not proof of automatic GitHub rewards. A merged PR earns these credits only when the corresponding contribution is recorded in the ledger.
Time Multiplier
- Base actions: Always
1.0× - LLM actions during off-peak hours (configurable, default 23:00–07:00):
1.5× - Off-peak scheduling is energy-conscious — the network preferentially routes batch LLM work to nodes currently in off-peak
Search Cost
| Tier | Contribution Score | Search Cost | Effective Ratio |
|---|---|---|---|
| Tier 1 | < 100 | 0.100 / query | 10 crawls → 100 searches |
| Tier 2 | 100 – 999 | 0.050 / query | 10 crawls → 200 searches |
| Tier 3 | ≥ 1,000 | 0.033 / query | 10 crawls → about 303 searches |
Fairness Guarantees
- Non-LLM participation: 10 credited crawls/hr cover 100 searches/hr at the normal Tier 1 rate (50 at the debt rate); this is credit arithmetic, not a throughput guarantee
- LLM contribution score capped: LLM actions contribute at most 60% of the effective contribution score used for tiers; this does not cap raw ledger earnings or balance
- Uptime rewards: 0.5 credits/hr just for keeping your node online, regardless of hardware
- Credit exhaustion does not block search: Even with zero credits, the ledger permits search under the rules below; resource safeguards can still limit requests
💳 Zero-Dollar Debt — No Credit Card, No Real Money
What happens when your credits run out? You keep searching.
InfoMesh doesn't cut you off. There's no paywall, no "please enter your credit card," no upgrade button. Instead, there's a simple, human-friendly recovery path:
| Phase | Duration | What Happens |
|---|---|---|
| ✅ Normal | While balance > 0 | Search at normal cost. Business as usual. |
| ⏳ Grace Period | First 72 hours at zero | Search works exactly as before. Your balance goes negative, but there's no penalty. Take your time. |
| 📉 Debt Mode | After 72 hours | Search continues, but at 2× cost. Debt accumulates — incentivizing recovery, never blocking. |
| 🔄 Recovery | Whenever you want | Just run your node. Earn credits by crawling, hosting, or contributing. Once your balance is positive again, you're back to normal. |
Credits ran out
     │
     ▼
┌─────────────────────────────────────┐
│  🟢 Grace Period (72 hours)         │
│  Search works normally.             │
│  Balance goes negative — no penalty.│
└──────────────┬──────────────────────┘
               │ 72h passed, still negative?
               ▼
┌─────────────────────────────────────┐
│  🟡 Debt Mode                       │
│  Search continues at 2× cost.      │
│  Debt accumulates.                  │
└──────────────┬──────────────────────┘
               │ Earn credits → balance > 0
               ▼
┌─────────────────────────────────────┐
│  🟢 Back to Normal                  │
│  Debt cleared. Grace reset.         │
│  Full speed ahead.                  │
└─────────────────────────────────────┘
The key principle: Debt in InfoMesh is measured in credits, not money. You recover by contributing, not by paying. Run your node, crawl some pages, keep the network alive — and your debt disappears naturally.
No credit card. No dollars. No subscription. No "trial expired" popup.
Just run your node, and you're back.
🤝 Contributing
We welcome contributions of all kinds — code, documentation, bug reports, feature ideas, and seed URL lists.
Getting Started
# Clone and install
git clone https://github.com/dotnetpower/infomesh.git
cd infomesh
uv sync --dev --locked

# Run the supported test suite
uv run pytest tests/ --ignore=tests/test_vector.py -x -q --tb=short

# Run linter + formatter
uv run ruff check infomesh/ tests/
uv run ruff format --check .

# Run type checker
uv run mypy infomesh/ --ignore-missing-imports
Ways to Contribute
| Contribution | Difficulty | Impact |
|---|---|---|
| 🐛 Report a bug | Easy | High — helps everyone |
| 📝 Improve docs / translations | Easy | High — lowers entry barrier |
| 🌱 Add seed URLs | Easy | Medium — expands crawl coverage |
| 🧪 Write tests | Medium | High — keeps distributed search, crawling, and dashboard regressions covered |
| 🔧 Fix an issue | Medium | Direct impact |
| ✨ Implement a feature | Hard | Moves the project forward |
| 🔐 Security audit | Hard | Critical for trust |
Code Style
- Formatter:
ruff format(black-compatible, 88 char lines) - Linter:
ruffwithE,F,I,UP,B,SIMrules - Type hints: Required on all public functions
- Docstrings: Required on all public classes and functions
- Tests: Every PR should include tests for new functionality
- No
print()in library code — usestructlog
Pull Request Workflow
- Fork the repository
- Create a feature branch:
git checkout -b feat/my-feature - Write code + tests
- Run
uv run ruff check infomesh/ tests/,uv run ruff format --check .,uv run mypy infomesh/ --ignore-missing-imports, anduv run pytest tests/ --ignore=tests/test_vector.py -x -q --tb=short - Submit a PR — merged contributions have ledger reward weights of 1,000 – 100,000 credits; crediting requires recording the contribution, not merely opening or merging a PR.
See CONTRIBUTING.md for the full guide.
📖 Documentation
Detailed documentation is available in the docs/ directory:
| Document | Description |
|---|---|
| Overview | Project vision, principles, and mission |
| Architecture | System design, data flow, and component interaction |
| Credit System | Full incentive mechanics and fairness analysis |
| Tech Stack | Technology choices and rationale |
| Legal | robots.txt, DMCA, GDPR, compliance |
| Trust & Integrity | Security model and threat analysis |
| Security Audit | Vulnerability analysis and enterprise hardening |
| Console Dashboard | TUI dashboard, tabs, widgets, shortcuts |
| MCP Integration | MCP server setup, IDE configuration guide |
| Publishing | PyPI packaging, CI/CD, release process |
📌 Documentation is also available in Korean (한국어).
📊 Project Stats
Working-tree snapshot on 2026-09-20. File/line counts include Python files under infomesh/ and tests/; source modules include package initializers. Test results below are from Python 3.13, excluding the optional vector suite and with the opt-in live LLM check skipped.
| Metric | Value |
|---|---|
| Source modules | 169 Python files |
| Test files | 91 test_*.py files |
| Source lines | 51,404 |
| Test lines | 28,478 |
| Tests passing | 2,183 passed, 1 skipped (--ignore=tests/test_vector.py) |
| MCP tools | 5 consolidated tools (legacy names supported) |
| Test coverage | Regression coverage; this run does not establish 100% code or runtime-path coverage |
| Development phases | 10 historical milestones (Phase 0 → 6); not a blanket runtime-conformance guarantee |
| Python version | 3.12+ |
| License | MIT |
🗺️ Roadmap
The table records completed historical component milestones, not a guarantee that every runtime integration or deployment requirement is complete. Current focus is on community growth and production hardening; see the runtime conformance record for evidence and operating limits.
| Phase | Focus | Status |
|---|---|---|
| 0 | MVP — single-node crawl + index + MCP + CLI | ✅ Complete |
| 1 | Index sharing — snapshots, Common Crawl, vector search, SimHash | ✅ Complete |
| 2 | P2P network — libp2p, DHT, distributed crawl & index, Sybil/Eclipse defense | ✅ Complete |
| 3 | Quality + incentives — ranking, credits, trust, attestation, audits, LLM | ✅ Complete |
| 4 | Production — link graph, LLM re-ranking, attribution, legal compliance | ✅ Complete |
| 5A | Core stability — resource governor, auto-recrawl, query cache, load guard | ✅ Complete |
| 5B | Search quality — latency-aware routing, Merkle Tree integrity | ✅ Complete |
| 5C | Release readiness — Docker, key rotation, mDNS, LICENSE, CONTRIBUTING | ✅ Complete |
| 5D | Polish — LLM reputation, timezone verification, dashboard settings, P2P credit verification | ✅ Complete |
| 6 | Search intelligence, RAG, security, observability, SDK, integrations, DX | ✅ Complete |
What's Next
- 🌍 Public bootstrap nodes — expand community-maintained seed nodes across multiple regions
Current configuration:
bootstrap/nodes.jsoncontains one Azure East US peer. P2P-enabled nodes attempt bootstrap discovery automatically; this list is not a live availability guarantee, and firewalls/NAT may require configuration. - 🎭 JS rendering — Playwright-based SPA crawling for JS-heavy sites
- 📱 Web dashboard — optional browser UI alongside the TUI
- 🔍 Semantic search fusion — BM25 + vector hybrid ranking with RRF
- 🌐 Multi-language stemming — language-specific tokenization and stemming
⚖️ Legal
- robots.txt: Strictly enforced. Sites that prohibit crawling are never crawled.
- Copyright: Full text stored as cache only; search results return snippets with source attribution.
- DMCA: Authorized signed notices persist exclusions and peer relay work. A 24-hour delivery deadline cannot be guaranteed for unreachable peers.
- GDPR: Distributed deletion records. Nodes can exclude pages with personal data.
- AI Summaries: Labeled as AI-generated, linked to source via
content_hash, original URL always provided. - Terms of Use: See TERMS_OF_USE.md for full terms.
🙏 Acknowledgements
InfoMesh stands on the shoulders of excellent open-source projects:
httpx •
trafilatura •
libp2p •
SQLite •
ChromaDB •
Textual •
FastAPI •
mcp-python-sdk •
uv •
structlog •
zstandard
MIT License — Copyright 2026 InfoMesh Contributors
If you find InfoMesh useful, consider ⭐ starring the repo — it helps others discover the project.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found