omp-laya-judge
Health Warn
- License — License: NOASSERTION
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Local Laya System-1 judge MCP server + skill for oh-my-pi: typed decisions in milliseconds, zero LLM tokens
omp-laya-judge
Local System-1 judge for oh-my-pi,
powered by laya. Typed decisions
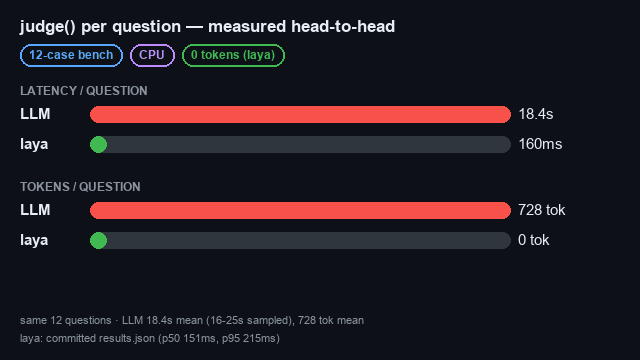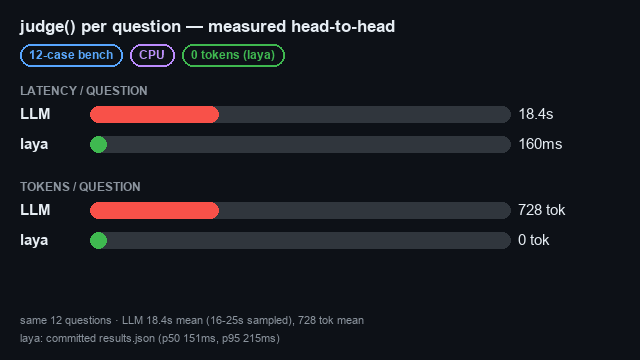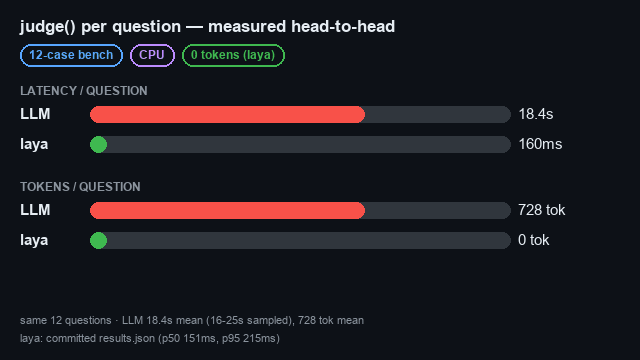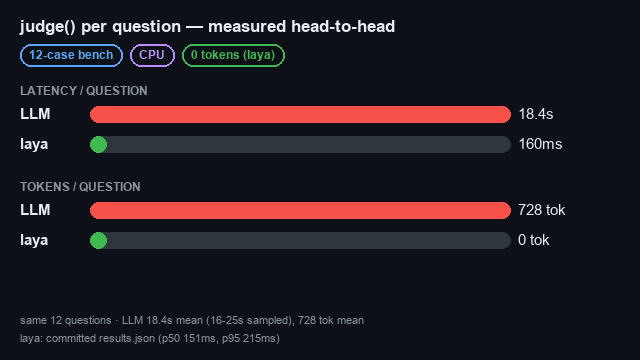
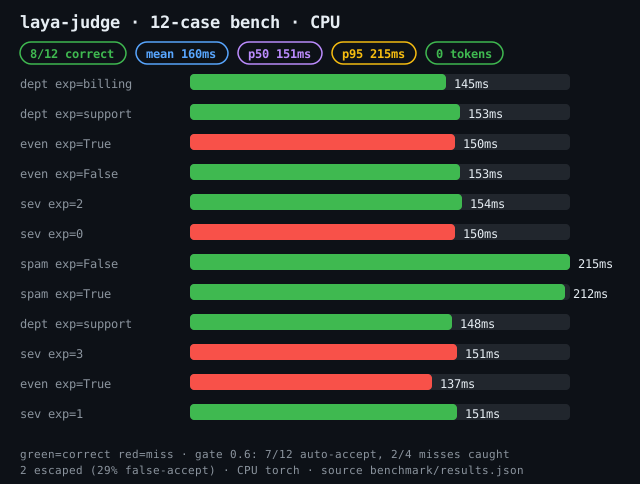
(choice/bool/score) at mean 160ms (p50 151ms, p95 215ms) on CPU,
0 LLM tokens burned, nothing leaves the machine.
Measured head-to-head
Same 12 classification questions, real model via omp -p vs this plugin
on CPU, no GPU:
LLM judge() |
laya-judge | |
|---|---|---|
| latency / question | 18.4s (16–25s sampled) | mean 160ms (p50 151ms, p95 215ms) |
| tokens / question | 728 | 0 |
| accuracy (12-case bench) | n/a (reference) | 8/12 |
Reproduce everything below from committed artifacts:
python benchmark/run.py           # -> benchmark/results.json (schema 2)
python benchmark/calibrate.py     # -> benchmark/calibration.json (gate metrics)
python benchmark/chart.py         # -> assets/benchmark.svg
python benchmark/before_after.py  # -> assets/before-after.gif
The 0.6 gate, honestly
Policy: answers with confidence ≥ 0.6 are auto-accepted, below escalates
to the LLM. What that bought on the 12-case bench
(benchmark/calibration.json, computed — not asserted):
- auto-accept 7/12, 5 escalated to the LLM
- 4 misses total: 2 caught by the gate, 2 escaped
- false-accept 29% (2 of the 7 auto-accepts were wrong)
Both escapes are parity questions at confidence 0.80/0.84 — the model is
confidently wrong on arithmetic. Confidence alone does not save you
there, which is why rules/laya-auto.md and the skill exclude
arithmetic/parity questions from auto-accept and route them to the LLM
regardless of confidence.
Checkpoint A/B/C + random
(benchmark/compare.json, reproduced by benchmark/compare_models.py):
| EN 12-case | TR 4-case | mean conf | mean ms | |
|---|---|---|---|---|
| english | 8 | 2 | 0.68 | 210 |
| typed-decisions | 8 | 3 | 0.54 | 198 |
| multilingual | 6 | 2 | 0.76 | 111 |
| random (coin flip) | 6 | 0 | — | 0 |
TR sample is small (4); the honest read is laya >> chance (2–3 vs 0), not
a checkpoint coronation.
Demos
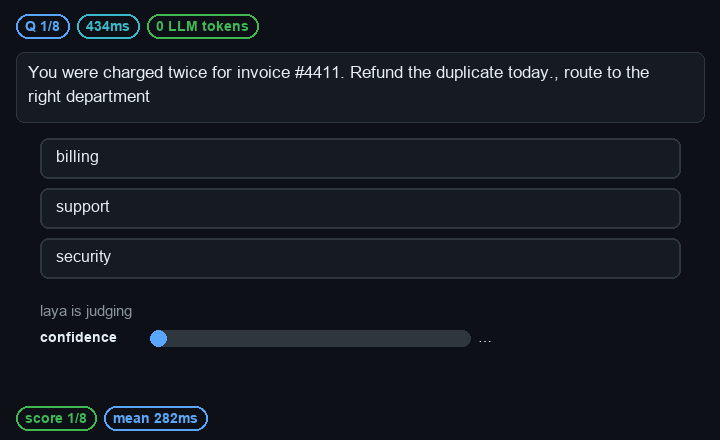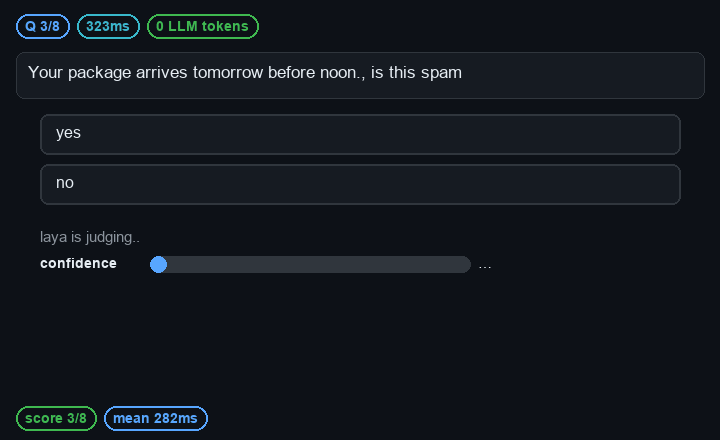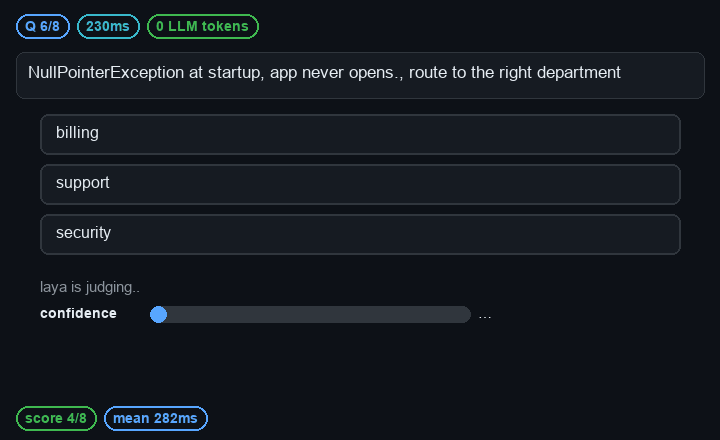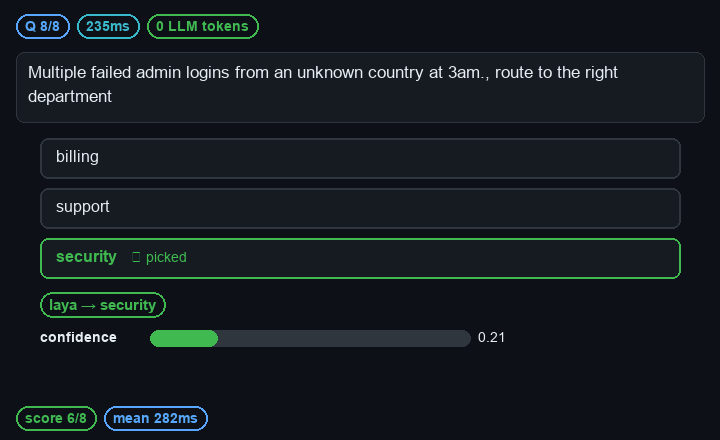
Grounded quiz (python demo/quiz.py): 6/8, mean 282ms, 0 tokens —
both misses came in under 0.2 confidence, exactly the cases the escalate
rule covers.
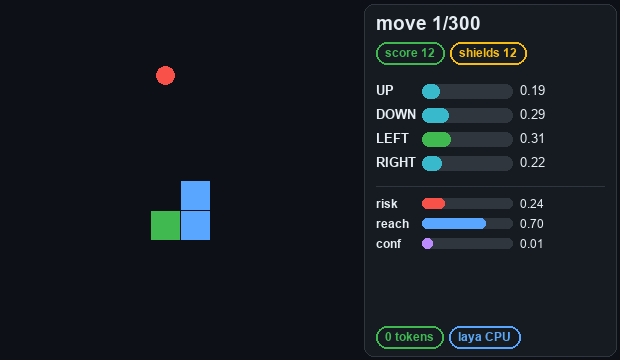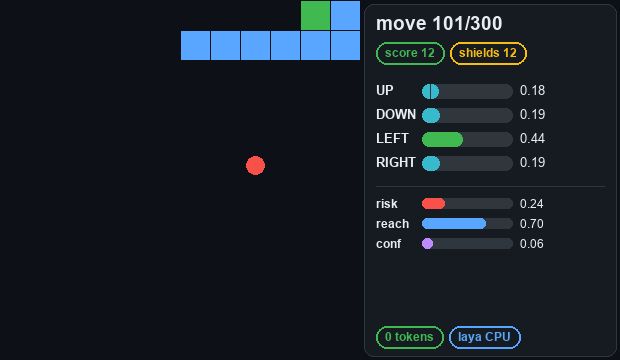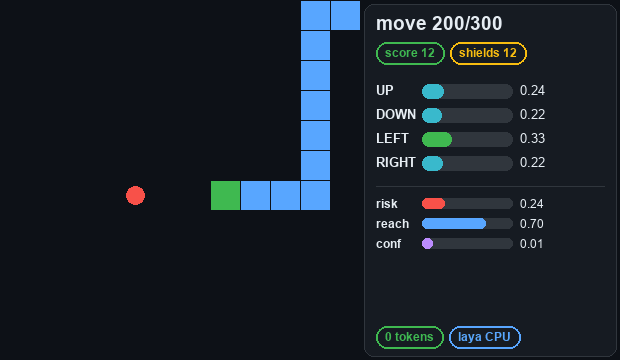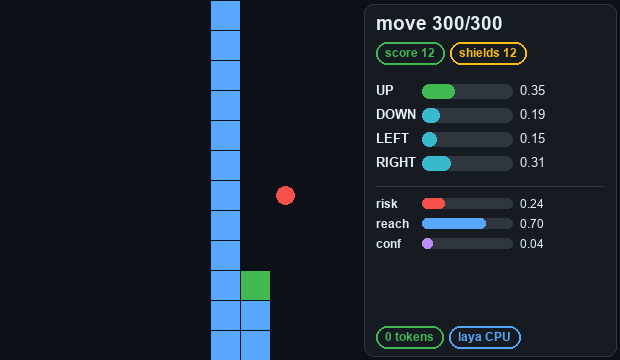
Snake (python demo/snake.py): score 12, 300 moves, alive, 12 shield
interventions, ~0.9s/move on CPU, 0 tokens. Watch every decision in the
browser: open web/snake.html (canvas replay with live probability bars,
play/pause/speed/scrub); quiz at web-quiz.html. Recipe (from
laya-mlx): a deterministic planner
describes each direction over a tiny state (Safe route: yes. Food reachable: …), a safety shield executes the best SAFE move. Short parallel criteria are
the whole trick — greedy end-to-end choice without the planner scores 0 (seedemo/snake.py header for the measured failure modes). Honest calibration:
per-move confidences on game states run at noise level (0.005-0.05; the quiz
gets 0.2-1.0 on text) — navigation is planner + shield with laya ranking, the
same division of labor as laya-mlx. The maze variant (demo/maze.py) is a
documented negative: corridors trap the noise walk (1 crumb/200 steps).
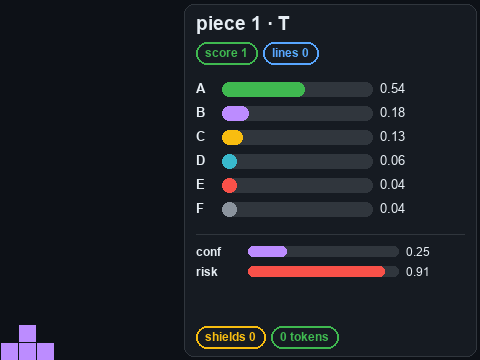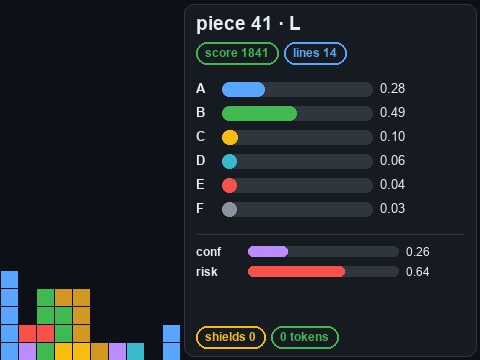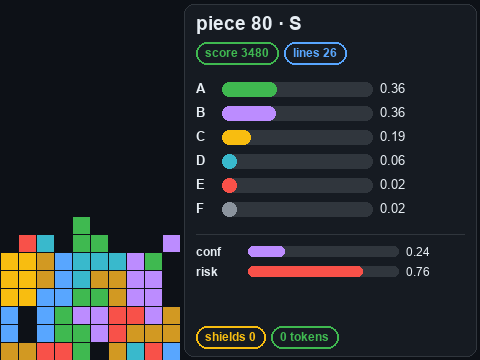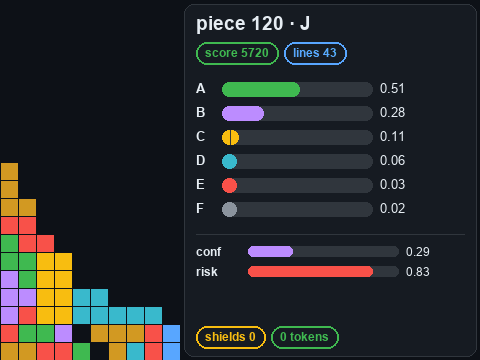
Tetris (python demo/tetris.py): score 5720, 43 lines, 120 pieces, alive,
~1s/placement on CPU, 0 tokens. Per piece the planner enumerates every
legal landing, shortlists 6 by classic features (lines, holes, height,
bumpiness), laya picks one in a batched call, and a shield keeps the stack
out of the top-4 danger zone. Replay in browser: web/tetris.html (colored
board, candidate cards with live probabilities, scrub).
Languages
The server routes per request: Latin script → english, everything else →multilingual (one extra ~0.7GB download, then cached). Turkish works today
(e.g. fatura/departman routing correct) but with lower confidence than
English — the same 0.6 gate applies. To pin a checkpoint, set LAYA_MODEL
in .mcp.json's env; the manifest ships unpinned because pinning
disables routing.
Install (step by step)
Requirements: Python 3.10+, pip, ~3GB disk (checkpoints), oh-my-pi.
pip install -r server/requirements.txt   # laya==0.3.20, mcp<2, torch, transformers>=4.48,<5
omp plugin marketplace add F0Rextasy/omp-marketplace
omp plugin install laya-judge@forextasy  # or: omp plugin link ./omp-laya-judge
omp plugin list                          # laya-judge should show ● enabled
Verify inside omp:
Call the tool mcp__laya-judge__judge_info and reply with its exact JSON output.
Expected: {"model": "laya/auto", "device": "cpu", "loaded": true, ...}.
First start imports torch and loads the checkpoint (~10s warm, longer on a
cold machine while both checkpoints download — the manifest shipstimeout: 600000 for exactly that), then ~0.16s per judgment.
Troubleshooting (all hit during development, all fixed in this repo):
transformers< 4.48 cannot load ModernBERT → pintransformers>=4.48,<5.mcp>=2renamed FastMCP → pinmcp<2.- On Windows, torch must init in the main thread → the server preloads eagerly
andjudge_inforeportsstartup_errorinstead of hanging if it fails. python.EXE/py.EXEuppercase spawn failures → use the shipped.cmdwrapper.
Use
The plugin exposes mcp__laya-judge__judge(state, questions) plus thelaya-judge skill (triage → pre-filter → escalate). Question shapes mirror
oh-my-pi's eval judge():
choice:criteria: {label: rubric}→{choice, probabilities, confidence}bool: yes/no statement →{bool: P(true)}(layanoulhead is[false, true])score:criteria: [lowest … highest]→{score, legend, probabilities, confidence}
Every reply carries model (laya/english or laya/multilingual, derived
from laya's own routing block), per-call latency_ms, and laya's usage/routing block so provenance survives in the transcript.
Tests
python -m unittest discover -s . -t . -p "test_*.py"             # fast suite (CI)
LAYA_SLOW_TESTS=1 python -m unittest discover -s . -t . -p "test_*.py"   # + model/stdio/routing/concurrency
The fast suite pins the mapping layer, the HTTP sidecar contract, repo
hygiene (requirements/license/versions/manifest), and — viatests/test_readme_lint.py + tests/test_calibration.py — that every
number on this page still matches the committed JSON. The slow suite needs
cached checkpoints: accuracy floor, MCP stdio handshake against a spawned
server, non-Latin routing, Turkish diacritics, and parallel judgments.
Status: tool + skill, not yet the agent loop
Honest scope: this plugin makes laya callable from any oh-my-pi session today.
It is not yet wired into the eval judge() chain — the agent won't call it
on its own; you (or your prompt) invoke it explicitly. The HTTP sidecar
(server/sidecar.py) is the stepping stone for auto-routing cheap judgments
to laya inside resolveJudge as a PR to oh-my-pi core.
Layout
.mcp.json— stdio server declaration (unpinned,timeout: 600000)server/server.py— FastMCP server, eager checkpoint load, auto-routingserver/core.py— pure mapping (no torch), batch + unpack layerserver/sidecar.py— HTTP sidecar (POST /judge,GET /info)server/laya-judge.cmd— Windows launcherskills/laya-judge/SKILL.md— when to use / when to escalaterules/laya-auto.md— auto-routing rule (arithmetic excluded)commands/laya.md+hooks/pre/laya-status.ts—/layastatus command + pre-run hookbenchmark/— reproducible accuracy + latency + gate proofdemo/— quiz/snake/tetris + maze (all seeded,*-stats.json)tests/— fast + slow suites;.github/workflows/test.ymlruns fastassets/—before-after.gif,benchmark.svg,quiz.gif,snake.gif,tetris.gif
License
MIT
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found