ServerPilot
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
MCP-based GPU coordination for AI agents, with human oversight across multiple servers.
ServerPilot
Agents take their own GPUs. You watch the whole fleet.
MCP for agents · Native desktop app · Open source
中文 · What it does · Quick start · Agent usage · Boundaries · Docs


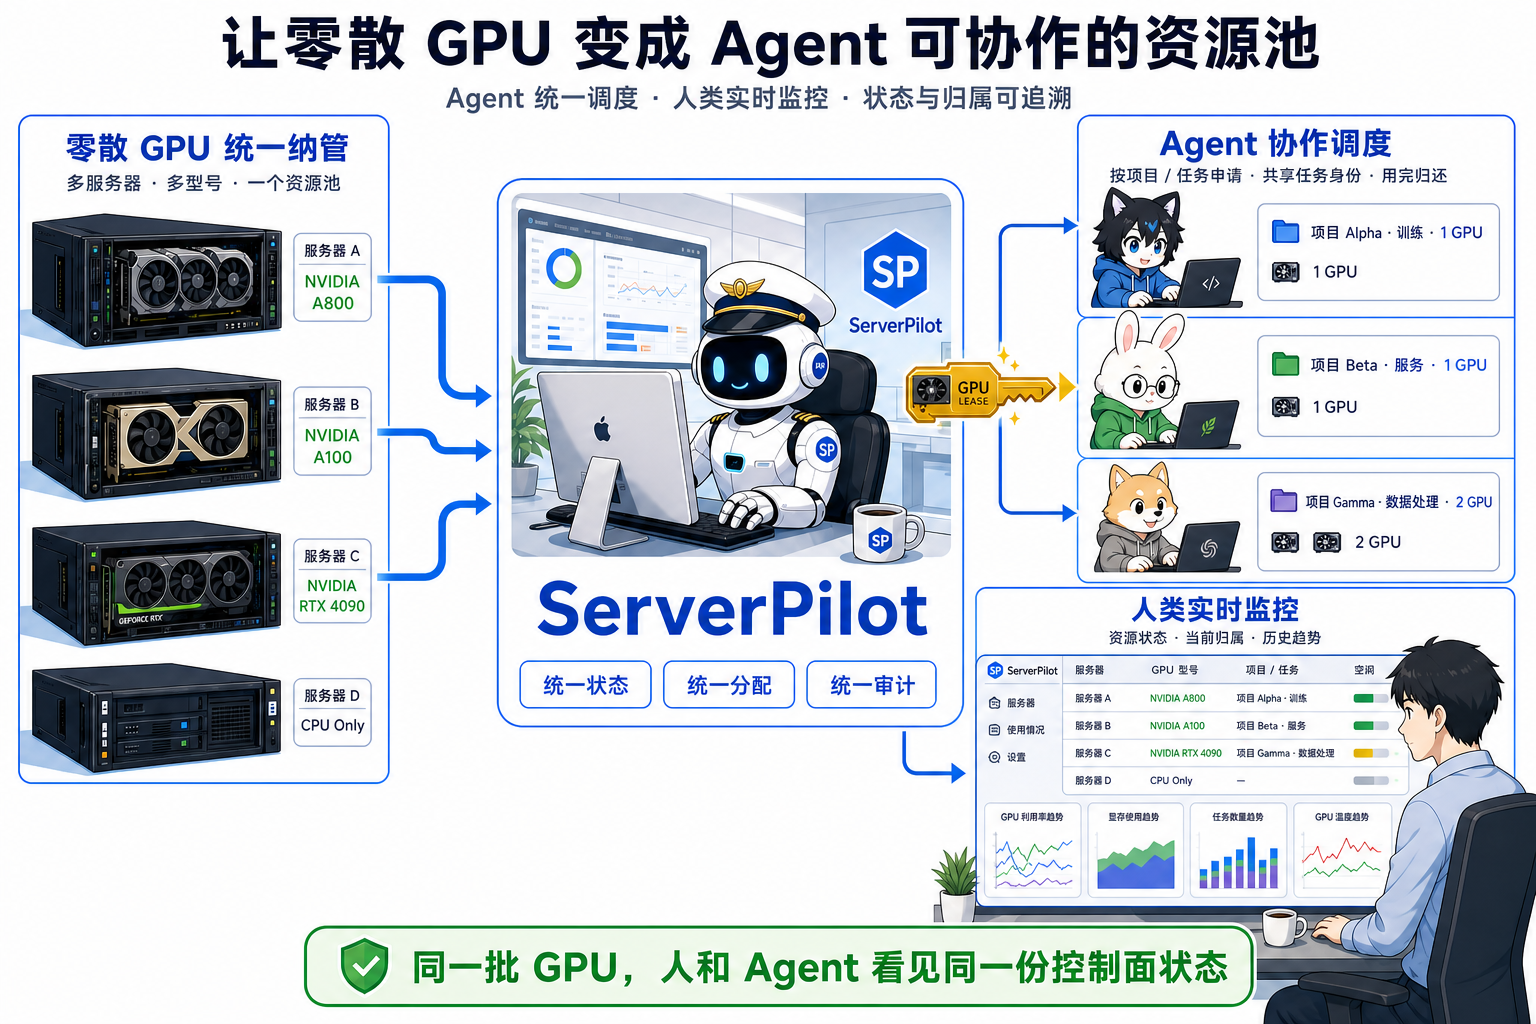
Illustration only; not a real resource state or app screen.
Your agents write code and run experiments on their own. Are you still handing
them GPUs one card at a time?
To an agent, ServerPilot is an MCP server: look at cards, take some, give them
back, and register or update a host. To you, it is a macOS app showing what
is free, what is busy, whose job is where, and what is failing
across every server you registered. There is no browser UI.
One local user, several servers, several agents. Resource state, requests, and
human correction all read the same committed snapshot from one local control
plane.
| What it gives you | How |
|---|---|
| One source of truth | The GUI, the CLI, and MCP all read the daemon's committed snapshot instead of each deriving state. |
| A three-step loop for agents | gpu_status → gpu_apply → gpu_release covers routine coordination. |
| A view for humans | Servers, tasks, ownership, and failures, with bounded manual correction when something is wrong. |
| Per-card idle holding | Optional keepalive yields only the card being requested and restores the rest. |
✨ What it does
🛰️ One picture of every server
Server state refreshes on the collection interval you set. Free cards, busy
cards, which task owns what, and collector failures are all visible in the app.
Servers can sit in a first-class group that carries a shared workspace plus
environment and data/weight notes; a member inherits that workspace or
overrides it. Environment notes are descriptive only. Allocatable capacity is
shown group → server → SKU, not as a menu of individual free cards.
🧩 Agents allocate for themselves
The MCP surface is exactly three tools:
- 🔎
gpu_status— free cards and your tasks, or one task, or one server - 🎯
gpu_apply— declare what a task needs and get how to enter its cards - 🧹
gpu_release— return a task's cards, all of them or some
A successful request returns the SSH connection, the remote working directory,
a CUDA selector, and a lease_id, so an agent never has to guess a server, a
directory, or a GPU index. Deleting a server stays in the app and REST; it is
not an MCP tool, and it refuses while that server holds active leases.
🛠️ You step in only when something is wrong
While agents work normally you only watch. When ownership looks wrong, a
connection fails, or a hold is left behind, you confirm and correct it: settle a
stale lease, or move a task to different GPUs while keeping the card count.
🐶 Optional: hold idle GPUs so nobody else takes them
Per-card keepalive can keep confirmed-idle GPUs on standby. When an agent
requests one, only that card is yielded, and it returns to standby after
release. Other cards on the same machine are untouched.
Use it only on servers you administer. It never touches an unknown process or
someone else's running job.
Keepalive workers run detached from the control plane. If the control plane
stops, those GPUs stay occupied until it comes back and reconciles, or until
someone stops them. There is no automatic release on shutdown.
When the control plane is unreachable, these commands put things back. None of
them needs the daemon to be running. They act on the control plane's data
directory:
serverpilot keepalive inspect --endpoint <server-id>   # what is still holding cards
serverpilot keepalive stop --endpoint <server-id>      # stop it and free them
serverpilot daemon reclaim                             # take port 8787 back
daemon reclaim only resolves the case where a ServerPilot service answers on
8787 without launchd owning it; when the daemon is properly owned it does
nothing. The port-ownership error names the holding process and its command
line.
🚀 Quick start
1. 🧰 Start the local control plane
On macOS the CLI is the backend. uv tool install installs the control
plane the daemon will run; the desktop app is only the GUI. Opening the app
does not start or replace that process.
macOS, from source, with Python 3.12+ and
uv:
git clone https://github.com/JinPLu/ServerPilot.git
cd ServerPilot
uv tool install --force .
serverpilot daemon install --source-root "$PWD"
serverpilot daemon status
daemon install registers a user LaunchAgent that starts the uv tool
install, and is macOS-only.
For later local updates, sync this checkout to the source you want to run, then
use the complete update entry. It also requires the macOS Swift toolchain:
zsh desktop/update-macos-app.sh
This replaces the root ServerPilot.app and the canonical backend together,
restarts both, and verifies the running code by content build ID as well as
version. It cleans verified old App copies and requires one freshly launched
root App; a failed restart or mismatch fails the update. Existing data and GPU
workloads are preserved. The script deploys the current checkout; Git syncing
and version/tag releases remain separate actions. See the
upgrade checklist
(Chinese) for MCP-client and remote-helper follow-up.
Either way it listens on http://127.0.0.1:8787.
2. 🖥️ Register your GPU servers
Nothing is installed on the GPU servers. ServerPilot reads them with one fixed,
read-only SSH probe, so a server is ready as soon as you can reach it:
ssh user@host true # must succeed without a prompt
The probe runs in a non-interactive SSH session, which is where PATH
differs from the one you get logging in by hand. On a GPU host it expectsnvidia-smi to be on that PATH; a host without it is registered as a CPU-only
machine rather than rejected.
ssh user@host nvidia-smi -L # on a GPU host, must list the cards
Then add the SSH connection and an absolute remote working directory in the app.
A GPU becomes allocatable only after a fresh collection succeeds. Bare metal
uses the built-in linux observation profile, a fixed read-only SSH probe;
nothing needs to be installed on the remote host. The full contract is in
observation and keepalive (Chinese).
Do not register a shared cluster (Slurm, LSF, PBS) as bare metal. A local
plugin takes over observation so only your own jobs are registered, and
requests go through that plugin's apply / release. The bundledslurm-immediate plugin is the reference; there is no separate scheduler
submission surface. See
observation and keepalive
for the contract.
3. 🤖 Connect an agent
serverpilot mcp install --client codex     # or claude, cursor
serverpilot mcp policy --install --client codex
For Claude Code, mcp install asks whether agents may call these tools without
stopping for approval, and --allow-tools answers yes. Without it, Claude Code
can pause or, in auto mode, refuse a GPU release, which stalls unattended work.
It adds only mcp__serverpilot to ~/.claude/settings.json. Run it again on an
existing install to change your mind. Codex and Cursor keep their own approval
settings, which ServerPilot does not touch.
serverpilot mcp install only writes the launch command: Codex and Claude
Code get their mcp add, and Cursor is merged into ~/.cursor/mcp.json
without disturbing servers already there. It does not refresh a client's
cached tool list — reconnect the server (Cursor: Disable → Enable, or reload
the window) so it runs tools/list again.
To paste it yourself, serverpilot mcp config --client all prints the
registration without writing anything. The standard block is:
{
  "mcpServers": {
    "serverpilot": {
      "command": "serverpilot-mcp",
      "env": { "SERVERPILOT_URL": "http://127.0.0.1:8787" }
    }
  }
}
Full per-client notes are in the
Agent / MCP guide.
🤖 How an agent uses it
prepare code and data (no cards) → gpu_status → gpu_apply(duration_seconds=<expected seconds>, server_group_id=<group>, gpu_count=<launch config>, task="my task") → start the job at once → gpu_release(lease_id)
Apply only when the GPU job is ready to launch, never to reserve cards while
coding or debugging; release between runs that will not start soon.Routine apply is
gpu_apply(task, gpu_count=1, server_group_id?, server_id?, duration_seconds?, change?, take_over?, project?).
Repeating it is safe: it returns the same task's entry.change=truegrows or
shrinks a task, andtake_over=truetakes it from a session that is gone.gpu_countis exact job parallelism from the launch script or config. The
safe default is 1. Never infer it from free capacity.On a grouped host — bare-metal
director plugindelegated— passserver_group_id; the broker then best-fits one host inside that group.server_idis only for ungrouped hosts. A plugin-adapted cluster appears as
an ordinary group, withallocation,limits, andlargest_allocatable_block(one apply's max cards, not remaining pool size;nullmeans unknown — do not invent a number).Register hosts with
serverpilot endpoint addor in the app. Remove a server
in the app or REST, which refuses while it holds
active leases.Assess a group's workspace, environment notes, and data/weight notes before
claiming. Endpoints inherit the group workspace or override it. Environment
notes are descriptive only — they are not executed or injected.Allocatable capacity is grouped group → server → SKU (
name,vram_mib,total_count,available_count), not a per-free-card menu, and carries no
telemetry. Load observable on a free card comes from ServerPilot's own
keepalive hold, which is stopped before the card is handed over, so it is not
evidence that the card is busy. Telemetry follows the lease:gpu_status(task=…, telemetry=true)returns rolling ten-minute averages forleased_gpusplus aleasesummary (min_memory_free_mib,slowest_gpu)
for judging whether your own job is using the cards well.SSH in,
cdto the returnedcwd, then set the returnedenv.
That path is a working directory, not a code repository.Release immediately if CUDA fails to initialise or the workload does not
start.no_capacitymeans nothing was allocated and nothing was queued. It comes
back as data, not as an error, and it is not worth retrying in the same turn.
🖥️ The desktop app
The Settings page shows this installation's MCP entry as an absolute path
and the pasteable mcpServers JSON. Copy either into Codex, Claude Code, or
Cursor. If the executable is missing, the same panel says so and repeats the
install hint instead of inventing a path.
macOS
Install the CLI first — that is the backend. Then open the desktop app to
watch state, ownership, and failures. The app does not run its own control
plane.
open "./ServerPilot.app"
There is no browser UI.
Manual reassignment updates the lease and the CUDA selector; it does not
migrate a running process, so the agent has to restart its workload against the
new selector.
🛡️ Boundaries and security
- ServerPilot manages the lifecycle of its own occupancy processes and of
plugin-side allocations. It does not start, migrate, or preempt your
workloads. The one time it ends a process of yours is when you return a task
in the App and confirm: after checking each one, it stops the processes on
that task's cards that belong to the SSH login account (SIGTERM, then
SIGKILL ten seconds later). Keepalive starts and stops a per-GPU CUDA process on the remote
host that keeps that card's GPU utilization and VRAM use, and its share of the
server's host memory, at the targets set per server in the App (85% each by
default; host memory is shared out per card and given back when other
programs need it), andgpu_applystops it before handing the card over. A plugin that declaresapply/releaseperforms the
matching cluster allocation on request and release. - Server state comes from fixed collection: the built-in
linuxSSH probe (a
fixed read-only query, nothing installed on the remote), or a local plugin'sobserve. The plugin calling contract is fixed v5 verbs —info,observe,apply,release, and optionalconnect/disconnect. No arbitrary remote command is accepted, and no
password or private key is provided. See OBSERVATION_zh.md. - Stale collection, connection errors, unknown processes, and resource conflicts
all refuse allocation locally. That holds for what collection reports:
the SSH user is trusted, and for a delegated cluster the plugin executable is
trusted. A replaced or malicious plugin that omits compute processes will
make a card look allocatable. - The control plane listens on loopback by default. There is no
authentication.X-ServerPilot-Actoris an audit label; any local process
can send it, take theallocatorrole, create endpoints, change keepalive
policy, claim GPUs, or name another actor and release that actor's leases.
Local processes under the same user account are not isolated from each other.
GPU UUID and endpoint are the resource identity boundary.
📚 Documentation
In English:
- Agent operating rules — the short contract you
can paste into an agent's global rules - Security · Contributing · Code of conduct · Changelog
In Chinese:
- Agent / MCP guide
- Observation and keepalive
- Upgrade checklist
- Implementation and verification status
Reference documentation is currently written in Chinese, and so are the desktop
app and the descriptions an agent reads over MCP. This README, the changelog,
and the agent operating rules are the English surfaces today.
License
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found