CSCCD-MetagenomeFlow
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Gut-metagenome multi-kingdom analysis platform: 183-script + Snakemake pipeline, agent-driven mining loop, MCP visualization — VibeCoding-ready
CSCCD-MetagenomeFlow
A self-contained metagenomics platform that profiles gut bacteria, viruses, and fungi in parallel — from raw reads to publication-ready statistics — with built-in host-microbe mechanism discovery and an automation-assisted workflow.
Developed by the China-Saudi Arabia Joint Laboratory for Cardiovascular and Cerebrovascular Diseases.


180 scripts · 143 Snakemake rules · 57 conda envs · ~1.2 TB databases
Table of Contents
- Overview
- Quick Start
- Analysis Dimensions
- Evidence & Interpretation Layer
- Reliability Engineering
- Statistical & ML Validity
- Figure Gallery
- Script Index
- Repository Layout
- Disk Requirements
- Migrating to a New Server
- Tools & References
Overview
(The project was developed under the internal codename "mgx / MaxMetagenome" — tool names like mgx-vis and environment variables like MGX_FIGURE_FORMATS still use the short form. They refer to this repository, CSCCD-MetagenomeFlow.)
Most published pipelines handle one kingdom at a time, depend on cloud infrastructure, or don't reproduce cleanly across servers. This platform takes a different approach: bacteria (scripts 11–43c), virome (51–72), and mycobiome (71–86) run side by side under one script convention and one Snakemake DAG, on a single server, with everything installed locally.
Why it works:
- One preprocessing chain, three kingdoms. Shared QC and host-removal steps; per-kingdom analysis branches off cleanly. No glue scripts or format conversion between steps.
- Mechanism discovery is part of the pipeline, not an afterthought. The
mechanism_kbknowledge base carries 5,295 microbe → metabolite → host-gene relations (GutMGene v2.0 curated causal chains, OmniPath interactions, MicrobiomeKG 2025 cohort associations), each traceable to a publication. Queries like "which microbial functions produce butyrate and activate FFAR2?" resolve directly against it. - Runs anywhere. 57 conda environments and ~1.2 TB of databases live under the project root. A new server is
git clone+bash 0Install.sh. - Statistics-ready outputs. Script 98b writes 11 integration tables per dimension — raw TPM, relative abundance, and CLR — that plug straight into LEfSe, ANCOM-BC2, MaAsLin2, and SIAMCAT.
- Three run modes, one script layer. Step-by-step for debugging, Bash pipelines with
--from/--skipcheckpointing for lightweight runs, Snakemake for production. All three call the same scripts underneath.
Recent Updates
- pixi delivery layer (2026-10) —
envs-pixi/provides lockfile-based environment delivery (user-approved): 53/57 environments locked (50 build-level exact, 1 busco version-compromised, 2 Track-2 only). glibc and AVX-512 issues resolved via system-requirements and build relaxation. Delivery: dual-track — pixi lockfiles + symlink wiring (recommended) or conda-pack per-env archives (fallback). Seedocs/plans/2026-10-03_pixi_adoption_techspec.md. - Path normalization fix (2026-10-05) —
libcommon.shmgx_beginnow converts WORKDIR/REPO to absolute paths viarealpath -m, fixing a critical bug where relative paths caused nested outputs (HUMAnN 6-sample failure) and could bypass the Project01 production write guard.
Details:
git log v1.1.4-baseline..HEAD(private dev history)
v1.4.1 (2026-09-30 — 2026-10-01) — Integrity & governance hardening (internal fixes). Addendum — new CLI surface (96-input governance): script 96 gains --combination B/V/F/BV/BF/VF/BVF with shared BVF sample pools, per-block relative-abundance prefiltering, bacteria domain filter (k__Bacteria species rows only), virus input via 98c TPM columns, protocol-pinned 98d fungi source, a user-visible resume behavior change (mismatched combination/sample_set/fungi_method or pre-governance sentinels now error instead of silently reusing old results — re-run with --force), cross-cohort loader dimensional alignment (97 mirrors 96's bacteria regime + zero-fill fail-hard gate at 100% feature absence, filter counts stamped into metrics) (all internal fixes, no interface changes): antiSMASH chain triple-defect fix (empty-chunk binning, region-GBK flatten contract for 28b, short-contig prefilter) with permanent CI regression guards for all three failure-semantics defenses (T-11/T-22/T-24); cross-cohort validation chain rebuilt (nine defects: direction pinning, role-aware in-sample/external split, T-11 failure semantics, dual-arm reporting with uncorrected primary + MMUPHin sensitivity, meta-analysis delta-method SE, duplicate-ID guard, external-validation metrics with sample-name alignment); 98c fail-fast on missing vOTU identity map (was: silent 100% evidence drop); repository hygiene (CCMetagen retired end-to-end, 946 tracked run-artifacts untracked, 1.66 GiB dangling objects reclaimed, E-5 archival batch with RAG rebuild); engineering governance (review review channel with 20+ gate audits, three-gate pre-commit hook with self-healing install, pip-only package inventory v3, PYTHONNOUSERSITE isolation, absolute database freeze with mechanical guards); RAG benchmark governance (two-tier release standard, baseline v2, freshness clause).
v1.4.0 (2026-09) — Evidence & interpretation layer + ML validity: Phase 2 evidence layer closed (taxonomy cross-validation, virome host/detection/AMG evidence contracts, cross-domain edge contract, DA consensus views); antiSMASH chunked execution adopted in production script 28; Phase 3 opened with subject-aware CV, reproducible split manifests and full metrics panel (PR-AUC/sensitivity/specificity); production write guard for Project01; global rename to CSCCD-MetagenomeFlow; review review channel + user governance rules (path hygiene, DB freeze, doc sync).
v1.3.0 (2026-09) — First public release. mgx-vis CLI bridge visualization module (publication PDF+PNG, CNS design system, 14-figure gallery reproducible from synthetic demo data); agent-driven metagenome mining loop; GitHub publishing pipeline with leak verification; environment lock manifests.
v1.2.1 (2026-09) — Cleanup & RAG expansion: ~770 GB reclaimed; antiSMASH 8 full re-run (regions +41.5%); literature_kb 5.7x; mechanism_kb +435 records; BugSigDB signature_kb added.
v1.2.0 (2026-09) — Engineering hardening: shared script library (-2,300 lines, shellcheck clean), antiSMASH 8 / SemiBin 2.5, metaSPAdes + PhaStyle opt-in tracks, remote CI, dual-model routing.
v1.1.4 (2026-09) — Binning-chain data-integrity remediation; Project01 MAG set rebuilt.
v1.1.3 (2026-09) — MetaX cross-domain verification layer; configurable kingdoms.
Earlier versions — see git history.
Quick Start
# Activate (required before every session)
source scripts/activate.sh

# First time on a new server only
bash scripts/checkm_config.sh
Install Footprint
What bash 0Install.sh (default INSTALL_MODE=online, official sources) costs on a fresh machine — all figures are order-of-magnitude:
| Resource | Scale |
|---|---|
Disk — conda envs (miniforge3/ + envs/, 57 environments) |
~60 GB |
Disk — databases (db/, 58 database directories) |
~1.2 TB |
| Network download | ~0.5–1 TB total, dozens of official sources |
| Wall time | hours at 100 MB/s sustained; days on slower links (database downloads dominate) |
With a local database bank (INSTALL_MODE=bank + DB_BANK/SIBLING_DB), the database stage collapses to local copies. Per-database provenance: docs/manifests/databases.yaml; per-env software locks: docs/manifests/envs/.
Zero-database demo path: bash mcp/vis/build_gallery.sh renders the full figure gallery with only the r_stat env — no db/ content required.
Run Modes
Step-by-step — debugging, fine-grained control:
bash scripts/01_qc_fastp.sh       -s SAMPLE_ID -t 16 -w /path/to/project -r ~/Course/CSCCD-MetagenomeFlow
bash scripts/02_qc_kneaddata.sh   -s SAMPLE_ID -t 16 -w /path/to/project -r ~/Course/CSCCD-MetagenomeFlow
Bash pipeline — lightweight, checkpointed:
bash scripts/00_pipeline_bacteria.sh -i samplesheet.csv -r ~/Course/CSCCD-MetagenomeFlow -t 16
bash scripts/00_pipeline_bacteria.sh -i samplesheet.csv -r ~/Course/CSCCD-MetagenomeFlow -t 16 --from metaphlan4   # resume
bash scripts/00_pipeline_bacteria.sh -i samplesheet.csv -r ~/Course/CSCCD-MetagenomeFlow -t 16 --force              # re-run
Snakemake — production, large cohorts:
# Edit pipeline/config/config.yaml: samplesheet, workdir, threads_per_job, max_jobs
snakemake -s pipeline/Snakefile --configfile pipeline/config/config.yaml --dry-run
snakemake -s pipeline/Snakefile --configfile pipeline/config/config.yaml -j 4 --rerun-incomplete
Optional step monitor — append --monitor to a bash pipeline (or export MGX_MONITOR=1 before any step script) and every hooked step appends a start/end event pair to {workdir}/logs/run_events.jsonl (start events carry exit_code=-1 as the "running" marker; negative values can never collide with real exit codes 0-255). Default off; never alters exit codes or stdout. Get a plain-text snapshot anywhere (cloud-friendly; ask the coding agent to run it and relay): python3 scripts/utils/run_monitor.py <workdir> --text (one-shot, prints running steps plus the last finished steps with script path, purpose, parameter legend and outputs); --follow keeps appending in a real terminal/tmux. Render a self-contained HTML dashboard with python3 scripts/utils/run_monitor.py <workdir> --watch, or serve it in real time with python3 scripts/utils/run_monitor.py <workdir> --serve [--port 8790] (SSE push, loopback-only: running steps appear as 运行中 cards the moment they start and flip to their final state within <1s of finishing; card commands are rebuilt from events, not copy-paste ready). On a remote/cloud server, reach the live dashboard through an SSH tunnel with matching local port (ssh -N -L 8790:127.0.0.1:8790 user@host; a different local port is rejected with 403 by the Host allowlist) — see Tutorial.md for the zero-config --watch fallback. Mode 3 (Snakemake): set monitor: true in pipeline/config/config.yaml (or run MGX_MONITOR=1 snakemake ...); the Snakefile then appends pipeline-level start/end events alongside every hooked step event in the same jsonl, and the dashboard header shows the run's final status. Snakefile load-time failures (e.g. samplesheet validation) are not covered — see the snakemake log for those.
Analysis Dimensions
| Dimension | Scripts | Pipeline script |
|---|---|---|
| Bacteria | 11–43c | 00_pipeline_bacteria.sh |
| Virome | 51–72 | 00_pipeline_virome.sh |
| Mycobiome | 71–86 | 00_pipeline_fungi.sh |
| Statistics | 91–98 | — |
| Full chain | 01–98 | 00_pipeline_full.sh |
Bacteria
QC → host removal → two parallel branches. Read-based profiling: MetaPhlAn4, StrainPhlAn4, HUMAnN3, Kraken2, Centrifuger, sylph, MetaX. Assembly-based: MEGAHIT assembly → Prodigal gene prediction → CD-HIT catalog → Salmon quantification. The gene catalog feeds pooled annotation (eggNOG, KEGG, AMRFinder, CARD, dbCAN3, VFDB, BacMet, antiSMASH, Defense-Finder, NCyc/PCyc/SCyc, Pfam, UniProt, FeGenie); per-sample contigs feed MAG recovery (CoverM → MetaBAT2/MaxBin2/SemiBin → DAS_Tool → CheckM2 → dRep → GTDB-Tk → Prokka, plus inStrain strain tracking, MLST, Roary pan-genome, Snippy SNPs, MGE/plasmid annotation, and gapseq/CarveMe/COBRApy metabolic modeling). Everything converges in script 98b's integration tables.
Virome
QC → host removal → MEGAHIT → geNomad + VirSorter2 → CheckV quality filter (MIUVIG standard) → Prodigal-gv. Then either the read-based vOTU track (vclust clustering → geNomad taxonomy → Salmon quantification → vOTU tables) or vMAG reconstruction (vRhyme → CheckV → CoverM). Annotation: PHAROKKA, PHOLD, VOGDB, BACPHLIP, PhaGCN3, PhaStyle, iPHoP host prediction, vConTACT3, DRAM, PhaBox2.
Mycobiome
Multiple taxonomic profilers cross-validate each other: Kraken2, MetaPhlAn4-euk, HUMAnN4-fungi, BLAST against the gut-fungus database, FunOMIC, MicroFisher, and the PHF profiler (760 gut fungal genomes, Yan et al. 2024 Cell). Downstream: fungal assembly → Eukfinder → Tiara/BUSCO QC → MetaBAT2 binning → MetaEuk protein prediction → eggNOG/KEGG/dbCAN/VFDB/AMR/MEROPS annotation.
Statistics
Diversity (91), differential abundance (92, 99b LEfSe), co-occurrence networks (93, FastSpar), visualization (94), batch correction and evaluation (95a/b, 10 methods), functional profiling across 20 dimension × type combinations (96 series), cross-cohort replication (97), snapshot reports (98). phyloseq objects for each kingdom feed all downstream R packages directly.
Evidence & Interpretation Layer
Every reported result carries traceable evidence — what was observed, by which method, at what resolution, and how strongly it may be interpreted.
- Quantification contract (
docs/QUANTIFICATION_CONTRACT.md): every abundance output is registered as entity × quantity × unit × normalization (gene TPM, vOTU TPM, MAG coverage, relative abundance, fungal read counts...); cross-unit joins are explicitly forbidden (MetaPhlAn 0–100 vs fraction 0–1 must be converted on purpose). - Taxonomy identity contract (
docs/TAXONOMY_SCHEMA.md): taxon names never travel without their system + rank + release context (GTDB R214/R220/R226 and NCBI-style sources stay distinct; no cross-system string joins). - Evidence sidecars (one row per raw evidence record, never collapsed by summaries): viral host evidence (sequence-linked CRISPR / genome alignment / model prediction with independence groups), detection caller consensus, AMG evidence with auxiliary-score provenance (native vs schema placeholder), fungal multi-source detections with low-support heuristic flags, cross-domain edges with
edge_type ≠ evidence_type ≠ score_type ≠ interpretation_status. - Provenance columns in integration tables: annotation evalue/bitscore/method per database, MAG quality profile (N50/GC/GUNC/source binner), gene→contig→MAG→sample traceability.
- Honest-state semantics:
RAW_EVIDENCE_ONLY,UNKNOWN,NOT_ASSESSED,UNMAPPEDare first-class outputs — evidence is preserved even when no frozen rule exists to rate it (e.g. host sequence evidence stays un-rated until an acceptance threshold is formally adopted).
Reliability Engineering
- Chunked antiSMASH execution (validated on a 284 Mb assembly: identical BGC universe, 289/289 regions): full-record chunks with per-chunk DONE/FAILED sentinels, merge gated on all-chunks-success. (Reruns currently rebuild all chunks; per-chunk resume is a registered backlog item, not yet implemented.)
- Failure semantics: tool failures never masquerade as "completed with no result" (explicit FAILED markers; downstream consumers refuse them).
- Production write guard: destructive re-runs against production project directories are blocked by default and require an explicit environment override.
- Input validation at every entry: sample sheets are checked for duplicates, illegal IDs and missing reads before any compute starts (bash and Snakemake entries alike).
Statistical & ML Validity
- Subject-aware cross-validation: when metadata carries subject/patient IDs with repeated sampling, train/test splits are grouped so one subject never straddles folds (with a persisted split manifest: seed, effective folds, split unit).
- Full evaluation panel beyond AUC: PR-AUC, sensitivity, specificity, PPV and binned calibration error are exported for every model.
- Differential-abundance consensus view: multi-method results are reported side by side (effect size + type, direction, FDR, prevalence, n) with direction-consistency flags — never collapsed into a single vote.
Figure Gallery
All figures below share one CNS-style design system (mcp/vis/cns/theme_cns.R: 0.3pt axes, Arial size hierarchy, muted Nature/NEJM-leaning palette, 89/183mm column widths, 600 dpi) and are drawn from a synthetic 24-sample demo project — no real data is used or distributed. The set is designed to composite directly into multi-panel figures. Every figure is stored in docs/figures/ in both PDF and PNG (except the natively interactive Krona HTML). The entire gallery is reproducible with one command:
bash mcp/vis/build_gallery.sh            # CNS style (default), ~3 min
                                         # --with-ml adds ML figures (~7 min)
                                         # --orbit0 keeps the raw pipeline-script style
The same figures can be rendered on demand for any real project through the mgx-vis CLI bridge server (vis_scan / vis_render / vis_mining) from any agent session; each CNS renderer is also a standalone script (Rscript mcp/vis/cns/fig_<name>.R <workdir> <out_dir>).
| Composition & network | Diversity | Differential & biomarkers |
|---|---|---|
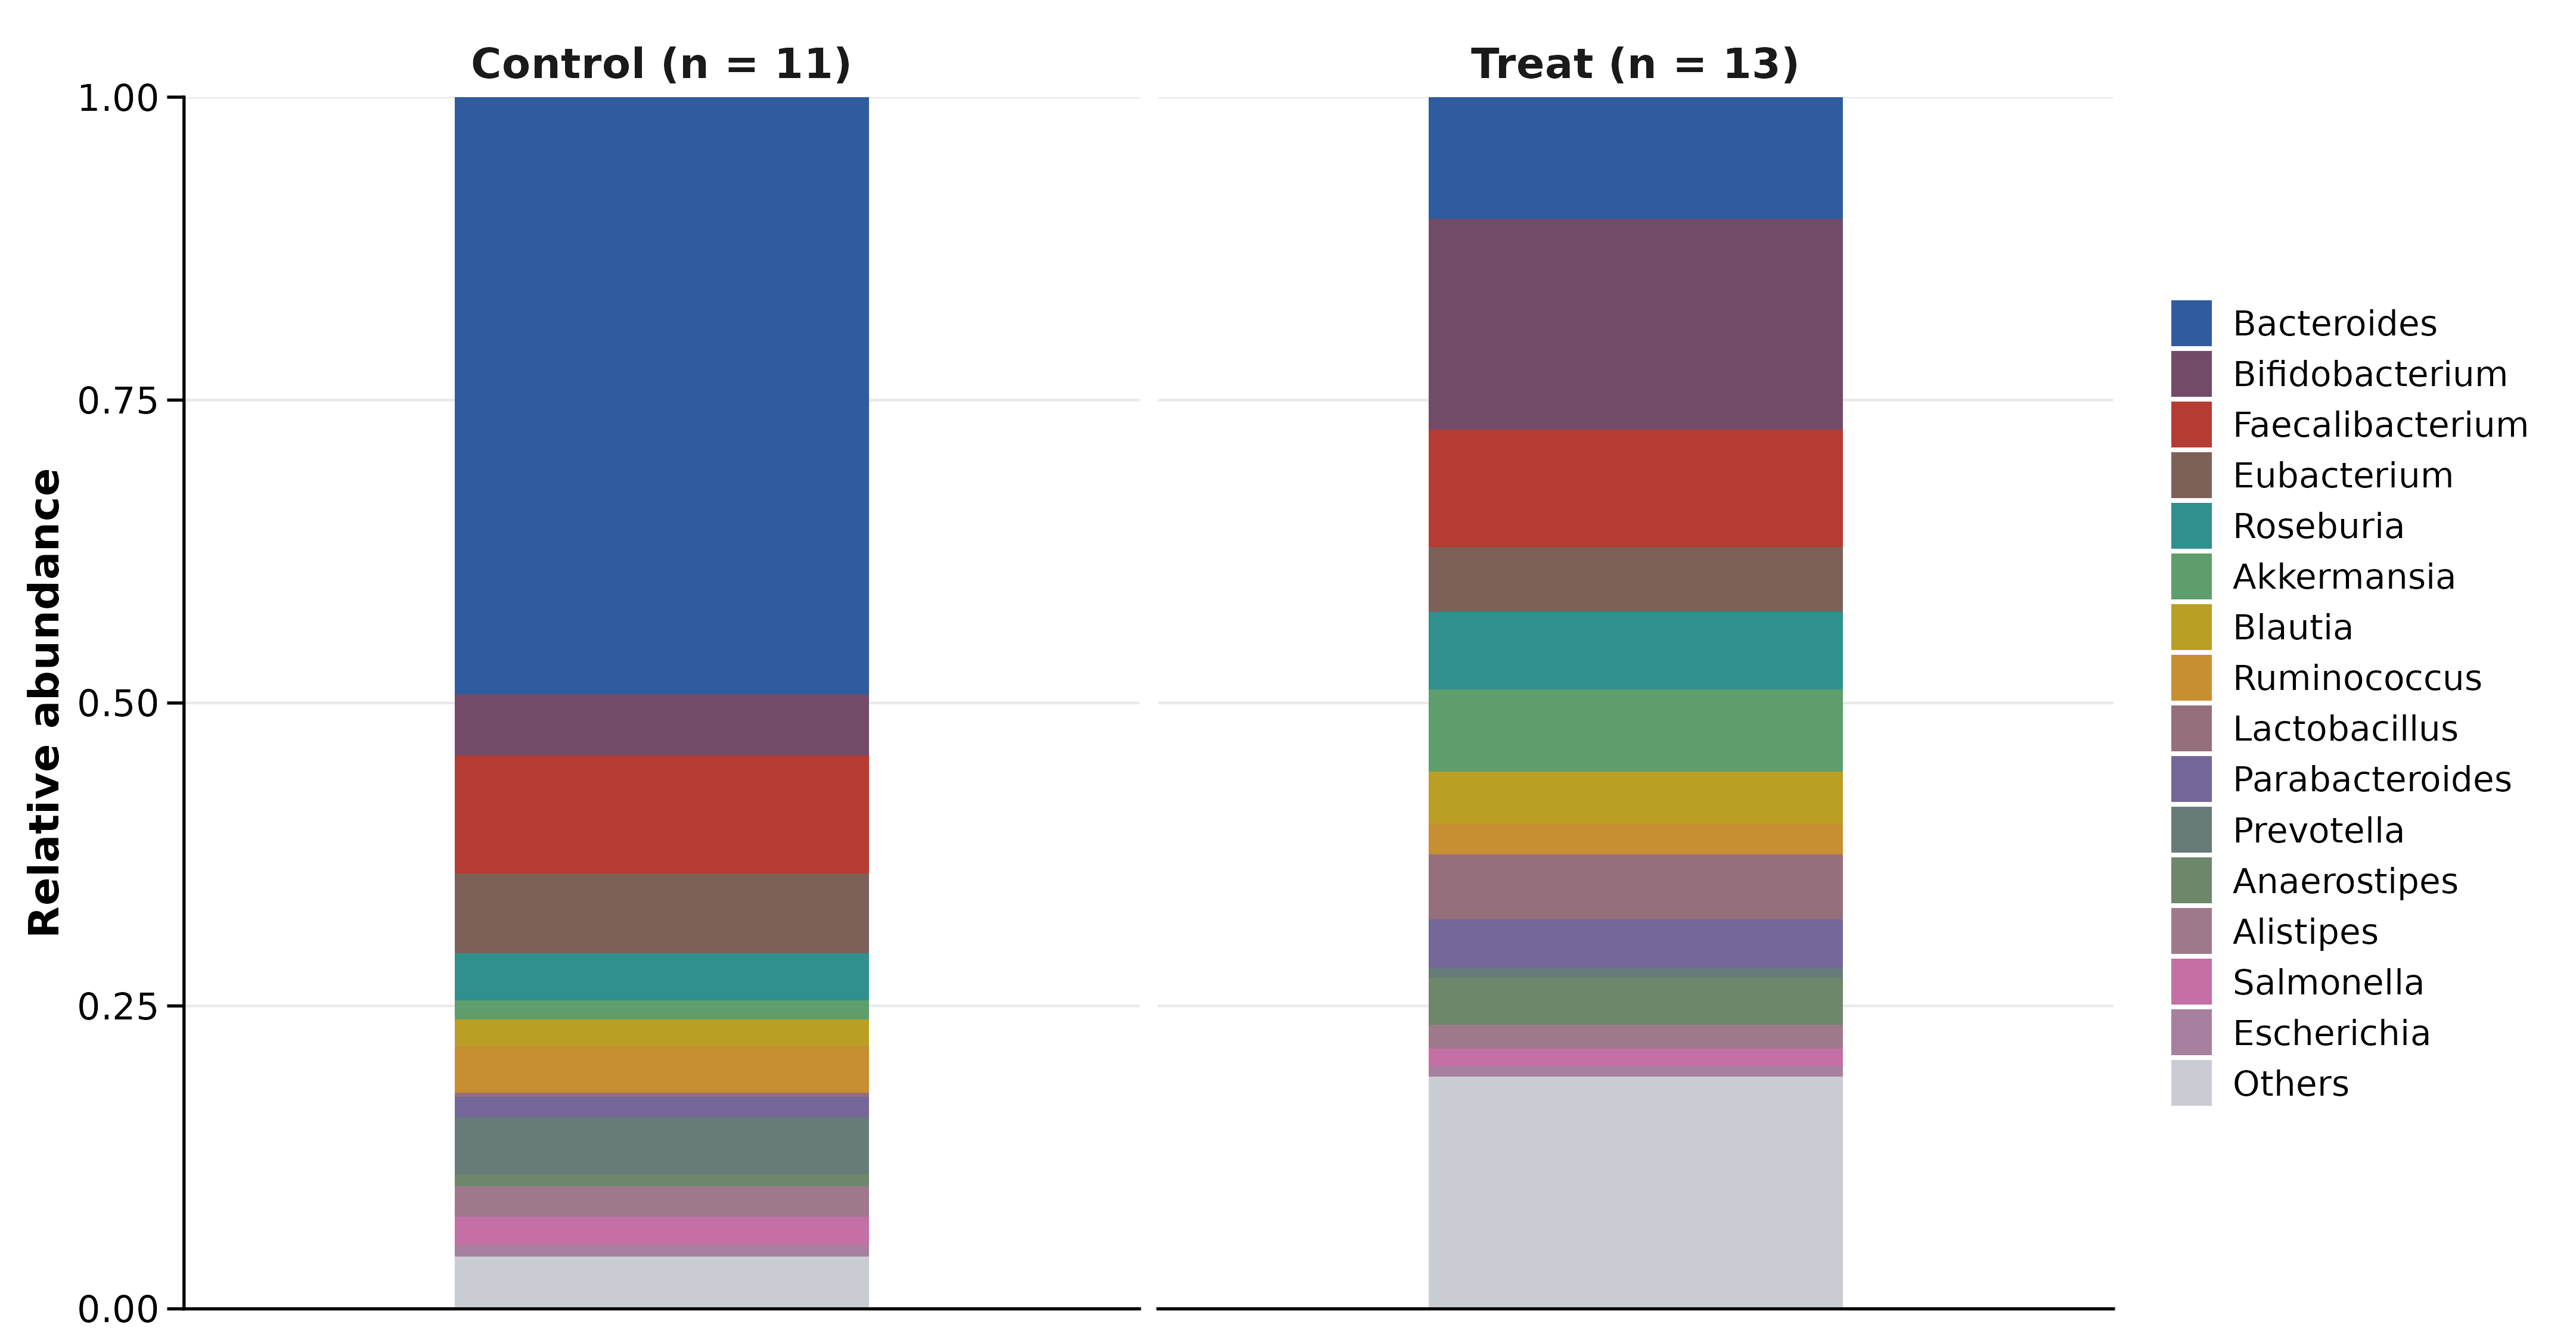 Composition barplot (94) |
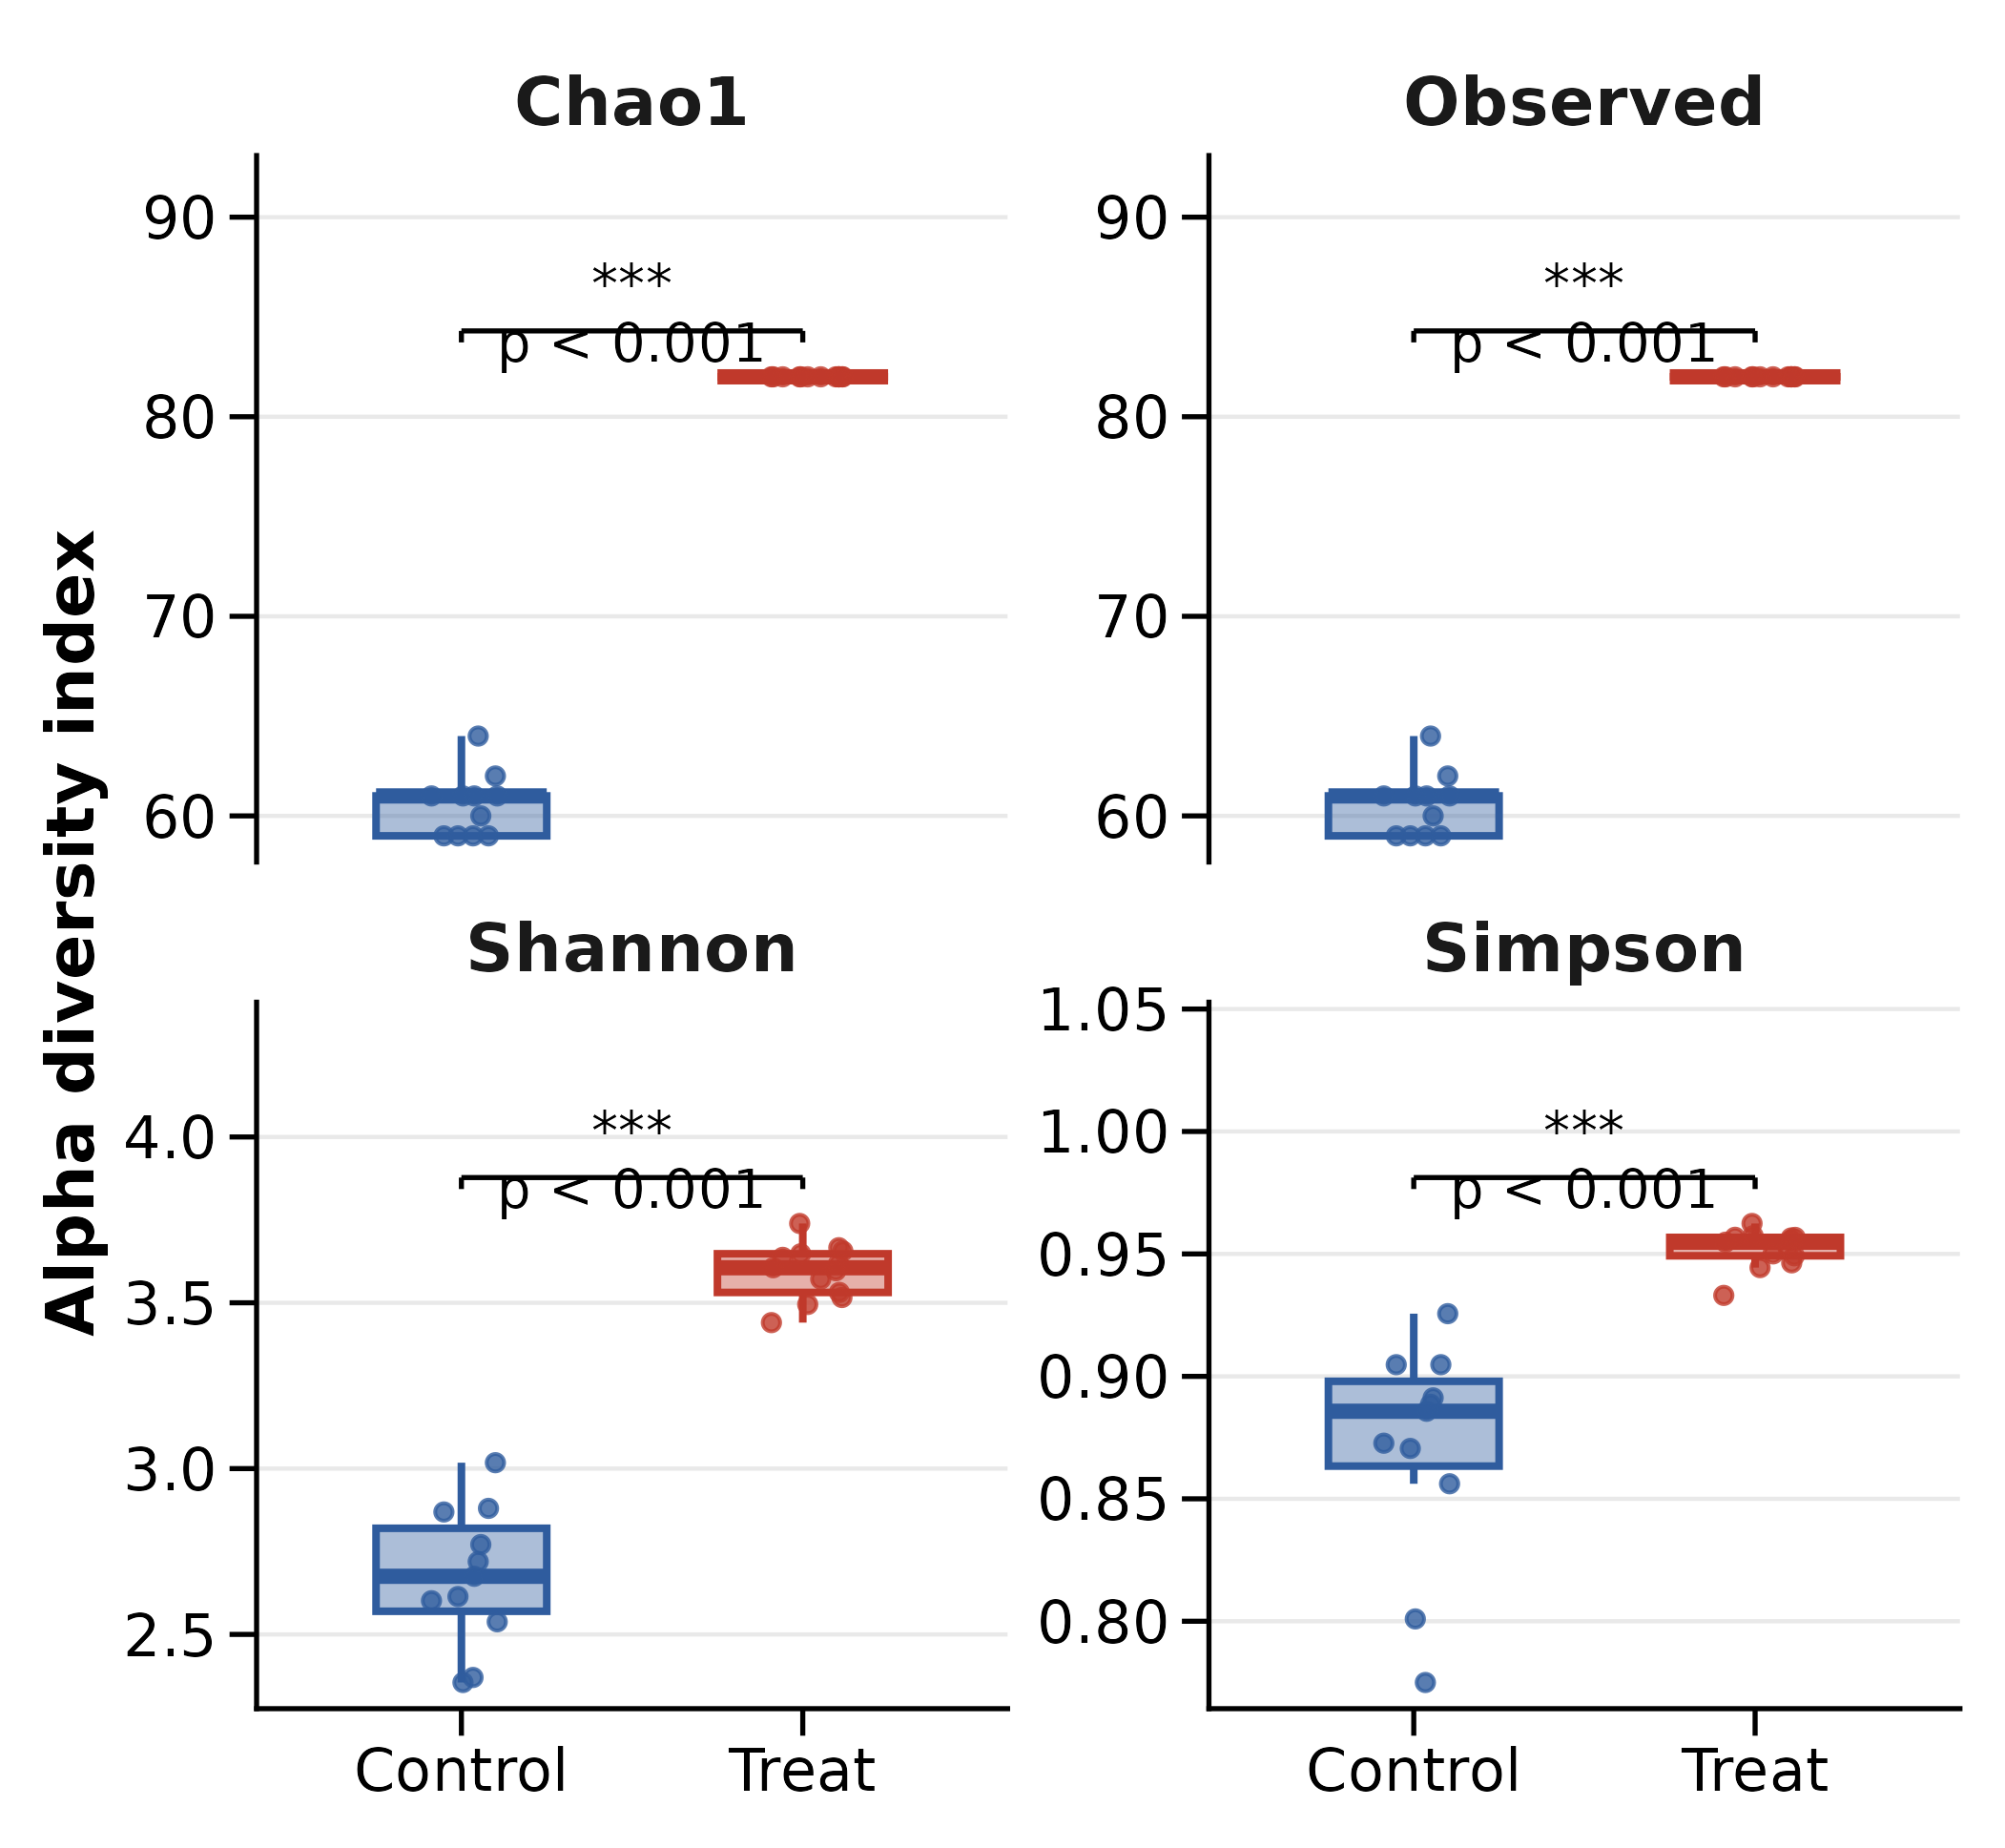 Alpha diversity (91) |
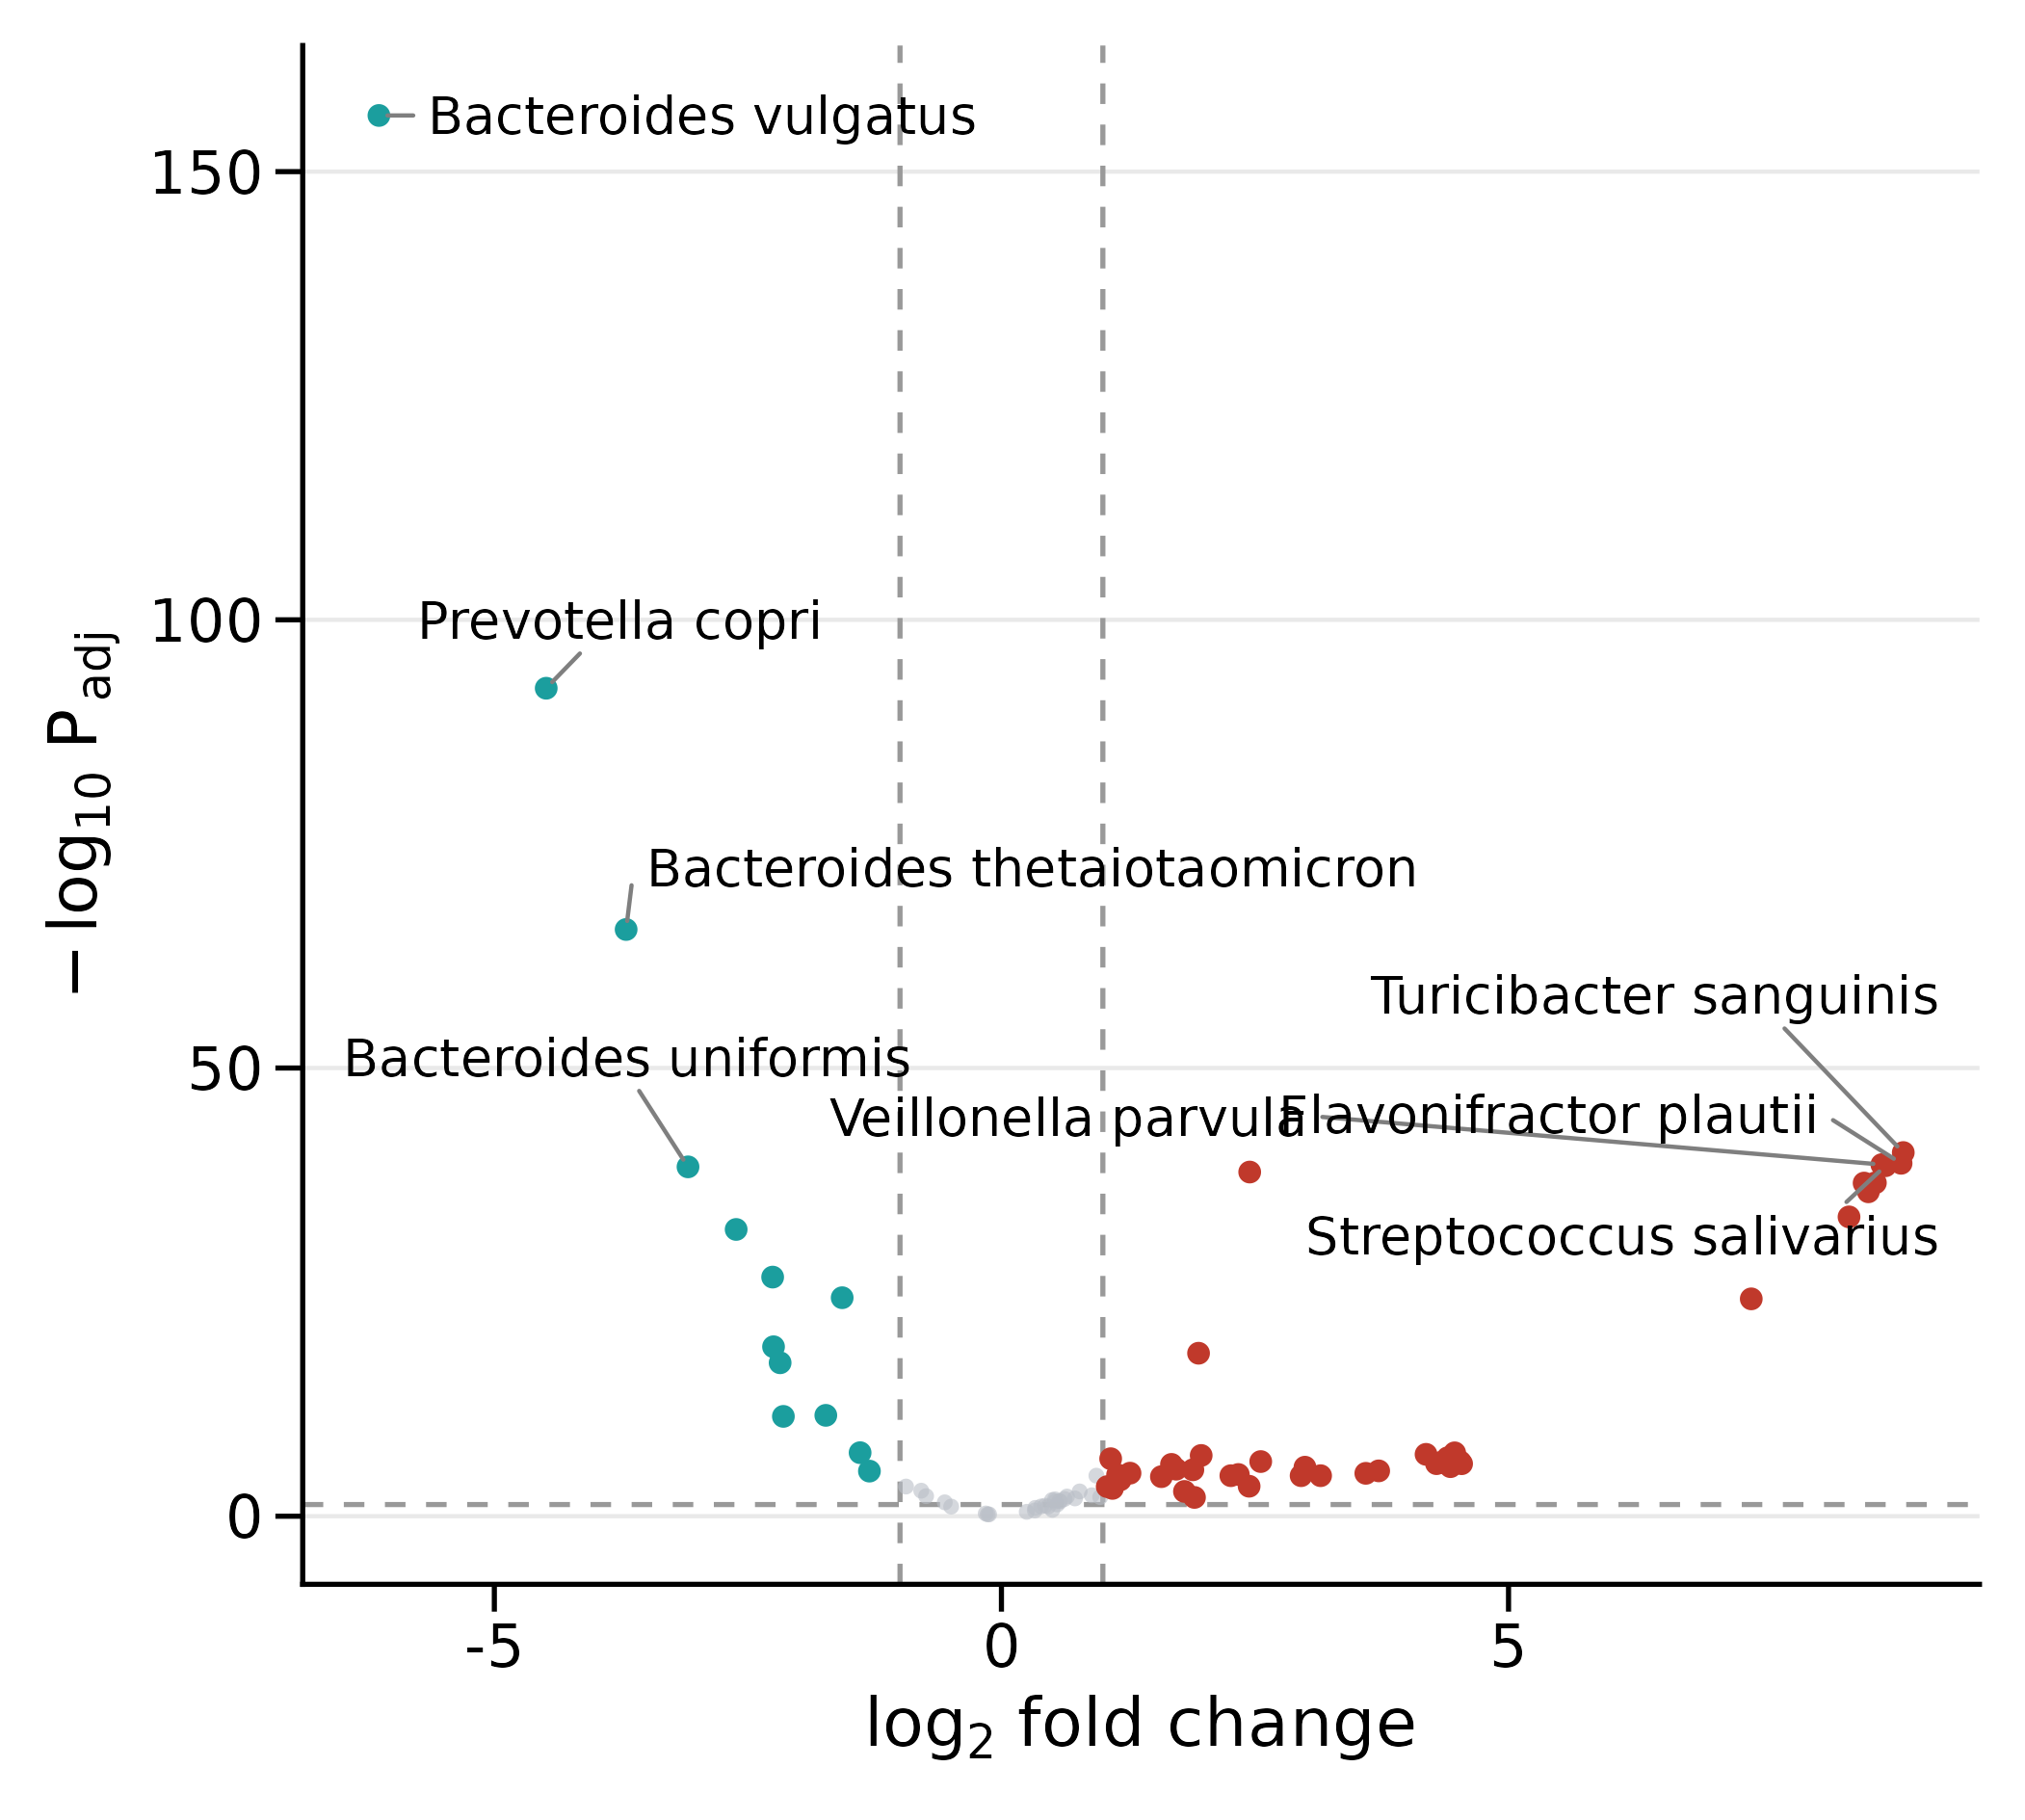 Volcano (92) |
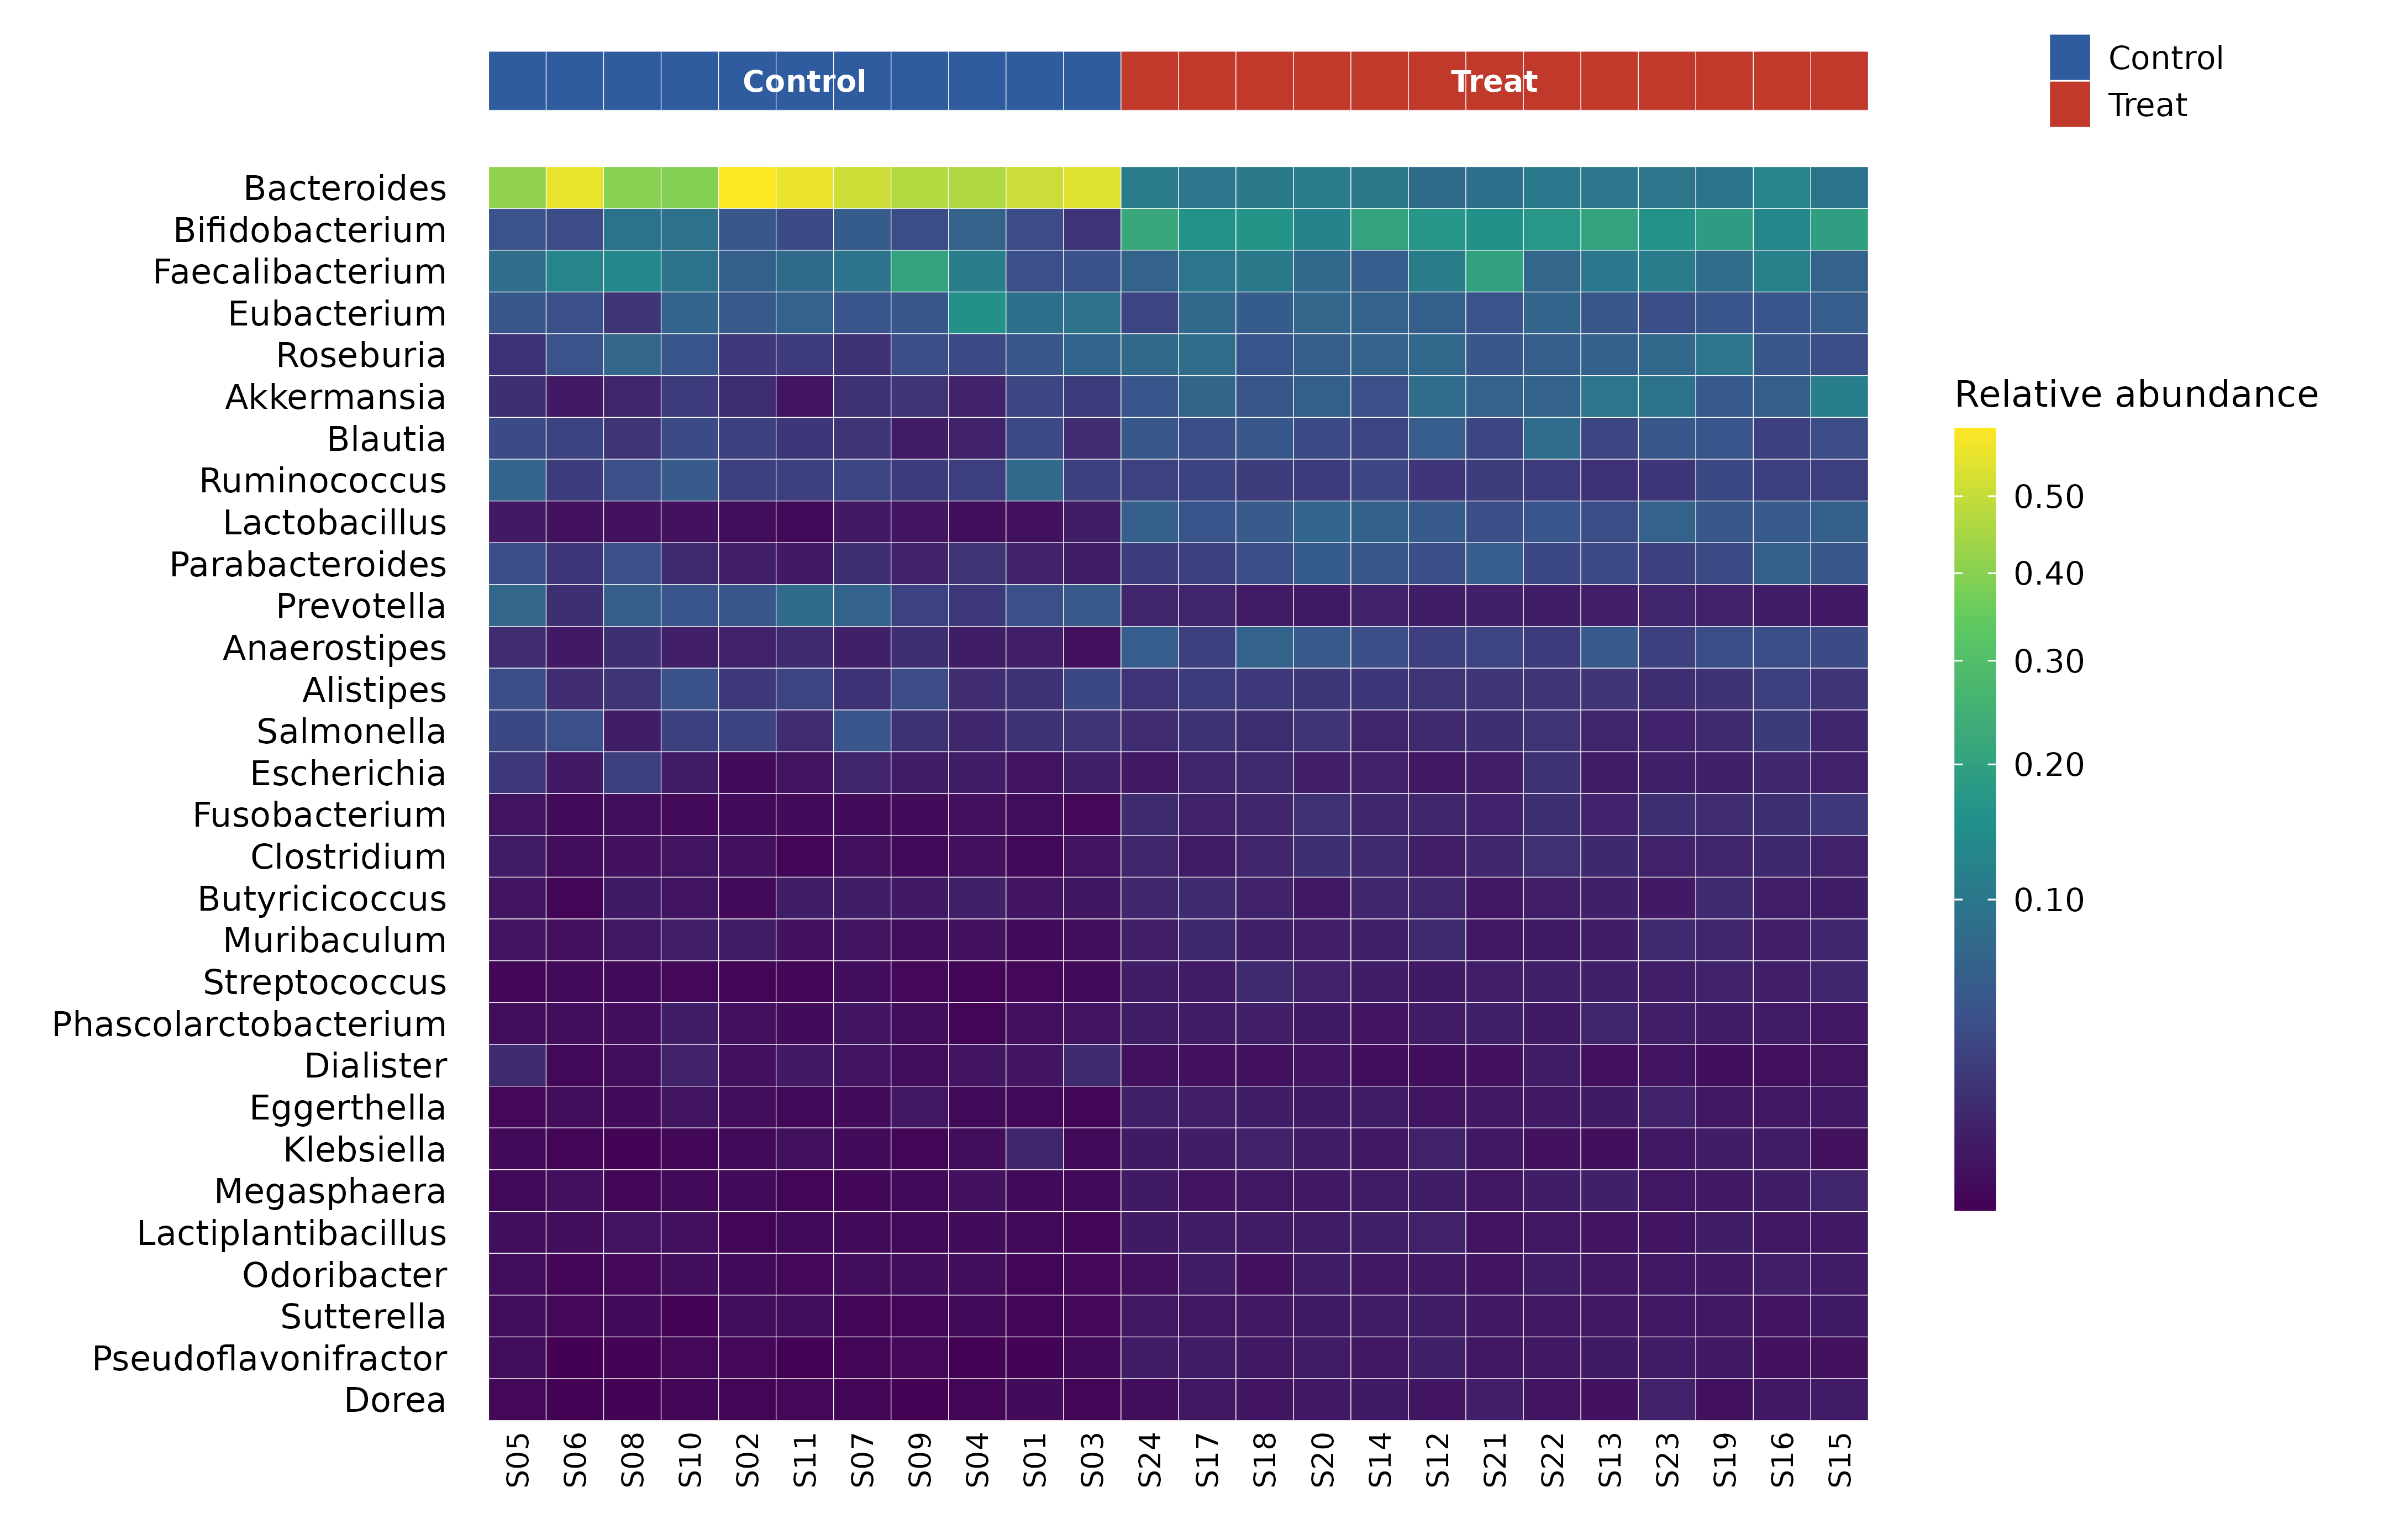 Genus heatmap (94) |
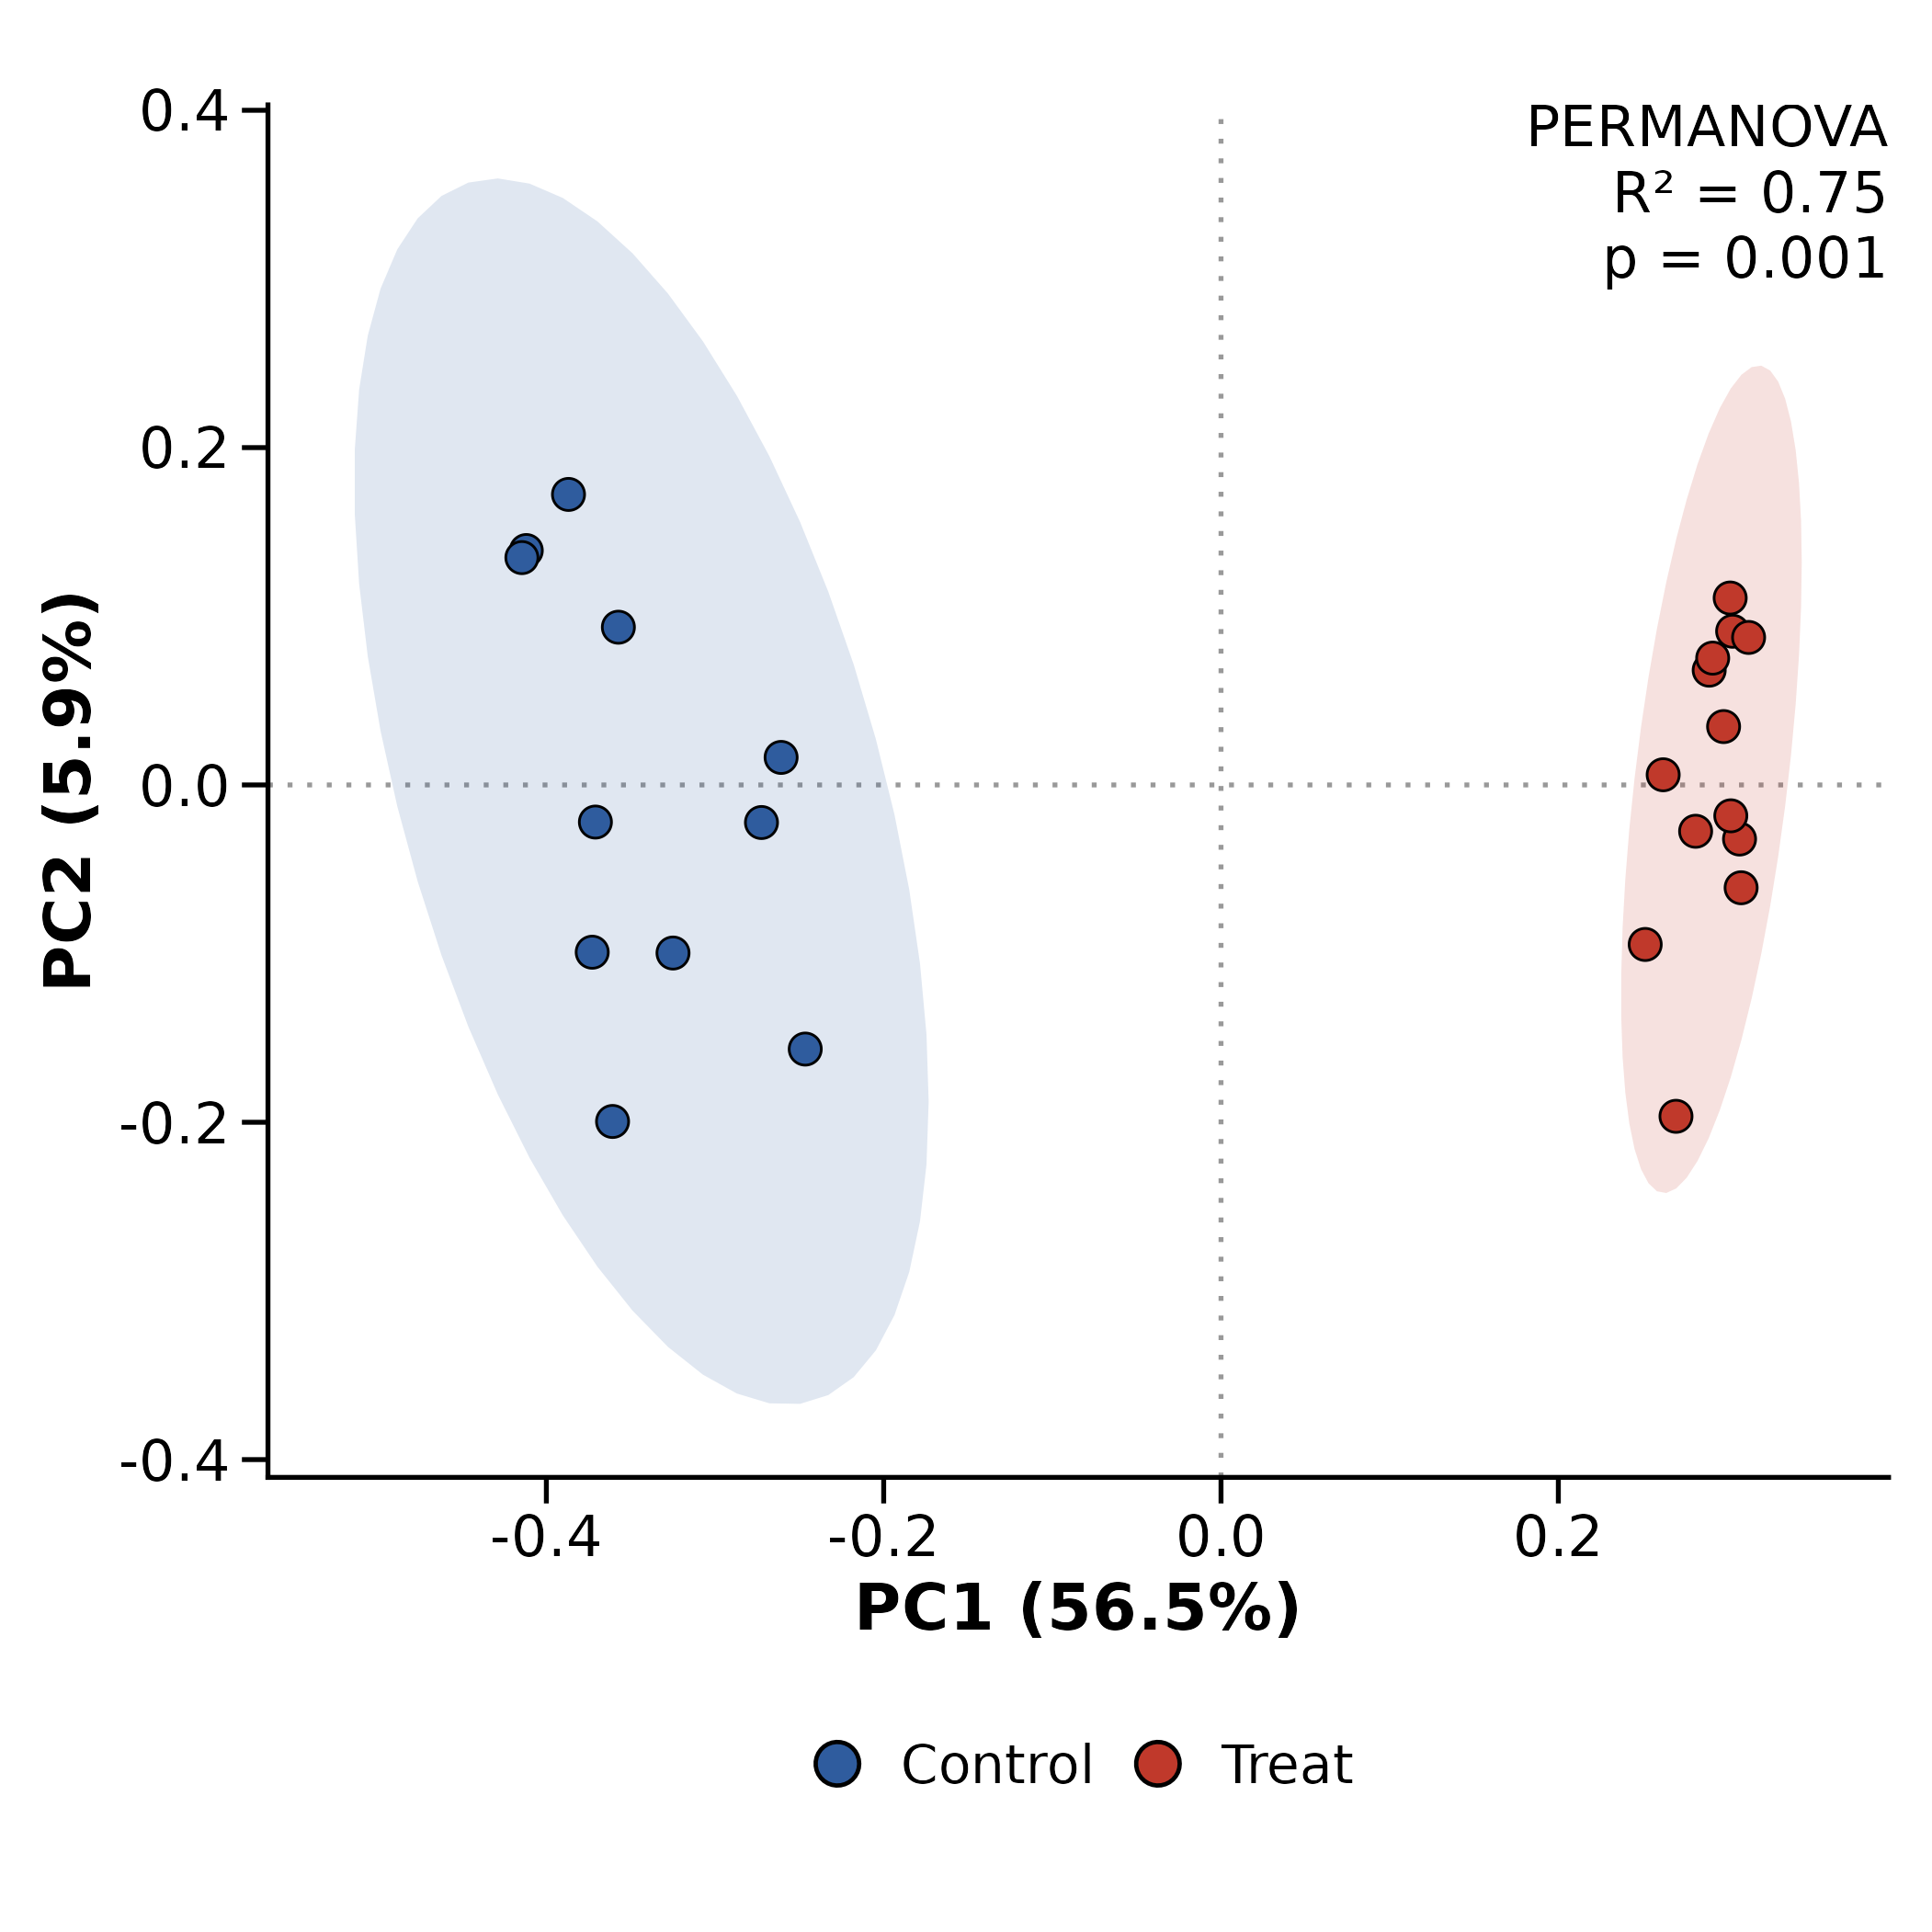 PCoA + PERMANOVA (91) |
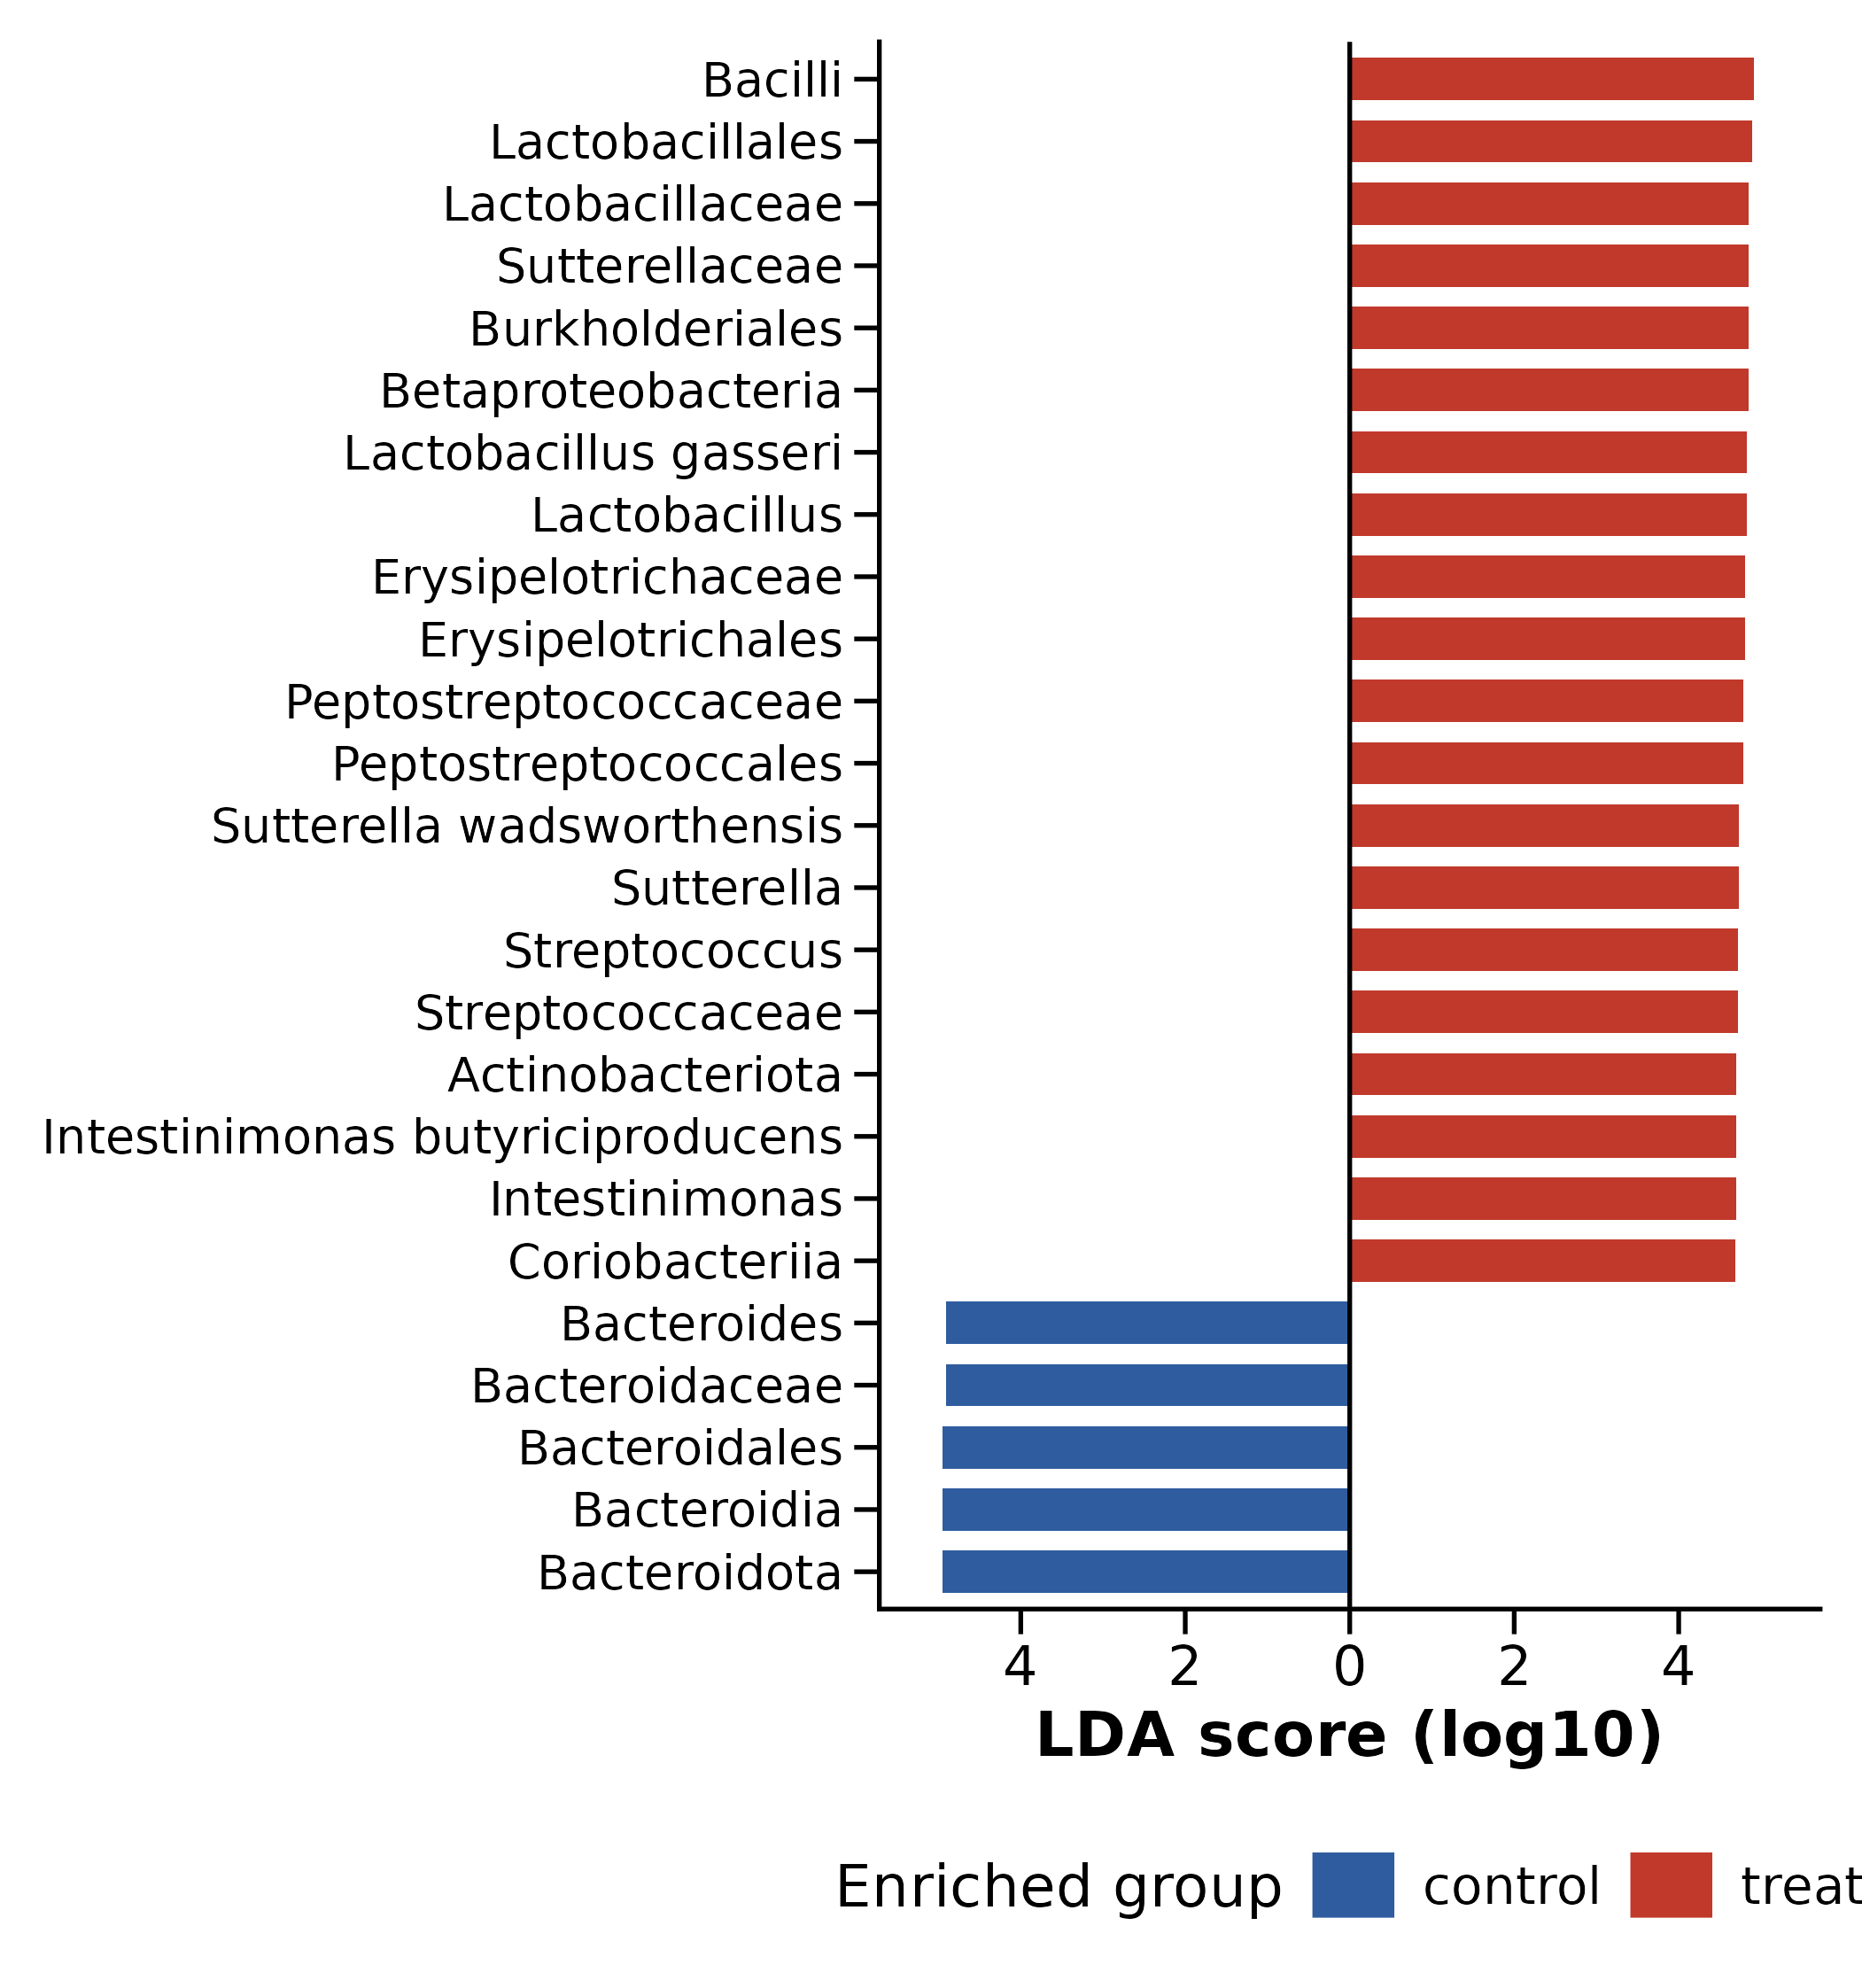 LEfSe LDA (99b) |
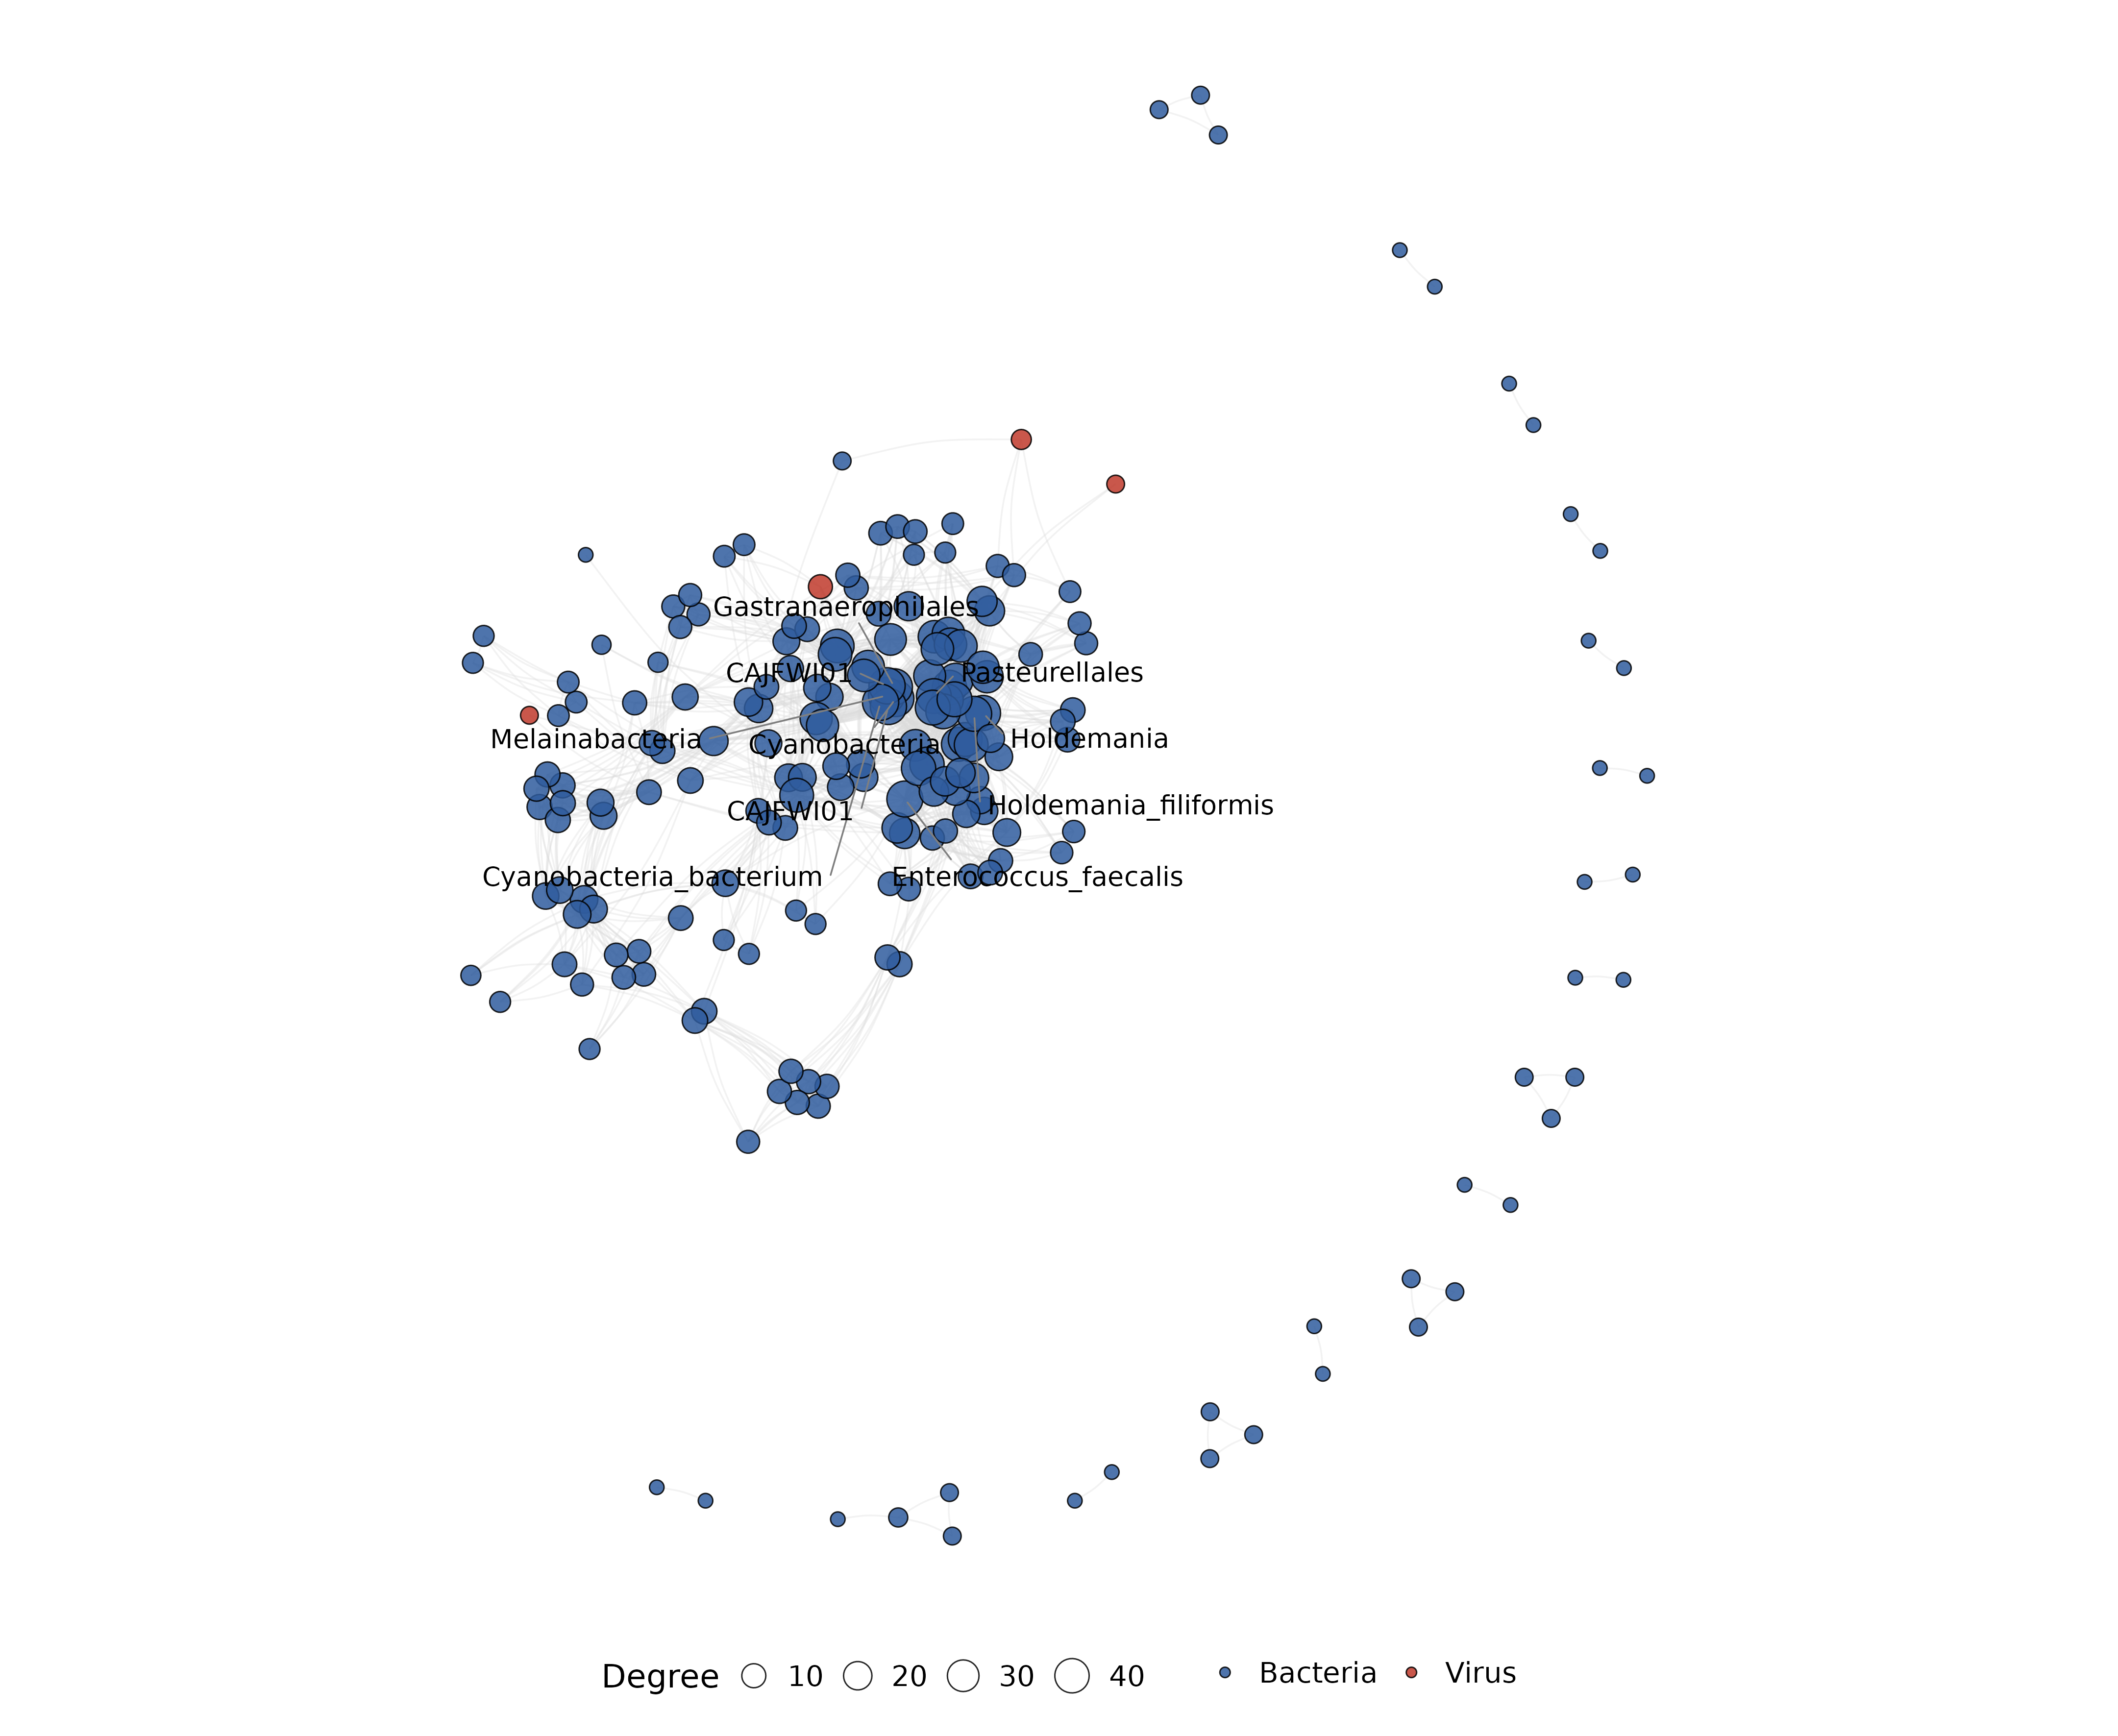 Cross-kingdom network (93) |
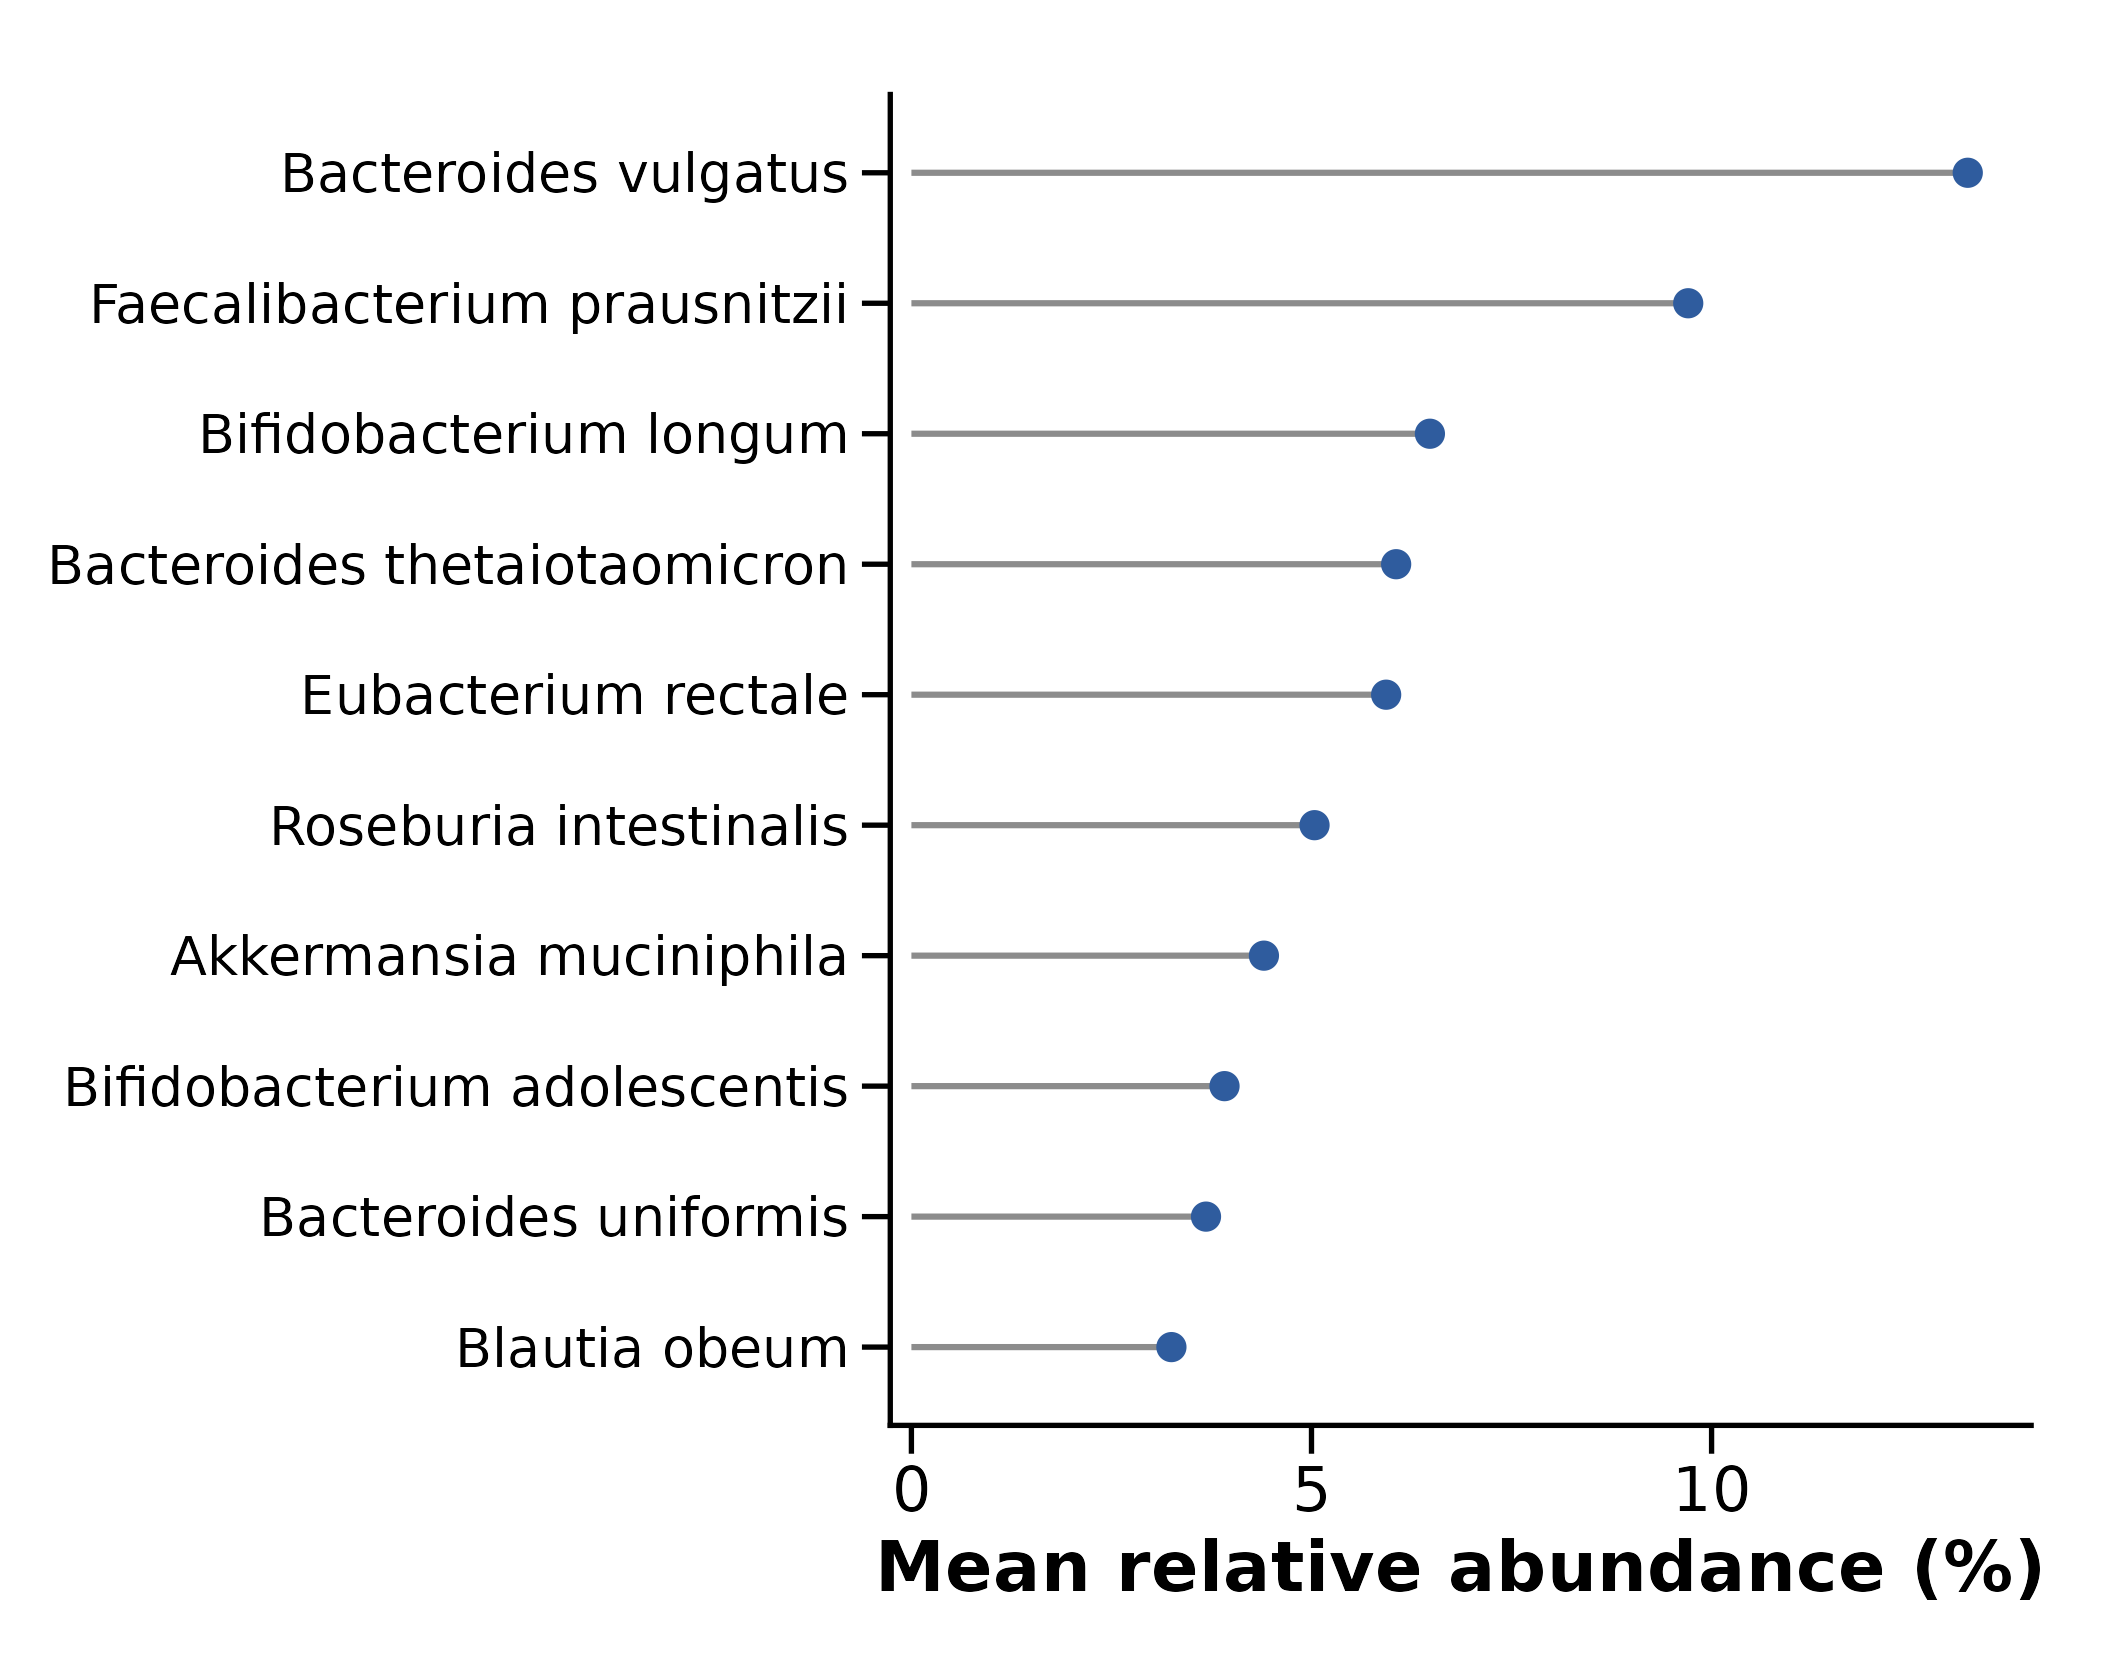 Core microbiome (99a) |
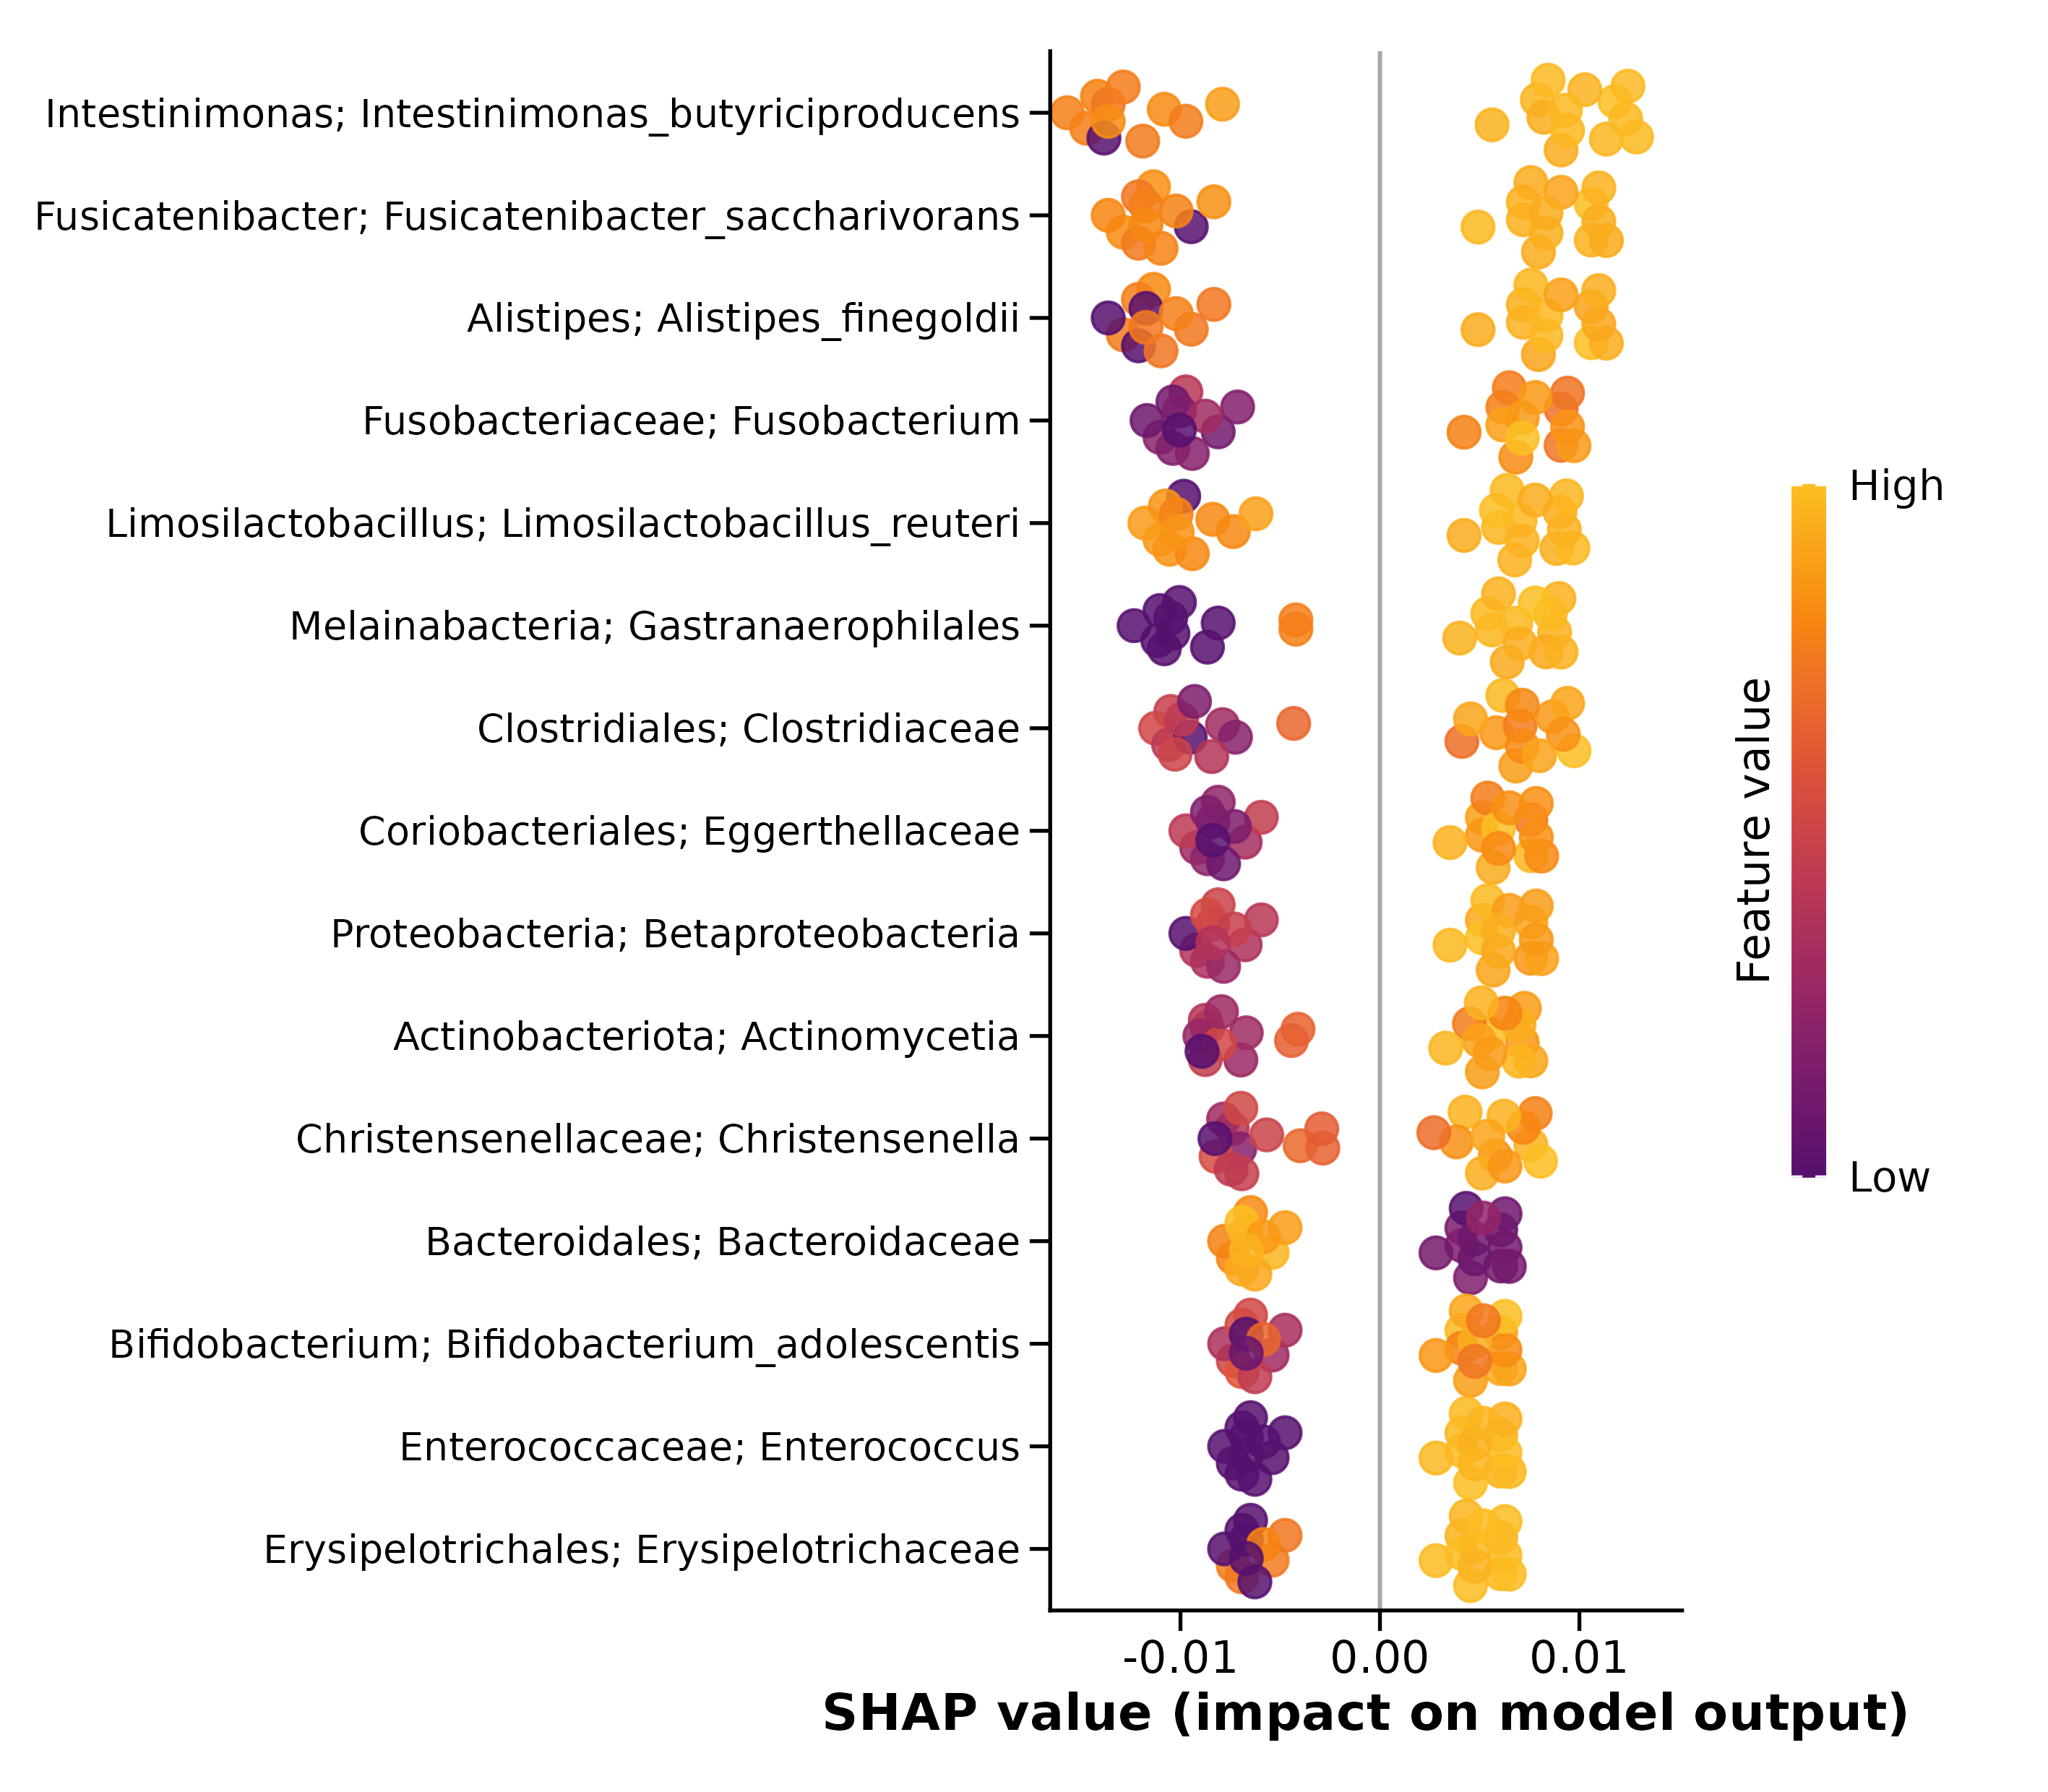 SHAP summary (96) |
| Functional profiling | Data mining registry | Interactive |
|---|---|---|
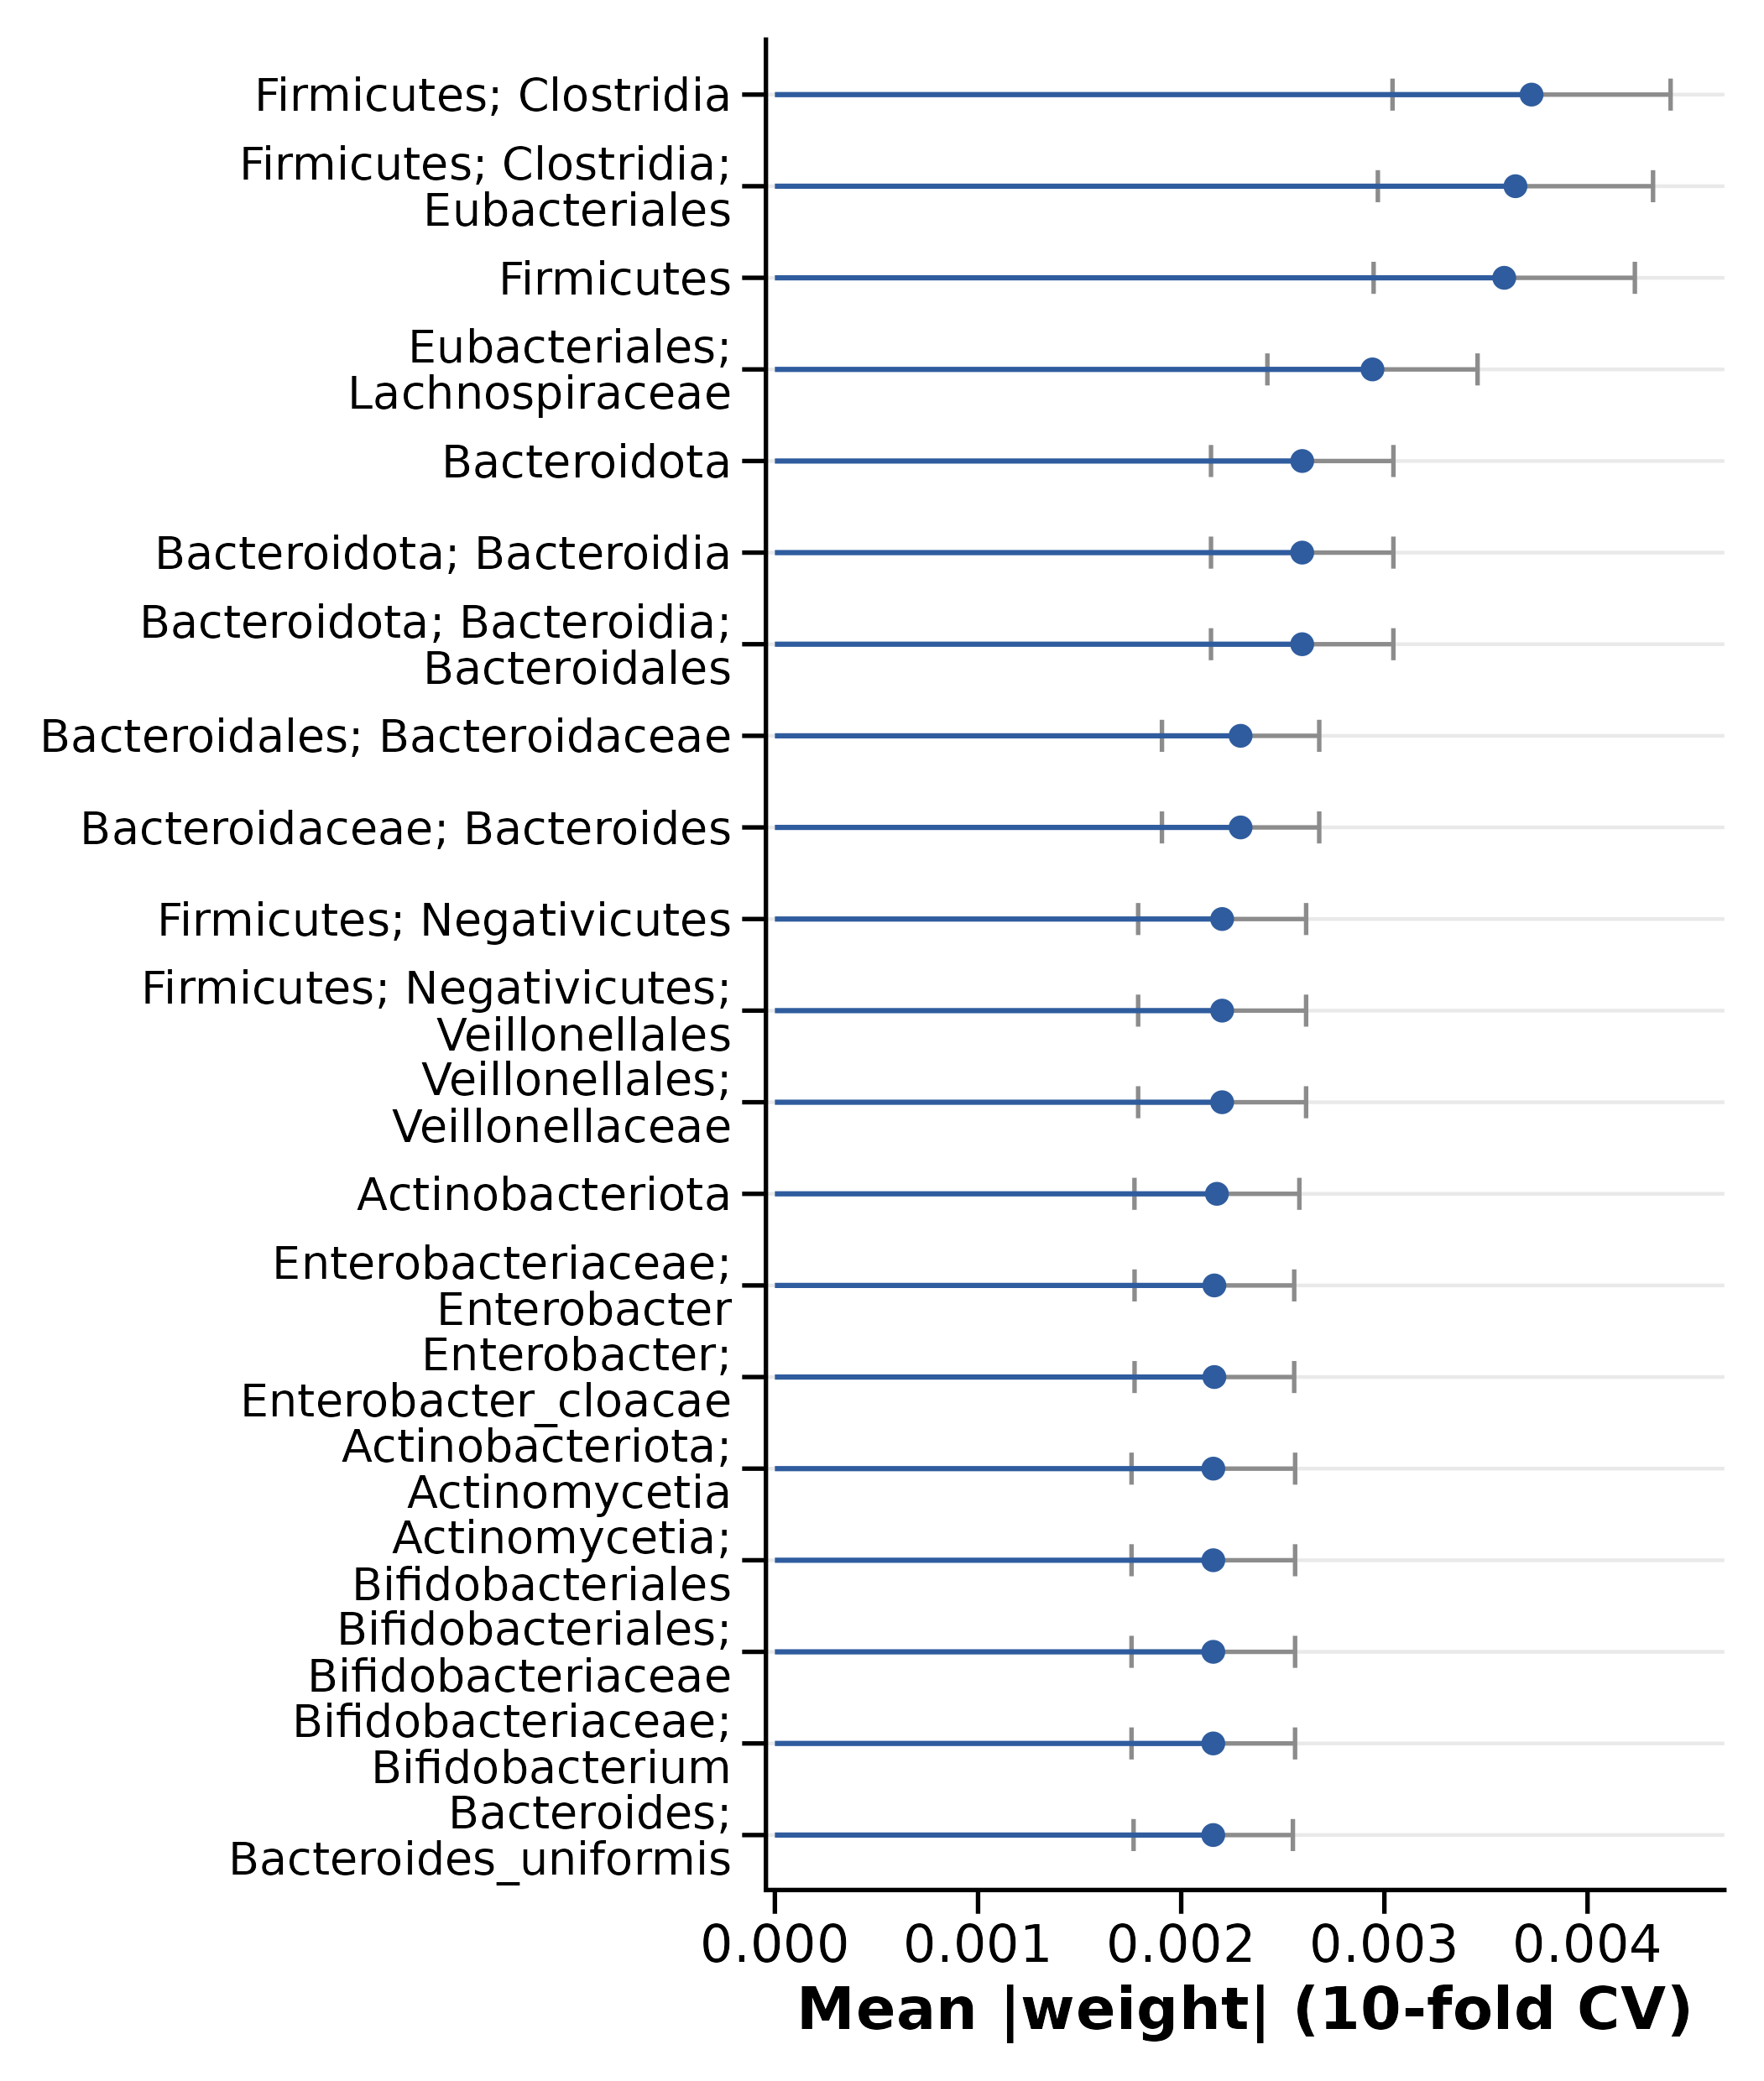 ML feature weights (96) |
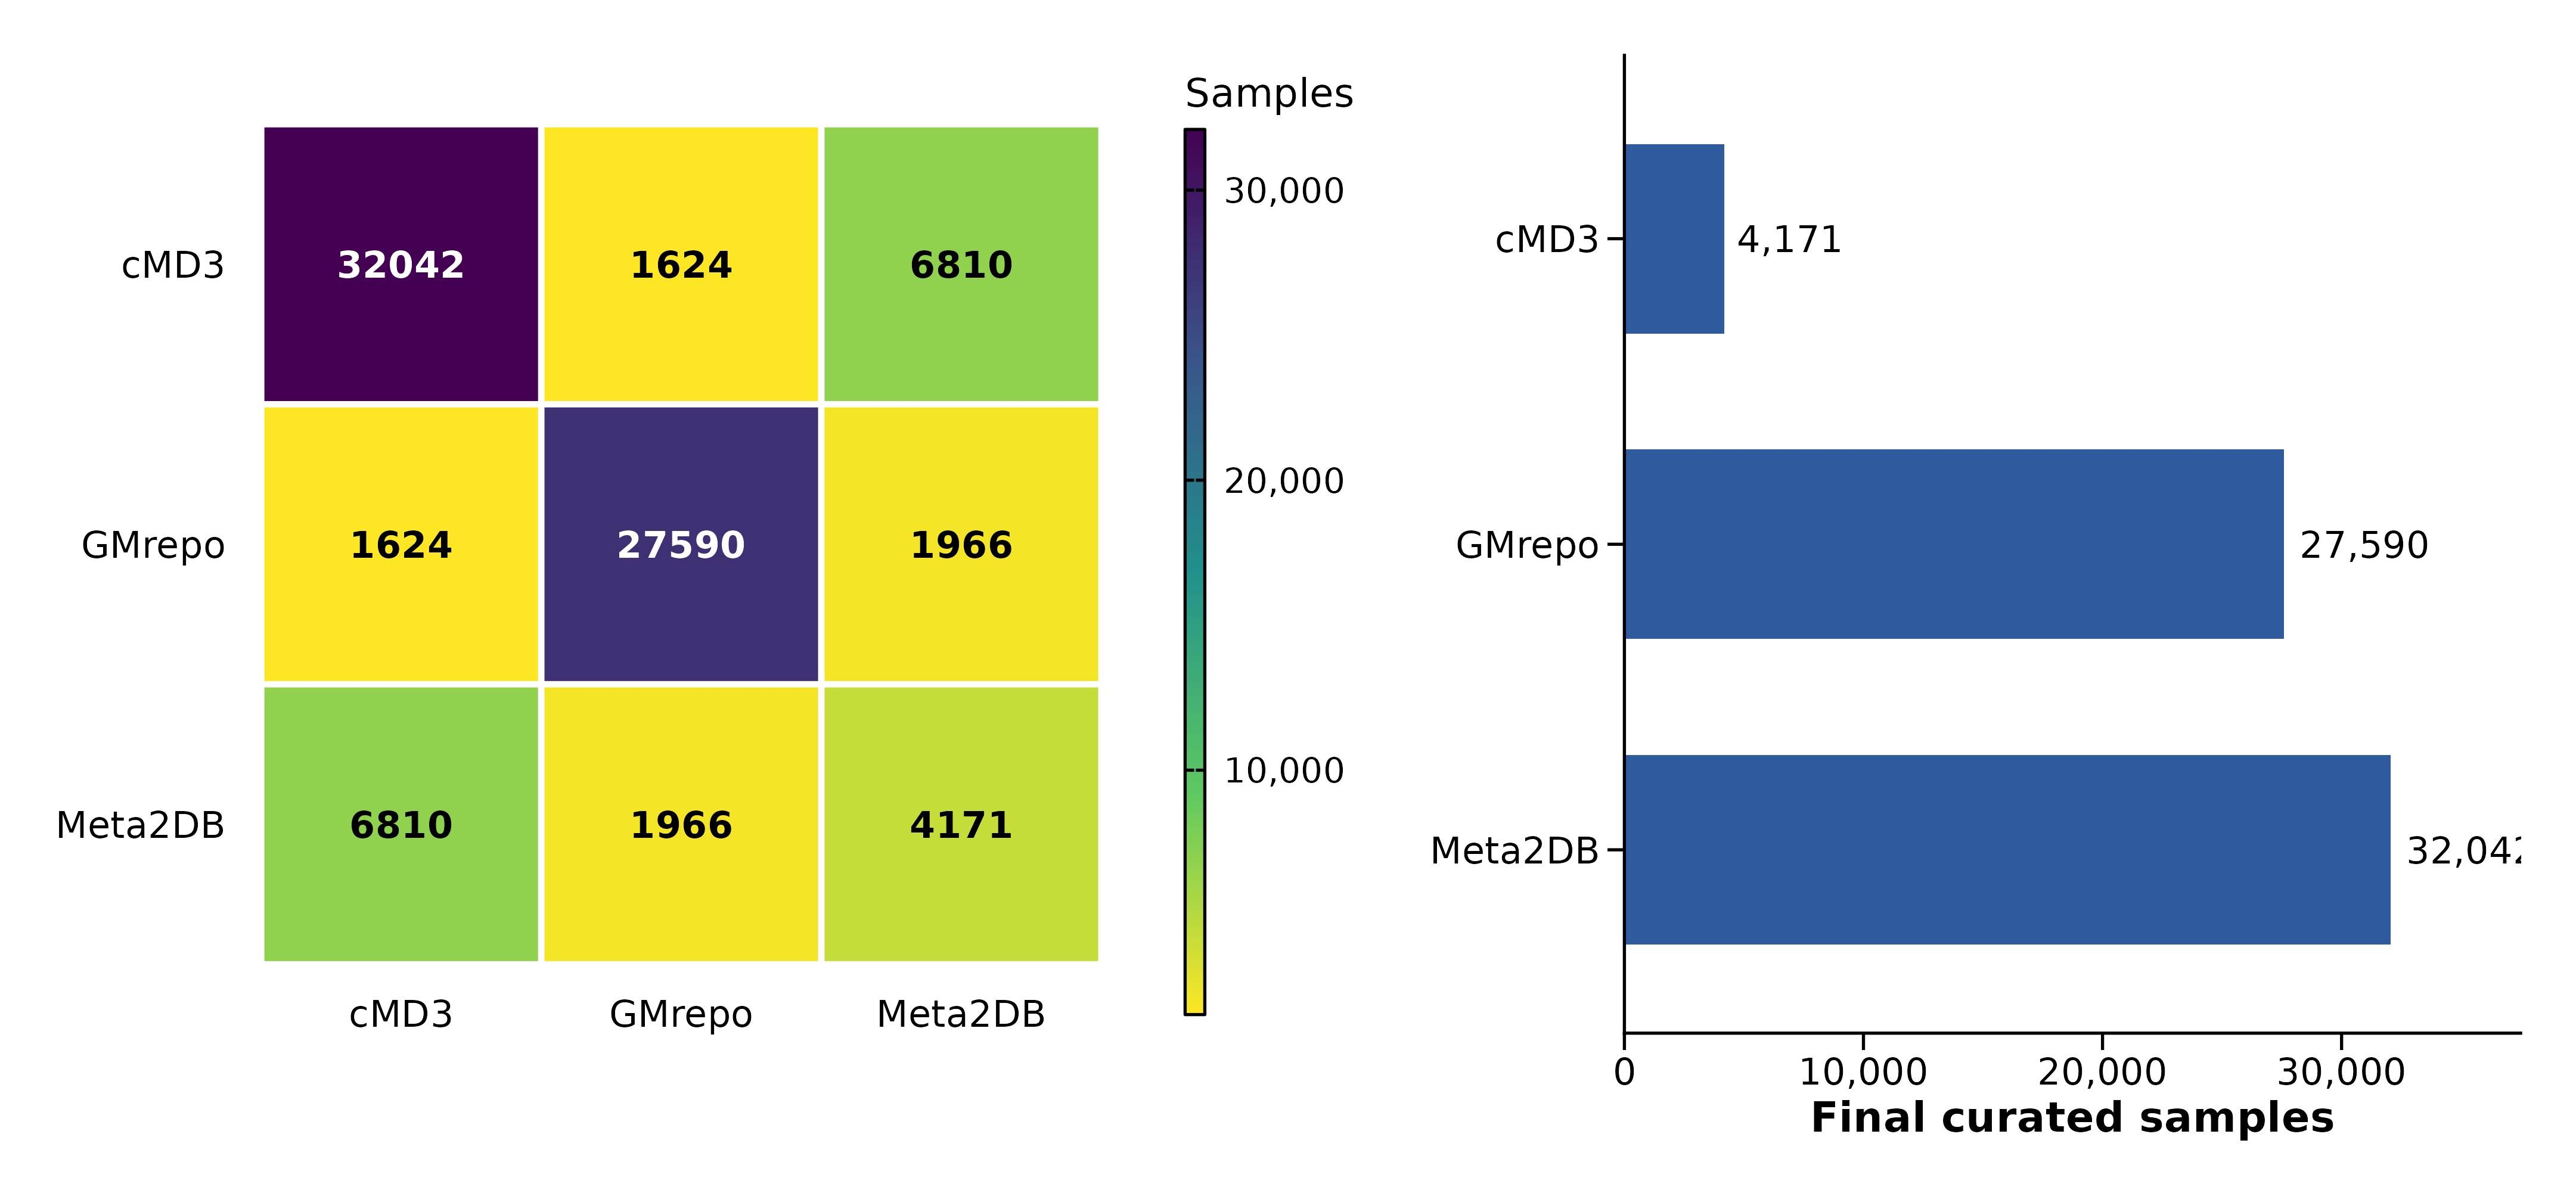 Source overlap (3 databases) |
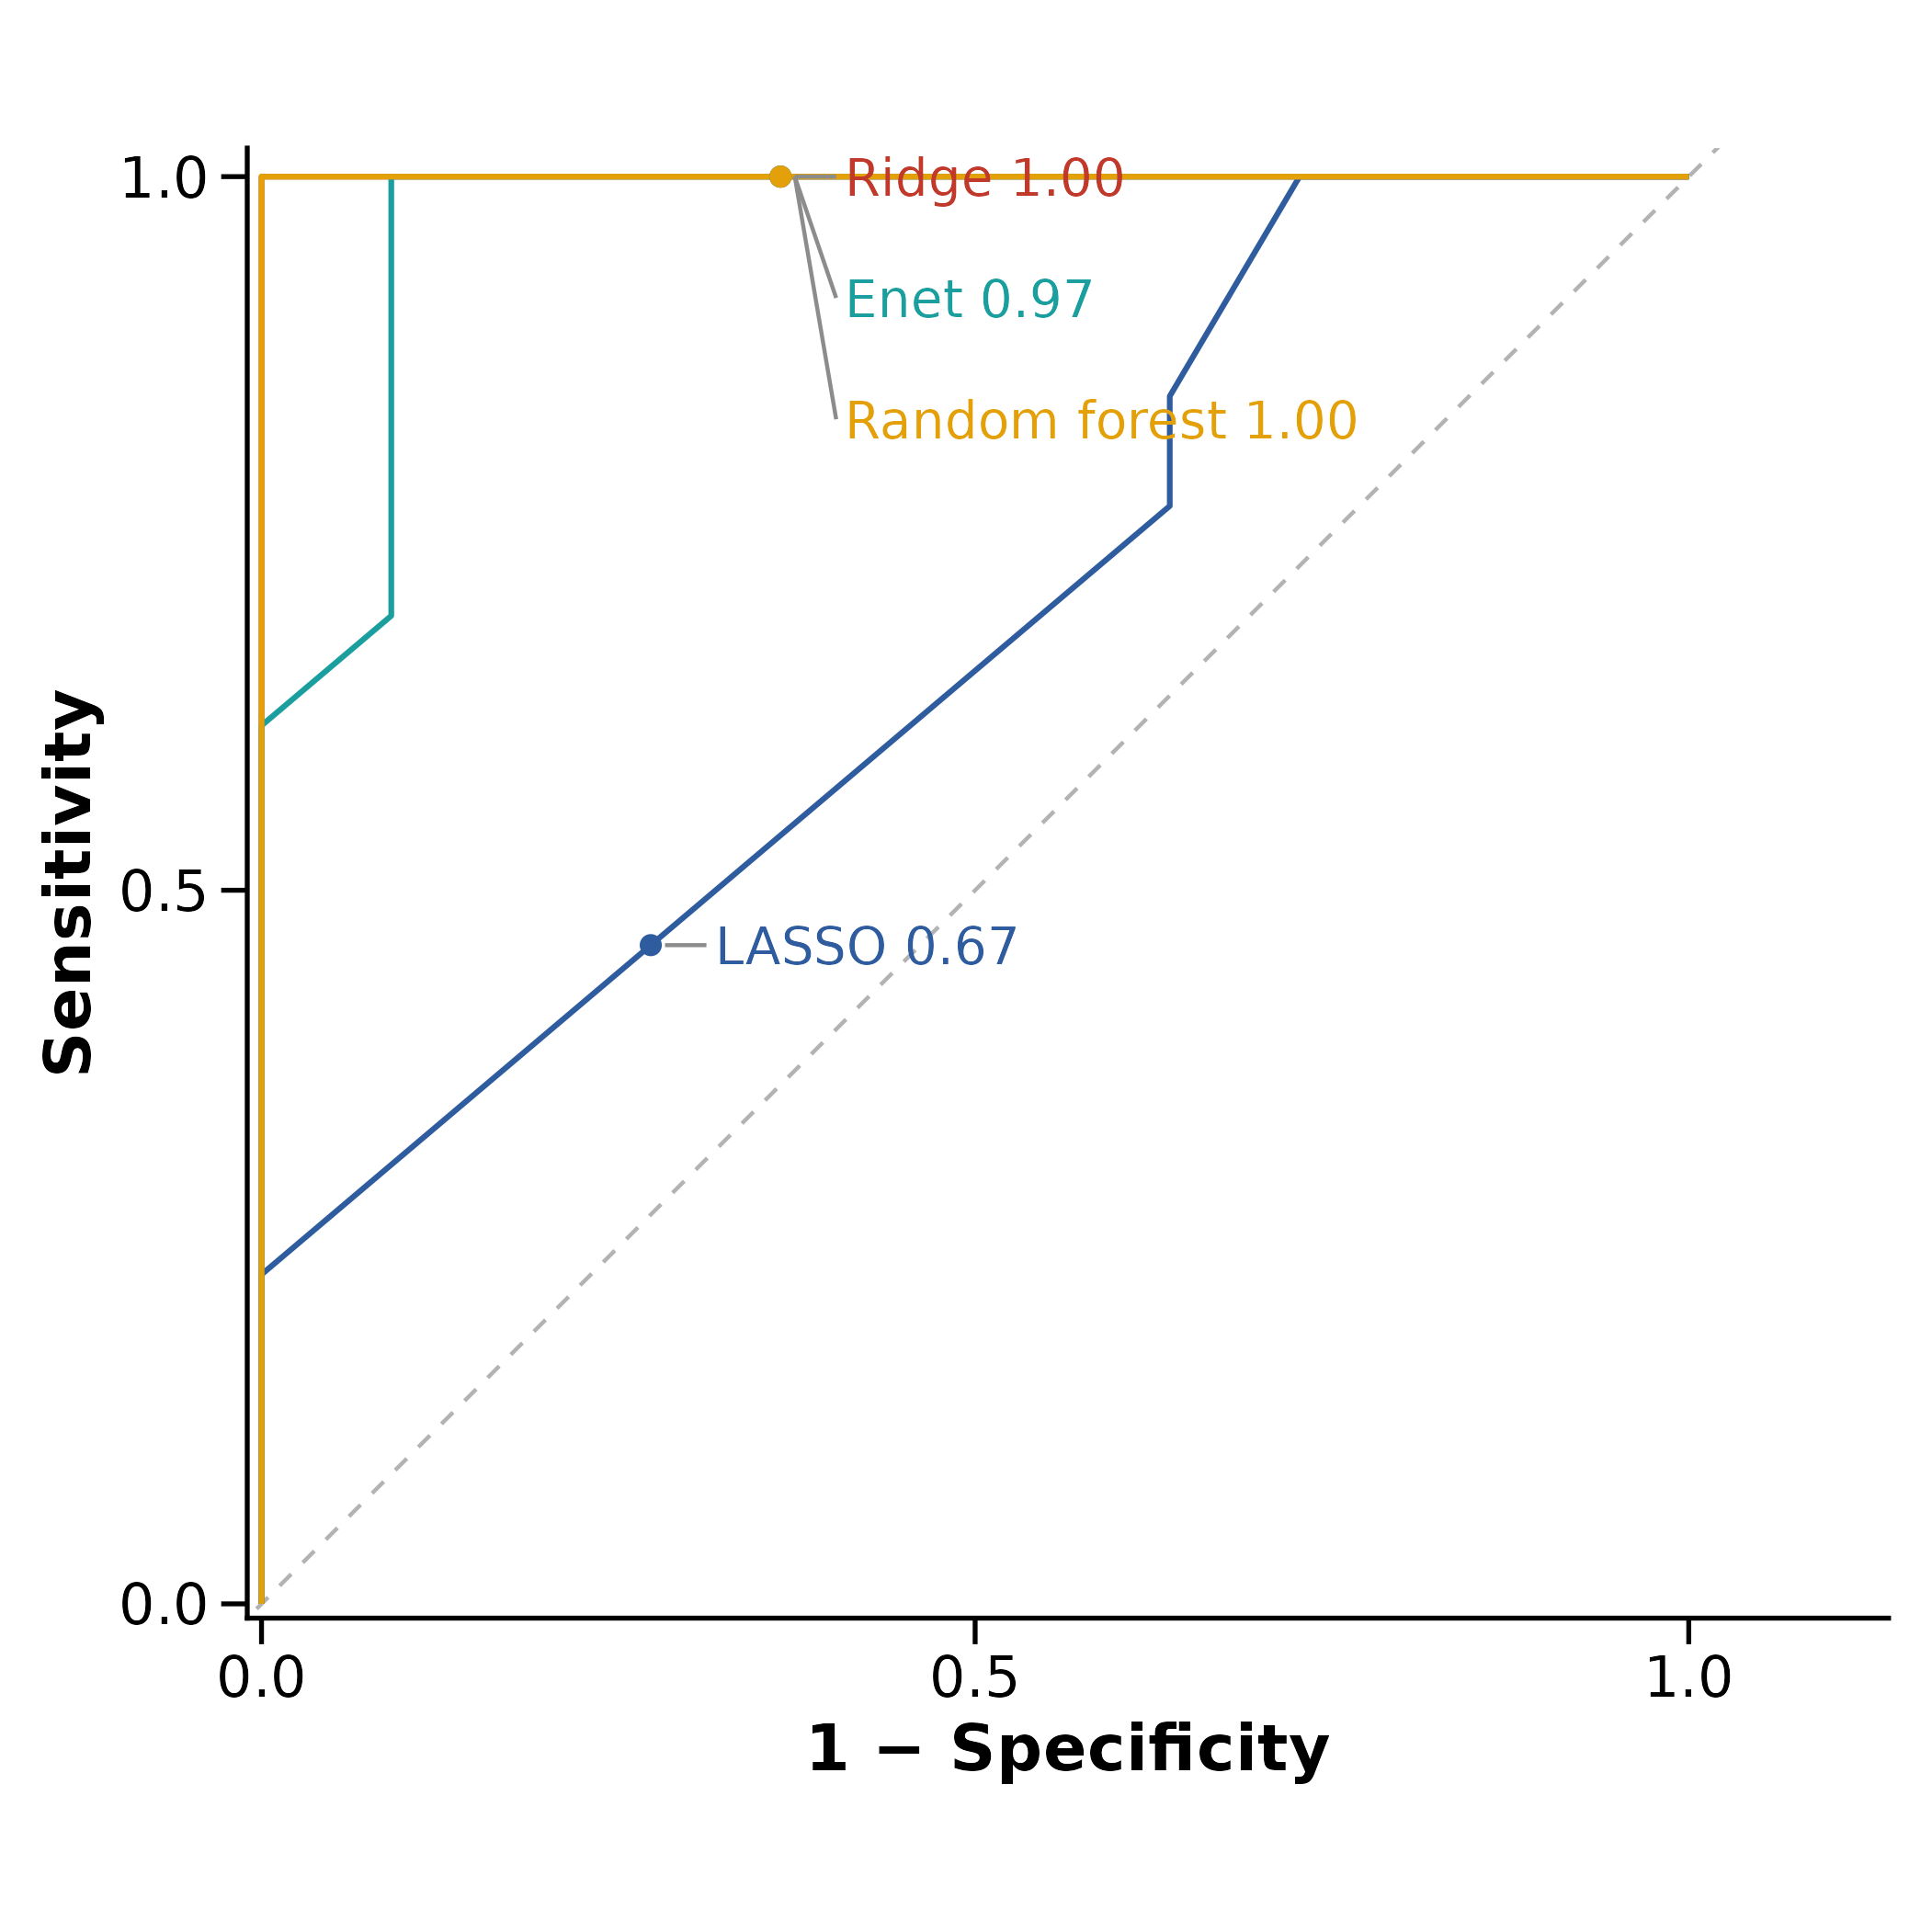 ML ROC (96, --with-ml) |
Additional figure families (not pictured): SpiecEasi functional co-occurrence networks (96), batch-correction evaluation (95b), cross-cohort replication with meta-analysis (97), MAG-level reports (dRep/inStrain/DRAM HTML from the 32–43c chain), and QC reports (fastp/MultiQC/Krona).
Script Index
Full index with per-script documentation lives in Tutorial.md (2,500+ lines, Chinese). Summary:
| Range | Content |
|---|---|
| 01–02b | Shared preprocessing (fastp, kneaddata, pair repair) |
| 11–15e | Bacteria read-based profiling (7 profilers + merges) |
| 16–20 | Assembly and quantification (incl. 16b metaSPAdes cross-check, opt-in) |
| 21–31e | Gene-catalog annotation (15 databases) |
| 28b | BGC novelty scoring against MIBiG |
| 32–43c | Binning, MAG QC/taxonomy/annotation, strain tracking, GEM modeling |
| 51–72 | Virome chain (incl. 67b PhaStyle third vote, opt-in) |
| 71–86 | Mycobiome chain (incl. 79b–79f eukaryotic QC/binning) |
| 91–99b | Statistics and reporting |
| 98e–98g | Cross-domain analyses (ANI clustering, orthogroups, correlation networks) |
| 00_* | Diagnostic and ops utilities |
Repository Layout
CSCCD-MetagenomeFlow/
├── scripts/                  180 scripts (157 sh + 7 py + 16 R) + scripts/utils/ helpers
├── pipeline/                 Snakefile, config, hardware profiles, 11 rule files
├── agents/                   registry.yaml, skill cards, optional run provenance records
├── docs/                     experience docs (RAG source), tool references
├── mcp/                      RAG indexers, bridges, CLI bridge servers
├── mining/                   auto-mining subsystem (discovery + curation + orchestrator)
├── db/                       ~1.2 TB analysis databases (not in git)
├── envs/                     57 conda environments (not in git)
├── 0Install.sh               environment + database installation
└── Tutorial.md               per-script documentation (Chinese)
Disk Requirements
| Component | Space |
|---|---|
| miniforge3 + conda envs | ~60 GB |
db/ databases |
~1.2 TB |
| 100-sample project (raw + intermediates + results) | ~2 TB |
Migrating to a New Server
git clone <repo-url>
cd CSCCD-MetagenomeFlow
bash 0Install.sh                 # envs + databases; DB_BANK/SIBLING_DB env vars
                                  # override the local database-bank paths if you have one
source scripts/activate.sh
bash scripts/checkm_config.sh
Tools & References
Taxonomic profiling


Assembly & quantification


MAG recovery & QC


MAG annotation & comparison


Functional annotation




Virome


Mycobiome


Knowledge bases


Statistics & ML


Community
Scan to follow the WeChat official account 肠动心弦 — tutorials, release notes, and metagenomics how-tos (Chinese).
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found