deep-research-mcp
Health Pass
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 115 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
MCP server for OpenAI and Gemini Deep Research, Tavily Research, DR-Tulu, and self-hosted openJiuwen DeepSearch (Gnosis).
Deep Research MCP



A Python-based agent that integrates research providers with Claude Code through the Model Context Protocol (MCP). It supports OpenAI (Responses API with web search and code interpreter, Chat Completions API for broad provider compatibility, or experimental ChatGPT subscription access through Codex OAuth), Gemini Deep Research via the Interactions API, Tavily Research, Allen AI's DR-Tulu research agent, and self-hosted Gnosis search through openJiuwen DeepSearch.
Prerequisites
- Python 3.11+
- uv installed
- One of:
- OpenAI API access (Responses API model
gpt-6-sol) - ChatGPT subscription with Codex access (experimental
openai-codexprovider) - Gemini API access with the Interactions API / Deep Research agent enabled
- Tavily API access for Tavily Research
- DR-Tulu service running locally or remotely (see DR-Tulu setup)
- Gnosis/openJiuwen DeepSearch run service and a shared output directory (see Gnosis setup)
- OpenAI API access (Responses API model
- Claude Code, or any other assistant supporting MCP integration
Installation
Run Without Cloning
With uv and Git installed, run the packaged commands directly from GitHub.uvx builds an isolated environment and reuses it from the local uv cache:
uvx --from "git+https://github.com/pminervini/deep-research-mcp.git@main" \
  deep-research-cli --help

uvx --from "git+https://github.com/pminervini/deep-research-mcp.git@main" \
  deep-research-mcp --help
For reproducible installation, replace main with a release tag or commit SHA.
The openai-codex device login is also available without a checkout:
uvx --from "git+https://github.com/pminervini/deep-research-mcp.git@main" \
  deep-research-cli auth login
Source Checkout
Recommended development setup (resolves the latest compatible versions):
# Install runtime dependencies + project in editable mode
uv sync --upgrade

# Development tooling (pytest, black, pylint, mypy, pre-commit)
uv sync --upgrade --extra dev

# Enable the pre-commit hook so black runs automatically before each commit
uv run pre-commit install

# Optional docs tooling
uv sync --upgrade --extra docs
Compatibility setup (pip-based):
python -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
pip install -e .
Code Layout
src/deep_research_mcp/agent.py: orchestration layer; owns callbacks and delegates provider work to backendssrc/deep_research_mcp/backends/: provider-specific implementations for OpenAI, OpenAI Codex subscription, Gemini, Tavily, DR-Tulu, and Gnosissrc/deep_research_mcp/cli.py: installeddeep-research-cliimplementationsrc/deep_research_mcp/mcp_server.py: FastMCP server and tool entrypointscli/deep-research-cli.py: compatibility wrapper for source-checkout usagecli/deep-research-tui.py: interactive full-screen terminal UI for research, status checks, and saving output to disktests/:pytestsuite covering configuration, MCP integration, results, and UI flows
Configuration
Configuration File
Create a ~/.deep_research file in your home directory using TOML format.
Library note: ResearchConfig.load() explicitly reads this file and applies environment variable overrides. ResearchConfig.from_env() reads environment variables only.
Common settings:
[research]                                  # Core Deep Research functionality
provider = "openai"                         # Available options: "openai", "openai-codex", "dr-tulu", "gemini", "tavily", "gnosis" -- defaults to "openai"
api_style = "responses"                     # Only applies to provider="openai"; use "chat_completions" for Perplexity, Groq, Ollama, etc.
model = "gpt-6-sol"                         # OpenAI: model identifier; Codex: "auto" or account model slug; Dr Tulu: logical provider id; Gemini: agent id; Tavily: "mini", "pro", or "auto"
reasoning_effort = "medium"                  # Optional for OpenAI API and Codex subscription; omit to keep provider/model defaults
api_key = "your-api-key"                    # API key, optional
base_url = "https://api.openai.com/v1"      # OpenAI: OpenAI-compatible endpoint; Codex uses a fixed endpoint; Dr Tulu: service base URL; Gemini: https://generativelanguage.googleapis.com; Tavily: https://api.tavily.com

# Task behavior
timeout = 1800
poll_interval = 30
cancel_on_timeout = false  # When true, cancel the provider task if it exceeds timeout. Default false: the task keeps running and the result can be recovered with research_status

[logging]
level = "INFO"

# Optional named backends for the MCP server. Each table accepts the same keys
# as [research]; `provider` is required. MCP clients select one with the
# `backend` argument of `deep_research`; the [research] table is the "default"
# backend and is used when no name is given.
[backends.fast]
provider = "openai"
api_style = "chat_completions"
model = "llama-3.3-70b"
base_url = "https://api.groq.com/openai/v1"
api_key = "gsk-..."

[backends.tulu-lab]
provider = "dr-tulu"
base_url = "http://lab-box:8080/"

[backends.gemini]
provider = "gemini"                         # api_key falls back to GEMINI_API_KEY
Note on precedence: [research] api_key and base_url map to the RESEARCH_API_KEY and RESEARCH_BASE_URL settings, which apply to every provider except openai-codex. For Tavily, TAVILY_API_KEY takes precedence over RESEARCH_API_KEY so a provider switch can use a Tavily-specific key. The Codex subscription provider ignores API keys and endpoint overrides so its bearer token cannot be redirected. If you switch another provider via an environment override (e.g. RESEARCH_PROVIDER=openai) while the file is configured for a different provider, also override RESEARCH_API_KEY and RESEARCH_BASE_URL.
Named backends ([backends.<name>]) are isolated from the default: provider, model, api_style, api_key, base_url, and reasoning_effort never leak into them from [research] or from RESEARCH_* environment variables. When a table omits api_key or base_url, the provider's own environment variables (OPENAI_API_KEY, GEMINI_API_KEY, TAVILY_API_KEY, DR_TULU_BASE_URL, and so on) and provider defaults apply; when the table sets them, the table wins, including over TAVILY_API_KEY. Runtime settings (timeout, poll_interval, cancel_on_timeout, enable_reasoning_summaries, [logging] level) are inherited from [research] and the environment unless the table overrides them. Several backends may share a provider, so two Dr Tulu servers or two OpenAI-compatible endpoints are simply two tables. The name default is reserved and names must not contain :. The server validates every named backend at startup. The CLI and TUI use the default backend unless started with --backend NAME.
OpenAI provider example:
The default gpt-6-sol balances demanding research and cost; choosegpt-6-astra for maximum capability or gpt-6-luna for lower-cost work.
The Responses backend enables web search and optional Code Interpreter.
Chat Completions defaults to gpt-6-luna but does not enable hosted research
tools. An OpenAI API key is separate from the experimental ChatGPT Codex
subscription login below. See OpenAI model guidance.
Set reasoning_effort to none, low, medium, high, xhigh, or max
for OpenAI Responses, Chat Completions, or the Codex subscription provider.
Supported efforts vary by model; OpenAI returns an error for unsupported
combinations. If omitted, the Responses backend retains its existing GPT-5/6
research defaults (including xhigh for GPT-6), while Codex and Chat
Completions leave effort to the provider. This is separate from reasoning
summaries (enable_reasoning_summaries). Environment variable:RESEARCH_REASONING_EFFORT. CLI flags override environment and TOML values.
[research]
provider = "openai"
model = "gpt-6-sol"                         # OpenAI model
api_key = "YOUR_OPENAI_API_KEY"             # Defaults to OPENAI_API_KEY
base_url = "https://api.openai.com/v1"      # OpenAI-compatible endpoint
timeout = 1800
poll_interval = 30
OpenAI Codex subscription provider example:
[research]
provider = "openai-codex"
model = "auto"                              # First picker-visible account model
timeout = 1800
Authenticate before starting the CLI or MCP server:
# Recommended: independent device-code session
uv run deep-research-cli auth login

# Optional short-lived import; never copies the Codex refresh token
uv run deep-research-cli auth login --import-codex

uv run deep-research-cli auth status
Credentials are stored independently in ~/.deep_research_auth.json with
owner-only permissions. auth logout removes only this file. Model names are
loaded from the signed-in account's /models catalogue; an explicit model must
be present in that catalogue. The catalogue request uses a fallback Codex client
version of 0.156.1; if codex is installed on PATH and reports a newer
stable version, that version is used instead. An older, missing, or unparseable
CLI leaves the fallback in place. model = "auto" selects the first
picker-visible model returned by the catalogue, not necessarily the newest.
This provider uses the undocumentedhttps://chatgpt.com/backend-api/codex consumer endpoint. It is not an official
OpenAI API integration and can change or reject third-party clients without
notice. It identifies itself as deep_research_mcp and does not impersonate the
Codex CLI. Review the current OpenAI Terms of
Use before enabling it.
Limitations:
- Native web search is enabled, but Code Interpreter is unavailable.
- Calls are synchronous SSE streams;
research_status, completed-report
recovery, background polling, andcancel_on_timeoutare unavailable. - Imported Codex credentials cannot refresh. Run
auth loginwhen the imported
access token expires.
Gemini Deep Research provider example:
[research]
provider = "gemini"
model = "deep-research-preview-04-2026"     # Gemini Deep Research agent id
api_key = "YOUR_GEMINI_API_KEY"                # Defaults to GEMINI_API_KEY or GOOGLE_API_KEY
base_url = "https://generativelanguage.googleapis.com"
timeout = 1800
poll_interval = 30
Gemini Deep Research agent IDs supported by this project:
| Agent ID | Intended use |
|---|---|
deep-research-preview-04-2026 |
Faster, more efficient research; this is the project default |
deep-research-max-preview-04-2026 |
Maximum comprehensiveness for context gathering and synthesis |
deep-research-pro-preview-12-2025 |
Older Gemini 3.1 Pro-based preview for accuracy-focused, long-running research |
Google's current Gemini Deep Research documentation
lists the April 2026 standard and Max agents as the supported versions. The
December 2025 Pro agent has a separate model page,
and its ID (deep-research-pro-preview-12-2025) still appears in the
Interactions API reference. It is
not listed in the current model catalogue,
but a live research task completed through this project with that ID on
September 27, 2026. Set any agent ID above as research.model; all are preview
identifiers and may change.
Tavily Research provider example:
[research]
provider = "tavily"
model = "mini"                       # "mini", "pro", or "auto"; defaults to "mini"
base_url = "https://api.tavily.com"
timeout = 1800
poll_interval = 30
Set TAVILY_API_KEY in your environment or set api_key in~/.deep_research. Tavily Research starts an asynchronous task; useresearch_status with its task ID to recover a completed report. Tavily does
not expose task cancellation, so a timed-out task may keep running even whencancel_on_timeout = true. See Tavily Research API
and credit costs.
uv run deep-research-cli research "What changed in Python 3.0?"
Gnosis provider example
Gnosis uses the state-space search workflow in
openJiuwen DeepSearch, not its
separate report-generation API. Deploy that service independently and publish
its run/telemetry port (8089). The adapter adds no openJiuwen SDK dependency.
[backends.gnosis]
provider = "gnosis"
base_url = "http://127.0.0.1:8089"
gnosis_config_path = "/absolute/path/to/gnosis-options.json"
gnosis_output_dir = "/absolute/path/to/shared/output"
timeout = 240
poll_interval = 2
cancel_on_timeout = true
gnosis_config_path points to a private JSON file containing the nativePOST /runs request options: llm, tool_map, search/fetch provider settings,
and optional search_workflow_per_question_params. Use the deployed service's/docs for its schema. Do not put query, run_id, or conversation_id in this
file; the adapter owns them. It sets search_mode="search" and disables question
routing so a run cannot silently switch to the differently bounded ReAct mode.
For example, a stock service using Tavily and Jina accepts:
{
  "llm": {
    "model_name": "YOUR_CHAT_MODEL",
    "base_url": "https://api.openai.com/v1",
    "api_key": "YOUR_LLM_API_KEY"
  },
  "tool_map": "search_fetch",
  "web_search_engine_config": {
    "search_engine_name": "tavily",
    "search_api_key": "YOUR_TAVILY_API_KEY"
  },
  "web_fetch_provider_config": {
    "provider_name": "jina",
    "api_key": "YOUR_JINA_API_KEY"
  },
  "search_workflow_per_question_params": {
    "max_workers": 2,
    "time_limit": 180,
    "actions_explored_limit": 10,
    "fail_limit": 2
  }
}
Protect that file (chmod 600) and keep it outside the repository. The model
and its reasoning options belong inside llm; the top-level model="gnosis"
is only a logical provider label. Codex OAuth cannot be passed directly as a
Chat Completions API key; subscription use requires a separately configured
compatible bridge. Search/fetch tools remain a separate service configuration.
The run API exposes completion metadata, not the full answer. The adapter readslogs/result_<internal-conversation-id>/final_result.json undergnosis_output_dir; mount the same output directory into the MCP process if
it runs in another container. HTTP access alone is insufficient for recovery.
Fresh clients can recover completed answers without loading the credential file.
Unknown or nonterminal telemetry is reported as unknown, because the service
does not expose live run status after a restart. Server restarts do not resume
in-flight searches. cancel_on_timeout requests cancellation; otherwise the
task ID is retained for later recovery. Graph action/time limits are not hard
request/token budgets.
Only confirmed, nonempty predictions count as completed answers. Guesses and
limit exits without a confirmed answer are failures. Citations are extracted
only from links in the selected answer, not inferred from visited pages. Code
Interpreter is unsupported. This mode may return a short answer rather than
a long research report.
uv run deep-research-cli --backend gnosis research "When was Python 3.0 released?"
uv run deep-research-cli --backend gnosis status RUN_ID
Equivalent default-provider flags are --provider gnosis,--gnosis-config-path PATH, and --gnosis-output-dir PATH. Environment aliases:GNOSIS_BASE_URL, GNOSIS_CONFIG_PATH, GNOSIS_OUTPUT_DIR; optionalGNOSIS_API_KEY authenticates the run service, not its LLM. Generic aliasesRESEARCH_GNOSIS_CONFIG_PATH and RESEARCH_GNOSIS_OUTPUT_DIR apply only to the
default backend; named tables remain isolated.
Dr Tulu provider example:
[research]
provider = "dr-tulu"
model = "dr-tulu"                   # Logical provider model id; currently informational
base_url = "http://localhost:8080/"   # Dr Tulu service base URL; the backend calls /chat
api_key = ""                        # Optional; defaults to RESEARCH_API_KEY / DR_TULU_API_KEY if set
timeout = 1800
poll_interval = 30
Running Dr Tulu locally:
- Clone and configure
dr-tuluseparately. - In
dr-tulu/agent/.env, set at least:SERPER_API_KEYJINA_API_KEYS2_API_KEY(optional but recommended)
- Start the DR-Tulu model server:
cd /path/to/dr-tulu/agent
conda run -n vllm bash -lc '
  CUDA_VISIBLE_DEVICES=0 \
  vllm serve rl-research/DR-Tulu-8B \
    --port 30001 \
    --dtype auto \
    --max-model-len 16384 \
    --gpu-memory-utilization 0.60 \
    --enforce-eager
'
- Start the Dr Tulu MCP backend:
cd /path/to/dr-tulu/agent
conda run -n vllm python -m dr_agent.mcp_backend.main --port 8000
- Start the Dr Tulu app service:
cd /path/to/dr-tulu/agent
conda run -n vllm python workflows/auto_search_sft.py serve \
  --port 8080 \
  --config workflows/auto_search_sft.yaml \
  --config-overrides "search_agent_max_tokens=12000,browse_agent_max_tokens=12000"
- Point
deep-research-mcpat that service:
[research]
provider = "dr-tulu"
base_url = "http://localhost:8080/"
timeout = 1800
The dr-tulu backend calls POST {base_url}/chat, so if you front Dr Tulu behind a different host, port, or reverse proxy, update base_url accordingly.
Perplexity (via Sonar Deep Research and Perplexity's OpenAI-compatible endpoint) provider example:
[research]
provider = "openai"
api_style = "chat_completions"              # Required for Perplexity (no Responses API)
model = "sonar-deep-research"               # Perplexity's Sonar Deep Research
api_key = "ppl-..."                         # Defaults to OPENAI_API_KEY
base_url = "https://api.perplexity.ai"      # Perplexity's OpenAI-compatible endpoint
timeout = 1800
Ollama (local) provider example:
[research]
provider = "openai"
api_style = "chat_completions"
model = "llama3.1"                     # Any model available in your Ollama instance
base_url = "http://localhost:11434/v1" # Ollama's OpenAI-compatible endpoint
api_key = ""                           # Not required for local Ollama
timeout = 600
llama-server (local llama.cpp server) provider example:
[research]
provider = "openai"
api_style = "chat_completions"
model = "qwen2.5-0.5b"                 # Must match the --alias passed to llama-server
base_url = "http://127.0.0.1:8081/v1"  # llama-server OpenAI-compatible endpoint
api_key = "test"                       # Must match the --api-key passed to llama-server
timeout = 600
Generic OpenAI-compatible Chat Completions provider (Groq, Together AI, vLLM, etc.):
[research]
provider = "openai"
api_style = "chat_completions"
model = "your-model-name"
api_key = "your-api-key"
base_url = "https://api.your-provider.com/v1"
timeout = 600
Install The Included Skill In Claude Code Or Codex
This repository also ships a repo-specific skill guide atskills/deep-research-mcp/SKILL.md.
Installing that file as a local skill gives Claude Code or Codex a focused
playbook for this repository's CLI, Python API, providers, and MCP server.
It does not install Python dependencies, start the MCP server, or replace
the provider configuration in ~/.deep_research. Treat it as complementary to
the MCP setup below, not a substitute for it.
Claude Code skill install
Claude Code's skills docs use these locations:
- personal skill:
~/.claude/skills/<skill-name>/SKILL.md - project skill:
.claude/skills/<skill-name>/SKILL.md
Personal install:
mkdir -p ~/.claude/skills/deep-research-mcp
cp /path/to/deep-research-mcp/skills/deep-research-mcp/SKILL.md \
  ~/.claude/skills/deep-research-mcp/SKILL.md
If you prefer to keep the installed skill linked to this checkout:
mkdir -p ~/.claude/skills/deep-research-mcp
ln -sf /path/to/deep-research-mcp/skills/deep-research-mcp/SKILL.md \
  ~/.claude/skills/deep-research-mcp/SKILL.md
Project-local install from the repository root:
mkdir -p .claude/skills/deep-research-mcp
cp skills/deep-research-mcp/SKILL.md .claude/skills/deep-research-mcp/SKILL.md
After that, restart Claude Code or open a new session if the skill does not
appear immediately. The skill can be invoked directly as/deep-research-mcp, and Claude can also load it automatically when the task
matches the skill description. For a reusable shared extension, package the
same skill into a Claude Code plugin instead of copying it by hand.
Official docs:
- Claude Code skills: https://docs.claude.com/en/docs/claude-code/skills
- Claude Code plugins: https://docs.claude.com/en/docs/claude-code/plugins
Codex skill install
Current Codex docs describe skills as skill folders containing SKILL.md,
stored globally in $HOME/.agents/skills or repo-locally in .agents/skills.
Personal install:
mkdir -p ~/.agents/skills/deep-research-mcp
cp /path/to/deep-research-mcp/skills/deep-research-mcp/SKILL.md \
  ~/.agents/skills/deep-research-mcp/SKILL.md
Or keep the installed skill linked to this checkout:
mkdir -p ~/.agents/skills/deep-research-mcp
ln -sf /path/to/deep-research-mcp/skills/deep-research-mcp/SKILL.md \
  ~/.agents/skills/deep-research-mcp/SKILL.md
Project-local install from the repository root:
mkdir -p .agents/skills/deep-research-mcp
cp skills/deep-research-mcp/SKILL.md .agents/skills/deep-research-mcp/SKILL.md
If your Codex setup still follows older CLI conventions that use~/.codex/skills or .codex/skills, mirror the same directory structure
there instead.
Codex can invoke the skill implicitly when the task matches its description, or
explicitly by mentioning $deep-research-mcp in the prompt. If the skill does
not show up immediately, restart Codex.
Official docs:
- Codex skills: https://developers.openai.com/codex/skills
- Codex customization and skill locations: https://developers.openai.com/codex/concepts/customization#skills
Claude Code Integration
- Configure MCP Server
Choose one of the transports below.
Option A: stdio (recommended when Claude Code should spawn the server itself)
Clone-free user installation:
claude mcp add --scope user --transport stdio deep-research -- \
  uvx --from "git+https://github.com/pminervini/deep-research-mcp.git@main" \
  deep-research-mcp
For a source checkout with provider credentials already stored in~/.deep_research, use:
claude mcp add deep-research -- uv run --directory /path/to/deep-research-mcp deep-research-mcp
If you want Claude Code to pass OPENAI_API_KEY through to the spawned MCP
process explicitly, use:
claude mcp add -e OPENAI_API_KEY="$OPENAI_API_KEY" \
  deep-research -- \
  uv run --directory /path/to/deep-research-mcp deep-research-mcp
Option B: HTTP (recommended when you want to run the server separately)
Start the server in one terminal:
OPENAI_API_KEY="$OPENAI_API_KEY" \
uv run --directory /path/to/deep-research-mcp \
  deep-research-mcp --transport http --host 127.0.0.1 --port 8080
Then add the HTTP MCP server in Claude Code:
claude mcp add --transport http deep-research-http http://127.0.0.1:8080/mcp
Replace /path/to/deep-research-mcp/ with the actual path to your cloned repository.
The verified Streamable HTTP endpoint is http://127.0.0.1:8080/mcp.
For multi-hour research, raise Claude Code's tool timeout before launching the CLI and rely on incremental status polls:
export MCP_TOOL_TIMEOUT=14400000  # 4 hours
claude --mcp-config ./.mcp.json
Kick off work with deep_research, note the returned job ID, and call research_status to stream progress without letting any single tool call stagnate. Task IDs are returned as <backend>:<provider task id> (for example default:resp_abc123) and must be passed back to research_status verbatim; an un-prefixed ID is looked up on the default backend. If ~/.deep_research declares [backends.<name>] tables, call list_backends to see them and pass backend="<name>" to deep_research to use one.
Output size: Claude Code limits MCP tool output (about 25,000 tokens by default, configurable via MAX_MCP_OUTPUT_TOKENS). The research tools declare the anthropic/maxResultSizeChars annotation so recent Claude Code versions accept large reports without extra configuration; on older versions, raise the limit before launching the CLI:
export MAX_MCP_OUTPUT_TOKENS=50000
claude
Timeout recovery: if a research task exceeds the configured timeout, the server leaves the provider task running by default and returns its task ID; call research_status with that ID to retrieve the full report once it completes. Pass --cancel-on-timeout to deep-research-mcp (or set cancel_on_timeout = true in ~/.deep_research) to restore the old cancel behavior.
- Use in Claude Code:
- The research tools will appear in Claude Code's tool palette
- Simply ask Claude to "research [your topic]" and it will use the Deep Research agent
OpenAI Codex Integration
- Configure MCP Server
Choose one of the transports below.
Option A: stdio (recommended when Codex should spawn the server itself)
Clone-free installation:
codex mcp add deep-research -- \
  uvx --from "git+https://github.com/pminervini/deep-research-mcp.git@main" \
  deep-research-mcp
For a source checkout, add the MCP server configuration to~/.codex/config.toml:
[mcp_servers.deep-research]
command = "uv"
args = ["run", "--directory", "/path/to/deep-research-mcp", "deep-research-mcp"]
# If your provider credentials live in shell env vars rather than ~/.deep_research,
# pass them through to the MCP subprocess explicitly:
env_vars = ["OPENAI_API_KEY"]
startup_timeout_ms = 30000  # 30 seconds for server startup
request_timeout_ms = 7200000  # 2 hours for long-running research tasks
# Alternatively, set tool_timeout_sec when using newer Codex clients
# tool_timeout_sec = 14400.0     # 4 hours for deep research runs
Replace /path/to/deep-research-mcp/ with the actual path to your cloned repository.
If your credentials are already configured in ~/.deep_research, env_vars is
optional. It is required when you expect the spawned MCP server to inheritOPENAI_API_KEY from the parent shell.
Option B: HTTP (recommended when you want to run the server separately)
Start the server in one terminal:
OPENAI_API_KEY="$OPENAI_API_KEY" \
uv run --directory /path/to/deep-research-mcp \
  deep-research-mcp --transport http --host 127.0.0.1 --port 8080
Then add this to ~/.codex/config.toml:
[mcp_servers.deep-research-http]
url = "http://127.0.0.1:8080/mcp"
tool_timeout_sec = 14400.0
The verified Streamable HTTP endpoint is http://127.0.0.1:8080/mcp.
Important timeout configuration:
startup_timeout_ms: Time allowed for the MCP server to start (default: 30000ms / 30 seconds)request_timeout_ms: Maximum time for research queries to complete (recommended: 7200000ms / 2 hours for comprehensive research)tool_timeout_sec: Preferred for newer Codex clients; set this to a large value (e.g.,14400.0for 4 hours) when you expect long-running research.- Kick off research once to capture the job ID, then poll
research_statusso each tool call remains short and avoids hitting client timeouts.
Without proper timeout configuration, long-running research queries may fail with "request timed out" errors.
- Use in OpenAI Codex:
- The research tools will be available automatically when you start Codex
- Ask Codex to "research [your topic]" and it will use the Deep Research MCP server
Gemini CLI Integration
- Configure MCP Server
Add the MCP server using Gemini CLI's built-in command:
gemini mcp add deep-research -- uv run --directory /path/to/deep-research-mcp deep-research-mcp
Or manually add to your ~/.gemini/settings.json file:
{
  "mcpServers": {
    "deep-research": {
      "command": "uv",
      "args": ["run", "--directory", "/path/to/deep-research-mcp", "deep-research-mcp"],
      "env": {
        "RESEARCH_PROVIDER": "gemini",
        "GEMINI_API_KEY": "$GEMINI_API_KEY"
      }
    }
  }
}
Replace /path/to/deep-research-mcp/ with the actual path to your cloned repository.
- Use in Gemini CLI:
- Start Gemini CLI with
gemini - The research tools will be available automatically
- Ask Gemini to "research [your topic]" and it will use the Deep Research MCP server
- Use
/mcpcommand to view server status and available tools
- Start Gemini CLI with
HTTP transport: If your Gemini environment supports MCP-over-HTTP, you may run
the server with --transport http and configure Gemini with the server URL.
Usage
As a Standalone Python Module
import asyncio
from deep_research_mcp.agent import DeepResearchAgent
from deep_research_mcp.config import ResearchConfig

async def main():
    # Initialize configuration
    config = ResearchConfig.load()

    # Create agent
    agent = DeepResearchAgent(config)

    # Perform research
    result = await agent.research(
        query="What are the latest advances in quantum computing?",
        system_prompt="Focus on practical applications and recent breakthroughs"
    )

    # Print results
    print(f"Report: {result.final_report}")
    print(f"Citations: {result.citations}")
    print(f"Research steps: {result.reasoning_steps}")
    print(f"Execution time: {result.execution_time:.2f}s")

# Run the research
asyncio.run(main())
As an MCP Server
Two transports are supported: stdio (default) and HTTP streaming.
# 1) stdio (default) — for editors/CLIs that spawn a local process
uv run deep-research-mcp

# 2) HTTP streaming — start a local HTTP MCP server
uv run deep-research-mcp --transport http --host 127.0.0.1 --port 8080
Notes:
- HTTP mode uses streaming responses provided by FastMCP. The tools in this
server return their full results when a research task completes; streaming is
still beneficial for compatible clients and for future incremental outputs. - The verified Streamable HTTP endpoint is
/mcp, so the default local URL ishttp://127.0.0.1:8080/mcp. - If you start the server outside the client and rely on environment variables
for credentials, export them before launching the server process. If you usestdioand let the client spawn the server, make sure the client passes the
required env vars through. - The server exposes three tools:
deep_research(with an optionalbackend
argument naming a[backends.<name>]table from~/.deep_research),research_status, andlist_backends, which reports each backend's
provider, model, endpoint, and whether credentials were found. Named
backends require the TOML file; an environment-only deployment exposes just
the default backend. Task IDs are returned as<backend>:<id>.
OAuth authentication for HTTP
HTTP OAuth is opt-in. Set both variables below before starting the server:
export MCP_AUTH_ISSUER_URL="https://firm-mermaid-02-staging.authkit.app"
export MCP_AUTH_RESOURCE_URL="http://127.0.0.1:8080/mcp"

uv run deep-research-mcp --transport http --host 127.0.0.1 --port 8080
MCP_AUTH_RESOURCE_URL must exactly match the Resource Indicator configured in
WorkOS, including the /mcp path. When enabled, the server verifies each
AuthKit access token's signature, issuer, expiration, and audience and publishes
RFC 9728 protected-resource metadata for MCP clients. No WorkOS API key or
client secret is required by the server. Local stdio usage is unchanged.
In WorkOS, enable Client ID Metadata Documents (CIMD), keep Dynamic Client
Registration (DCR) enabled for older clients, and add the resource URL under
Connect → Configuration. See the WorkOS MCP authentication
guide.
Command-Line Interface
The installed deep-research-cli command provides direct access to all
research functionality from the terminal. Its implementation lives insrc/deep_research_mcp/cli.py, while cli/deep-research-cli.py remains a
source-checkout compatibility wrapper. It supports two modes of operation:
agent mode (default) which runs DeepResearchAgent directly, and MCP
client mode which connects to a running MCP server over HTTP.
Configuration is loaded from ~/.deep_research by default. EveryResearchConfig parameter can be overridden via CLI flags, which take
precedence over both the TOML file and environment variables. Pass--backend NAME to use a named [backends.NAME] table instead. The status
command accepts task IDs in the <backend>:<id> form returned by the MCP
server and routes them to the named backend automatically.
Terminal UI
The repository also ships with a full-screen terminal UI atcli/deep-research-tui.py. It presents the same core functionality as the
CLI in a dark, keyboard-driven interface for running deep research, task status
checks, and saving output to disk.
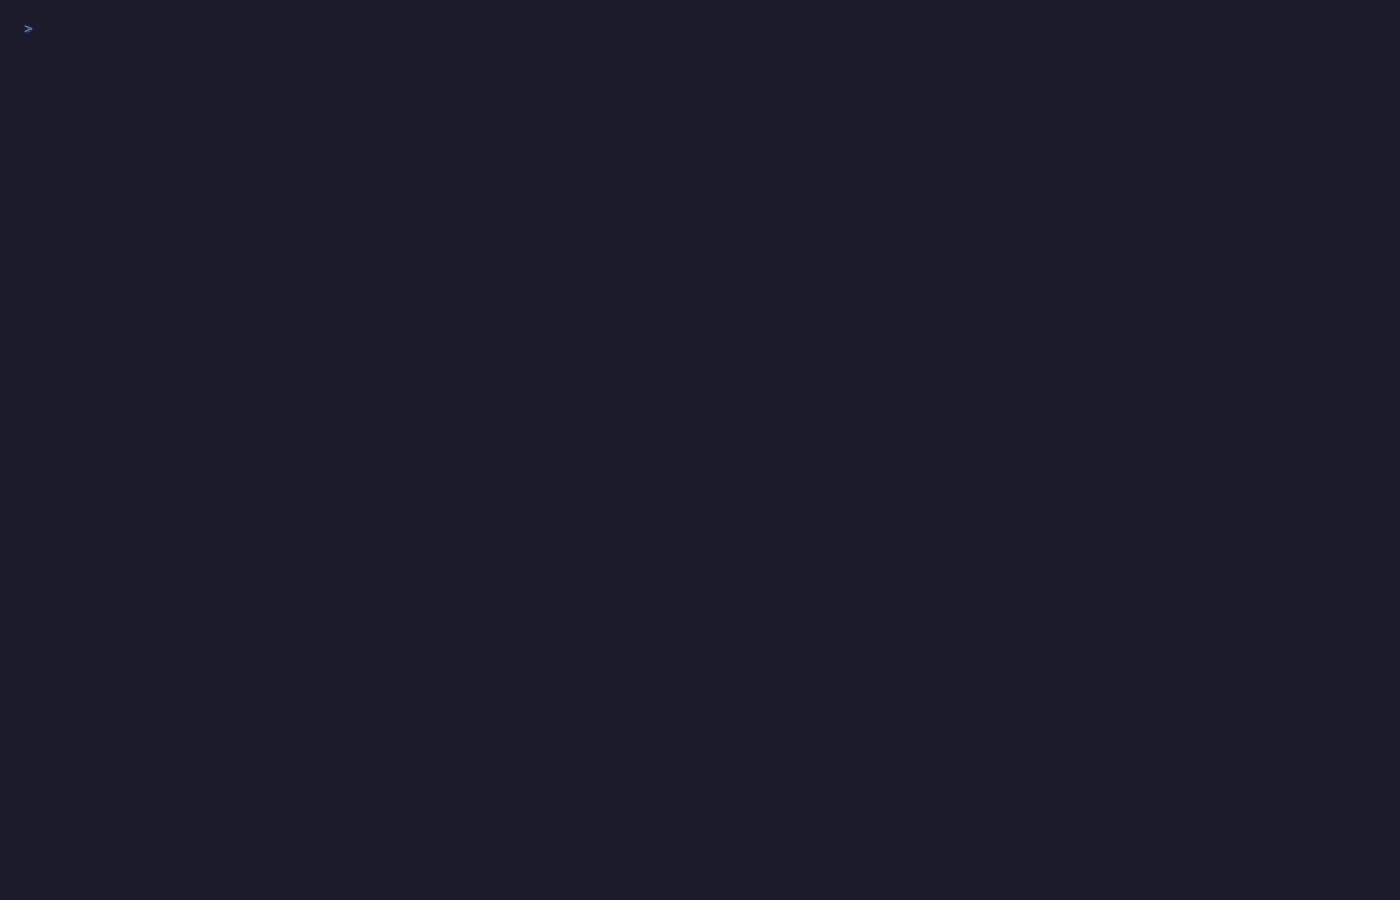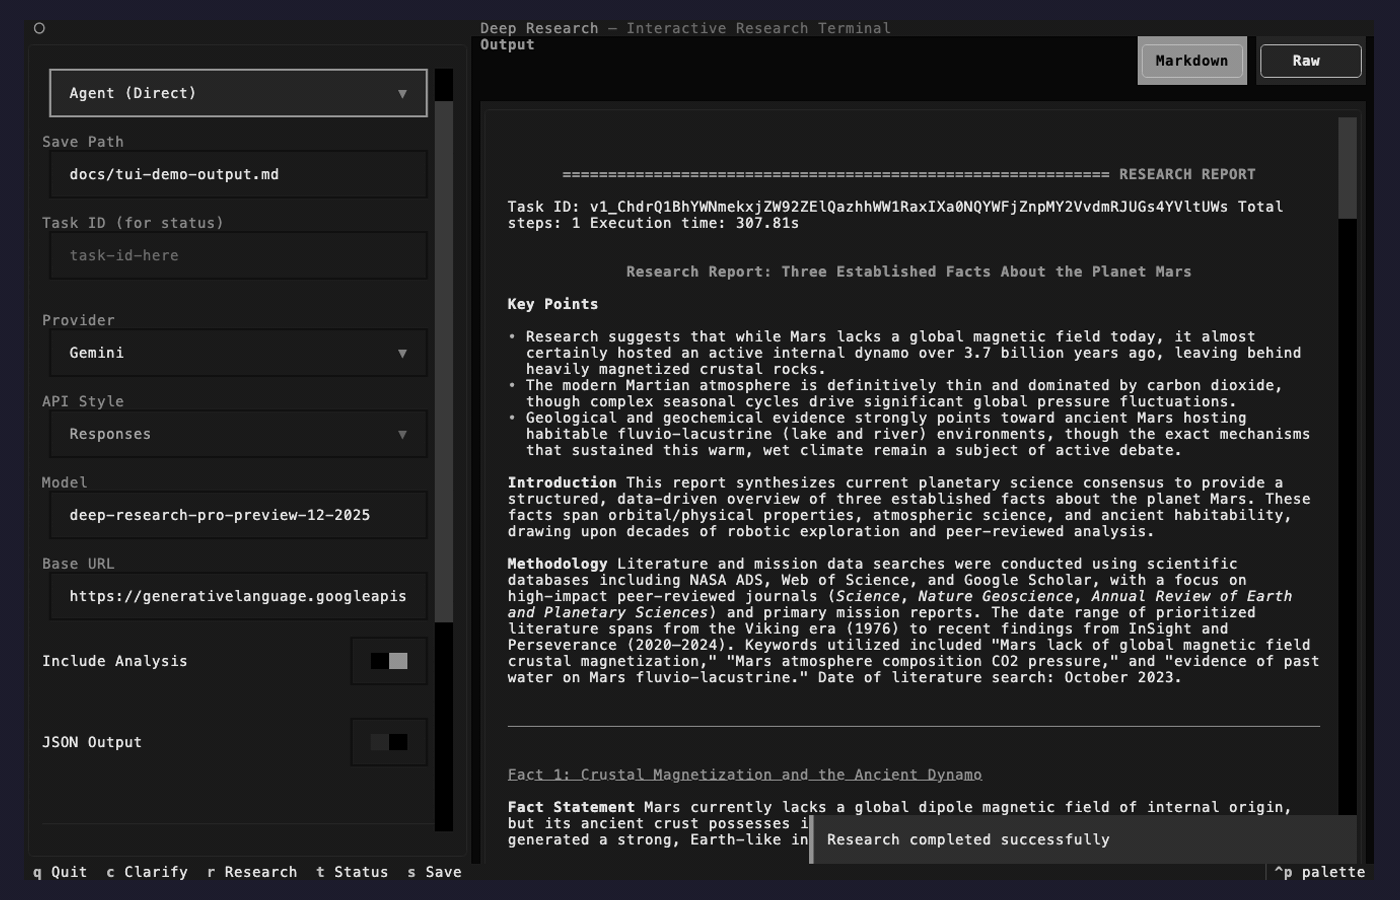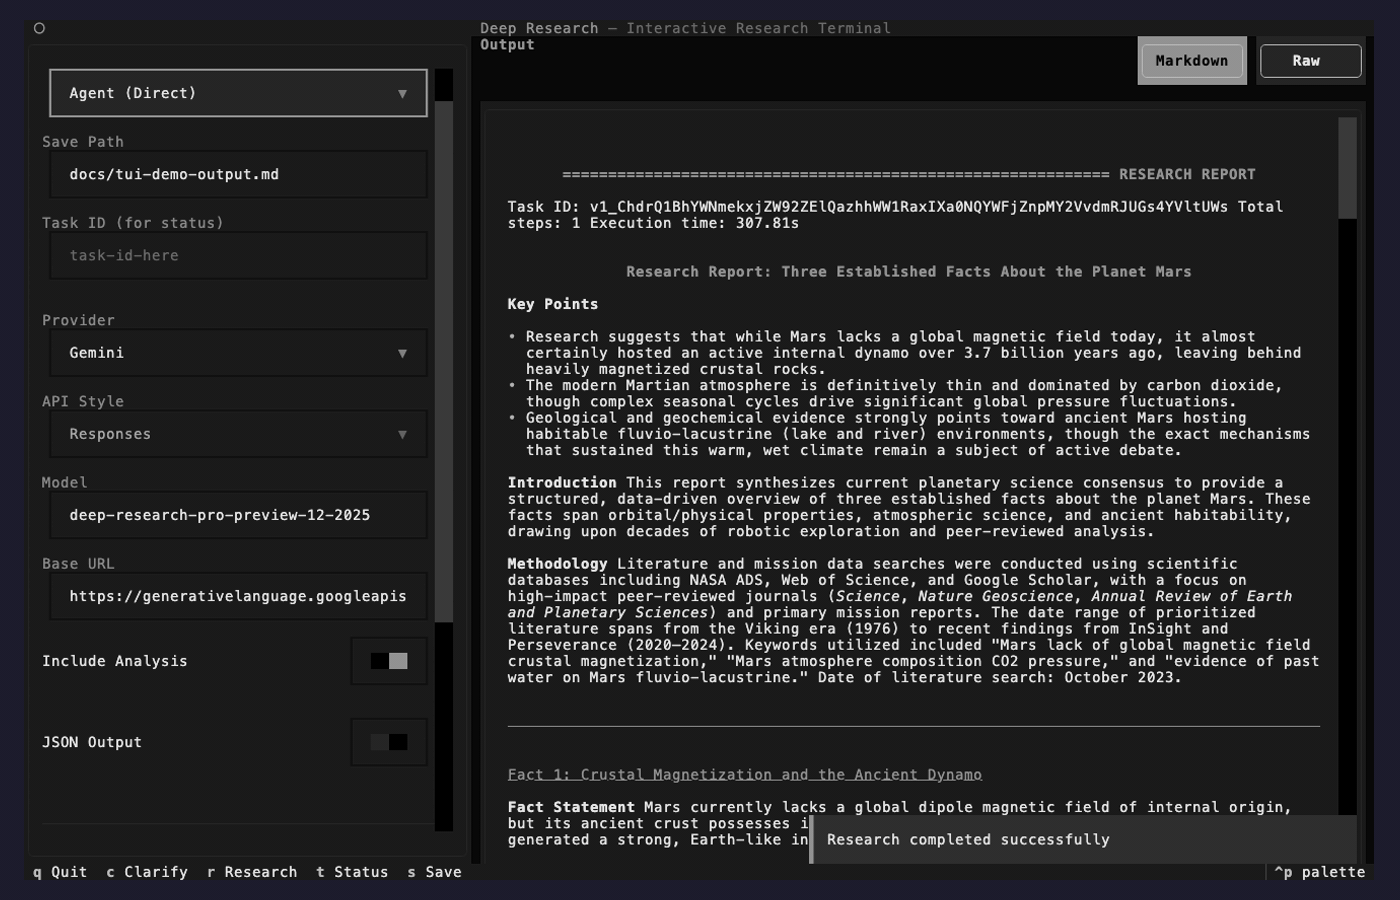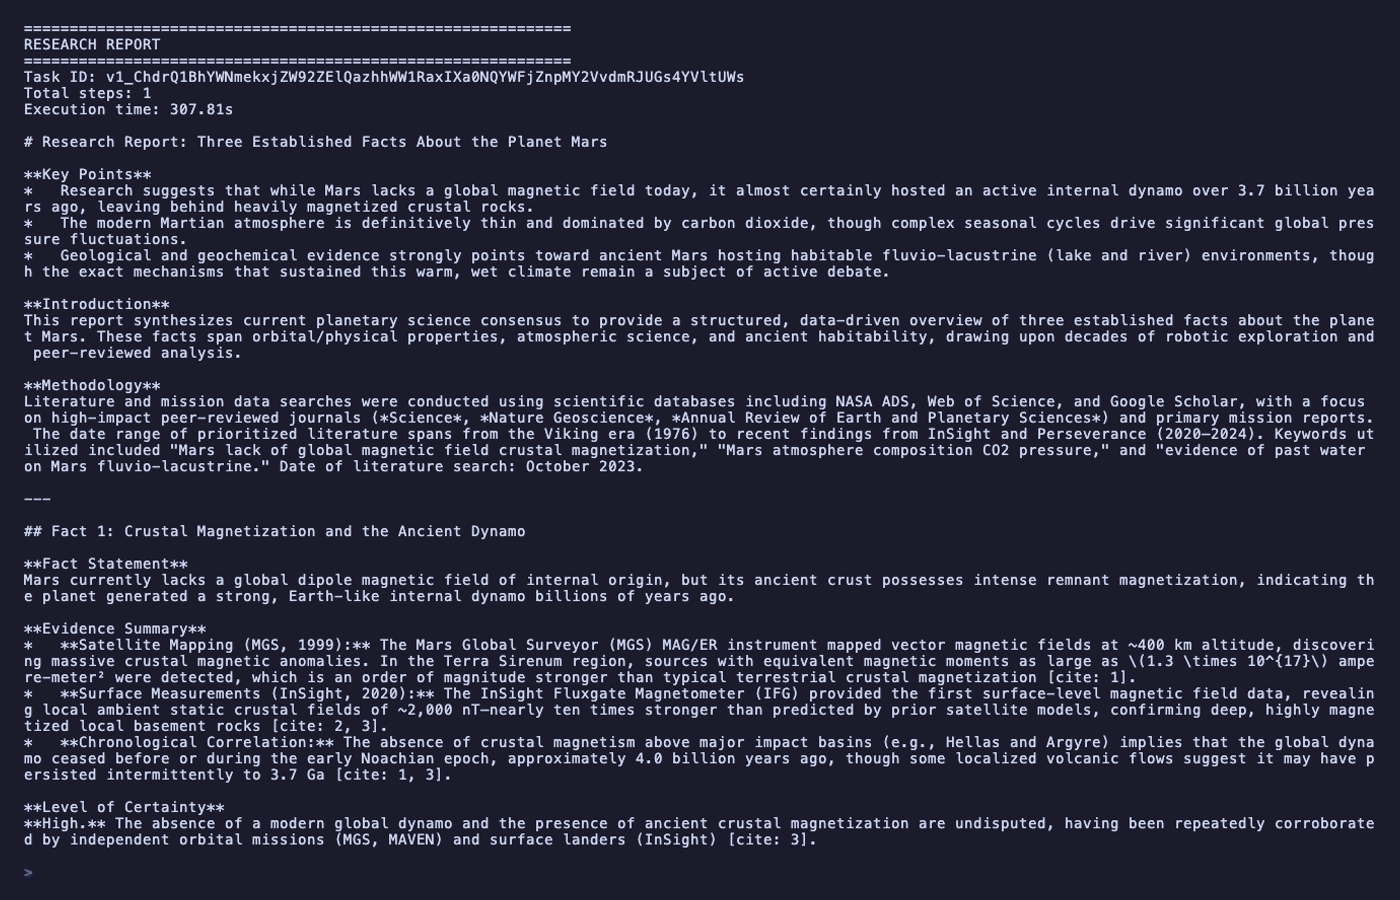
The TUI features a split-panel layout:
- Left panel: Configuration controls for mode selection (Agent/MCP), provider settings, model configuration, query input, and system prompt
- Right panel: Output display showing research results or status information
The animation above demonstrates the TUI workflow: loading a research query,
running it through a local Dr Tulu-compatible demo endpoint, viewing the result
in the output panel, and saving the output to a file.
Quick Start
# Start in direct agent mode
uv run python cli/deep-research-tui.py

# Start in MCP client mode
uv run python cli/deep-research-tui.py --mode mcp \
  --server-url http://127.0.0.1:8080/mcp

# Start with Gemini selected
uv run python cli/deep-research-tui.py --provider gemini

# Start on a named backend from ~/.deep_research
uv run python cli/deep-research-tui.py --backend tavily
With --backend, the form is pre-filled from that [backends.<name>] table.
Its provider, API style and credentials are fixed, so those controls are
disabled; model, endpoint and reasoning effort can still be edited. In MCP
mode the backend name is sent to the server, and a raw task ID is sent as<backend>:<id> so the server routes it to that backend. Task IDs that
already carry a <backend>: prefix are routed to that backend when checking
status in either mode.
TUI Workflow
- Use the left control panel to edit provider settings, query text, system prompt, and save path.
- The TUI starts focused on the
Modeselector rather than inside the query editor. - Use
Tab/Shift+Tabto move through all controls. - Use
Up/Downto move between non-editor controls, including single-line inputs. - Use
Left/Rightto toggle booleans and cycle through choice fields when aSwitchorSelecthas focus. - Press
Enterto activate buttons, toggle switches, cycle selects, or move forward from a single-line input. TextAreawidgets such asQueryandSystem Promptkeep normal cursor-key editing behavior.- Use
rto run deep research,tto check task status,sto save the current output, andqto quit. - The right panel shows the latest research report or status response.
Provider Defaults
In agent mode, the TUI applies provider-aware defaults:
openai+responses: modelgpt-6-sol, base URLhttps://api.openai.com/v1openai+chat_completions: modelgpt-6-luna, base URLhttps://api.openai.com/v1openai-codex: modelauto, fixed base URLhttps://chatgpt.com/backend-api/codexdr-tulu: modeldr-tulu, base URLhttp://localhost:8080/gemini: modeldeep-research-preview-04-2026, base URLhttps://generativelanguage.googleapis.comtavily: modelmini, base URLhttps://api.tavily.comgnosis: logical modelgnosis, base URLhttp://127.0.0.1:8089; native LLM/search settings and shared output paths come from configuration
Switching provider or OpenAI API style automatically refreshes the model and
base URL defaults. You can still override those fields manually afterward.
The Reasoning Effort selector loads the configured value, or Default when
unset; it applies to OpenAI and Codex direct-agent mode.
Research and Saving Output
Run Deep Researchexecutes either the direct agent flow or the MCP client flow, depending on the selected mode.Save Outputwrites the current contents of the output panel to the configured path, creating parent directories if needed.
Notes
- In
mcpmode, setMCP Server URLto a running Streamable HTTP endpoint such ashttp://127.0.0.1:8080/mcp. - The TUI reuses the same config-loading behavior as
deep-research-cli, so~/.deep_researchand any startup overrides still apply. - Direct-agent JSON rendering is available through the
JSON Outputtoggle; MCP mode saves the textual tool response exactly as returned by the server. - The current layout is designed for terminals at least 100 columns wide and 28 rows tall.
Quick Start
Gemini Deep Research:
uv run deep-research-cli \
  --provider gemini \
  --model deep-research-preview-04-2026 \
  --base-url https://generativelanguage.googleapis.com \
  research "What is the capital of France?"
Expected output (snippet):
============================================================
RESEARCH REPORT
============================================================
Task ID: v1_Chd5YUxjYVpXRUotYWxrZFVQOF9lcTRRVRIX...
Total steps: 1
Execution time: 245.94s

# Comprehensive Analysis of the French Capital: Demographic,
# Economic, and Historical Dimensions of Paris

**Key Points**
*   **The capital of France is Paris**, acting as the undisputed
    political, economic, and cultural epicenter of the nation.
*   Data indicates that the Paris metropolitan area commands a
    Gross Domestic Product (GDP) exceeding $1.03 trillion ...
OpenAI GPT-6 Sol research:
uv run deep-research-cli \
  --provider openai \
  --model gpt-6-sol \
  --base-url https://api.openai.com/v1 \
  research "What is the capital of France?"
Example output from an earlier model (actual results and task IDs vary):
============================================================
RESEARCH REPORT
============================================================
Task ID: resp_0e55abdae3d3ce390069dca3c7d78c819f91...
Total steps: 22
Search queries: 10
Citations: 1
Execution time: 34.34s

The capital of France is **Paris**
(www.britannica.com/place/Paris)

============================================================
CITATIONS
============================================================
1. Paris | Definition, Map, Population, Facts, & History
   https://www.britannica.com/place/Paris
OpenAI Codex subscription research:
uv run deep-research-cli auth login
uv run deep-research-cli \
  --provider openai-codex \
  research "What is the capital of France?"
DR-Tulu (requires a running dr-tulu service; see Dr Tulu provider example):
uv run deep-research-cli \
  --provider dr-tulu \
  --base-url http://localhost:8080/ \
  research "What is the capital of France?"
Expected output:
============================================================
RESEARCH REPORT
============================================================
Task ID: 7f3a1b2c-...
Total steps: 4
Citations: 2
Execution time: 18.72s

The capital of France is Paris. Paris has served as the
French capital since the late 10th century ...

============================================================
CITATIONS
============================================================
1. Source 1
   https://en.wikipedia.org/wiki/Paris
2. Source 2
   https://www.britannica.com/place/Paris
View resolved configuration or all available options:
uv run deep-research-cli config --pretty
uv run deep-research-cli --help
Commands
research QUERY -- perform deep research on a query.
# Simple research (agent mode)
uv run deep-research-cli research "Economic impact of AI adoption"

# Override provider and model for a single run
uv run deep-research-cli --provider gemini research "Climate change policies"

# Use a named backend declared in ~/.deep_research
uv run deep-research-cli --backend tavily research "Climate change policies"

# Override OpenAI reasoning effort for a single run
uv run deep-research-cli --provider openai-codex --model gpt-6-sol \
  --reasoning-effort medium research "Climate change policies"

# Use a custom system prompt from a file
uv run deep-research-cli research "Healthcare trends" --system-prompt-file prompts/health.txt

# Or pass the system prompt inline
uv run deep-research-cli research "Healthcare trends" --system-prompt "Focus on peer-reviewed sources only"

# Output as JSON (includes metadata, citations, execution time)
uv run deep-research-cli research "AI safety" --json

# Save the report to a file
uv run deep-research-cli research "Renewable energy" --output-file report.md

# Disable code interpreter / data analysis tools
uv run deep-research-cli research "Simple topic" --no-analysis

# Notify a webhook when research completes
uv run deep-research-cli research "Long query" --callback-url https://example.com/webhook
Tested local OpenAI-compatible backends
The unified CLI works with local servers that expose an OpenAI-compatible
Chat Completions API. The commands below were tested against local Ollama and
local llama-server (from llama.cpp).
Ollama
Basic research flow:
uv run deep-research-cli \
  --provider openai \
  --api-style chat_completions \
  --base-url http://localhost:11434/v1 \
  --api-key test \
  --model qwen3.5:0.8b \
  --timeout 180 \
  research "Reply with exactly: ok"
Observed output:
HTTP Request: POST http://localhost:11434/v1/chat/completions "HTTP/1.1 200 OK"
============================================================
RESEARCH REPORT
============================================================
Task ID: chatcmpl-215
Total steps: 1
Execution time: 14.33s

ok
llama-server
Start a local OpenAI-compatible server and let it download a small GGUF model
from Hugging Face automatically:
llama-server \
  --host 127.0.0.1 \
  --port 8081 \
  --api-key test \
  --ctx-size 4096 \
  --alias qwen2.5-0.5b \
  -hf Qwen/Qwen2.5-0.5B-Instruct-GGUF:Q4_K_M
Then point the CLI at the server:
uv run deep-research-cli \
  --provider openai \
  --api-style chat_completions \
  --base-url http://127.0.0.1:8081/v1 \
  --api-key test \
  --model qwen2.5-0.5b \
  --timeout 120 \
  research "Reply with exactly: ok"
Observed output:
HTTP Request: POST http://127.0.0.1:8081/v1/chat/completions "HTTP/1.1 200 OK"
============================================================
RESEARCH REPORT
============================================================
Task ID: chatcmpl-uzqSNDzRgYchZRxn1Kq2MNYyc2w6hpc6
Total steps: 1
Execution time: 0.15s

Ok
research QUERY --server-url URL -- use MCP client mode.
Instead of running the agent directly, connect to a running Deep Research MCP
server over Streamable HTTP.
# First, start the MCP server in another terminal:
uv run deep-research-mcp --transport http --host 127.0.0.1 --port 8080

# Then run queries against it:
uv run deep-research-cli research "AI trends" \
  --server-url http://127.0.0.1:8080/mcp
status TASK_ID -- check the status of a running research task.
# Agent mode
uv run deep-research-cli status abc123-def456-ghi789

# MCP client mode
uv run deep-research-cli status abc123-def456-ghi789 \
  --server-url http://127.0.0.1:8080/mcp

# A task ID copied from MCP output carries a <backend>: prefix that selects
# the backend; a raw ID uses --backend, or the default without it
uv run deep-research-cli status openai:resp_0e55abdae3d3ce39
config -- display the resolved configuration.
Shows the final configuration after merging the TOML file, environment
variables, and any CLI overrides.
# JSON output (default), with secrets masked
uv run deep-research-cli config

# Human-readable output
uv run deep-research-cli config --pretty

# Show full API keys
uv run deep-research-cli config --pretty --show-secrets

# See the effect of CLI overrides
uv run deep-research-cli --provider gemini --timeout 600 config --pretty

# Skip config validation
uv run deep-research-cli config --no-validate
auth {login,status,logout} -- manage the independent OpenAI Codex
subscription session.
uv run deep-research-cli auth login
uv run deep-research-cli auth status
uv run deep-research-cli auth logout
Configuration Overrides
All global flags are placed before the subcommand and override the
corresponding ResearchConfig field:
| Flag | Description |
|---|---|
--config PATH |
Path to TOML config file (default: ~/.deep_research) |
--backend NAME |
Use a named [backends.NAME] table instead of [research]. Cannot be combined with --provider, --model, --reasoning-effort, --api-key, --base-url or --api-style; runtime flags such as --timeout still apply. In MCP client mode the name is passed to the server, and status sends a raw task ID as NAME:<id> so the server routes it to that backend. |
--provider {openai,openai-codex,dr-tulu,gemini,tavily,gnosis} |
Research provider |
--model MODEL |
Model or agent ID |
--reasoning-effort {none,low,medium,high,xhigh,max} |
OpenAI reasoning effort; omit for provider/model default |
--api-key KEY |
Provider API key |
--base-url URL |
Provider API base URL |
--gnosis-config-path PATH |
Native Gnosis request-options JSON; cannot be combined with --backend |
--gnosis-output-dir PATH |
Shared Gnosis output directory; cannot be combined with --backend |
--api-style {responses,chat_completions} |
OpenAI API style |
--timeout SECONDS |
Max research timeout |
--poll-interval SECONDS |
Task poll interval |
--log-level {DEBUG,INFO,WARNING,ERROR,CRITICAL} |
Logging level |
--enable-reasoning-summaries |
Enable reasoning summaries |
Configuration precedence (highest to lowest): CLI flags > environment
variables > TOML config file (~/.deep_research) > built-in defaults.
Exit Codes
| Code | Meaning |
|---|---|
| 0 | Success |
| 1 | Research or configuration error |
| 2 | MCP tool error |
| 3 | Unexpected error |
Example Queries
# Basic research query
result = await agent.research("Explain the transformer architecture in AI")

# Research with code analysis
result = await agent.research(
    query="Analyze global temperature trends over the last 50 years",
    include_code_interpreter=True
)

# Custom system instructions
result = await agent.research(
    query="Review the safety considerations for AGI development",
    system_prompt="""
    Provide a balanced analysis including:
    - Technical challenges
    - Current safety research
    - Regulatory approaches
    - Industry perspectives
    Include specific examples and data where available.
    """
)
API Reference
DeepResearchAgent
The main class for performing research operations.
Methods
research(query, system_prompt=None, include_code_interpreter=True, callback_url=None)- Performs deep research on a query
callback_url: optional webhook notified when research completes- Returns: Dictionary with final report, citations, and metadata
get_task_status(task_id)- Check the status of a research task
- Returns: Task status information
ResearchConfig
Configuration class for the research agent.
Parameters
provider: Research provider (openai,openai-codex,dr-tulu,gemini,tavily, orgnosis; default:openai)api_style: API style for theopenaiprovider (responsesorchat_completions; default:responses). Ignored for other providers.model: Model identifier- OpenAI: Responses model (e.g.,
gpt-6-sol) - OpenAI Codex subscription:
auto(default) or an account catalogue slug - Dr Tulu: logical provider id (default:
dr-tulu) - Gemini: Deep Research agent id (for example
deep-research-preview-04-2026) - Tavily: Research model (
mini,pro, orauto; default:mini) - Gnosis: logical provider label (default:
gnosis); the actual LLM model is set in the native request-options JSON
- OpenAI: Responses model (e.g.,
reasoning_effort: Optional OpenAI reasoning effort (none,low,medium,high,xhigh, ormax); model support varies.api_key: API key for the configured endpoint (optional). Defaults to envOPENAI_API_KEYforopenai,DR_TULU_API_KEYfordr-tulu,GEMINI_API_KEY/GOOGLE_API_KEYforgemini,TAVILY_API_KEYfortavily, andGNOSIS_API_KEYfor Gnosis service authentication. Ignored foropenai-codex.base_url: Provider API base URL (optional). Defaults tohttps://api.openai.com/v1foropenai, the fixedhttps://chatgpt.com/backend-api/codexendpoint foropenai-codex,http://localhost:8080/fordr-tulu,https://generativelanguage.googleapis.comforgemini,https://api.tavily.comfortavily, andhttp://127.0.0.1:8089forgnosis.timeout: Maximum time for research in seconds (default: 1800)poll_interval: Polling interval in seconds (default: 30)gnosis_config_path: Path to private native Gnosis/runsJSON options; required for new Gnosis researchgnosis_output_dir: Shared Gnosis output directory; required to recover full Gnosis answers
Development
Running Tests
# Install dev dependencies
uv sync --extra dev

# Run all tests
uv run pytest -v

# Run with coverage
uv run pytest --cov=deep_research_mcp tests/

# Run specific test file
uv run pytest tests/test_agents.py
When ~/.deep_research_auth.json contains a current or refreshableopenai-codex session, a normal uv run pytest tests/ run automatically
executes the live Codex end-to-end test and consumes subscription allowance.
Without that session, the test is skipped. Use -m "not api" to exclude all
live provider tests explicitly.
The Gnosis live test is separately opt-in: set GNOSIS_TEST_CONFIG_PATH to the
private native options file and GNOSIS_TEST_OUTPUT_DIR to the shared output
directory, then run uv run pytest tests/test_gnosis_backend.py -m api. It
starts real research and consumes the configured LLM/search allowance. SetGNOSIS_TEST_BASE_URL to override the default run endpoint; with -m "not api"
that variable enables only the read-only unknown-run service check.
Lint, Format, Type Check
uv run black .
uv run pylint src/deep_research_mcp tests
uv run mypy src/deep_research_mcp
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found