Our survey
From Existing Methods to New Research Ideas: Two Perspectives on Recursive Self-Improvement
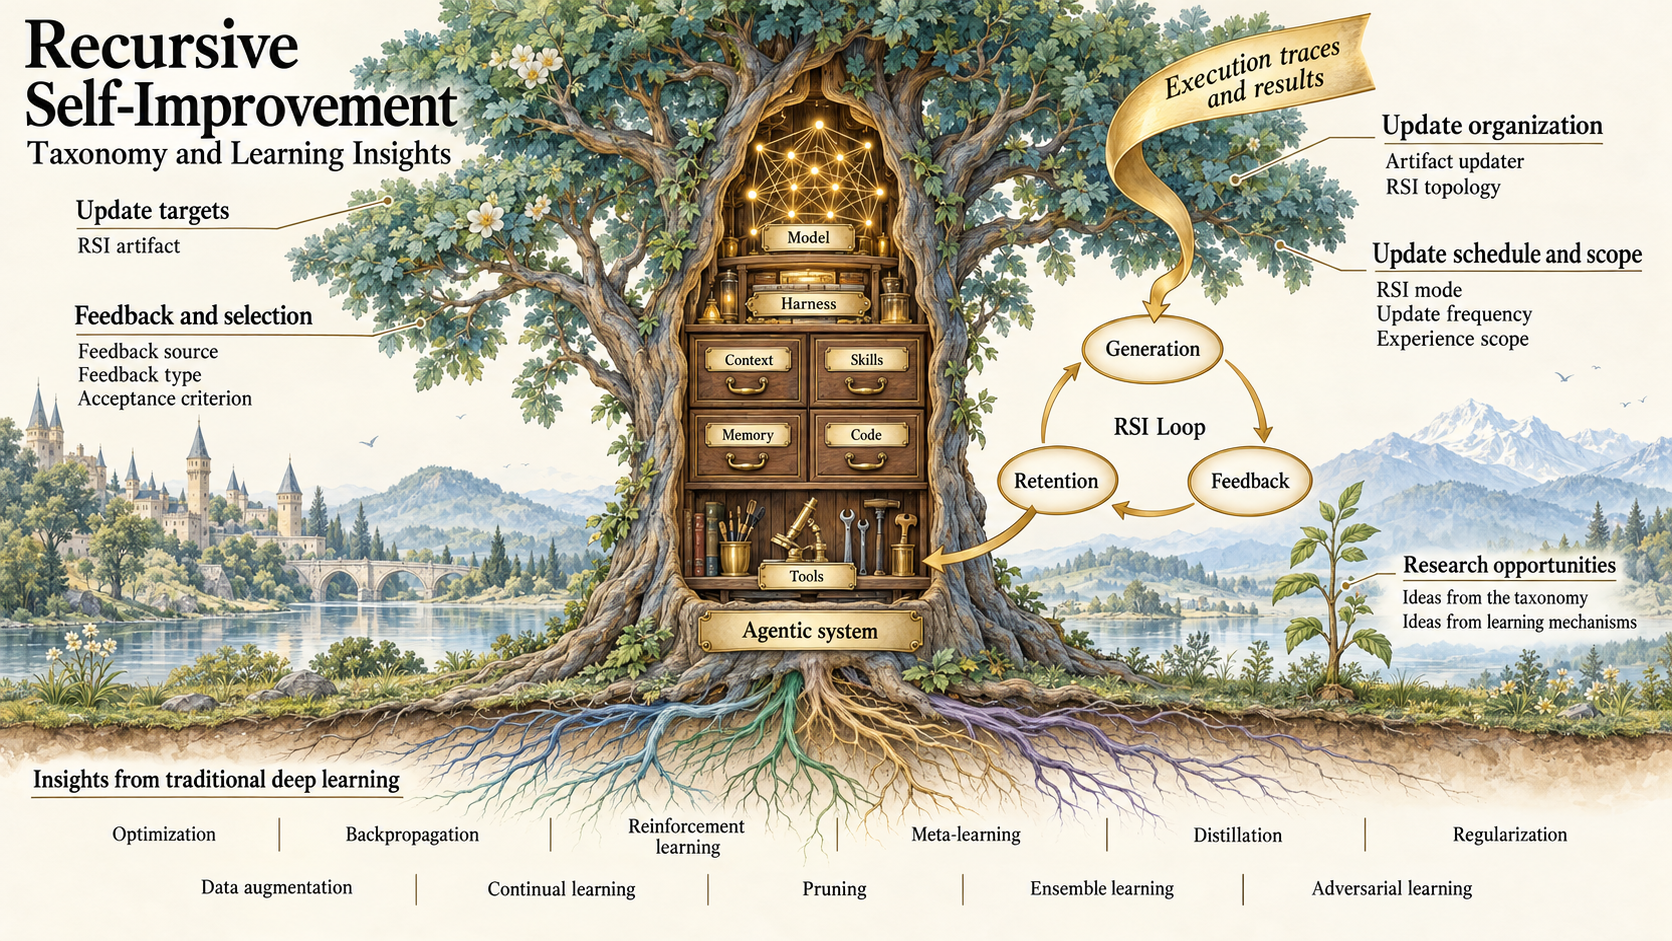
A nine-dimension taxonomy of RSI methods and insights from traditional deep learning to inspire new research.
Watch the walkthrough · 1 min
https://github.com/user-attachments/assets/70f488af-925c-4b93-ba03-5c84711b8dbf
Start here
Awesome RSI collects benchmarks, methods, and systems for Recursive Self-Improvement. We follow the loop: an agent performs tasks, learns from trajectories and feedback, updates its own state, and uses that updated state in later work. That state can be model parameters, harness code, context, memory, or skills.
113 method papers · 33 benchmark papers · 3 systems
| Looking for… |
Start with… |
| An introduction to RSI |
Understanding RSI — an illustrated guide, available in English and Chinese. |
| A method to build on |
Methods & Systems — filter by artifacts, topology, feedback, and more. |
| A way to measure improvement |
Benchmarks — compare artifacts and online, offline, or hybrid protocols. |
| Connections between papers |
Citation graphs — switch between methods and benchmarks, search for a node, zoom, and pan. |
| More background |
Books, courses, and learning materials. |
Paper map
Each list in this README is organized along one dimension: RSI artifact for methods and systems, and RSI mode for benchmarks. For more ways to explore the collection, visit the Awesome RSI website, where you can compare additional dimensions and combine filters to find work that matches your interests.
What does the agent improve? The tree below follows the RSI artifact dimension.
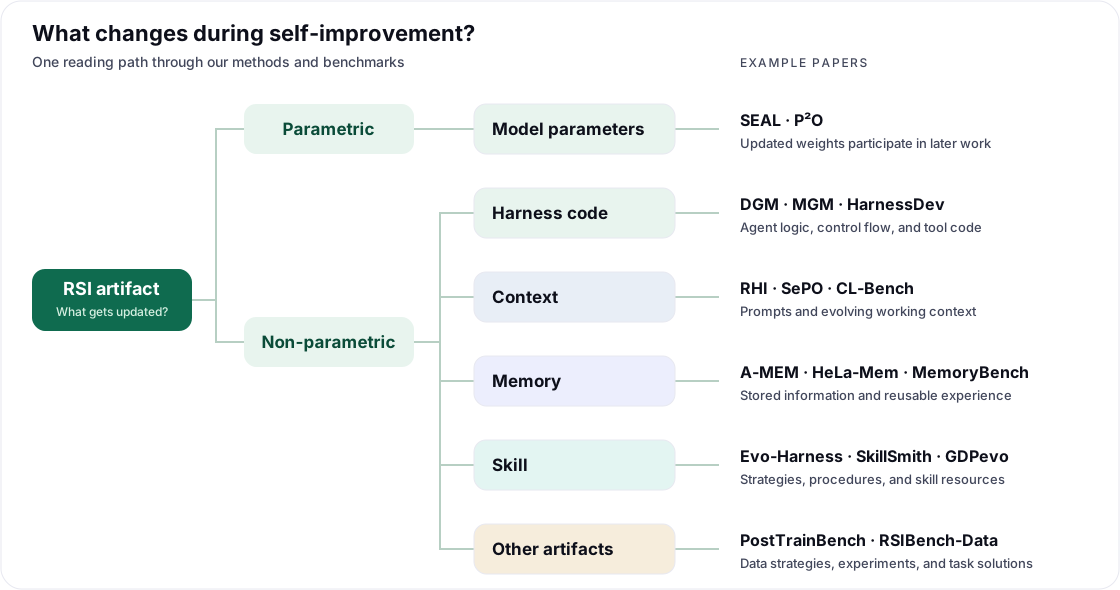
Model parameters · Harness code · Context · Memory · Skill · Other artifacts · Benchmarks
The tree shows examples from the collection. The lists below use the website's existing labels; a work can appear under multiple artifacts. Inclusion covers both explicit self-modification and experience-driven improvement during long-running tasks.
Methods & Systems
Compare all dimensions on the website →
Grouped by RSI artifact and ordered by first publication or project release date, newest first. Conference labels reflect the venue recorded in the collection; projects link to their repositories.
Model parameters
The student's model parameters are updated to improve task performance. This includes a teacher using student performance feedback to refine successive training rounds, even when each round restarts from the initial model, as well as the updated student continuing to learn from later tasks.
Harness code
Executable agent, harness, control-flow, self-improvement, or tool code is modified.
Context
Prompts or working context are updated. Observations, feedback, and experience can accumulate or be reorganized during a continuous run to guide later actions or tasks.
| Paper or project |
Publication |
| HarnessPro: Recursive Harness Self-Improvement with Pareto Optimization for Performance-Cost Trade-offs |
arXiv preprint |
| EvoAlloc: A Self-Evolving Resource Allocation Agent for Efficient Program Evolution |
arXiv preprint |
| EvoBelief: Falsifiable World Models for Self-Improving LLM Agents |
arXiv preprint |
| RoboRSI: Stable, efficient, and reusable robot self-evolution in complex real-world environments |
arXiv preprint |
| Learning from Revision Consequences: Hindsight Meta-Experience Distillation for Self-Improving Agents |
arXiv preprint |
| EviSkill: Grounding Skill Evolution in Replayable Evidence |
arXiv preprint |
| MESH-Harness: Self-Improving Agent Harnesses via Bandit-Guided Compositional Evolution |
arXiv preprint |
| VERSE: Verified Self-Evolving Optimizer for Agent Harnesses |
arXiv preprint |
| Learning from Research: Toward Lifelong Agent Harness Evolution |
arXiv preprint |
| NavHarness: Towards Lifelong Embodied Navigation |
arXiv preprint |
| MoMHa: Multi-Objective Optimization of LLM Harnesses over Accuracy, Safety, and Tokens |
NeurIPS 2026 |
| SkillEvoReg: Regularizing Agent Skill Evolution Against Overfitting |
arXiv preprint |
| SkillRefine: Cross-Source Skill Induction and Execution Validation for LLM Agents in Refinery Planning Software |
arXiv preprint |
| A Wrong Turn Does Not Ruin the Journey: Deviation-Guided Skill Self-Evolution for LLM Agents |
arXiv preprint |
| HarnessPAI: An Evolving Harness for Physical AI |
arXiv preprint |
| SEEK: Skill-Routed Evaluation with Evolvable Knowledge for Industrial Search |
arXiv preprint |
| Grow the Harness, Not the Context: From Strategy-Free Scaffolds to Reusable Specialist Agents |
arXiv preprint |
| Harness as a Language: A Minimalist Agent Framework With Maximal Expressivity |
arXiv preprint |
| Recursive self-improvement of AI research agents |
arXiv preprint |
| Harness-Zero: Harness Distillation via Agent-as-Harness |
arXiv preprint |
| RRSI: Regularized Recursive Self-Improvement of Agent Harnesses |
arXiv preprint |
| TTSE: A Two-Track Online Self-Evolution Framework |
arXiv preprint |
| Designer-RSI: Evolving Procedural Memory from User Traffic for Agentic Graphic Design |
arXiv preprint |
| Self Improvement via Fast Tree-search |
arXiv preprint |
| SkillAA: Attribution-Guided Skill-Graph Updating with Targeted Validation and Rollback |
arXiv preprint |
| SoL-Pi: Recursively Scaling Auto-Research Loops for Efficient Agent Harness |
arXiv preprint |
| EvolveTrade: Experience-Driven Policy Refinement for Self-Evolving LLM Trading Agents |
arXiv preprint |
| Reflect, Revise, Reuse: Training-Free Skill Evolution for GUI Agents |
arXiv preprint |
| AlgoEvo: Self-Evolving Agentic Search for Automated Algorithm Discovery |
arXiv preprint |
| AnchorGUI: Asymmetric Memory for Dual-Scale Learning in GUI Navigation |
ECCV 2026 |
| EvoOntology: A Self-Evolving Ontology Layer for Data Agents |
arXiv preprint |
| ModularRSI: Modular and Generalizable Recursive Harness Self-Improvement |
arXiv preprint |
| RSIAgent: Autonomous Exploration for Recursive Self-improvement in New Environments |
arXiv preprint |
| Dream-RSI: Recursive Self-Improvement through Evolving Worlds |
Preprint |
| COBRA-Skills: Contextual Bandit-Guided Evolution for Agent Skill Optimization |
arXiv preprint |
| Ecdysis: Efficient and Effective Training of Runtime Harnesses for LLM Agents |
arXiv preprint |
| Code-to-Harness: Distilling Black-Box Optimizers from Self-Play |
arXiv preprint |
| Experience Funnel: A State-Policy Alternating Loop for Self-Evolving Agents |
arXiv preprint |
| Procedural Graphs: Self-Evolving Execution Structures for LLM Agents |
arXiv preprint |
| SkillAdam: Stable and Efficient Skill Evolution for Agents |
arXiv preprint |
| SimSkill: A Self-Evolving LLM Agent for Skill and Knowledge Accumulation in Traffic Simulation |
arXiv preprint |
| CHIME: Credit-Aware Hierarchical Memory Evolution for Long-Horizon Agentic Planning |
arXiv preprint |
| Reef: Continual Learning Infrastructure for Self-Improving Agents |
Project · v0.0.2 |
| SkillGLoW: Procedural-Family Skill Consolidation for Self-Improving Agents on Long-Horizon Task Streams |
arXiv preprint |
| Harness-of-Harness: Multi-Day Autonomous Software Development with Continual Improvement |
arXiv preprint |
| HarnessEvolve: Learning from Reference Trajectories for Reliable Agent Self-Evolution |
arXiv preprint |
| PILOT in the Loop: Live Self-Improvement for Long-Horizon Agents |
arXiv preprint |
| WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution |
arXiv preprint |
| Recursive Experiential-Working Memory Evolution for Long-Horizon Agent Harnesses |
arXiv preprint |
| MediSkill-Evo: Process-Constrained Self-Evolution for Evidence-Grounded Clinical Interaction |
arXiv preprint |
| Prime Agent: A Self-Improving RLM Harness |
arXiv preprint |
| Proteus: A Harness-Agnostic Self-Evolution Framework for AI Agents |
Project · v0.3.0 |
| TRACE: A Self-Evolving Skill Bank for Consistent, Limit-Aware LLM Agents |
arXiv preprint |
| ForeDreamer: A Self-Evolving Dual-Agent Memory Architecture for Future Event Prediction |
Findings of EMNLP 2026 |
| EnvHarness: Awakening Static Worlds for Agent Learning |
arXiv preprint |
| HyperSkill: Self-Evolving LLM Agents via Hypergraph-Structured Skill Memory |
arXiv preprint |
| Evo-Harness: Context-to-Harness Skill Compilation for Self-Evolving Agents |
arXiv preprint |
| DIVE: Unlocking Self-Improvement in Frozen Language Models Through Diversity-Driven Skill Evolution |
arXiv preprint |
| Mendel Gödel Machine: Recursive Self-Improving Coding Agents via Comparative Evolution |
arXiv preprint |
| SkillHEX: Improving Agent Skills via Hypothesis-Driven Autonomous Exploration and Exploitation |
arXiv preprint |
| EvolveNet: Collaborative Harness Evolution for Agent Self-Improvement |
arXiv preprint |
| DarwinX: Evolving Agent Harnesses Through Natural Selection |
arXiv preprint |
| Knowledge-Centric Self-Improvement |
arXiv preprint |
| Recursive Harness Self-Improvement |
arXiv preprint |
| HarnessBank: Semantic Gene-Bank Search with Gated Verification for Agent-Harness Self-Evolution |
arXiv preprint |
| SAGEAgent: A Self-Evolving Agent for Cost-Aware Modality Acquisition in Multimodal Survival Prediction |
arXiv preprint |
| The Red Queen Gödel Machine: Co-Evolving Agents and Their Evaluators |
arXiv preprint |
| When Rules Learn: A Self-Evolving Agent for Legal Case Retrieval |
ACL 2026 |
| HarnessX: A Composable, Adaptive, and Evolvable Agent Harness Foundry |
arXiv preprint |
| Self-Harness: Harnesses That Improve Themselves |
arXiv preprint |
| From Failed Trajectories to Reliable LLM Agents: Diagnosing and Repairing Harness Flaws |
arXiv preprint |
| OpenSkill: Open-World Self-Evolution for LLM Agents |
arXiv preprint |
| SePO: Self-Evolving Prompt Agent for System Prompt Optimization |
arXiv preprint |
| SkillRevise: Improving LLM-Authored Agent Skills via Trace-Conditioned Skill Revision |
Findings of EMNLP 2026 |
| ExpGraph: Model-Agnostic Experience Learning with Graph-Structured Memory for LLM Agents |
arXiv preprint |
| PANDO: Efficient Multimodal AI Agents via Online Skill Distillation |
arXiv preprint |
| DemoEvolve: Overcoming Sparse Feedback in Agentic Harness Evolution with Demonstrations |
arXiv preprint |
| Continual Harness: Online Adaptation for Self-Improving Foundation Agents |
arXiv preprint |
| LLMs Improving LLMs: Agentic Discovery for Test-Time Scaling |
arXiv preprint |
| Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses |
arXiv preprint |
| Mem²Evolve: Towards Self-Evolving Agents via Co-Evolutionary Capability Expansion and Experience Distillation |
ACL 2026 |
| Meta-Harness: End-to-End Optimization of Model Harnesses |
arXiv preprint |
| P²O: Joint Policy and Prompt Optimization |
arXiv preprint |
| Hyperagents |
arXiv preprint |
| Group-Evolving Agents: Open-Ended Self-Improvement via Experience Sharing |
arXiv preprint |
| Meta Context Engineering via Agentic Skill Evolution |
ICML 2026 |
| Huxley-Gödel Machine: Human-Level Coding Agent Development by an Approximation of the Optimal Self-Improving Machine |
ICLR 2026 Oral |
| Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models |
ICLR 2026 |
| ReasoningBank: Scaling Agent Self-Evolving with Reasoning Memory |
ICLR 2026 |
| Memp: Exploring Agent Procedural Memory |
Findings of ACL 2026 |
| GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning |
ICLR 2026 Oral |
| Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents |
ICLR 2026 |
| Dynamic Cheatsheet: Test-Time Learning with Adaptive Memory |
EACL 2026 |
| Gödel Agent: A Self-Referential Agent Framework for Recursive Self-Improvement |
ACL 2025 |
| Cradle: Empowering Foundation Agents Towards General Computer Control |
ICML 2025 |
Memory
Information or experience is stored, updated, and retrieved across steps, trajectories, or tasks.
Skill
Reusable strategies, procedures, workflows, or skill resources are created and revised.
Other artifacts
Other artifacts evolve, such as data strategies, experiment configurations, or task solutions.
Benchmarks
Compare benchmark dimensions on the website →
Grouped by RSI mode, newest first. Benchmarks that support multiple protocols appear in each relevant group. Artifact labels describe what evolves in the evaluated workflow.
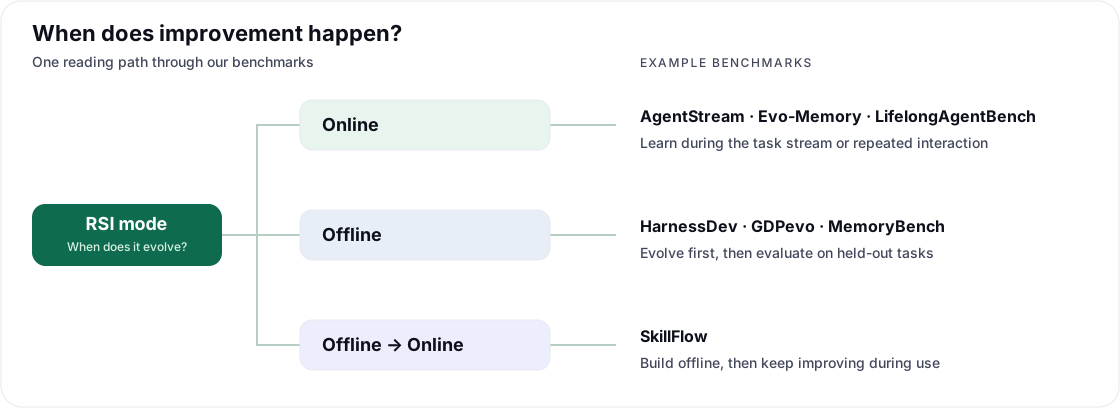
Online · Offline · Offline → Online
Online
Experience accumulates during the task stream or repeated interaction, and later work can use it.
Offline
Evolution precedes a separate held-out evaluation.
Offline to online
An artifact is built offline and continues to evolve during online use.
Use the explorer
- Choose a collection: Benchmark papers or Methods & Systems.
- Narrow the question: select multiple tags within a row, then combine dimensions across rows. For example, look for methods that update Skill, run Online, and use Environment feedback.
- Read and compare: search titles, sort by recency or citations, and expand abstracts and taxonomy profiles.
- Follow the connections: open Citation graph, choose methods or benchmarks, and search for a paper. Drag and zoom to explore its neighborhood.
The site supports English and Chinese, with the language switch in the upper-right corner.
Citation
If this collection is useful in your work, please cite it:
@misc{awesomersi2026,
  title        = {Awesome RSI: A Curated Collection of Recursive Self-Improvement Benchmarks and Methods},
  author       = {Prism-Shadow},
  year         = {2026},
  howpublished = {\url{https://github.com/Prism-Shadow/awesome-rsi}},
}
WeChat Group
Scan the QR code to join the Awesome RSI discussion group.
Back to top ↑