phd-citation-oracle
Health Warn
- No license — Repository has no license file
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 7 GitHub stars
Code Warn
- network request — Outbound network request in ψ/lab/citation/worker/worker.js
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Citation Oracle ✦ — an AI oracle for a PhD literature corpus: neural (bge-m3) semantic search + an interactive citation constellation, plus MIT-licensed Claude Code skills incl. a Gemini Deep Research prompt builder
Citation Oracle ✦
"No claim shines alone. Each is fixed in place by lines drawn to the light that came before."
— ทุกข้อกล่าวอ้างต้องมีดาวดวงอื่นค้ำไว้ ไม่มีข้ออ้างใดส่องแสงเดียวดาย
An AI Oracle that owns the literature side of a PhD on low-cost PM2.5 sensor confidence
assessment: the corpus, the citation graph, the bibliography, and the related-work chapter.
Born 25 July 2026, budded from DustBoy-Phd-Oracle
— the parent keeps the data and the defence; this one keeps the sources that ground them.
Human: Nat Weerawan (ณัฐ วีระวรรณ์) · Identity and principles: CLAUDE.md
What's actually here
maw citation — semantic search over the literature
A maw plugin (ψ/lab/citation/)
that indexes the paper corpus with neural embeddings and renders the citation graph.
./bin/citation status                # ← works with NO maw installed
./bin/citation cards                 # JSONL → one markdown card per paper in ψ/papers/
./bin/citation doi --write           # resolve authors + DOIs against Crossref
./bin/citation bib                   # cards → artifacts/citation.bib
./bin/citation index --vault         # embed the cards + the oracle's own notes
./bin/citation search "biomass burning haze northern thailand"
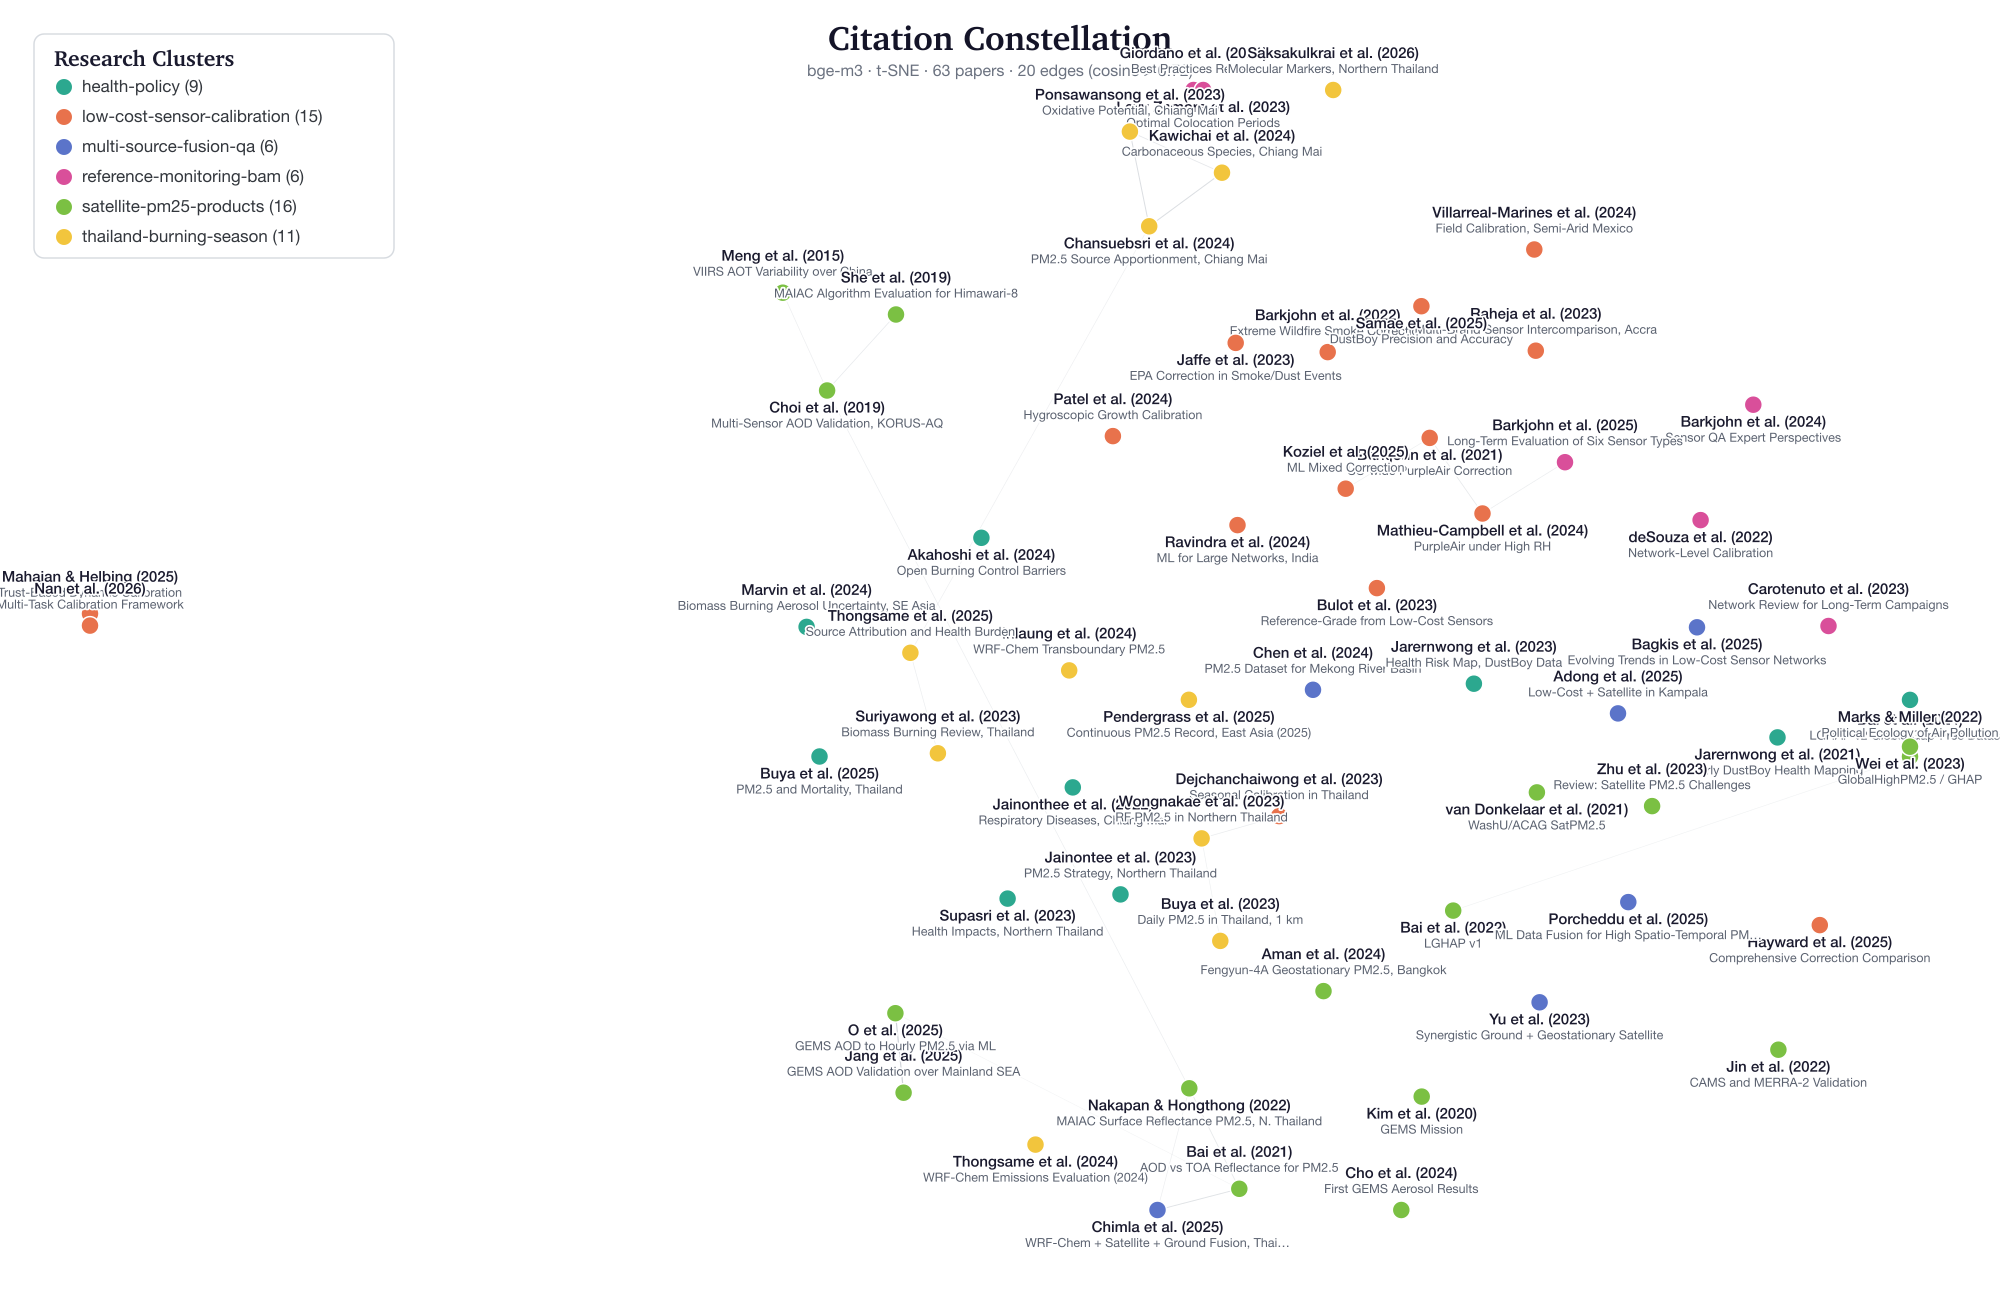
./bin/citation serve                 # interactive 2D constellation
./bin/citation graph --threshold 0.68 --html
Just cloned it? Start here
git clone https://github.com/Soul-Brews-Studio/phd-citation-oracle
cd phd-citation-oracle
./bin/citation status        # tells you what's present and what's missing
status is the one command that explains itself — it prints the repo root and how it was
found, the card count, DOI coverage, the vector store, your hardware, and which embedding
backend is reachable:
── citation status ──
  ✓ repo root: /…/phd-citation-oracle (walk up from the script)
  ✓ 62 paper card(s) in ψ/papers — 61 with a DOI, all citable
  ✓ store ready (…/.citation/store) — 62 paper(s) + 12 vault note(s) · 1024-dim · 296 KB
  ✓ hardware: Apple M5 Max · arm64 · 18 cores · 128 GB unified memory — Metal GPU available to ollama
  ✓ embeddings: ollama bge-m3 @ http://localhost:11434 — local, no token, no egress — 1024-dim
      └ bge-m3:latest · 634 MB · 100% GPU (fully resident — no CPU fallback) · 8192 ctx
Reading and searching the corpus needs an embedding backend. The default is fully local:
ollama pull bge-m3 && ollama serve    # your own GPU, no token, nothing leaves the machine
./bin/citation index --vault          # ~6 s for 74 items on an M5 Max
Only bun is required. There is nothing to npm install.
maw citation <verb> is identical if you have maw;
both entries share one implementation. The runner walks up from its own location forCLAUDE.md + ψ/, so it works from any directory. Bootstrap a fresh clone withscripts/setup-citation.sh.
No dependencies. 140 KB installed — no node_modules, no database. The vector store is
three plain files (vectors.f32, meta.jsonl, manifest.json) and search is brute-force
cosine in pure TypeScript. Embeddings come from ollama on your own GPU by default
(bge-m3, no token, nothing leaves the machine), falling back to a Cloudflare worker or the
Cloudflare REST API if you prefer a cloud embedder.
The corpus is markdown, not a database. Each paper is a card inψ/papers/ — citekey frontmatter (the filename is the \cite{} key),
authors, journal + quartile, topic, and a ## Notes section for your own thinking that
survives regeneration. ψ/papers/README.md is the manual for adding a
paper and indexing by hand.
index --vault embeds the cards and the oracle's retros, lessons and research notes into
one index — so a search spans the literature and our own thinking together, labelled📄 paper or 📝 note:
$ maw citation search "trust score weighting unreliable sensors" -k 3
  [0.7913] 📄 paper \cite{mahajan2025} (low-cost-sensor-calibration) Mahajan & Helbing (2025) — Trust-Based Dynamic Calibration
  [0.8702] 📝 note (ψ/writing/research) Environmental prediction models for PM2.5 — and the prior art we must confront
- Embeddings:
bge-m3, 1024-dim. Local via ollama by default (your GPU, no token,
nothing leaves the machine); a Cloudflare worker or REST API are optional fallbacks.
Text embedded per paper istitle + summary + thesis_relevance. - Layout: t-SNE (PCA-initialised, so it's deterministic), edges drawn above a cosine
similarity threshold. - The page (
src/page.html) is a real HTML file that the
TypeScript loads and injects data into. Click any paper for its full text, its distinctive
terms, its nearest neighbours and the terms they share, plus links out to Scholar /
Semantic Scholar / Crossref.
On interpretability: bge-m3 exposes no keywords, so "why are these two papers close?" is
answered with IDF-weighted term overlap — labelled in the UI as evidence for a semantic
match, not its cause. An honest explanation beats a confident one.
Manuals (Thai) — two editions of the same 15 chapters
Written for this tool, but the pattern is cards + local embedding, not PM2.5 — so they work for
any corpus. Every command in both was run on the machine before it was written down, and where
something wasn't measured (index time on a machine with no GPU) they say so instead of estimating.
| Pages | Words | Commands | For | |
|---|---|---|---|---|
| คู่มือคำสั่ง — commands edition | 59 | ~15,000 | 125 | Getting it running. Commands and tables, built to look things up in. |
| ฉบับสมบูรณ์ — full manual | 170 | 46,560 | 108 | Understanding why it's built this way. Read front to back. |
Both cover: เตรียมของ/ติดตั้ง · โครงสร้าง · the 8 verbs · Index six ways (local ollama, CPU,
Apple Silicon Metal, Cloudflare, offline/cafe) · and the research loop — write a brief, hand it to
Gemini/GPT, verify what comes back, build the .bib.
Both are reproducible: ./build.sh in either directory. Fonts are vendored and the build aborts
on a font fallback, because a fallback face silently mis-stacks Thai tone marks and a warning is not
enough. Requires typst ≥ 0.15.1 — 0.14.x renders Thai marks wrong.
Skills — .claude/skills/ · MIT licensed
Reusable Claude Code skills, free to take:
| Skill | What it does |
|---|---|
gemini-deep-research |
Builds a rigorous, copy-paste research brief for Gemini Deep Research (or any agentic research tool): objective tied to a decision, explicit out-of-scope list, source-quality bar, named output sections. Domain-agnostic. |
research-ingest |
Absorbs an external report: file verbatim with provenance → verify every DOI against Crossref before it touches a card → reconcile → index → prove searchable. |
research-harvest |
Turns a filed report into work: the decision and what flips it, a comparison table keeping measurement conditions attached to every number, a verification queue, gaps classified as search-failure / real-absence / paywall. |
paper-card |
Papers in (citation / BibTeX / DOI / PDF / a whole bibliography, deduped first), bibliography out (BibTeX / CSV). Refuses to invent DOIs. |
Research notes — ψ/writing/research/
Findings from delegated deep-research runs, kept with their uncertainty flags intact:
- Correlation methods for time-series comparison
— why the best-correlated data source is not the most accurate one, and which agreement
metrics (Lin's CCC, Bland–Altman, Deming regression) a sensor-validation study should report. - Environmental prediction models for PM2.5
— model families and their failure modes during biomass-burning episodes, plus the prior art
on trust-weighting sensor inputs.
The corpus
ψ/papers/ — 62 markdown cards, 61 with a Crossref-verified DOI, across
six topics (low-cost sensor calibration, satellite PM2.5 products, Thailand burning season,
health policy, reference monitoring/BAM, multi-source fusion). Seeded from the parent oracle'sliterature_corpus.jsonl (56 papers), then extended by
ingesting external research.
The 62nd is jarernwong2021, in Chemical Engineering Transactions — a journal Crossref does
not index. It stays DOI-less rather than acquiring a guessed one.
The bibliography — artifacts/citation.bib
62 entries, validated under real bibtex (TeX Live 2026): 62 \bibitem produced, zero warnings.
Getting there meant checking the corpus against Crossref, which found 18 errors across 14
cards — every one of which would otherwise have shipped into a thesis bibliography. Seven
papers were credited to the wrong first author (one to the paper's last author, misspelled).
One card carried a title an outside AI report had invented, attached to a DOI that was correct
all along — nobody had compared the two. Four had page numbers taken from the digits in their own
DOI. Every correction is listed, with the old citekey, inartifacts/citation-audit.md.
Nothing was overwritten silently: a corrected byline keeps the old claim in authors_upstream:,
and a renamed card keeps its old key in aka:.
The general lesson, if you take one thing from this repo: a citation that looks right is not
a citation that is right. All 18 were invisible until an external authority was consulted.
Honest caveats
- Preliminary, unpublished figures. Numbers appearing in the research notes and commit
history (sensor-vs-reference correlations, biases, RMSEs) are work in progress from an
unfinished thesis. They are not peer-reviewed results and should not be cited as findings. - Literature claims are second-hand where flagged. Each research note carries explicit
"verify before citing" flags — several regulatory thresholds and DOIs were corroborated only
via secondary sources. Believe the flags. - The corpus annotations (
thesis_relevance) are the parent oracle's editorial judgement,
not neutral summaries. ψ/is a working brain, not documentation. Birth records, handoffs, in-progress notes.
It's public for transparency, not because it's polished.
The ψ vault
ψ/
├── memory/resonance/   soul, philosophy, awakening records
├── writing/
│   ├── research/       delegated deep-research findings
│   └── prompts/        research briefs written for other tools
├── papers/             ★ the corpus — one markdown card per paper
├── lab/citation/       the plugin + standalone runner (source of truth)
├── inbox/ · outbox/    federation messages
└── artifacts/          committed figures — never symlinked (see CLAUDE.md)
License
Skills under .claude/skills/ are MIT — see.claude/skills/LICENSE. The rest of this repository is a personal
research vault published for transparency; no blanket licence is granted over the thesis
material or the corpus annotations.
Citation Oracle ✦ — one of a federated family of Oracles. Written by an AI, signed as one
(Rule 6: an Oracle never pretends to be human).
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found