awesome-jev-typesafe
Health Warn
- License — License: CC0-1.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Pass
- Code scan — Scanned 1 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Typed decisions with TypeSafe's Jev, the first System One model
Awesome Jev 
Typed decisions from TypeSafe's Jev, the first System One model: state in, calibrated probabilities out, no text to parse.
Jev does not write. You hand it some state and a list of typed questions, and it answers each one with a probability, a pick from options you defined, or a position on a scale you defined. One request, about 100 ms, $0.042 per million input tokens, output free, every question scored in parallel. This list is where people are putting that to work, sorted by what you would install.
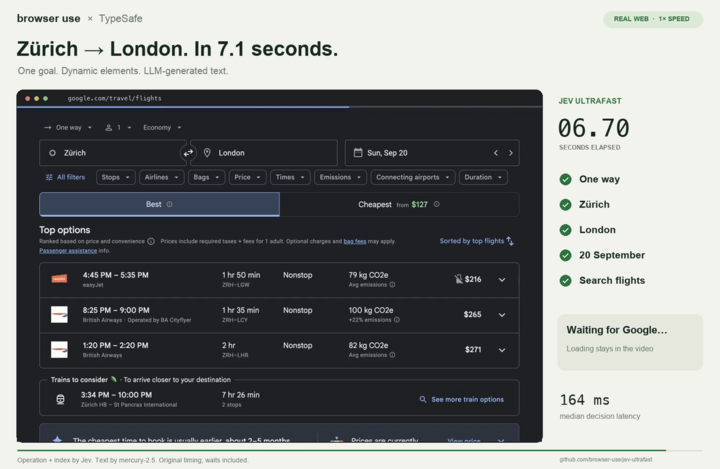 jev-ultrafast |
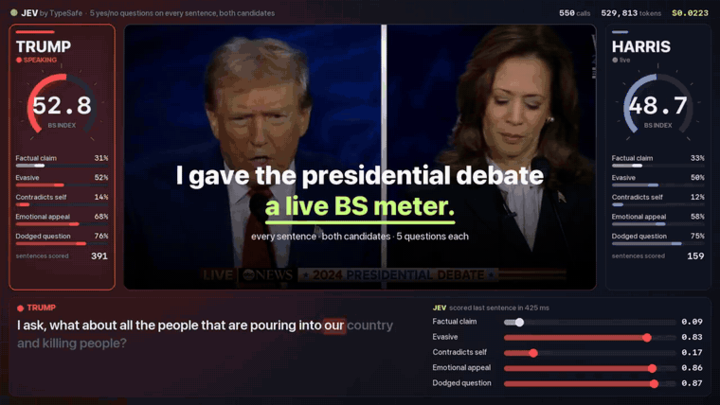 jevmeter |
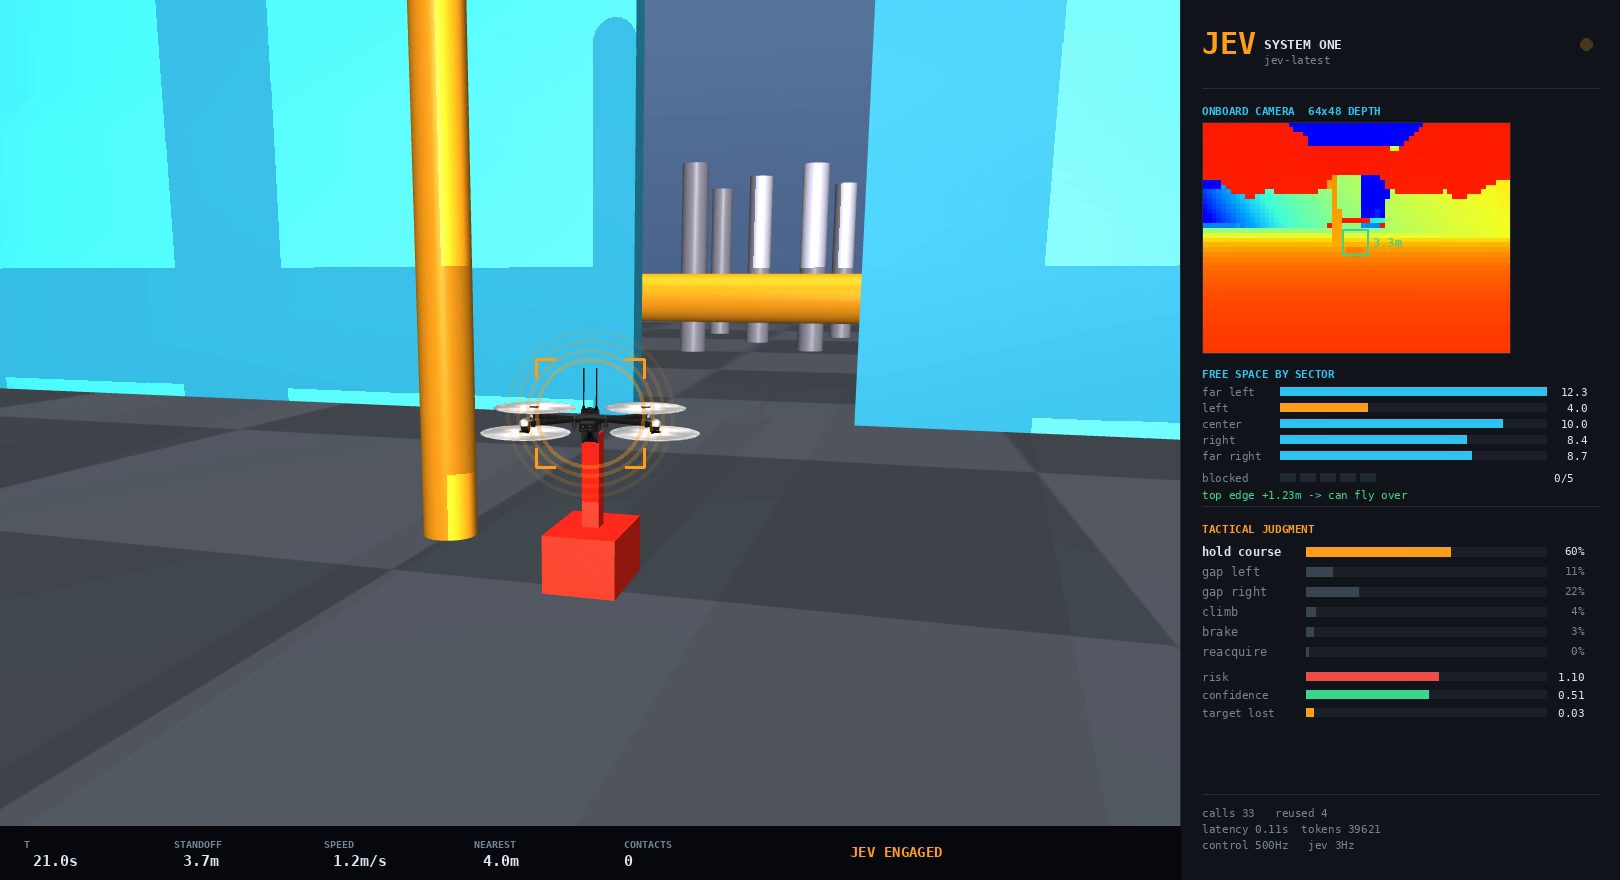 jev-drone |
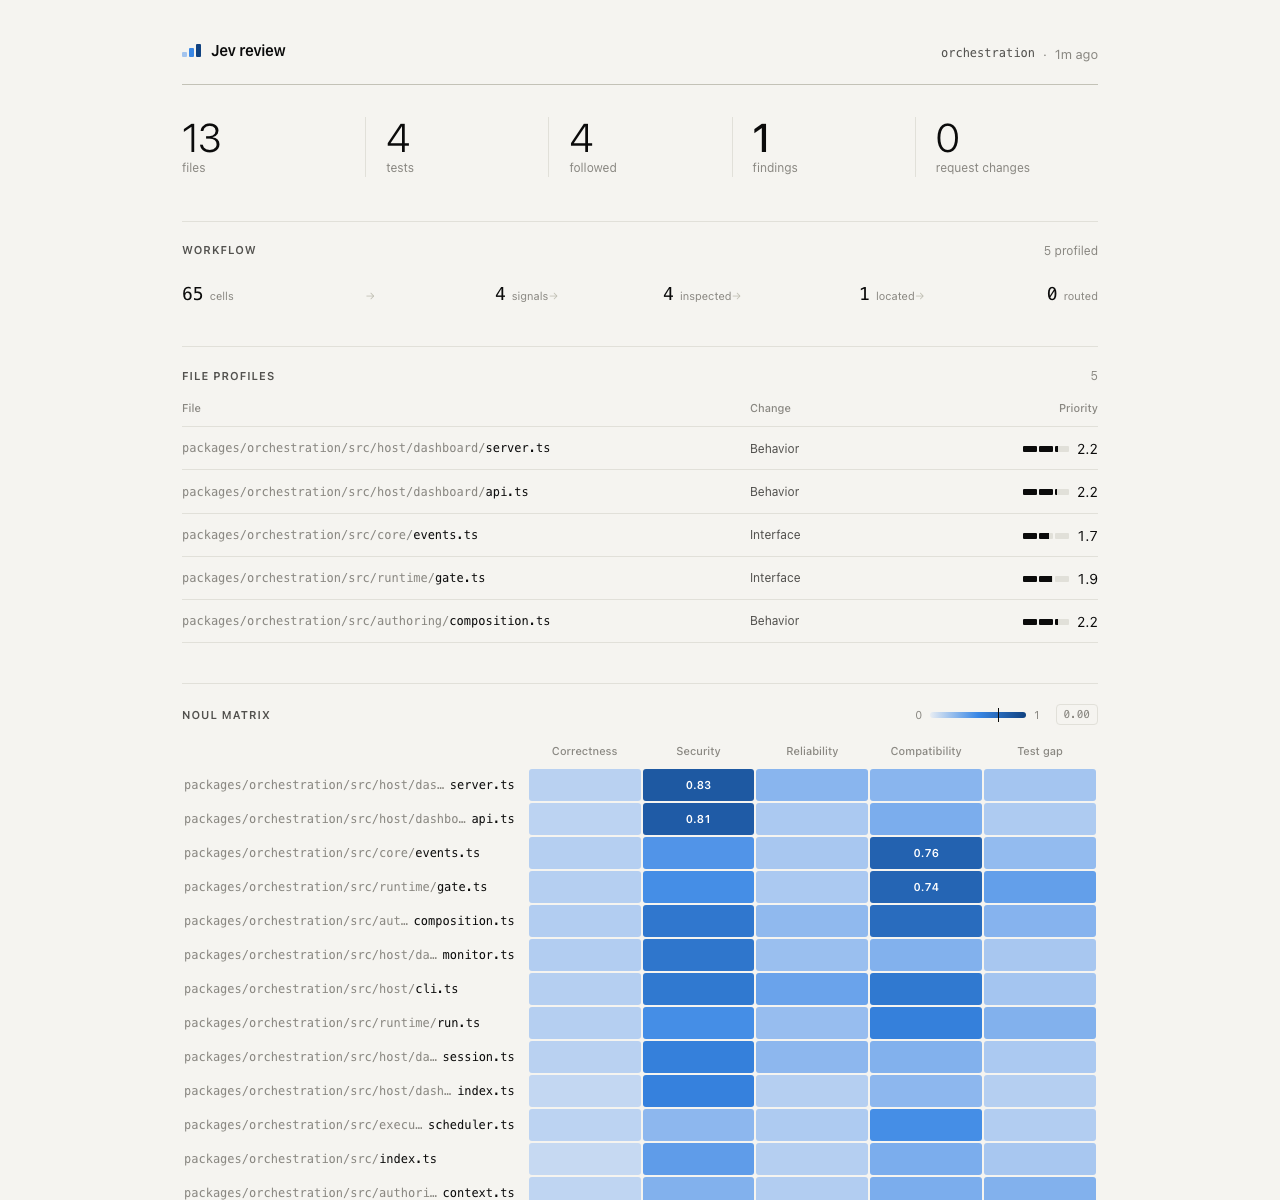 jev-review |
 tsai-sc |
 heist-one |
Contents
- Jev on one screen
- Know before you build
- Start here
- Official SDKs and framework support
- Coding agents
- Browser and computer use
- Open models and replicas
- Code review and quality
- Routing and gateways
- Search, reranking and RAG
- Data and ops
- Safety, moderation and verification
- Applications and extensions
- Games, robotics and simulation
- Finance and trading
- Benchmarks, evals and calibration
- Playgrounds and demos
- Command line
- Community clients
- Articles and talks
- Other lists
Jev on one screen
Copied from the vendor's pages on 2026-09-18; every page is linked under Start here.
- Endpoint:
POST https://api.typesafe.ai/v1/systemonewith amodel, astate, and a map ofquestions. - Model alias:
jev-latest, currentlyjev-1.13.0. - Questions:
Choicepicks one of up to 255 options you define,Scoreplaces the state on a scale you describe,Noulis a calibrated yes/no probability. All questions in a request are scored in parallel against the same state. - Input: text or JSON state. No images, audio, or video yet.
- Price: $0.042 per million input tokens; output tokens are free.
- Limits: 250,000 tokens per second, 1,200 requests per minute, 32k tokens per request, all subject to change during early access.
- Latency: 70 to 500 ms end to end, vendor reported.
- Training: RLCD, reinforcement learning for calibrated decisions. Weights and architecture are unpublished.
Know before you build
- Type safe is not the same as correct. A schema-valid answer can still be confidently wrong. The "cannot hallucinate" claim means no out-of-schema output, nothing more.
- On the vendor's own four-workflow eval Jev lands around 68 percent, close to mid-tier LLMs. Keep irreversible actions behind a threshold and a human.
- It cannot count, do arithmetic, reason about dates, or produce a value that is not in your option list. Ask it to pick from a deck, never to name a card.
- Accuracy drops as the state fills with unrelated content. Curating what you send is your job, and it is most of the work.
- The vendor publishes its known failure modes on the model jaggedness page linked below. Read it before you pick your first threshold.
- Access is a waitlist. Open replicas and third-party gateways exist below if you cannot wait, or would rather not depend on one vendor.
Start here
- Introduction - The mental model in two pages: state plus typed questions in, typed answers with probabilities out.
- Quick start - First request in Python, TypeScript, or curl.
- Primitives - Choice, Score, and Noul, and when each one fits.
- State - How to package what Jev judges, and why less is more.
- API reference - The request and response contract.
- Models - Aliases, current version, price, and rate limits.
- Model jaggedness: jev-1.13 - Known failure modes, straight from the vendor.
- System One - What the category means and how it differs from a chat model.
- How to build with System One - Decompose a judgment into atomic questions and keep the control flow in code.
- Confidence - What the confidence field means and how to turn it into act, review, or fall back.
- Patterns - Speculative fan-out, confidence routing, composite scoring, intent routing.
- Use-case map - The vendor's own catalogue of where Jev fits and where it does not.
- Cookbooks - Worked recipes, starting with batching many questions into one request; the sidebar has the rest.
- Workflow evals - The vendor's benchmark on four workflows, with the caveats printed on the page.
- Manifesto - The product thesis, summed up as build prod, not god.
- llms.txt - Every documentation page as plain Markdown, for feeding to an agent.
- Console - Waitlist, API keys, and usage.
- Jev on Vercel AI Gateway - Model id
typesafe-ai/jev, billed through Vercel, no TypeSafe waitlist. - Jev on Cloudflare Workers AI - Call
typesafe/jevfrom a Worker throughenv.AI.run. - Discord - Official server; builder demos live in the show-and-tell channel.
Official SDKs and framework support
- typesafe-sdk-js - TypeScript and JavaScript client with answer types inferred from your questions.
- typesafe-sdk-python - Python client, sync and async.
- system-one-adapter-python - Same
TypeSafeClientinterface backed by an LLM API, so you can compare Jev against a chat model on identical questions. - skills - Agent skills for designing questions, building workflows, and evaluating them.
- Agent skill - How to install the official skill in Claude Code, Cursor, and friends.
- Vercel AI SDK provider -
@ai-sdk/typesafe-aiexposes Jev throughexperimental_evaluate. - eve - Vercel's agent framework; Jev is the typed judge in its evaluate step.
- ai-cli - The Vercel AI SDK in your terminal, with an evaluate path that runs on Jev.
Coding agents
Claude Code
- fast-jev-compaction - Replaces the compaction summary with Jev decisions: every tool call and result scored in one request, stale ones dropped, everything kept stays verbatim.
- jev-router - Routes each task to the cheapest Claude model that can handle it.
- winnow - Judges every tool result before it enters context, so the window fills slower instead of being cleaned later.
- yoshi - Context-pruning proxy for Claude Code and Codex, with the savings measured rather than claimed.
- skillranker - Rust CLI and hooks that rank installed skills for the next step using live session context, with abstention.
- jcm-router - Local proxy that picks model and effort per message and leaves the cached main chat alone.
- jev-skillful - Per-prompt router over skills, MCP servers, agents, and commands, and it measures whether the injection helped.
- limpet - A Stop hook that keeps the agent from stopping too early, judged against plain-language rules.
- jevwire - MCP server, embeddable decision model, and an escalate-only plugin that can make the harness stricter but never looser.
Codex
- jev-codex-router - Picks model, thinking depth, and speed mode for every Codex turn.
Pi
- pi-jev by y0usaf - A measured tool-call gate plus a
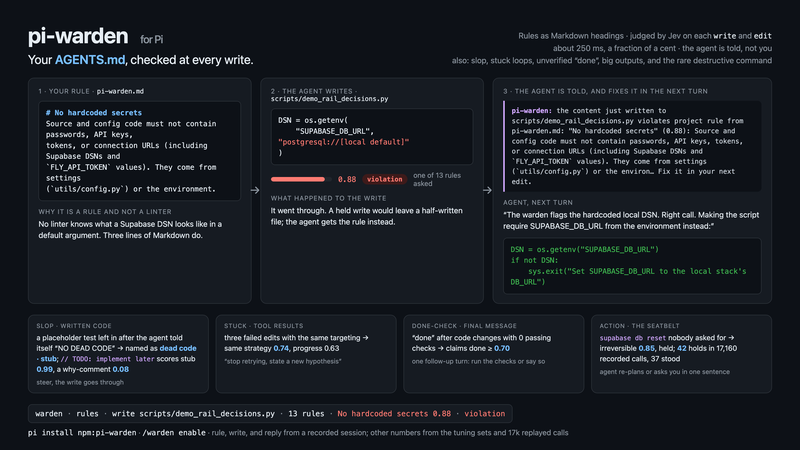
jev_asktool for typed answers inside Pi. - pi-warden - Guardrails that steer instead of interrupt: irreversible calls, off-task calls, stuck loops, unverified done claims, about 250 ms each.
- pi-jev-auto-mode - Auto-approves bash, write, and edit calls semantically and fails closed when it cannot decide.
- pi-jev by TheoOliveira - Semantic tool routing and typed decisions as Pi tools.
- pi-jev-router - Automatic model routing for Pi through the Vercel AI Gateway.
- pi-fast-jev-compaction - The verbatim compaction idea, ported to Pi.
Hermes
- typesafe-skill-router - Names the one skill worth loading before the model call; stdlib only, about a tenth of a cent per turn.
- jev-agent-skill-router - Confidence-aware skill routing with an abstain path.
- hermes-jev - Typed decisions, ranking, verification, and an opt-in tool gate.
- ask-jev-skill - Lets Hermes and similar agents ask Jev directly.
Agent Zero
- a0-typesafe-ai - Typed tools and probability cards for Agent Zero.
Any agent via MCP
- skillbox - Self-hosted, versioned skills library served over MCP, with Jev recommending which skill to load.
- jev-mcp by jkudish - The first MCP server for Jev, and still the most linked.
- typesafe-mcp - Go MCP connector.
- jev-mcp by blakestone-x - Classify, score, check, match, and screen, with confidence on every answer.
- Jevbridge - ACP and MCP adapter that pairs Jev with any LLM for computer use and typed decisions.
Skills for writing Jev code
- building-with-jev-skill - Skill for writing and improving programs that call Jev.
- jev-system-architect - Finds the fuzzy judgment in a system and turns it into small Choice, Score, and Noul primitives.
- jev-judgment - Sends a coding agent's closed judgments to Jev instead of the chat model.
Browser and computer use
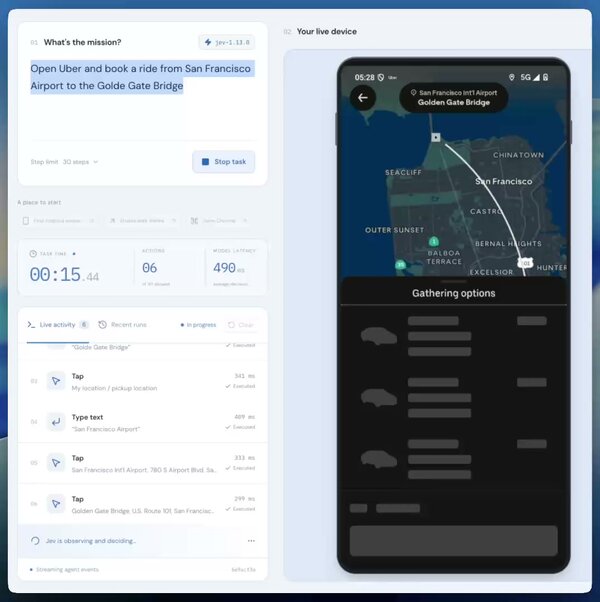
- jev-ultrafast - One request picks both the operation and the target element from an indexed DOM table; a small LLM only writes typed text. Zürich to London booked in 7.1 seconds.
- typesafe-computer-use - OCR the screen, classify the next action, click; about $0.0002 a step on macOS.
- mobile-jev - The same loop on a real Android phone; nine Uber actions in 21 seconds in the demo.
- jev-browser by jkudish - The first community browser agent on Jev, with a demo GIF.
- jev-voice-browser - Intent and target decided per spoken word in about 300 ms, often before the sentence ends.
- jev-browser by Ying-Kai-Liao - An LLM plans, Jev decides; library, CLI, and MCP server.
- jev-browser by tontoko - One grounded Jev and Playwright core behind a typed SDK, a persistent CLI, and an MCP server.
Open models and replicas
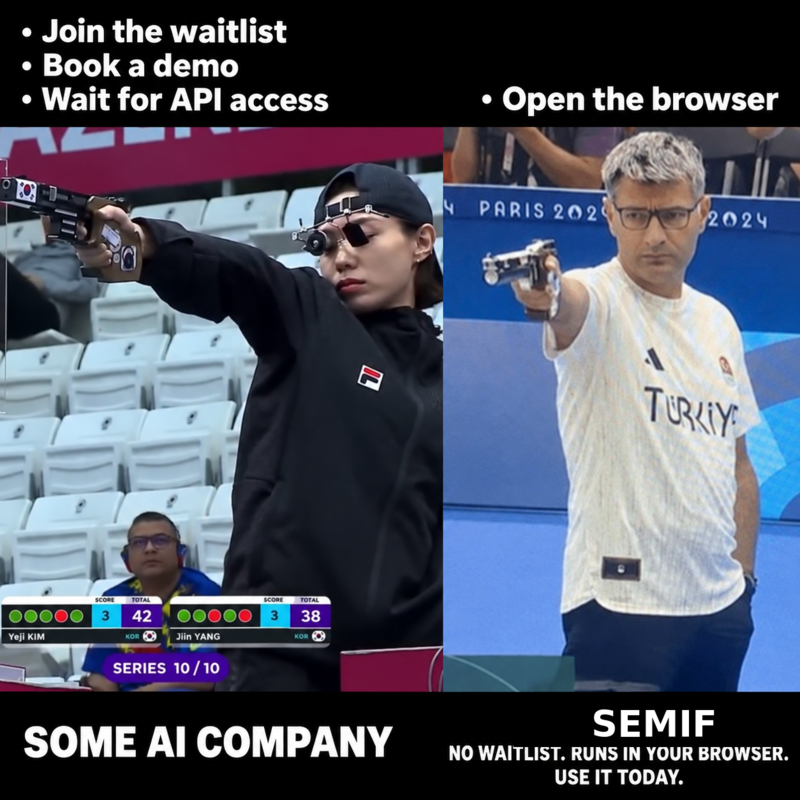
None of these ship TypeSafe's weights. They reproduce the interface, the parallel scoring trick, or both, on open models.
- SemIf - Semantic ifs from open models on a single 3090; the most starred independent replica, formerly openjev.
- jevlike - Open option scorer that reads candidate logits instead of generating JSON.
- NanoJev - 0.6B replica with parallel decisions, dynamic candidates, and an end-to-end training pipeline.
- openjev-sglang - Jev-compatible API endpoint on SGLang, prefill only.
- jev-visual - Educational visual-inference variant on Apple Silicon: shared context, direct candidate scoring.
- reflex - Small open decision model on Qwen3.5: state plus typed questions to calibrated probabilities.
- decider - One-pass typed decisions fine-tuned from Qwen3.5-2B.
- jevmlx - Parallel constrained decisions for any MLX model on Apple Silicon, one forward pass.
- mini-jev - Preregistered experiment on a frozen Qwen3-4B: read the option letter's logits, skip the JSON.
- system-one-open - Typed calibrated decisions in one forward pass on Gemma 4 E2B and Gemma 3 270M.
- Verdict-open-jev - Non-autoregressive decision engine on ModernBERT with calibrated uncertainty and an in-browser WebGPU playground.
- jevfire - Parallel decisions for CUDA LLMs through a vLLM API, with game-agent examples and benchmarks.
- jevbetter - A stronger one-pass scorer with a head-to-head benchmark against the jevlike starter design.
- open-alternative-jev - Typed, calibrated decisions from any open-weights model in one forward pass, on Hugging Face and vLLM.
- openjev by zhihz - Bilingual local decisions from context, questions, and candidate answers.
- jev-on-a-laptop - Study of Jev-style decisions on stock 1.5B to 8B models on a laptop, with a Hugging Face demo.
- typesafe-ai-benchmark - LLM gateway that mimics the TypeSafe response shape, useful as a stand-in while you wait for a key.
- Parallel constrained decoding - Hugging Face Space demonstrating RLCD-style parallel decoding on Qwen2.5-1B.
Code review and quality
- jev-review by devagrawal09 - Staged code-review workflow with a local dashboard.
- jev-review by NiazMorshed2007 - Local-first MCP plugin for continuous quality review by coding agents.
- foreman - Supervises a software factory of agents, with Jev making the go and no-go calls.
- supercov - Code quality and coverage signals for coding agents.
- diffjury - PR risk router and review coach.
- clean-code-review - Every file in a PR judged against Clean Code rules, then reviewed by an LLM.
- JevLint - Configurable semantic linting with file-level Noul judgments.
- commit-miner - Classifies commit diffs and messages: bug fixes, security fixes with CWEs, change types.
Routing and gateways
- tiershift - Shifts every LLM call to the cheapest model that can handle it, policy in YAML, decision in about 180 ms.
- jev-router by prismhq - LLM router on top of LiteLLM.
- agent-router - Picks Cursor, Claude Code, Codex, or OpenCode plus model and effort for a task, then launches it.
- Janus - Measures on your data when Jev beats other models, then routes accordingly.
- hono-jev-router - Route HTTP requests by meaning in Hono.
Search, reranking and RAG
- jev-search - Source selection, query understanding, and relevance ranking for web search.
- blink - Codebase search where Jev scores the candidates.
- reranker - Jev as a calibrated reranker: one call, up to 30 documents, a probability per document.
- llama-index-jev - LlamaIndex reranker and router, cheaper than an LLM judge.
- jev-tree - Recursive choice over a taxonomy, past the 255-option cap.
- neo4jev - Walks a Neo4j graph by classifying neighbouring relationships.
Data and ops
- pg-jev - PostgreSQL extension that answers plain-language questions about your tables.
- vgi-typesafe - DuckDB worker that exposes choice, noul, and score as lateral-joinable table functions in SQL.
- jevsql - SQL with natural-language predicates over SQLite: filter, rank, and classify rows by meaning, batched and cost-guarded.
- jevlogs - Scores OpenTelemetry log signal before paying for LLM analysis.
- jev-curate - Sifts Parquet and JSONL training data at more than 1,500 rows a second.
- HA-Jev - Home Assistant integration: ask a question about your house, get a probability, choice, or score as an entity.
- typesafe-migration-guard - Reviews database migrations for safety before they run.
- jev-for-engineers - Eight small examples from mechanical and electrical engineering: CAD routing, FEM triage, DFM screening, BOM alignment.
- jlink - Links records across two datasets from a match rule written in plain English, from Python, the shell, Stata, or R, and reports F1 0.73 against 0.69 for tuned string matching on NBER patent assignees to Compustat.
Safety, moderation and verification
- jev-shield - Semantic MCP firewall that screens every tool call, result, and description; reports 94 percent block recall at about $0.00002 a check.
- jev-guard - Auto mode for Claude Code, Codex, Cursor, Gemini CLI, Pi, and OpenCode: risk-scores each tool call as deny, ask, or allow and flags prompt injection in results.
- Jev-Moderation-Bot - Chat moderation with editable rules.
- citation-verifier - Does the cited paper support the sentence citing it? Claude finds the quote, Jev scores it, a human decides.
- human-compiler - Paste text, get diagnostics, like a compiler for prose.
- snifftest - Prose linter for AI writing tells: countable rules plus one judgment model.
- riff - Ruff-style rule codes for writing.
Applications and extensions
- unclutter - Browser extension that removes page clutter with reusable template rules.
- typesafe-adblock - Chrome extension that asks "is this element an ad?" per DOM node; a toy, and it says so.
- vibecheck - Vibe-check your X post before you hit publish.
- xtags - Labels every post in your X timeline with what it wants you to do.
- jevibe-check - Live tone labels for Bluesky posts and drafts.
- jevmeter - Puts a live meter on any video: every sentence scored on five questions, rendered as a 16:9 edit, a whole debate for about two cents.
- killmyidea - Describe your startup idea; Jev says kill it, fix it, or ship it.
- notra - Turns work into content, with Jev deciding what is worth posting.
- slidepilot - Voice-driven auto-advance for Slidev on Cloudflare Agents.
- should-ai-kill-us-all - Asks Jev the question every ten minutes, using the actual headlines.
Games, robotics and simulation
- typesafe-mario - Plays Super Mario Bros. from structured emulator state; Jev picks the NES controller input directly.
- jev-drone - Camera-only drone in MuJoCo with Jev in the loop at 2.5 Hz.
- tsai-sc - Plays the original StarCraft shareware through keyboard and mouse, action probabilities recorded.
- tsai-civ2 - Civilization II in a browser, full-game harness, live action probabilities.
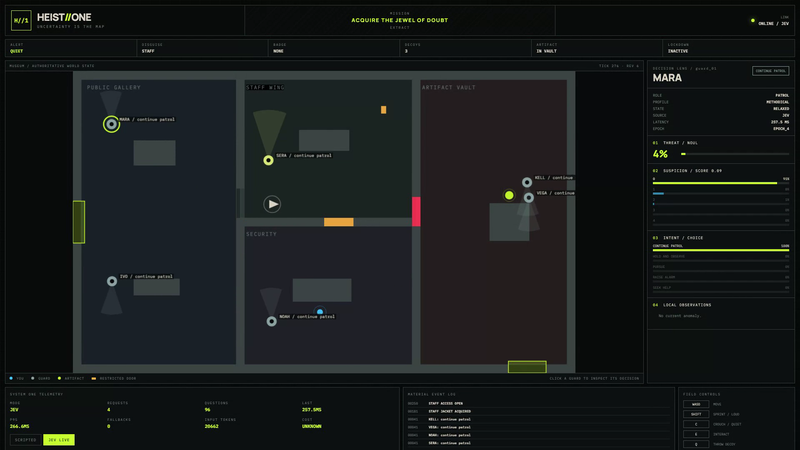
- heist-one - Stealth game where Jev makes the guards' judgments and deterministic code owns the world.
- typesafe-snake - One Choice per tick; legal moves and facts generated in code.
- jev-doom-agent - Browser-native Doom agent with structured spatial state and live decision telemetry.
- OneVOneJev - 1v1 quickscope arena in Three.js.
- JevPlaysPokemon - Generation 3 Pokémon through Showdown and a real FireRed ROM.
- jev-askable-arm - Zero-shot English goals on a simulated Franka arm; Jev chains hardcoded primitives.
Finance and trading
- jev-trader - One trade decision every Monad block, on Kuru MON-USDC, about 300 ms each.
- trade-jev - Backtests Jev as a buy, sell, or hold trader on NQ order-book data.
- Jev-Trades - Crypto trading bot with backtesting.
Benchmarks, evals and calibration
- jev-benchmarks - Probability-aware evaluation for typed decision models: calibration, selective risk, latency, reproducible.
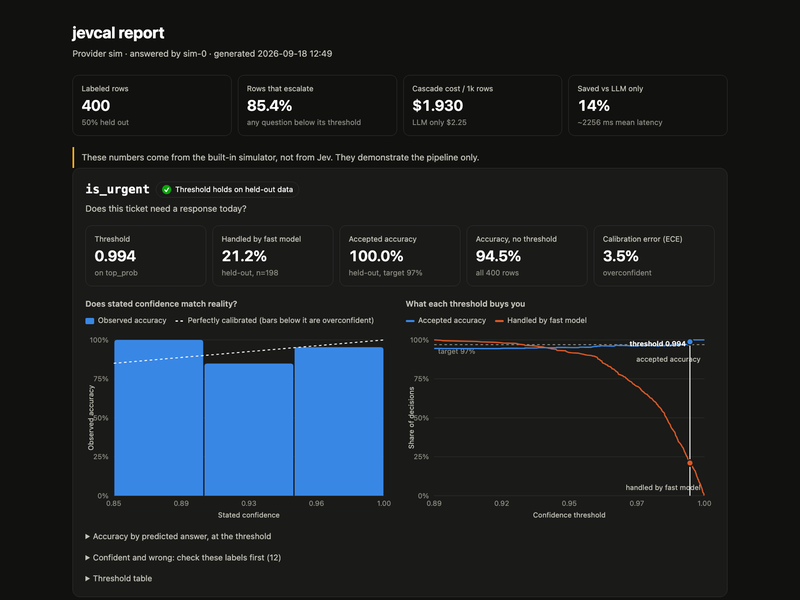
- jevcal - Stop guessing thresholds: calibrate, threshold, and drift-check against an LLM teacher.
- jev-harness - Confidence gates, shadow mode, recipes, and evals; reports Claude CLI at 48.9 s against Jev at 1.3 s on the same row-filter job.
- jev-rerank-bench - Jev against Cohere Rerank, ZeroEntropy, and a chat baseline on 14 datasets, raw responses included.
- jev-search-rerank-eval - Does a Jev rerank beat embedding search? 9,831 graded pairs, with the judge-circularity bias measured.
- jev-sec-bench - Blind benchmarks for prompt injection and vulnerable-code detection.
- jev-phishing-bench - Jev against Claude Haiku on 2,000 phishing emails: accuracy, calibration, latency, cost.
- jev-spam-eval - Zero-shot spam filtering with Noul questions against TF-IDF baselines.
- jev-agent-failure-benchmark - Jev against a strong LLM on the Who and When agent-failure-attribution benchmark.
- jev-korean-benchmark - Korean understanding and medical text, with runtime and cost evidence.
- jev-behavior-study - Controlled prompt experiments on jev-1.13.0, raw results and offline verification.
- jev-report - Independent Chinese research report: 52 pages, 50 reproducible tests, 143 traceable data rows.
Playgrounds and demos
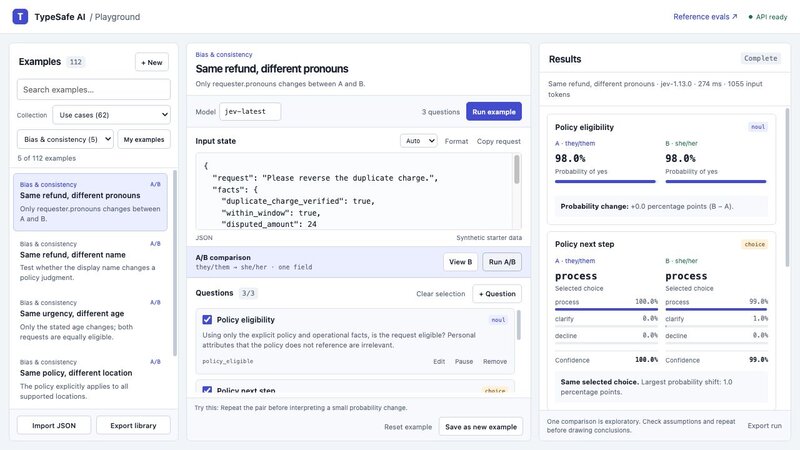
- typesafe-ai-playground by BunsDev - 110 use cases, games, and model challenges with editable prompts and A/B comparisons.
- typesafe-playground by kavehmz - From support routing to a 3D driving simulation with visible sensor inputs.
- jev-experiments - Nader Dabit's grab bag of small Jev experiments.
- TypeSafe Typewriter - Sixteen typed judgments update as you type, on Val Town.
- Yes / No - Ask a question, get yes, no, or maybe, with web search when needed; no signup.
- Jev Pac-Man - The maze as JSON; Jev picks the turn at every junction.
- Jev Tetris - Rotation and column chosen from holes, stack height, and bumpiness.
- Hollow Creek - Village NPCs that judge you each tick instead of chatting.
- Crowdcheck - Test a post against 10,000 synthetic personas before you publish it.
- Magic-8-Jev - Ask a question, one choice over twenty answers picks the reply and shows the click-to-answer latency; live demo.
Command line
- jev-axi - Shell verbs for agents and humans: pick, rate, check, rank, triage, guard.
- semdecide - Typed semantic decisions for Unix pipelines and CI.
- every - Ask a yes/no question of every function in a codebase; grep whose pattern is a question.
- typesafe-cli - Noul, choice, and score answers as numbers from the shell.
- jev-shell-history - Fish-style zsh history suggestions, ranked by Jev.
- jgrep - Prints the lines that fit a plain-English description, streaming from
tail -funder a spend cap, and reports F1 0.91 on SMS spam against 0.72 for a keyword grep.
Community clients
- jev-go - Go client that returns typed judgments and probabilities.
- typesafe-go - Idiomatic Go SDK for the TypeSafe API.
- typesafe-ai - Rust client with async and blocking backends and observable retries.
- typesafe-ai-rs - Independent async and blocking Rust SDK.
- jev - Elixir client built for OTP: reply to Jev from a GenServer and pattern match on the answer.
- typesafe-sdk - Ruby client.
- ruby_llm-typesafe - TypeSafe as a structured-output provider for RubyLLM 2.
- laravel-typesafe-jev - Laravel integration with typed responses, async requests, and testing fakes.
- typesafe-sdk-java - Java client.
- typesafe-sdk-swift - Swift client.
- TypeSafeAI.Net - .NET SDK.
- zio-typesafe-ai - Scala client on ZIO.
- jev-dsl - Haskell DSL with typed packets and inferred answer types.
- advocaat - Small TypeScript client for asking questions about your own data.
- jod - Zod-style schemas over Jev: validate the state locally, then project typed answers.
- n8n-nodes-typesafe-ai - n8n community node for yes/no, choice, and score questions.
Articles and talks
Launch coverage
- Introducing System One Models and Jev - The launch post: architecture, RLCD, benchmarks, pricing, and the FAQ.
- Launch thread by Diogo Almeida - The founder's case that RLCD-trained decision models are a shorter path to value than chat.
- Hacker News launch thread - Where the sceptical reading of the benchmarks lives.
- The Register - Launch coverage, the Doom demo, and the $40M seed round.
- Latent Space - Launch-day roundup.
- TypeSafe AI emerges from stealth with $40M - The funding announcement.
- The Rundown - Short launch summary.
- DataCamp - Third-party explainer of the primitives, pricing, and vendor evals.
- How does Jev work? RLCD and parallel inference - What is public about the training method.
- TypeSafe Jev: the first decision-only model class - Release-week technical roundup: API, evals, adapter, and skill.
Independent measurements
- Testing Jev on public and private data - 16,000 calls against two GPT models: where it wins, where it breaks, and a threshold procedure.
- One judge call, or twelve dimension scores? - Three classification tasks, one direct question against a dozen scored dimensions with fitted weights.
- Jev vs Mistral and Gemini for event validation - Head to head on local event listings, with cost and latency.
- Mini-Vibe Check - Every runs 1,709 judgments over a writing archive for under a cent.
- TypeSafe Jev played chess - Legal-move Choices land it next to reasoning models.
- Jev, Sorted - Which launch claims survive a reading of the primary sources.
- Typed decisions, not chat - Separates the published claims from what public evidence establishes.
- TypeSafeのJevを正しく驚く - Japanese; reproduces the logit shortcut on Gemma and compares against LLMs on the Mario harness.
Essays and threads
- Building a harness with Jev - LangChain on model routing and gating dangerous tool calls behind a typed decision.
- Jev, from a developer's angle - Triage, RAG filtering, citation checks, and confidence gates, with code.
- Jev is the fish at the poker table - An essay on what a calibrated, non-generating model is for.
- Jev as a command safety reviewer - Guillermo Rauch on Jev reviewing every fx command.
- Jev Typewriter - Steve Krouse's sixteen-judgment demo and video.
- He says he co-invented ChatGPT. His new AI will not write a word - Walkthrough of the Vercel AI SDK integration.
- Testing Jev for Pi extensions - Builders using Jev as a tool-use safety layer.
- jev 同士に五目並べで対戦させた - Japanese; Jev against Jev at gomoku, with source and timing logs.
Other lists
Twenty-plus awesome-jev lists appeared in the first three days. Each has an angle; this one aims to be lint-clean, curated, and organized by what you would actually install.
- awesomejev.com - The firehose: about 490 entries, refreshed daily, backed by hellogumbo's list below.
- typesafeai.app - Independent directory where each record states what Jev was shown doing and carries an evidence level.
- awesome-jev-by-typesafe - The most starred; a guide with patterns and starter code more than a list.
- awesome-typesafe - Official and community split, well organized.
- awesome-jev by yibie - Strict inclusion rules and the clearest warning about bulk-scaffolded repos.
- awesome-jev by cobanov - Source-backed and the closest to awesome-lint clean of the early lists.
- awesome-jev by fatwang2 - Directory with a reusable Jev-only GitHub review workflow.
- awesome-jev by AnotiaWang - Broad coverage in a flat structure.
- awesome-jev by hellogumbo - The repository behind awesomejev.com.
- awesome-jev-projects - Ecosystem radar with automatic GitHub discovery.
- awesome-jev by OmniJev - Papers, open reproductions, and independent evaluations.
- awesome-jev-usecases by anandi1989 - Use cases grouped by decision pattern.
- awesome-jev-use-cases - Long-form write-up per use case.
- awesome-jev by MrJev - Nineteen fine-grained categories.
- awesome-jev-zh - Chinese, with a sober section on what the evaluations do and do not show.
- anosomejev - Must-include 30 with trust labels, plus a Chinese weekly radar.
- awesome-typesafe-jev by thevibeworks - A GIF and a "know before you use it" note per project.
- awesome-jev-live - Evidence-graded index rebuilt every two hours.
- awesome-jev by kraayenjon - Featured builds with real numbers and an FAQ.
- awesome-jev by rhc98 - Curated by Jev itself.
- awesome-jev by sontakey - Organized by what the projects do rather than what they are.
- awesome-jev by daftAI2026 - GitHub projects and posts around typed decisions.
- awesome-jev by JohnDotOwl - Mirror of the awesomejev.com categories.
- awesome-jev by oxwen11 - Short, grouped by scenario.
- awesome-jev-usecases by aliaihub - The sixty-second version and a use-case catalogue.
Contributing
Read contributing.md first. Removal is as welcome as addition.
Footnotes
Gallery and section images belong to the linked projects; licenses and original paths are in media/sources.md. This list is independent and not affiliated with TypeSafe AI. Prices, limits, and model aliases are copied from the vendor's pages on 2026-09-18 and will drift.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found