memory-agent
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 6 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Multi-agent AI/CS learning assistant: LangGraph routing, LightRAG graph RAG, three-layer memory, learning roadmaps. FastAPI + React.
memory-agent
English | 简体中文




A multi-agent knowledge assistant for learning AI / Computer Science, built on LangGraph + LightRAG + FastAPI + React.
Most "RAG demos" stop at retrieve-then-answer. This one goes further: it routes each question to a specialised agent, remembers you across sessions, plans a learning roadmap for a topic, and diagnoses how far you actually got. It also degrades instead of crashing — if the graph database or the embedding API goes down, it falls back to plain LLM or keyword retrieval and tells you so.
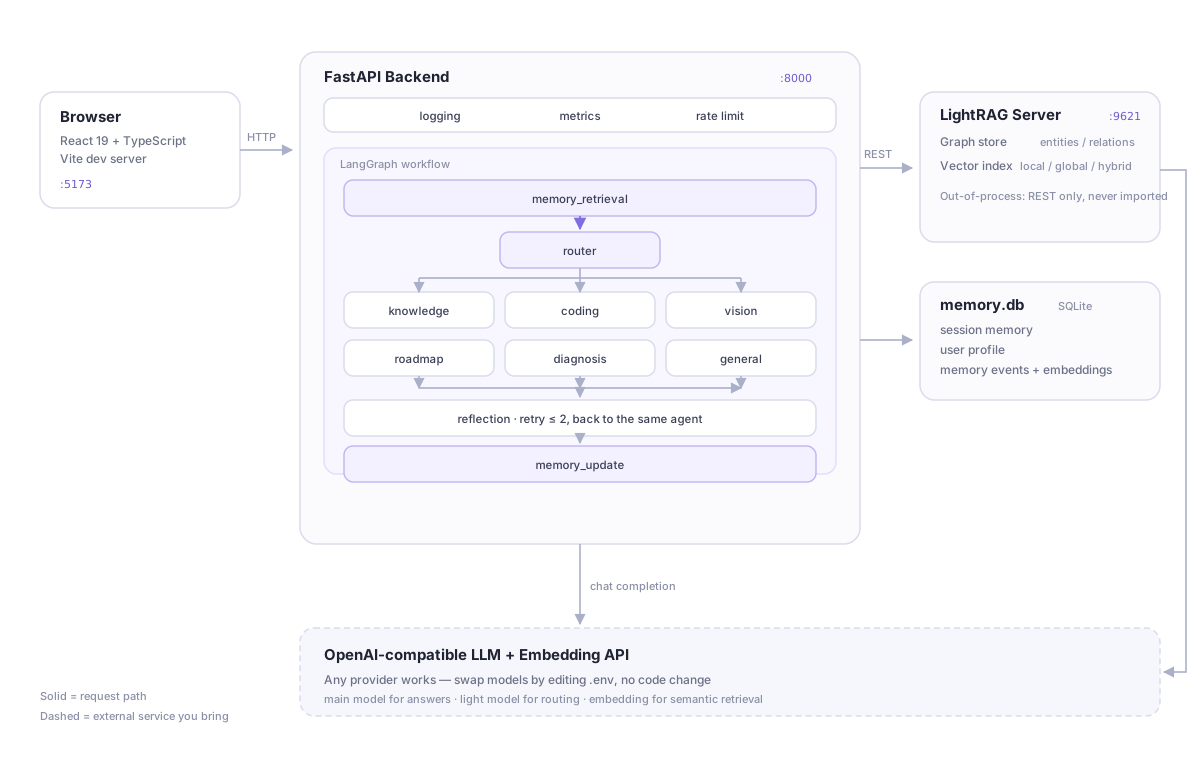
Table of contents
- What it does
- Quickstart
- Configuration
- How a request flows
- Memory system
- Learning roadmap & diagnosis
- API reference
- Project layout
- Tests & evaluation
- Known limitations
- Contributing
- License
What it does
| Capability | Detail |
|---|---|
| Multi-agent routing | A light model classifies every question into knowledge / coding / vision / roadmap / diagnosis / general, with keyword fallbacks so intent-critical requests are never misrouted |
| Graph RAG | LightRAG builds an entity/relation graph; queries run in local / global / hybrid mode |
| Learning roadmap | Extracts the topic, retrieves from the knowledge base, generates a 5–10 step plan, persists it, and tracks per-step progress |
| Learning diagnosis | Combines roadmap progress + user profile + recent memory events into a report of strengths, weak spots and next steps |
| Three-layer memory | SQLite-backed session memory, long-term user profile, and an event log with feedback and expiry |
| Semantic de-duplication | The same preference phrased differently is not stored twice; if you change your mind, the old record is superseded instead of piling up |
| Self-reflection | Answers shorter than 20 chars or containing "No relevant context" trigger a retry — back to the same agent, max 2 times |
| Tool use | Sandboxed python_repl and Firecrawl web search, surfaced in the UI |
| Observability | Request/latency metrics, structured logging, rate limiting, and a 30-question end-to-end evaluation suite |
Quickstart
Prerequisites — Python 3.11+, Node 18+, and access to any OpenAI-compatible LLM and Embedding API (StepFun, OpenAI, SiliconFlow, vLLM, Ollama…).
1. Install
git clone https://github.com/007350/memory-agent.git
cd memory-agent

python -m venv .venv
source .venv/bin/activate         # Windows: .venv\Scripts\activate

pip install -r backend/requirements.txt
pip install "lightrag-hku[api]==1.5.6"   # the LightRAG server, separate process
cd frontend && npm install && cd ..
2. Configure
cp backend/.env.example backend/.env
cp lightrag/.env.example lightrag/.env
# edit both files — fill in your LLM and embedding keys
Only these five values are actually required:
LLM_BASE_URL=...        LLM_API_KEY=...     LLM_MODEL_MAIN=...
EMBEDDING_BASE_URL=...  EMBEDDING_API_KEY=...  EMBEDDING_MODEL=...
backend/.envdrives the assistant;lightrag/.envdrives graph indexing. They may use different models — but the embedding model inlightrag/.envis permanent once you have indexed documents.
3. Run
# Windows
start.bat

# macOS / Linux
chmod +x start.sh && ./start.sh
Both scripts auto-detect your interpreter (MEMORYAGENT_PYTHON → .venv → PATH) and launch the three services. Then open http://localhost:5173.
Or start them by hand:
cd lightrag && lightrag-server                     # :9621
cd backend  && uvicorn app.main:app --port 8000     # :8000
cd frontend && npm run dev                         # :5173
Or use Docker:
docker compose up
4. Load some documents
Paste text in the Knowledge tab, or upload the five bundled sample documents:
python upload_docs.py
Indexing is asynchronous — a large document can take 1–5 minutes. Watch progress at http://localhost:9621.
Configuration
Everything lives in two .env files; nothing is hardcoded. Full annotated versions are in backend/.env.example and lightrag/.env.example. The knobs worth knowing:
| Key | Default | Effect |
|---|---|---|
LLM_MODEL_MAIN / LLM_MODEL_LIGHT |
step-3.7-flash / step-3.5-flash | Answers vs. routing — using a cheap model for routing cuts cost and latency |
MEMORY_SEMANTIC_TOP_K |
20 | Max memory events retrieved per turn |
MEMORY_DECAY_HALF_LIFE_DAYS |
14 | How fast old memories lose weight |
MEMORY_CONTEXT_BUDGET_CHARS |
3000 | Hard cap on memory text injected into the prompt |
PYTHON_REPL_TIMEOUT |
5 | Seconds before python_repl is killed |
Swapping LLM providers means editing three lines. No code changes.
How a request flows
query
  └─ memory_retrieval   load session memory + score memory events
       └─ router        pick an agent (light model + keyword fallback)
            ├─ knowledge   LightRAG hybrid retrieval → LLM
            ├─ coding      code writing / debugging
            ├─ vision      image understanding
            ├─ roadmap     topic → retrieval → 5-10 step plan → SQLite
            ├─ diagnosis   progress + profile + events → report
            └─ general     chat / real-time questions (+ web search)
                 └─ reflection   quality gate, retry ≤ 2 on the same agent
                      └─ memory_update   persist facts & preferences
The router does not trust model names emitted by the LLM — it always resolves them through services/model_registry.py, so a hallucinated model string cannot break a request.
Memory system
Three independent layers, all SQLite (aiosqlite), no external memory service:
| Layer | Scope | Purpose |
|---|---|---|
| Session memory | per session_id |
key facts and preferences from this conversation |
| User profile | per user_id |
long-term traits that survive sessions |
| Memory events | per user_id |
append-only log, with feedback and expiry markers |
Retrieval is a weighted blend rather than plain cosine similarity:
score = 0.55 · cosine_similarity
      + 0.25 · keyword_coverage   (character-bigram based, so Chinese works)
      + 0.10 · importance
      + 0.10 · time_decay          (0.5 ^ (age_days / half_life))
If the embedding API is unavailable, the weights are redistributed across the remaining terms and retrieval silently degrades to keywords. A dead embedding endpoint makes memory dumber, not broken.
Learning roadmap & diagnosis
Roadmap — say "plan a learning path for LangGraph":
- The light model extracts the topic;
- The topic drives a hybrid LightRAG query (falls back to a placeholder context if the server is down);
- The main model must return JSON with 5–10 steps — each step is validated, malformed ones dropped, ids renumbered;
- The plan is written to the
learning_roadmapstable and rendered as Markdown.
The UI lets you tick off steps, delete a plan, or re-plan; RoadmapStats draws completion with hand-written SVG (no chart library).
Diagnosis — ask "how am I doing?": roadmap progress + user profile + the 50 most recent memory events go into one prompt, and out comes a report with overall progress, strengths, weak spots, and what to do next.
API reference
Interactive docs at http://localhost:8000/docs.
| Group | Endpoints |
|---|---|
| Chat | POST /chat |
| Documents | POST /documents, POST /documents/upload, GET /documents/{track_id}/status |
| Roadmaps | GET /roadmaps, GET /roadmaps/{id}, PATCH /roadmaps/{id}/steps/{step_id}, DELETE /roadmaps/{id} |
| Memory | GET /memory/{session_id}, DELETE /memory, profile CRUD + /summary + /rollback, events + /feedback |
| Ops | GET /health, GET /metrics |
curl -X POST http://localhost:8000/chat \
  -H "Content-Type: application/json" \
  -d '{"query":"What is LangGraph?","session_id":"s1","user_id":"u1"}'
{
  "answer": "LangGraph is a framework for building stateful multi-actor applications...",
  "agent": "knowledge",
  "sources": [{"id": "chunk-001", "file_path": "langgraph_overview", "content": "..."}],
  "retrieval_mode": "hybrid",
  "reflection_passed": true,
  "reflection_count": 0,
  "used_memories": [],
  "latency": 5.3,
  "session_id": "s1"
}
Project layout
backend/app/
  main.py              FastAPI wiring: middleware, routers, lifespan
  config.py            pydantic-settings, reads env only
  graph/               LangGraph state / nodes / workflow
  agents/              router + 6 specialised agents
  services/            lightrag_client, memory_service, embedding_service, model_registry
  tools/               python_repl, web_search
  routes/              chat, documents, memory, roadmap, health, metrics
  middleware/          logging, metrics, rate_limit
frontend/src/          React 19 + TS: ChatPage, KnowledgePage, RoadmapPage
lightrag/              LightRAG server config + local index (git-ignored)
docs/                  architecture diagram
Tests & evaluation
cd backend
python -m pytest tests/ --ignore=tests/evaluation -q   # 112 passed, 3 skipped — no network needed
python -m pytest tests/ -m integration                 # requires LightRAG on :9621
python tests/evaluation/eval_rag.py                    # 30-question end-to-end eval
Tests never touch the network: LLM and HTTP calls are mocked, embeddings are switched off, and every database test gets its own tmp_path so runs cannot pollute each other.
Latest end-to-end run — 30 questions over 7 documents (LangGraph, LightRAG, RAG survey, Python async, Transformers…):
| Category | Score |
|---|---|
| Simple QA | 10/10 |
| Cross-document | 10/10 |
| Multi-hop | 5/5 |
| Unanswerable (should refuse) | 5/5 |
| Total | 30/30 |
Retrieval hit rate 96% (29/30), average latency 27.4 s — hybrid graph retrieval plus reflection costs several LLM round-trips, so a 10–30 s first response is expected.
Known limitations
- Single-user assumption — there is no auth layer;
user_idcomes from the client. python_replruns code in a subprocess with a timeout, not a real sandbox. Do not expose it publicly.- Latency is dominated by sequential LLM calls; streaming is partial (UI-side only).
- Evaluation is a 30-question smoke suite, not a benchmark — treat the numbers as a regression guard.
Contributing
Issues and PRs are welcome. Please read CONTRIBUTING.md first — it covers how to add an agent, how to run tests locally, and the conventions CI enforces.
License
MIT © 2026 007350
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found