dekko
Health Uyari
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Gecti
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Static code map generator (MAP.md + map.json) powered by tree-sitter — a Claude Code /map plugin and MCP server that gives coding agents call graphs, file outlines, and impacted-test lookups without spending tokens on parsing.




Ever watched your coding agent grep blind through a repo, open three
files it didn't need, and burn fifteen thousand tokens just to answer
"who calls this function"? That's the problem dekko exists to fix.
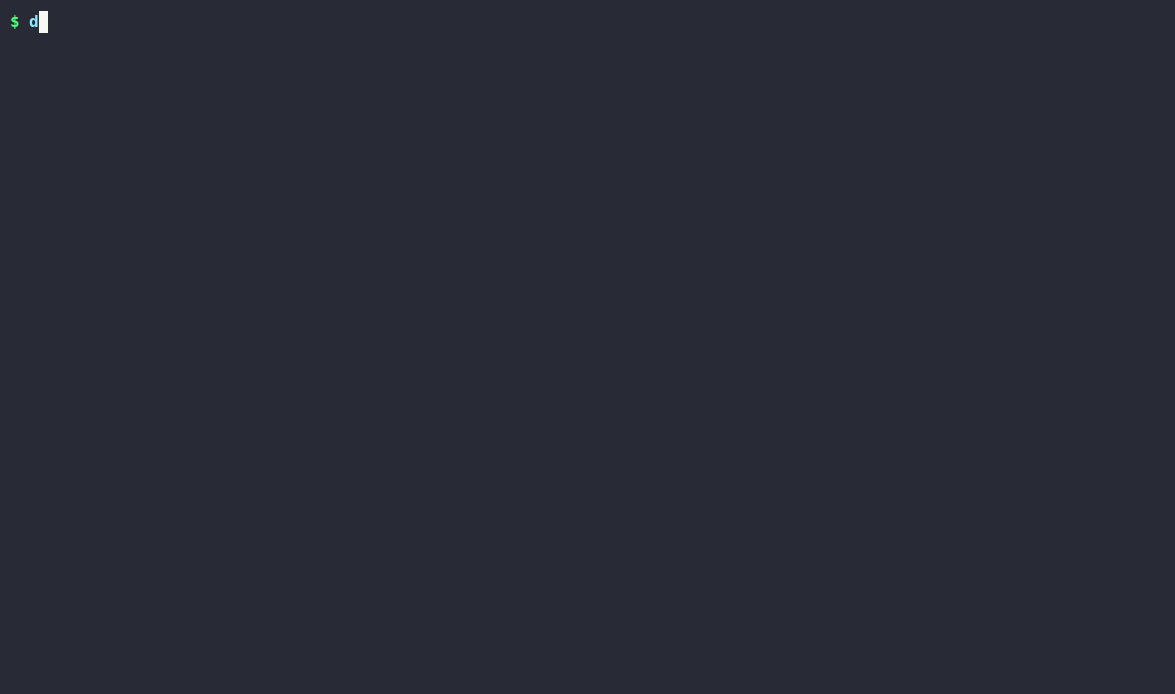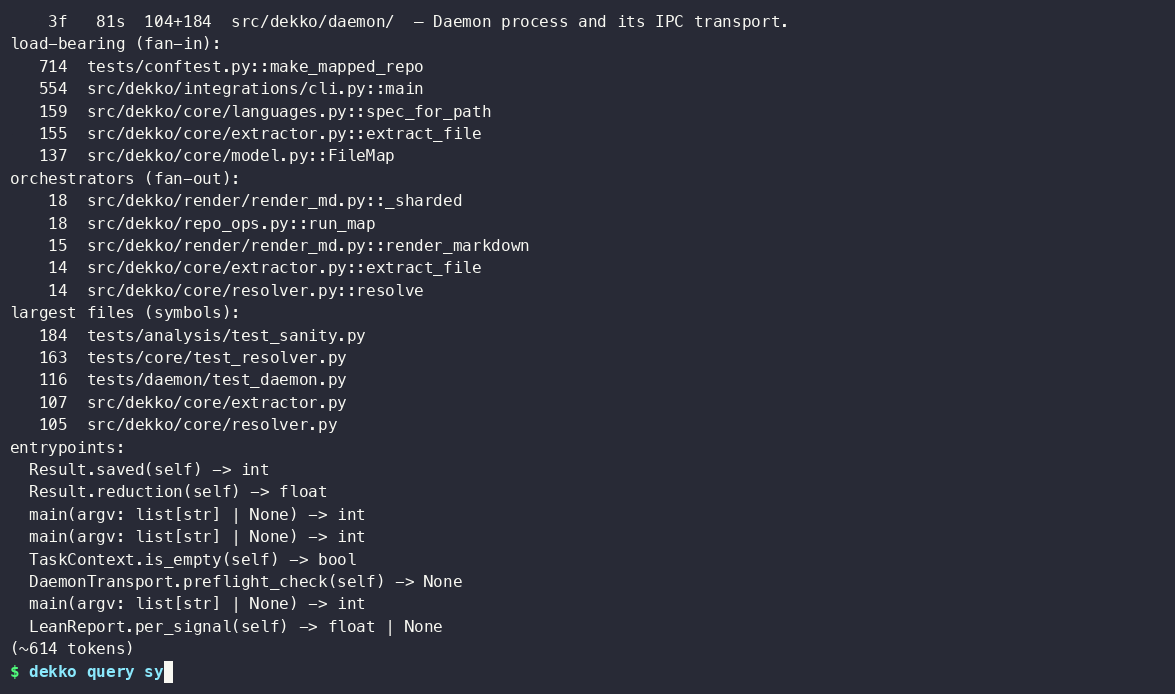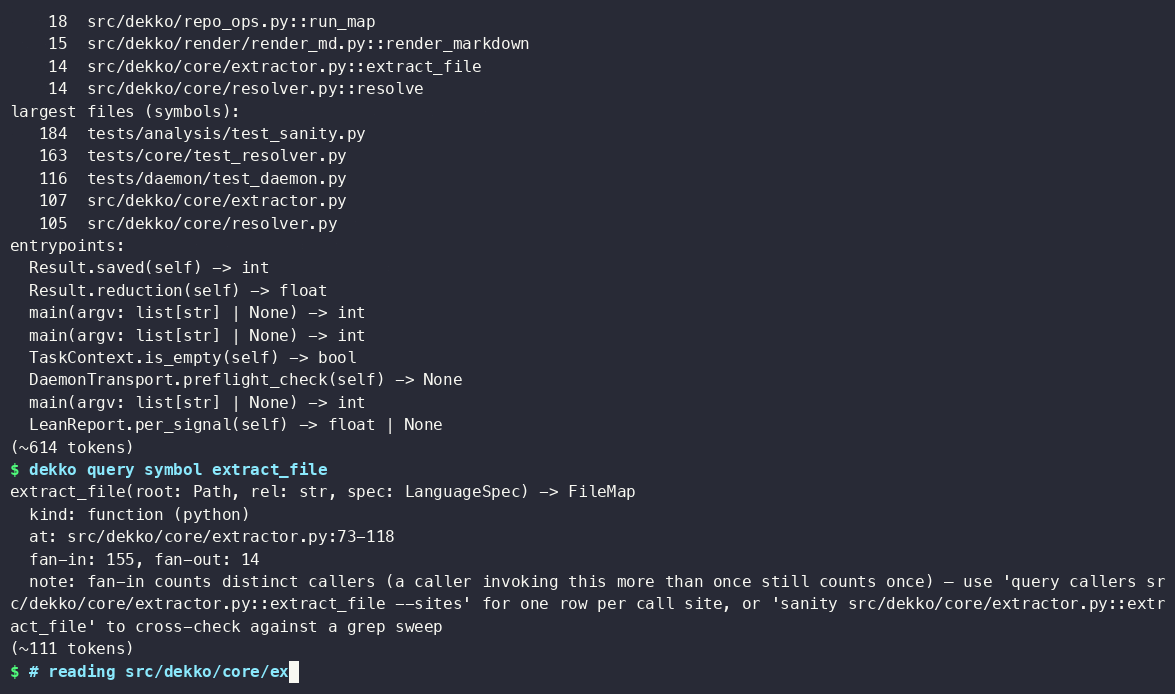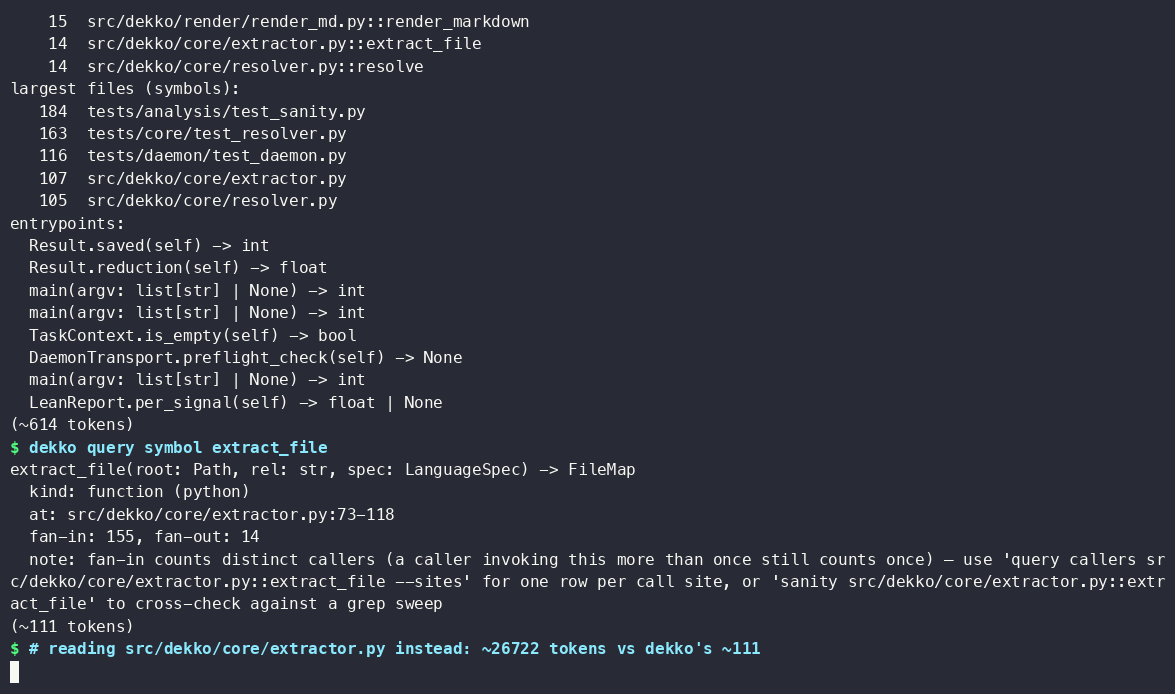
This demo runs on dekko's own repo (commit 835733c) — clone it and run the same three commands yourself.
dekko is a fast, offline, dependency-free static code map
generator and codebase indexer for LLM coding agents. It scans a
repository with tree-sitter (no model
tokens spent parsing) and writes:
MAP.md— a human-readable map: a per-directory overview, an
embedded architecture diagram, load-bearing/orchestrator rankings,
then every file's functions/methods with signatures, doc lines, and
who calls and is called by whom.map.json— the same graph in machine-readable form.
On top of the map, dekko gives an agent a token-cheap way to answer
questions like "what does this file contain," "who calls this function,"
and "what do I need to safely change this" — without reading whole files.
It ships as a CLI, a Claude Code /map plugin + MCP server
(Model Context Protocol), and
works with Cline too.
The result: 3x-200x fewer tokens than a plain Read/Grep workflow
for the same task, measured across 7 real, unmodified open-source
repos. The full breakdown is right below.
Why dekko?
Most agent workflows gather context by reading whole files or grepping
across a repo — expensive, and it throws away structure (who calls
what, what a function's fan-in/fan-out looks like). dekko instead
parses the repo once into a call graph and answers targeted questions
against it. Measured across 7 real, unmodified open-source repos
(Go, TypeScript, Java, Rust, Python/C++ — up to 14k files), dekko's
structured queries used 3x–200x fewer tokens than the equivalentRead/Grep workflow for the same task (repo orientation, outlining a
large file, tracing a symbol's callers/callees).
| Task | Example repo (scale) | dekko | Read/Grep | Savings |
|---|---|---|---|---|
Repo orientation (summary) |
awesome-go (10 files) | 308 tok | ~15,271 tok | ~50x |
Repo orientation (summary) |
cline (2,730 files) | 1,202 tok | ~4,020 tok | ~3.3x |
| Outline a large file | claude-code main.tsx (4,683 lines) |
1,017 tok | 200,981 tok | ~197x |
| Outline a large file | zed editor.rs (12,554 lines) |
1,996 tok | 115,109 tok | ~58x |
Symbol lookup (query_symbol + callers/callees) |
tensorflow Graph class |
~811 tok | 61,656 tok | ~76x |
Symbol lookup (query_symbol + callers/callees) |
spring-boot prepareContext |
759 tok | ~18,460 tok | ~24x |
Bundled context (workset) |
zed | 2,984 tok | ~5,903+ tok (targeted) / ~164,571 tok (whole file) | ~2x / ~55x |
Bundled context (workset) |
awesome-go | 617 tok | ~6,136 tok | ~10x |
dekko's cost stays roughly flat per query while Read/Grep scales
with file/repo size, so the ratio grows with scale. It's fast in wall-clock
terms too: mapping dekko's own ~3,500-symbol codebase from a cold
cache takes about 1.8 seconds; queries against the resulting map
return instantly. The win isn't
universal — small,
self-contained files and already-grep-friendly local symbols see
little to no benefit, and a few cases in the raw data are void because
the cheap answer was also an incomplete one. Seebenchmarks/real-world-repos/
for the full per-task breakdown, methodology, and correctness caveats.
Compared to tag-index tools like ctags/gtags, dekko resolves actual
call edges (not just definitions), ranks files by load-bearing-ness,
and speaks directly to agents over MCP or the CLI — no editor plugin
required.
Install
uv tool install dekko      # or: pip install dekko / pipx install dekko
dekko --claude-install     # add the /map command + MCP server to Claude Code, then restart
Extras (dekko[all] for ~55 more languages, dekko[search] for
embedding search), installing from a local clone, and uninstalling are
in docs/install.md.
Quick start
cd my-project
dekko map                  # writes .dekko/MAP.md + .dekko/map.json
dekko summary               # ~40-line digest: dirs, hotspots, entry points
.dekko/ is git-ignored by default; the map regenerates on demand, so
you rarely need to run dekko map again by hand. If your repo has
languages outside the default Tier-1 set (Python, C, C++, JS/TS, Go,
Java, Rust), dekko map will say so per file; install dekko[all] for
~55 more languages (see Install) and re-run.
Documentation
- docs/install.md — installation, extras, local
clone, uninstall - docs/cli.md — every CLI command, symbol targets,
excluding files, notes, daemon mode, language support - docs/claude-code.md — the
/mapplugin, push
hooks, Claude Code skills, the MCP server, and Cline
Learn more
- CHANGELOG.md — per-version history
- CONTRIBUTING.md — dev setup, testing, releasing
- benchmarks/ — token-efficiency measurements, including
a 7-repo real-world comparison against a plain Read/Grep workflow
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi