HumanStudy-Bench
Health Gecti
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 18 GitHub stars
Code Gecti
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
HumanStudy-Bench: Towards AI Agent Design for Participant Simulation
HumanStudy-Bench: Towards AI Agent Design for Participant Simulation


LLMs are increasingly used to simulate human participants in social science research, but existing evaluations conflate base model capabilities with agent design choices, making it unclear whether results reflect the model or the configuration.
Overview
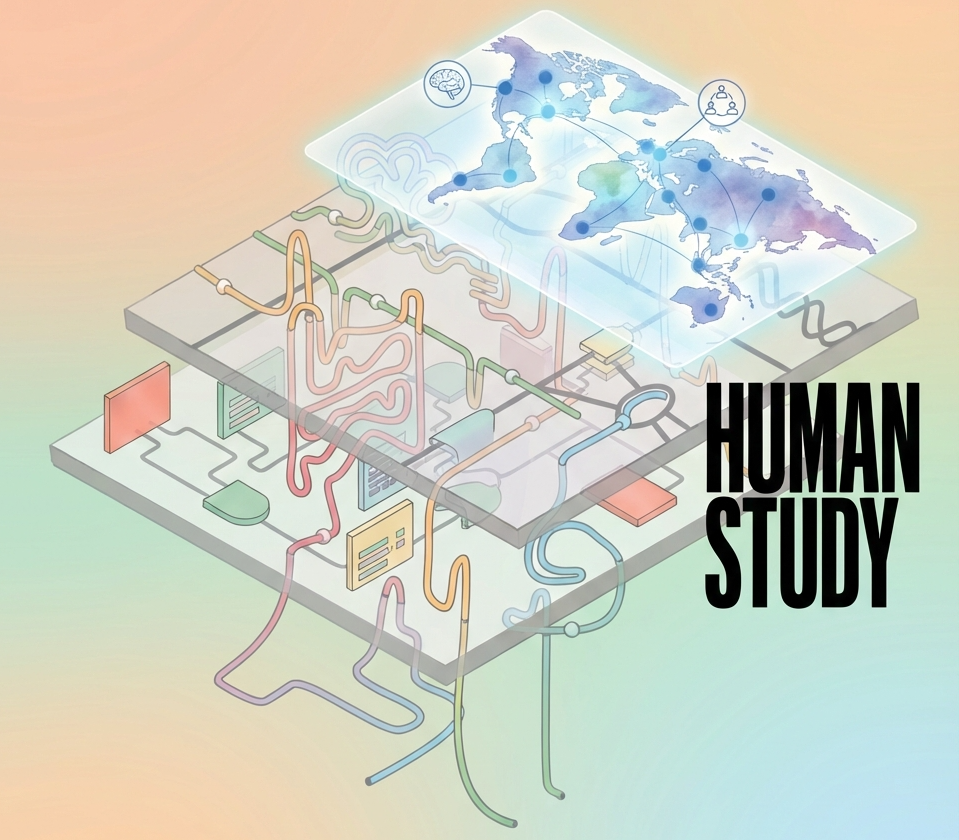
HumanStudy-Bench treats participant simulation as an agent design problem and provides a standardized testbed — combining an Execution Engine that reconstructs full experimental protocols from published studies and a Benchmark with standardized evaluation metrics — for replaying human-subject experiments end-to-end with alignment evaluation at the level of scientific inference.

With HumanStudy-Bench You Can:
- Test different agent designs on the same experiments to find what works best
- Run agents through real studies reconstructed from published human-subject research
- Compare results rigorously using inferential-level metrics that measure whether agents reach the same scientific conclusions as humans
We include 12 foundational studies (cognition, strategic interaction, social psychology) covering more than
6,000 trials with human samples ranging from
tens to over 2,100 participants.
You can also add your own studies using our automated pipeline to test custom research questions.
Quick Start
Installation
pip install -r requirements.txt
Running a Simulation
You can run an AI agent through a specific study (e.g., the "False Consensus Effect") or the entire benchmark suite. The engine handles the interaction, data collection, and statistical comparison against human ground truth.
# Run a specific study with a specific agent design (e.g., Mistral with a demographic profile)
python scripts/run_baseline_pipeline.py \
  --study-id study_001 \
  --real-llm \
  --model mistralai/mistral-nemo \
  --presets v3_human_plus_demo
Evaluation Metrics
Probability Alignment Score (PAS): Measures whether agents reach the same scientific conclusions as humans at the phenomenon level. It quantifies the probability that agent and human populations exhibit behavior consistent with the same hypothesis, accounting for statistical uncertainty in human baselines.
Effect Consistency Score (ECS): Measures how closely agents reproduce the magnitude and pattern of human behavioral effects at the data level. It assesses both the precision (capturing the pattern) and accuracy (matching the magnitude) of agent responses compared to human ground truth.
Viewing Results
After running simulations, get a summary of all runs (PAS, ECS, tokens, cost):
python scripts/simple_results.py
Outputs are written to results/benchmark/: simple_summary.md, simple_studies.csv, simple_findings.csv.
Customizing Agent Design
You can easily test new behavioral hypotheses by defining custom agent specifications. Simply create a new method file in src/agents/custom_methods/ to control how your agent presents itself to the experiment.
Example: src/agents/custom_methods/my_persona.py
def generate_prompt(profile):
    return f"You are a {profile['age']}-year-old {profile['occupation']}. Please answer naturally."
Run your new design:
python scripts/run_baseline_pipeline.py --study-id study_001 --real-llm --system-prompt-preset my_persona
Documentation
- Adding New Studies – Parse research PDFs and auto-generate simulation code
- Model Configuration – Set up API keys for OpenAI, Anthropic, Google, or OpenRouter
Community Edition
Looking to contribute new studies or explore community-contributed experiments? Check out the HumanStudy-Bench Community Edition — an open repository where researchers can submit, review, and share new study implementations beyond the original benchmark.
Citation & Hugging Face
If you use HumanStudy-Bench, please cite:
@misc{liu2026humanstudybenchaiagentdesign,
      title={HumanStudy-Bench: Towards AI Agent Design for Participant Simulation},
      author={Xuan Liu and Haoyang Shang and Zizhang Liu and Xinyan Liu and Yunze Xiao and Yiwen Tu and Haojian Jin},
      year={2026},
      eprint={2602.00685},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2602.00685},
}
Hugging Face: Benchmark and resources are available on the Hugging Face Hub — fuyyckwhy/HS-Bench-results.
License
This project is licensed under the MIT License - see the LICENSE file for details.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi