ReadAnyDoc
Health Warn
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 7 GitHub stars
Code Fail
- Hardcoded secret — Potential hardcoded credential in examples/reducto_sdk.py
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Open-source Reducto alternative: parse PDFs, scans and forms into Markdown, tables and typed data with a citation for every value. Claude Haiku or any model. Python library, MCP server, Reducto-compatible API.
ReadAnyDoc




Parse and extract documents with vision models, on your own machine and your own model account.
Open source, Reducto-compatible, built by Unmute. Website: https://arpitpatel25.github.io/ReadAnyDoc/
ReadAnyDoc reads every page of a PDF, scan, photo or Office file with a vision model (Claude Haiku 5.5 by default)
and returns typed blocks, tables, Markdown, or the fields of your schema, each with the place on the page it came
from. Around the model sits an engine that adds what a model alone does not give you: block types and positions,
form fields, headers and footers, table checks, word-level citations. It runs as a Python library or as a server
that speaks Reducto's HTTP API, so existing Reducto integrations work by changing one URL.
import readanydoc

result = readanydoc.parse("invoice.pdf")
print(result.markdown)
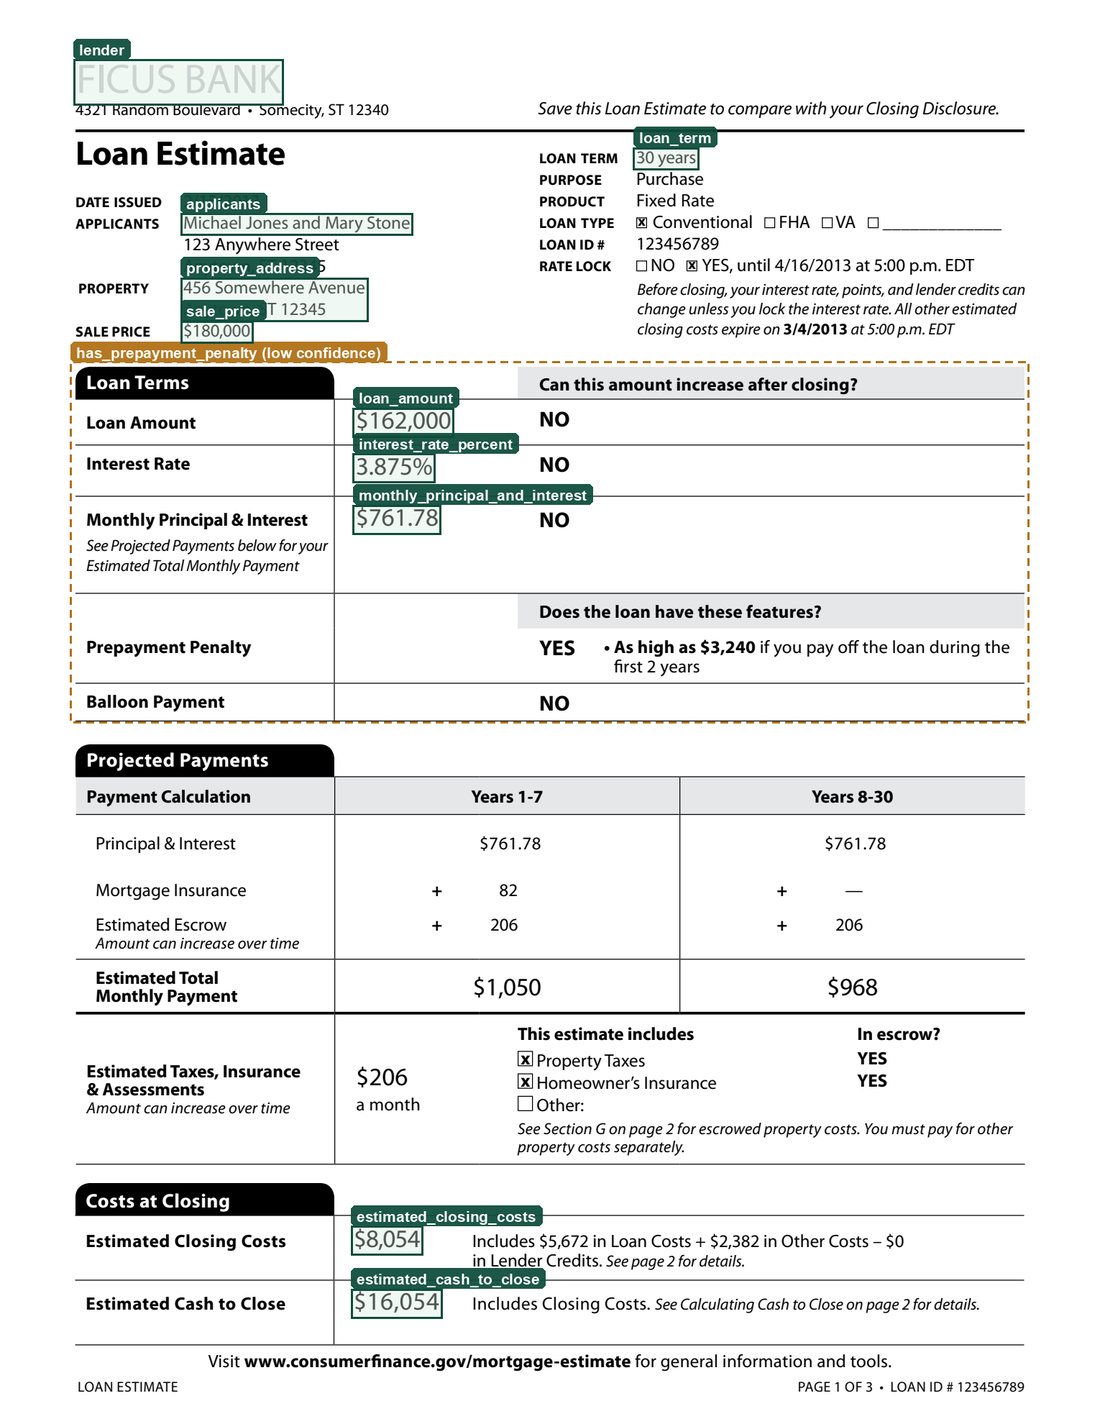
A real document, unedited: the US government's sample Loan Estimate, extracted in one call for about 1 cent.
All 11 fields are right, and every box is a citation ReadAnyDoc returned. A yes/no answer that is not printed as one
word is marked low confidence instead of pretending. A faded 1904 invoice is in the same folder:
examples/showcase. If it looks useful, ⭐ star the repo.
Results
Five public benchmarks (about 4,250 pages and 10 long documents), each scored with the benchmark's own grader (no AI judge). Same
documents and same requests for all three systems. Details and caveats: BENCHMARKS.md.
| Benchmark | Reducto r-1 | Model only (Haiku 5.5) | ReadAnyDoc engine (Haiku 5.5) |
|---|---|---|---|
| olmOCR-bench, overall (1,403 pages) | 80.9 | 82.2 | 84.2 |
| OmniDocBench, text error, lower is better (1,651 pages) | 0.095 | 0.081 | 0.081 |
| OmniDocBench, layout: block types right | 84.6% | 55.6% | 78.3% |
| RD-TableBench (1,000 tables) | 88.9 | 88.2 | 88.2 |
| FUNSD, form question/answer pairs (199 forms) | 78.6 | 71.6 | 77.4 |
| Cost per page | $0.010 | $0.001-0.002 | $0.003-0.005 |
Where Reducto is ahead: page layout (by about 6 points), formulas, header and footer removal, and speed
(about 5 s a page against 20-50 s here).
Install
pip install "readanydoc[engine]"        # the engine: layout model and OCR run on your CPU
pip install readanydoc                  # model-only mode, no local models
The engine also uses Tesseract when it is installed
(brew install tesseract / apt install tesseract-ocr). The layout and OCR weights (about 200 MB, Apache-2.0)
are downloaded on first use, so the very first parse takes a few minutes longer; later runs start straight away. Python 3.12.
Set your model provider's key: export ANTHROPIC_API_KEY=... (or OPENAI_API_KEY for OpenAI models).
Or let your coding agent set it up
Paste this into Claude Code, Codex or Cursor. It installs ReadAnyDoc, tests it on one of your files and wires it
into your project the way you choose (what it follows):
Set up ReadAnyDoc in this project. Follow the instructions at
https://raw.githubusercontent.com/arpitpatel25/ReadAnyDoc/main/AGENT_SETUP.md
Use
Parse
result = readanydoc.parse("statement.pdf")
result.blocks          # [Block(type="Table", content="<table>...", bbox=BoundingBox(...)), ...]
result.tables          # the Table blocks
result.markdown        # the whole document as Markdown
result.usage           # model calls, tokens, cost in USD, seconds
result.warnings        # anything that went wrong on a page
Extract into your own types
from pydantic import BaseModel

class Invoice(BaseModel):
    number: str
    issued: str
    total: float

out = readanydoc.extract("invoice.pdf", schema=Invoice)
out.data                      # Invoice(number="INV-2041", issued="2026-03-01", total=1575.0)
out.citations["total"]        # [Citation(content="1,575.00", bbox=BoundingBox(page=1, left=0.81, ...))]
A JSON Schema dict works as well as a pydantic class. instructions= is the system prompt for the extraction
model; array_extract=True processes long documents in parts and merges their lists.
Choose the mode and the models
| Mode | What it does |
|---|---|
engine (default) |
The model reads each page; the engine adds layout, forms, headers/footers, table checks and citations |
model-only |
One model read per page and nothing else: cheapest, fastest, no structure beyond what the model writes |
Every model the pipeline uses can be chosen, with its effort level and any further request options:
readanydoc.parse(
    "form.pdf",
    mode="engine",
    model="claude-haiku-5-5", effort="high",                 # page reading (the default)
    model_options={"max_tokens": 32000},                     # sent as given to the provider
    handwriting_model="claude-sonnet-5-5",                   # handwritten pages (the default); None = like any page
)

readanydoc.extract("contract.pdf", schema=Terms,
                 model="claude-haiku-5-5",                   # reads the pages
                 extract_model="claude-sonnet-5-5", extract_effort="high")   # fills the schema
Models: any Claude model, OpenAI models (gpt-...), or any OpenAI-compatible endpoint written asopenai_compatible:<model>@<base_url>. The benchmark numbers above are for Claude Haiku 5.5; other models work
but have not been measured here.
Command line
readanydoc parse invoice.pdf --markdown
readanydoc parse scan.pdf --mode model-only --model claude-sonnet-5-5
readanydoc extract invoice.pdf --schema invoice.schema.json
Server (Reducto-compatible API)
readanydoc serve --port 8000
# or: docker compose up
from reducto import Reducto   # Reducto's own SDK, unchanged

client = Reducto(api_key="anything", base_url="http://127.0.0.1:8000")
upload = client.upload(file=Path("invoice.pdf"))
result = client.parse.run(input=upload.file_id)
Parse, extract, split, classify, edit, async jobs, webhooks and citations are implemented. Configuration,
security settings and a route-by-route compatibility table: the documentation.
Inside Claude, Cursor and other assistants (MCP)
pip install "readanydoc[engine,mcp]"
claude mcp add readanydoc -e ANTHROPIC_API_KEY=your-key -- readanydoc mcp
In Claude Code you can install the plugin instead (server plus a skill): /plugin marketplace add arpitpatel25/ReadAnyDoc,
then /plugin install readanydoc@readanydoc.
Gives the assistant two tools, parse_document and extract_fields (with citations), on files on your computer.
Setup for Claude Desktop, Cursor and others: MCP guide.
LangChain and LlamaIndex
from readanydoc.integrations.langchain import ReadAnyDocLoader     # pip install "readanydoc[engine,langchain]"
from readanydoc.integrations.llamaindex import ReadAnyDocReader    # pip install "readanydoc[engine,llamaindex]"
One Markdown document per page with its page number. Guide.
How it works
Each page goes through a fixed sequence of stages (readanydoc/pipeline/): intake (file type, pages), triage
(digital or scanned, rotation), layout (an open layout model on CPU), read (the vision model; zoomed re-reads of
scanned pages where two reads must agree before a character changes; handwritten pages to a stronger model),
verify (table grids and printed totals checked without a model), ground (word and cell positions, block types,
form fields), assemble and shape (the requested output format). Nothing the model wrote is changed without
independent evidence. Design decisions and their reasons: docs/decisions.md.
Limits
- Slower than Reducto: 20-50 s per page here against about 5 s.
- About 1.5-3% of pages in large public benchmarks are declined by the model provider (content filtering). Those
pages fall back to plain OCR text atlowconfidence, or to a second model if you setREADANYDOC_REFUSAL_READER; the response says so inwarnings. - Confidence values are tiers from how a value was found on the page, not calibrated probabilities.
Documentation
| BENCHMARKS.md | full results against Reducto, cost, method, caveats; per-document scores in results/ |
| docs/story.md | why this exists, the bet behind it, what we learned |
| docs/research/journey.md | the full research record: every stage, every experiment, what was kept and dropped and why |
| docs/decisions.md | every design decision with its reason |
| Documentation | guides, API reference, configuration, migrating from Reducto |
| examples/ | runnable scripts |
| AGENTS.md, llms.txt | a map of the repo for AI agents; point your agent at it to ask questions |
Community
If ReadAnyDoc saved you time, a star on GitHub helps other developers find it.
Questions, ideas and what you built: GitHub Discussions.
Bugs: open an issue. Release news: watch the
repository (Watch, Custom, Releases).
Contributing
See CONTRIBUTING.md. Security reports: SECURITY.md.
License
Apache-2.0. The layout model (Docling "heron") and the PP-OCR weights are Apache-2.0.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found