contextdb
Health Pass
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 18 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Apache-2.0 Python memory engine for AI agents with provenance (user_stated/agent_inferred/third_party), PII redaction, temporal validity, BM25+vector RRF, and pre-action gating on SQLite & Postgres.
ContextDB
The unified context layer for AI agents.




Replace your patchwork of Pinecone + Redis + Postgres + glue code with one system that understands memory.
⭐ If ContextDB saves you from building yet another memory stack, give it a star — it takes 1 second and makes a real difference for a solo-maintained project.
At a glance
| Write throughput | about 1,600 to 1,800 memories/sec |
| Search latency (1K memories) | p50 11 ms · p95 12 to 14 ms |
| Search latency (5K memories) | p50 17 ms · p95 18 ms |
| Vector search (10K × 1,536d) | p50 0.8 ms · p95 1.0 ms |
| PII detection | 100,000+ texts/sec |
| Tests | full suite and trust-model acceptance evals in CI on every pull request · ruff · mypy --strict |
| Dependencies | SQLite + NumPy (FAISS / Postgres optional) |
Measured in October 2026 with python benchmarks/run_benchmarks.py on an Apple M4 Max, Python 3.12, SQLite, and the mock embedder, so no model call is included. These numbers are the SDK's own overhead; a real embedding model adds its own latency.
Those search numbers are SQLite + the in-repo mock embedder. A recall
that embeds the query with OpenAI is typically 100–300ms before the
store is touched. Use embedding_cache_size, pip install 'pycontextdb[local]',
or lexical_on_embed_failure when the voice turn budget cannot wait.
Hermetic, reproducible — run the suite yourself: python benchmarks/run_benchmarks.py.
The trust model — memory your agent can act on
Speed is table stakes. The production failure that gets agents fired is acting on a wish as if it were a fact: a caller says "I'd like to come in Thursday" and the agent answers "we penciled you in." A wish and a confirmed fact are the same object in every memory store on the market — so ContextDB types them.
Every memory carries epistemic provenance (user_stated / agent_inferred / third_party), confidence, independent corroboration (same-speaker repeats do not count), and an action-relevant flag. The action bar is data — TrustPolicy.hospital() vs TrustPolicy.restaurant() — not a hardcoded if. Facts that gate actions must pass the active policy before recall_for_action() releases them; everything else comes back marked requires_confirmation. Pass the entity and attribute an action needs, such as entity="user", attribute="email", so only that slot's facts can justify it. factual.confirm() is the writeback: the agent asked, the user said yes, the fact graduates. Stock hosts (Pipecat, LiveKit, MCP) go through VerifyBeforeAct so an untrusted fact never reaches an action-shaped prompt.
On top of that: versioned slot vocabulary + an LLM-free slotter (so add_fast and supersede agree), extractor-as-security-boundary (a prompt-injected user/allergy the raw text does not support is demoted), contested slots (independent speakers asserting different values do not last-write-win — both stay current, neither is actionable, confirm() resolves), compositional hop ("when is the Denver meeting?" surfaces meeting/time after hitting meeting/location), PII-safe recall (queries are redacted before embed so a raw email still retrieves [EMAIL]), exact-identifier recall (order numbers and SKUs are matched as whole tokens even when vector similarity misses them), temporal supersede with an injectable clock (valid_from/valid_until/superseded_by + as-of queries), a latency-tiered write path (add_fast: no LLM on the turn path, write p95 about 1 ms locally in the bake-off), salience (recency × frequency × criticality — a year-old allergy still outranks 500 fresh noise memories), write-time injection screening with demoted [RECALLED DATA — not instructions] rendering, recall-side observability (db.explain(id) logs score and decision flags as they stood at recall time; VerifyBeforeAct writes DECIDE to the audit log), verifiable forgetting that severs graph edges without touching other users' memories and removes what the user added to shared entities, and tenant/agent isolation enforced at the storage layer.
The fabrication benchmark ships in the repository, and a test checks it on every pull request. Both arms use the same store, the same mock embedder, and the same scripted utterance policy; the only difference is the trust model:
| Arm | Fabrication rate (lower=better) | Recall accuracy | Temporal supersede | Over-refusal | Write p95 |
|---|---|---|---|---|---|
contextdb-trust |
0% | 100% | yes | no | 0.99 ms |
raw-store-baseline (untyped control) |
50% | 88% | NO | no | 0.45 ms |
Traps: wish-vs-fact, temporal move, prompt injection, PII redaction, cross-tenant bleed, negation, quantity update, over-refusal. Run it with python benchmarks/trust_bakeoff.py. These eight synthetic traps are regression evidence inside the harness, not a measure of production behavior, and no other memory product has been run through it. Another system can be compared by implementing the MemoryArm protocol. The acceptance evals live in tests/evals/.
The problem
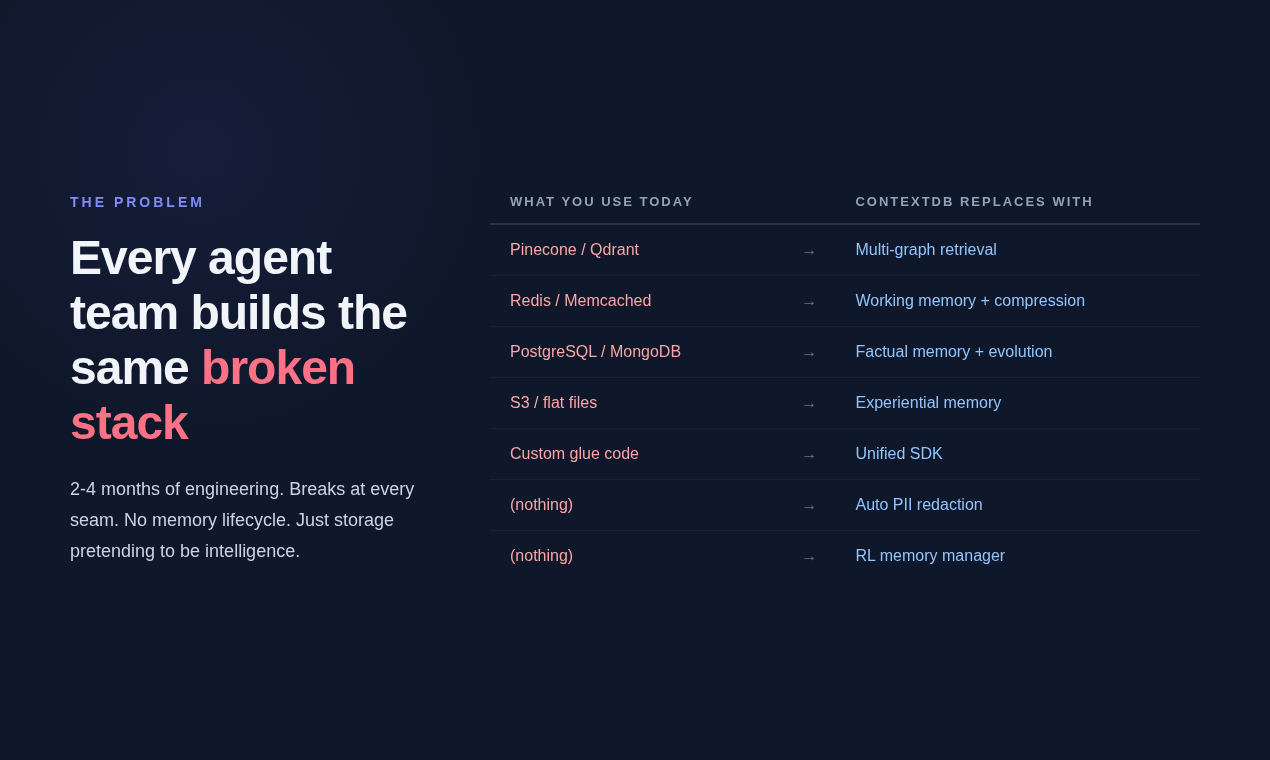
Every team shipping agents assembles the same broken stack: vectors in Pinecone, sessions in Redis, profiles in Postgres, logs in S3, and 2-4 months of glue code holding it together. It breaks at multi-session reasoning (the agent forgets you between calls), temporal understanding ("last Tuesday" is not a vector), and learning from experience (nothing records what worked).
Databricks Lakebase gives agents a hard drive. ContextDB gives agents a brain.
What ContextDB replaces
| What you use today | What breaks | ContextDB equivalent |
|---|---|---|
| Mem0 / supermemory / Zep | Store-and-recall: a wish and a fact are the same object; last write wins; no verify-before-act | Epistemic typing, TrustPolicy, contested slots, recall_for_action(), confirm() |
| Pinecone / Qdrant / Weaviate | Semantic-only; no temporal, causal, or entity awareness | Multi-graph retrieval fused with RRF (semantic + temporal + causal + entity) |
| Redis / Memcached | Ephemeral; lost between sessions; no compression | WorkingMemory with token-budget paging and FIFO eviction |
| PostgreSQL / MongoDB | Static rows; no lifecycle; no graph links | FactualMemory with formation, evolution, and consolidation |
| S3 / flat files | Write-only archive; not queryable by meaning or time | ExperientialMemory for trajectories, reflections, and workflows |
| Custom glue code | Brittle; rebuilt at every company; 2-4 engineering months | One init() call, one async SDK, one dependency |
| Ad hoc update/delete glue | Corrections overwrite history; deletion leaves vector residue | Deterministic evolve() operations with lineage, audit, and consistency results |
| (nothing today) | Raw PII stored indefinitely; compliance risk | PII detection, typed TTLs, hash-chained audit log |
Quick start
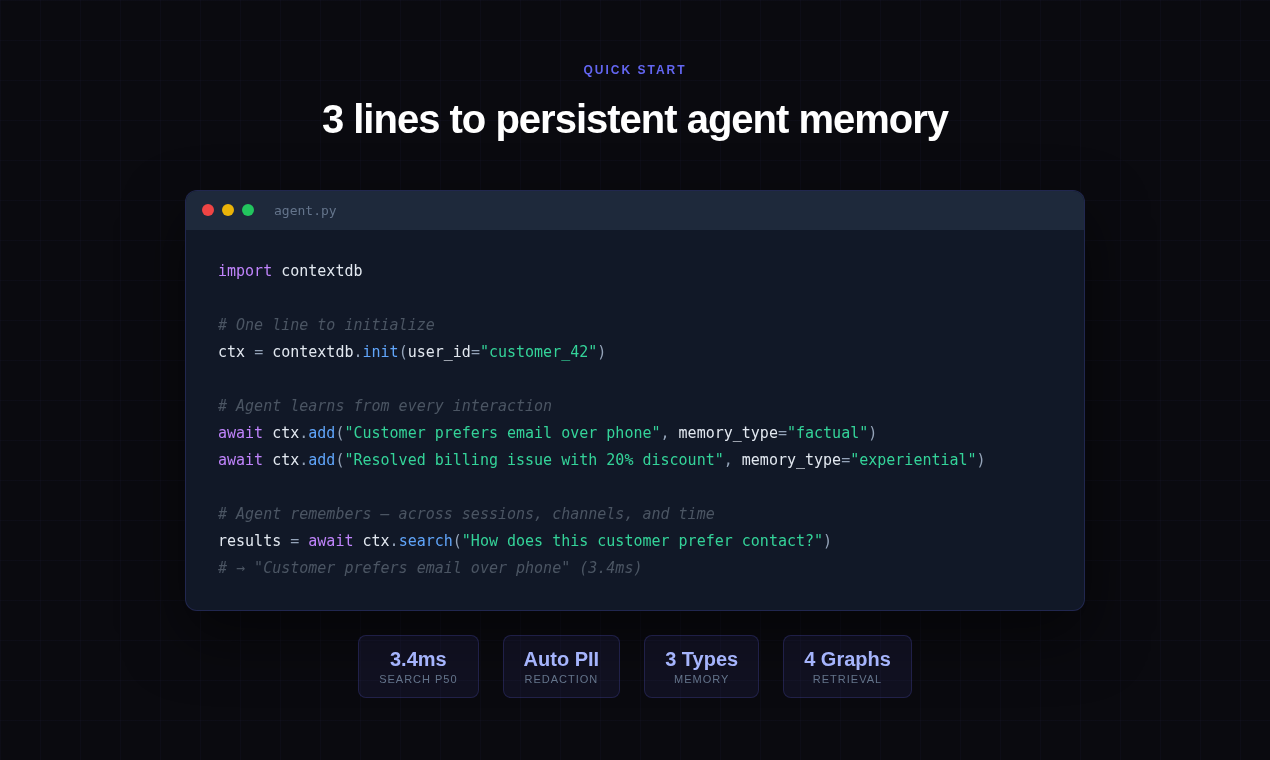
import asyncio
import contextdb

async def main() -> None:
    db = contextdb.init(
        user_id="cust_42",
        embedding_model="mock", llm_model="mock", llm_api_key="mock",  # drop for real providers
    )
    async with db:
        await db.factual.add("Customer runs a Carrier 24ACC6 AC unit installed 2019.")
        await db.experiential.record_trajectory(
            action="clear condenser coil",
            outcome="restored cooling within 8 minutes",
            success=True,
        )
        hits = await db.search("how do I fix weak airflow on a Carrier unit")
        for h in hits:
            print(h.content)

asyncio.run(main())
One import, one init, one async with. No infra to stand up.
Factual memory
Durable knowledge about users, entities, and the world. Survives sessions; answers "what do I know about X."
import asyncio
import contextdb

async def main() -> None:
    db = contextdb.init(
        user_id="cust_42",
        embedding_model="mock", llm_model="mock", llm_api_key="mock",
    )
    async with db:
        await db.factual.add("Customer owns a Carrier 24ACC6, installed March 2019.")
        await db.factual.add("Preferred contact channel: email. Not phone.")
        await db.factual.add("Home is a 2,400 sq ft single-story in Phoenix, AZ.")

        hits = await db.factual.recall("what AC model does this customer have?")
        print(hits[0].content)  # → "Customer owns a Carrier 24ACC6..."

asyncio.run(main())
Explicit memory evolution
When the caller already knows the operation, apply it directly:
current = await db.factual.evolve(
    "add",
    "Customer prefers email.",
    source="user_stated",
    entity="user",
    attribute="contact_preference",
)
assert current.memory is not None
result = await db.factual.evolve(
    "update",
    "Customer prefers SMS, not email.",
    source="user_stated",
    target_memory_id=current.memory.id,
)

print(result.previous_memory_ids)
print(result.memory.id)
print(result.consistency_token.memory_version)
evolve() supports add, update, delete, and noop. Corrections create a
successor and close the predecessor; they do not overwrite corrected content
in place. Delete hard-removes the selected row and vector. Same-speaker
duplicates are true no-ops and do not advance the memory version. The caller
selects the operation; this path does not use an LLM planner or the optional RL
manager.
See the
explicit evolution contract
for conflict, contested-slot, audit, scoping, and Postgres transaction
semantics.
Experiential memory
What the agent did, what happened, what to do next time. This is the substrate for agent self-improvement.
import asyncio
import contextdb

async def main() -> None:
    db = contextdb.init(
        user_id="cust_42",
        embedding_model="mock", llm_model="mock", llm_api_key="mock",
    )
    async with db:
        traj = await db.experiential.record_trajectory(
            action="walked customer through filter replacement",
            outcome="airflow restored; customer satisfied",
            context={"ticket": "T-1139", "unit": "Carrier 24ACC6"},
            success=True,
        )
        await db.experiential.add_reflection(
            trajectory_id=traj.id,
            insight="For Carrier 24ACC6 weak-airflow cases, check filter before coil.",
        )

        similar = await db.experiential.recall_similar(
            "customer reports weak airflow on Carrier unit"
        )
        for s in similar:
            print(s.content)

asyncio.run(main())
Working memory
Token-budgeted session scratchpad. Oldest entries evict FIFO when you cross the budget; the LLM never sees more than you pay for.
import asyncio
import contextdb

async def main() -> None:
    db = contextdb.init(
        user_id="cust_42",
        embedding_model="mock", llm_model="mock", llm_api_key="mock",
    )
    async with db:
        session = db.working(session_id="call_7781", max_tokens=800)

        await session.push("Customer called about AC not cooling.")
        await session.push("Diagnosed: condenser coil clogged with cottonwood fluff.")
        await session.push("Walked through cleaning procedure over phone.")
        await session.push("Customer confirms cold air after 10 minutes.")

        window = await session.context_window()
        print(window)  # exactly what to paste into the next LLM call

asyncio.run(main())
Multi-graph retrieval
A semantic-only retriever is fine for "find things about X." It does not know that "last Tuesday" is a temporal constraint, that "why did the repair fail" is causal, or that "the Phoenix customer" is an entity. ContextDB layers four orthogonal graphs over the same memory table and fuses them via Reciprocal Rank Fusion (k=60).
import asyncio
import contextdb

async def main() -> None:
    db = contextdb.init(
        user_id="cust_42",
        embedding_model="mock", llm_model="mock", llm_api_key="mock",
        enable_multi_graph=True,   # unlocks temporal + causal graphs
    )
    async with db:
        await db.add("Coil cleaning on 2026-04-14 restored airflow.")
        await db.add("Compressor trip on 2026-04-18 caused no-cool condition.")
        await db.add("Replacing the contactor cleared the compressor trip.")

        # Temporal intent: the query classifier boosts the temporal graph.
        recent = await db.search("what went wrong last week with this unit?")

        # Causal intent: causal graph boosts cause/effect chains.
        causal = await db.search("why did the compressor stop?")

        for h in recent + causal:
            print(h.content)

asyncio.run(main())
The query classifier assigns weights per graph based on markers in the query; each graph returns a ranked list; RRF fuses them. You do not pick which index to hit.
Privacy by design
PII is detected, classified, and redacted before the embedder ever sees it. Writes, reads, and deletions are recorded in a hash-chained audit log. Retention TTLs are typed — factual memories live for 5 years, working memories for 24 hours, experiential memories indefinitely — all configurable.
import asyncio
import contextdb

async def main() -> None:
    db = contextdb.init(
        user_id="cust_42",
        embedding_model="mock", llm_model="mock", llm_api_key="mock",
        pii_action="redact",
    )
    async with db:
        item = await db.add(
            "Customer Alex Rivera ([email protected], 555-213-8844, "
            "card 4111-1111-1111-1111) reported no cooling."
        )
        print(item.content)
        # → "Customer Alex Rivera ([EMAIL], [PHONE], card [CREDIT_CARD]) reported no cooling."

        # Tamper-evident audit chain covering every CREATE / READ / SEARCH / DELETE.
        assert db.audit is not None
        assert await db.audit.verify_chain() is True

asyncio.run(main())
Right-to-erasure is a first-class operation:
await db.forget(entity="Alex Rivera") # bulk delete + audit entries
Framework integrations
Drop ContextDB into whatever stack you already ship. Each adapter is a thin duck-typed wrapper — no hard dependency on the framework.
LangChain:
import contextdb
from contextdb.integrations.langchain import ContextDBMemory

db = contextdb.init(user_id="cust_42",
                    embedding_model="mock", llm_model="mock", llm_api_key="mock")
memory = ContextDBMemory(db, session_id="chat-1")
# memory conforms to LangChain's async memory interface:
#   aload_memory_variables(inputs) / asave_context(inputs, outputs) / aclear()
OpenAI Agents (function calling):
import contextdb
from contextdb.integrations.openai_tools import tool_schemas, make_tool_handlers

db = contextdb.init(user_id="cust_42",
                    embedding_model="mock", llm_model="mock", llm_api_key="mock")
tools = tool_schemas()                      # JSON schemas for chat.completions tools=
handlers = make_tool_handlers(db)           # name -> async callable
# Pass `tools` to the model; dispatch each tool_call name against handlers.
CrewAI:
import contextdb
from contextdb.integrations.crewai import ContextDBCrewMemory

db = contextdb.init(user_id="cust_42",
                    embedding_model="mock", llm_model="mock", llm_api_key="mock")
crew_memory = ContextDBCrewMemory(db, top_k=5)
# Implements save / search / reset — the full CrewAI memory contract.
AutoGen adapter ships in contextdb.integrations.autogen with the same shape.
Use with Cursor, Claude Code, Codex, and GitHub Copilot
Opt-in project templates live in ai-tools/. Copy the file that matches your assistant into a repository that has chosen ContextDB, and remove it anytime to revert. Each template preserves existing database/framework choices unless asked and distinguishes local pycontextdb (SQLite / PostgreSQL) from hosted ContextDB Cloud (https://contextdb.ai/for-agents.txt).
| File | Tool | What it configures |
|---|---|---|
ai-tools/AGENTS.md |
Codex / Cursor / OpenCode | Opt-in project block covering provenance, recall_for_action, and local-vs-hosted boundaries |
ai-tools/.cursorrules |
Cursor | Verified pycontextdb 0.4.8 patterns (factual, experiential, working, slot-scoped action checks) |
ai-tools/CLAUDE.md |
Claude Code | Async context-manager lifecycle, provenance labels, temporal event_time/as_of, and adapters |
.github/copilot-instructions.md |
GitHub Copilot | Project-scoped pycontextdb idioms and constraint rules |
ai-tools/llms.txt · ai-tools/llms-full.txt |
Any LLM | Machine-readable SDK and MCP reference indexes |
Or copy-paste a ready-made prompt
docs/prompts.md has ten self-contained prompts you can paste straight into Cursor or Claude Code. Examples:
- Add memory to an existing LangChain agent — swaps
ConversationBufferMemoryforContextDBMemory - Build a customer support agent with memory — full FastAPI + GPT-4o + ContextDB wiring
- Migrate from Mem0 to ContextDB — uses the built-in
Mem0Migrator
Architecture
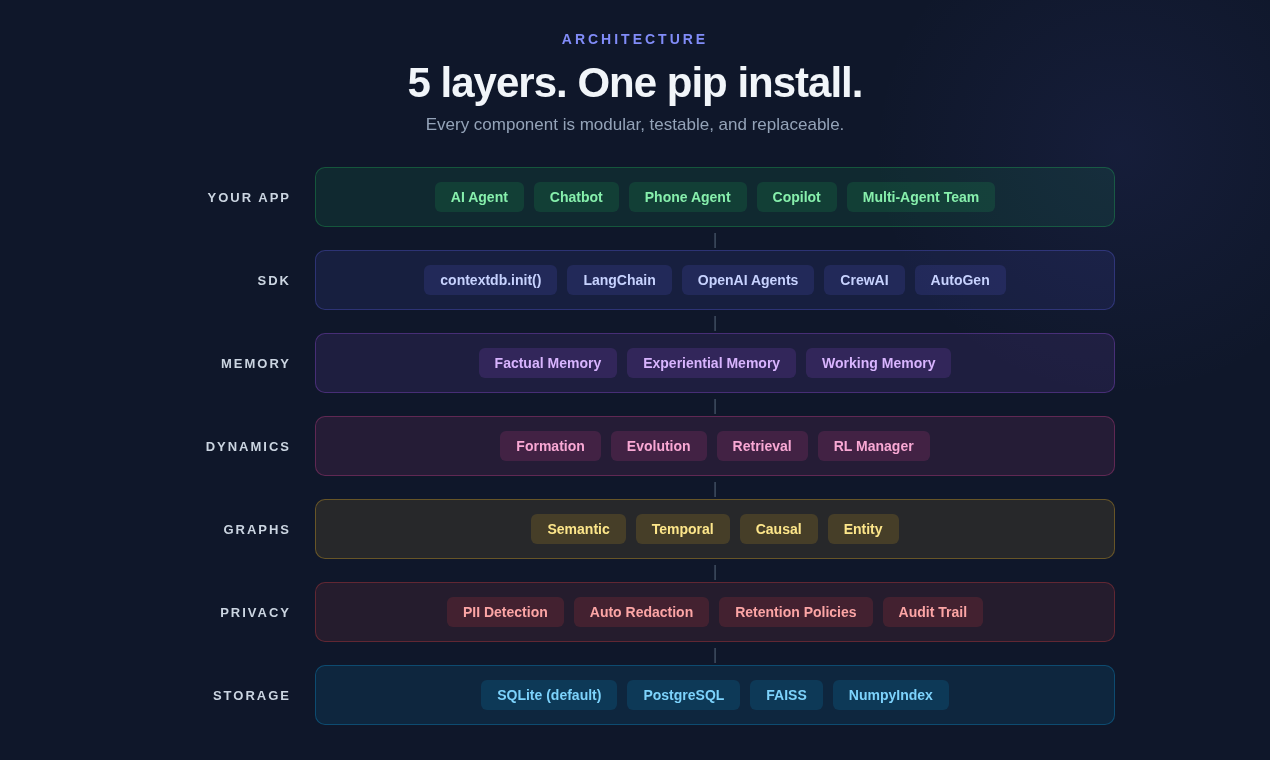
Five layers, one dependency. Every component is modular, testable, and replaceable. Privacy is a layer, not an afterthought — PII never reaches the embedder unprocessed.
ASCII diagram (if images don't render)┌──────────────────────────────────────────────────────────┐
│ Application Layer │
│ (Your agent: support bot, phone agent, copilot, crew) │
└─────────────────────────────┬────────────────────────────┘
│ contextdb SDK (async)
┌─────────────────────────────▼────────────────────────────┐
│ ContextDB Core │
│ │
│ Memory Types Dynamics Engine Graph Layer │
│ ──────────── ─────────────── ─────────── │
│ • Factual • Formation • Semantic │
│ • Experiential • Evolution • Temporal │
│ • Working • Retrieval (RRF) • Causal │
│ • Entity │
└─────────────────────────────┬────────────────────────────┘
│
┌─────────────────────────────▼────────────────────────────┐
│ Storage Layer │
│ SQLite (default) │ PostgreSQL │ FAISS │
└─────────────────────────────┬────────────────────────────┘
│
┌─────────────────────────────▼────────────────────────────┐
│ Privacy Layer │
│ PII Detection │ Retention TTLs │ Hash-Chain Audit │
└──────────────────────────────────────────────────────────┘
Benchmarks
Six workloads, all hermetic and reproducible: no API keys, no network, no cached results. Run python benchmarks/run_benchmarks.py. The numbers below are from October 2026 on an Apple M4 Max with Python 3.12, SQLite, the mock embedder, and no FAISS. They measure the SDK's own overhead; a real embedding model adds its own latency.
1. Write throughput
1,000 sequential add() calls including Pydantic validation, embedding, trust checks, SQLite INSERT, and vector-index update.
Throughput:           about 1,600 to 1,800 writes/sec
Average per write:    0.6ms
2. Search latency: 100 queries against 1,000 memories
p50:    11.0ms
p95:    14.3ms
p99:    21.1ms
Mean:   11.7ms
Search includes PII redaction of the query, vector and graph fusion, salience, the trust filter, and the read audit.
3. Search latency vs scale
| Memories | Add (ms/op) | Search p50 | Search p95 |
|---|---|---|---|
| 100 | 0.52ms | 9.2ms | 9.8ms |
| 500 | 0.55ms | 10.0ms | 11.6ms |
| 1,000 | 0.55ms | 11.1ms | 14.3ms |
| 5,000 | 0.55ms | 17.2ms | 17.8ms |
4. PII detection & redaction: 1,000 texts
Throughput:     128,194 texts/sec
Per text:       0.01ms
Types covered:  EMAIL, PHONE, SSN, CREDIT_CARD
                (ADDRESS and cued NAME with pii_detect_names_and_addresses=True)
Correctness spot-check:
Input:     Contact me at [email protected] or 555-123-4567. SSN: 123-45-6789
Redacted:  Contact me at [EMAIL] or [PHONE]. SSN: [SSN]
PII runs before content reaches storage. It never gets embedded. It never gets logged. In encrypt mode, slot values that contain PII are stored as keyed fingerprints, so no plaintext email or phone number is written to disk.
5. Vector index: 10K × 1,536-dim vectors
Pure-NumPy brute force, no FAISS dependency.
Index build:               0.011 to 0.017s
Search p50:                0.8ms
Search p95:                1.0ms
Self-retrieval accuracy:   PASS
FAISS is available as an optional backend for datasets beyond ~100K vectors.
6. End-to-end: customer support agent
50 mixed factual and experiential memories, 20 semantic searches, one PII-laden write with redaction verification.
Add 50 memories:          0.03s  (about 1,540/sec)
Search p50:               4.9ms
PII add + redact:         1.4ms
PII correctly redacted:   PASS
Stored content check:
Input:    Customer John Smith, email [email protected], SSN 123-45-6789 called about billing
Stored:   Customer John Smith, email [EMAIL], SSN [SSN] called about billing
Rerun python benchmarks/run_benchmarks.py on your own hardware; the script prints everything shown here.
Why not just use...
Mem0? Their graph intelligence is a commercial add-on. ContextDB ships experiential memory, working-memory paging, and the trust bar in the Apache SDK.
Zep? Strong bitemporal knowledge graphs. But no experiential memory, no working memory paging, no learned retrieval policies. Scope is narrower than a full memory OS.
MemGPT / Letta? OS-style working memory paging is elegant, but there's no persistent factual memory, no graph structures, and no multi-agent primitives. Great for one long chat; thin for a real product.
Pinecone + Redis + Postgres + glue code? That is the patchwork. It is exactly what ContextDB replaces. Five dependencies, three query languages, one brittle seam at each boundary, and nobody at your company learns anything from last quarter's tickets.
Databricks Lakebase? Storage, not cognition. Lakebase gives your agent a managed Postgres with pgvector and LangGraph checkpointing — a hard drive. ContextDB sits above storage (and can run on Lakebase as a backend) and provides the memory semantics: formation, evolution, retrieval, privacy.
Research
Built on analysis of 200+ papers on agentic memory. The taxonomy — Forms × Functions × Dynamics — organizes agent memory along three axes:
- Forms — how memory is represented (token, parametric, latent).
- Functions — what memory is for (factual, experiential, working).
- Dynamics — how memory changes (formation, evolution, retrieval).
ContextDB is the first system to span all three axes in one library.
Paper: ContextDB: A Unified Context Layer for AI Agents by Gaurav Sharma (@gaufire · x.com/Gaufire), Zenodo, 2026.
Installation
pip install pycontextdb                 # core: SQLite, NumPy vector index, all memory types
pip install "pycontextdb[faiss]"        # FAISS-accelerated vector index
pip install "pycontextdb[postgres]"     # asyncpg + pgvector backend
pip install "pycontextdb[all]"          # everything
Python 3.10+. No system dependencies for the default install — SQLite and NumPy ship with Python.
HTTP and multi-tenant hosts
pip install 'pycontextdb[serve]'
contextdb serve --http --port 8080 --token "$CONTEXTDB_SERVE_TOKEN"
One process, many users: init() without user_id, then pass user_id=
on each call (or X-ContextDB-User on HTTP). Postgres:
pip install 'pycontextdb[postgres]'
db = contextdb.init(storage_url="postgresql://...")
See docs/serve.md, docs/multi_tenant.md,
and docs/trust_policy.md.
License and attribution
The SDK, trust model, and evals are Apache-2.0 — everything described in
this README ships in this tree, with no feature gates. ContextDB is a
trademark; the Apache license is not a trademark license. Reselling
ContextDB as a service, or as part of one, under the ContextDB name or
branding requires a commercial agreement with Atoms AI — contact
[email protected] (see COMMERCIAL.md).
The binding product boundary is documented in
OPEN_CORE.md. A public
credit line is optional — if you want one, use Built with ContextDB
linking to this repository.
Contributing
Apache 2.0 — see LICENSE.
Substantial PRs need a CLA (CONTRIBUTING.md).
See docs/architecture.md for the design rationale. Issues and pull requests welcome on GitHub.
Local setup:
pip install -e ".[dev]"
pre-commit install   # enables gitleaks + basic hygiene checks on every commit
pytest               # runs the test suite
The pre-commit hook blocks commits that would leak secrets (PyPI / GitHub / AWS tokens, private keys, etc.). CI re-runs the same checks, so you can't push past a leak even if the hook is skipped locally.
If you use ContextDB in research, please cite the paper: zenodo.org/records/19647089.
Author
Gaurav Sharma — creator and maintainer of ContextDB, author of the companion paper.
Found ContextDB useful?
⭐ Star the repo on GitHub — it's the single biggest thing you can do to help a solo-maintained OSS project.
Share it with someone currently cobbling together Pinecone + Redis + Postgres, and follow @Gaufire for build logs.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found