guarded-computer-use-mcp
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Fail
- spawnSync — Synchronous process spawning in e2e/approval-inject.mjs
- process.env — Environment variable access in e2e/approval-inject.mjs
- process.env — Environment variable access in e2e/gate-lock-e2e.mjs
- process.env — Environment variable access in server.js
- exec() — Shell command execution in src/approval.js
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Windows computer-use MCP with a human-in-the-loop approval gate
guarded-computer-use-mcp
Give your agent hands — without giving away the keys.
A Windows computer-use MCP server where every risky action stops and waits for a
real human click. 26 tools: screenshot, mouse, keyboard, UI Automation, OCR,
windows, clipboard.
[!WARNING]
This server moves your real mouse and keyboard, with your user's privileges,
on your real desktop. There is no sandbox and no undo.It can send messages as you, delete files, and read everything on your screen —
and what it reads is transmitted to your model provider.The approval gate and the policy lists reduce the blast radius. They do not
eliminate it. Read Risks and disclaimer before you
point an agent at this.
Why
Most computer-use tools hand the model a keyboard and hope for the best. That is
fine until the model mis-clicks into a chat window, an email, or a payment page —
and there is no undo.
This one puts a gate in front of the dangerous part:
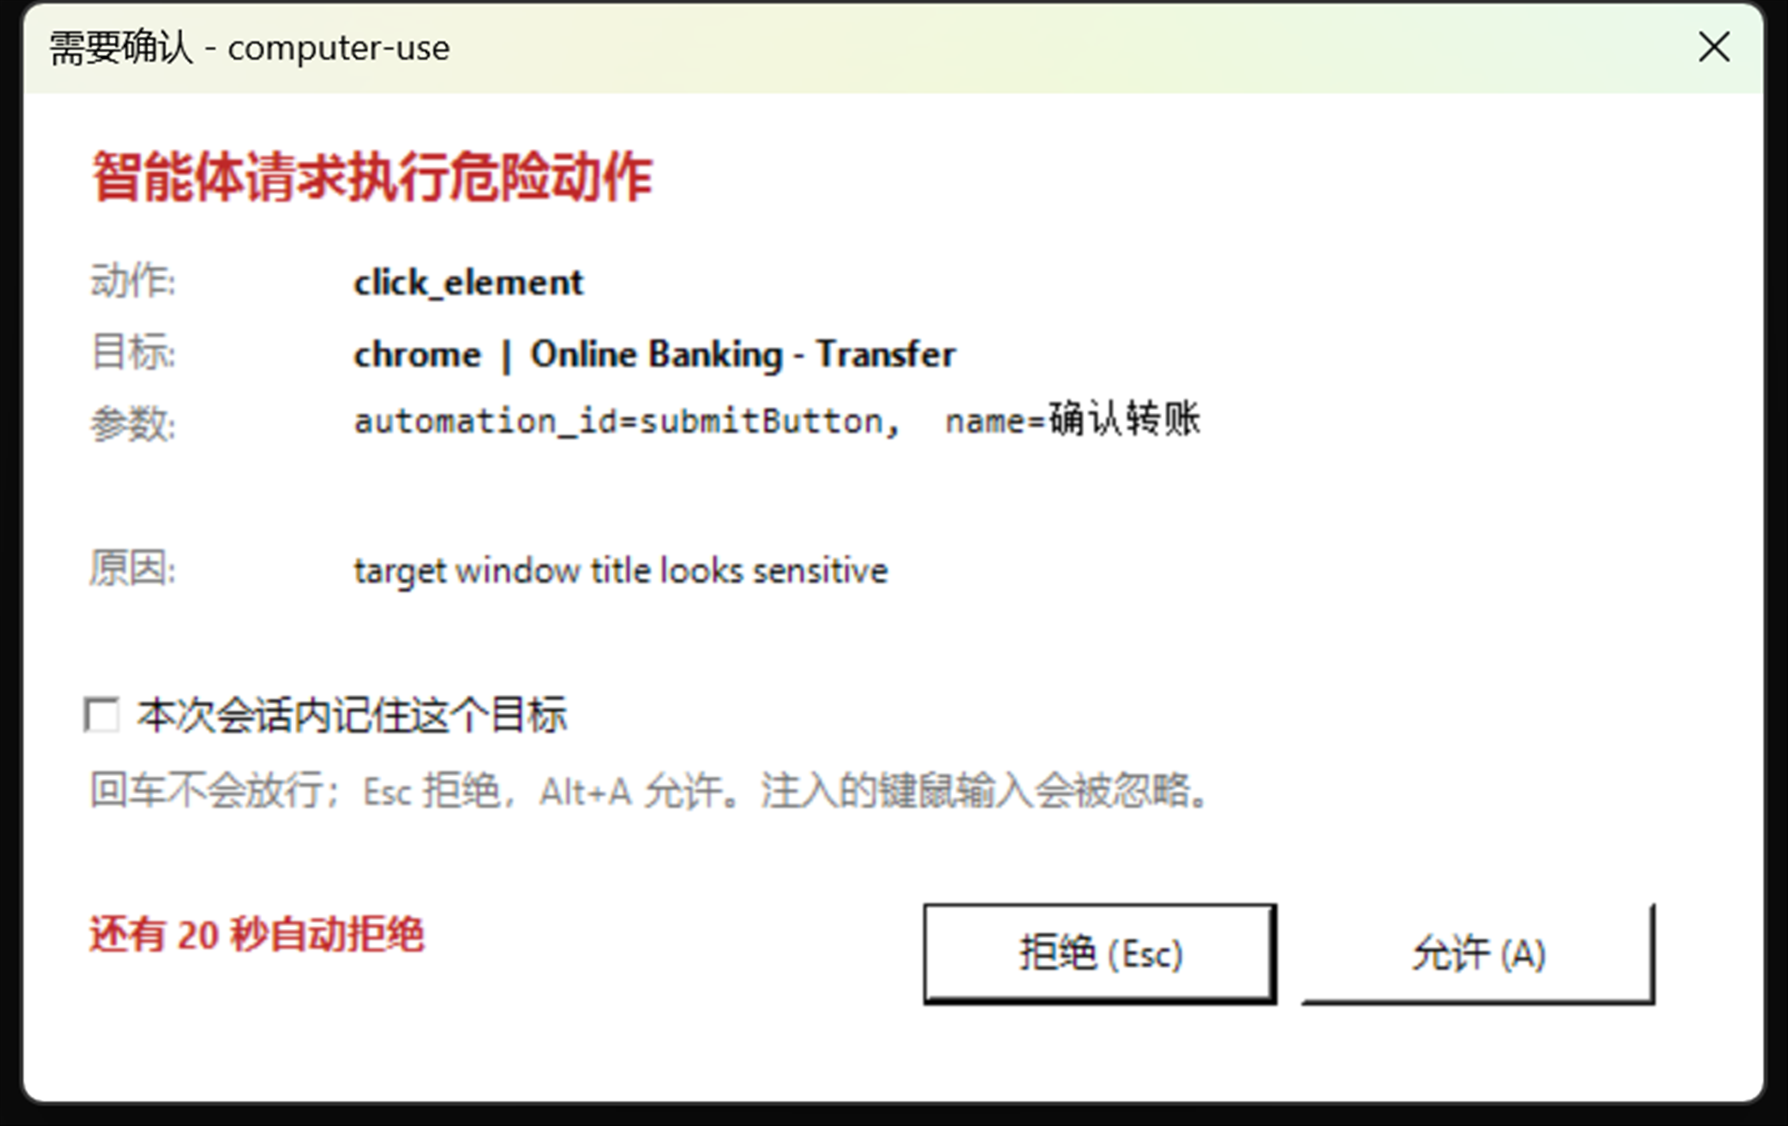
The MCP server blocks on that dialog and uses its exit code. Three
independent things stop the model from answering its own prompt:
- The gate lock — while a dialog is open, every input-injecting tool is
refused (refused_by_approval_gate), and the check runs again after everyawait(including insidebatch, whose step loop could otherwise resume
after a parallel call opened a dialog). MCP handlers are async, so without
this a parallel tool call (key("alt+a"),click(x, y)on Allow) would
answer the dialog. That was a real bypass; it is fixed and covered bynpm run test:injectandnpm run test:lock. - Only one dialog at a time — a second approval-requiring call is refused
rather than stacking a dialog, so the lock cannot lift while another prompt is
still unanswered. - The dialog wants a physical event — it installs low-level keyboard and
mouse hooks, discards every event carrying the Windowsinjectedflag, and
only accepts an allow from those hooks (a real Alt+A, or a real click inside
Allow).SendInputfrom any automation tool, a postedBM_CLICK/WM_KEYDOWN, and a UIAutomationInvokePatternall fail this test, and the
dialog says how many injected events it threw away.
{ "refused_by_approval_gate": true,
  "reason": "an approval dialog is waiting for a human decision — input-injecting tools are refused until it is answered" }
Built so a stray keystroke cannot approve anything:
| Key | Effect |
|---|---|
Enter |
nothing — deliberately unbound |
Esc / window close |
deny |
Alt+A / click Allow |
allow (physical input only) |
| no answer in time | auto-deny (countdown shown) |
The dialog also shows the actual arguments being executed
(automationId=…, name=…), follows your OS language (Chinese/English), beeps,
and stays on top. Tick remember this target for this session to stop being
asked about the same tool + target until the server restarts.
Exit codes: 0 allow once · 1 deny · 2 timeout · 3 dialog unavailable
(falls back to pending_safety_check) · 4 allow + remember for this session.
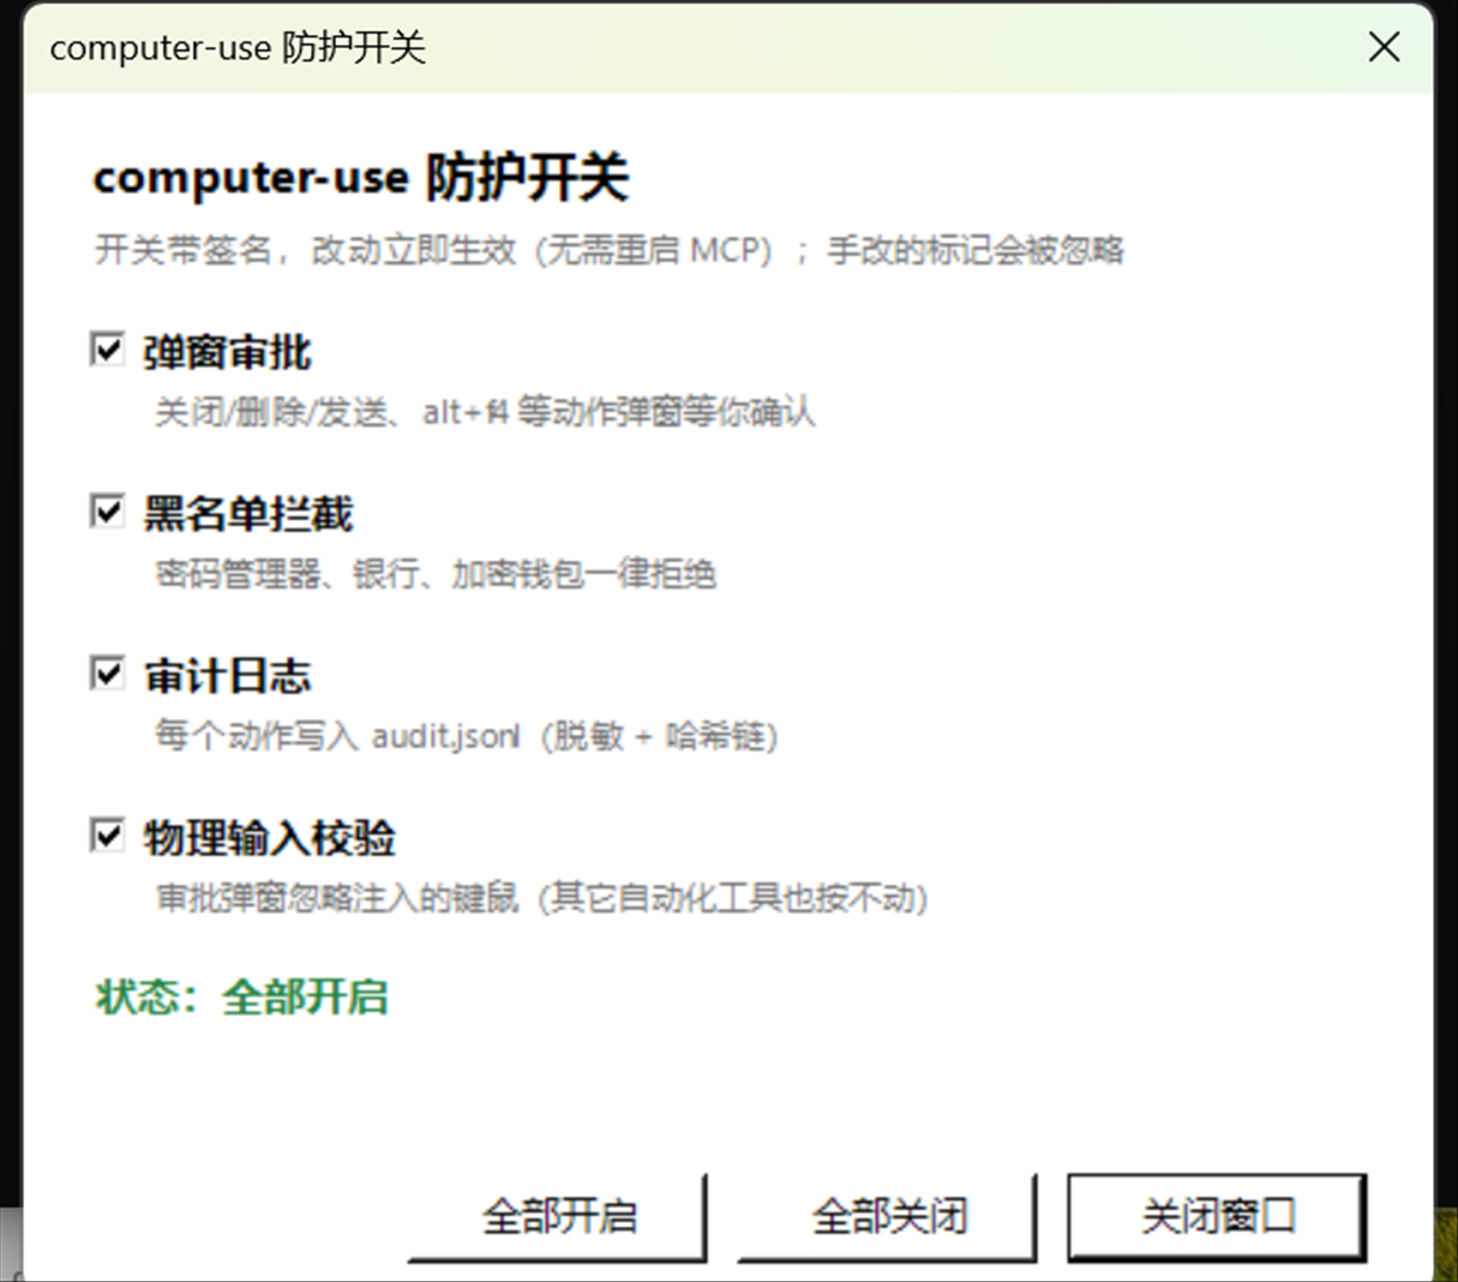
Flip it off any time when you don't want to be interrupted:
double-click  guard-panel.cmd      # the panel: four independent switches
double-click  toggle-approval.cmd  # quick toggle for the dialog only
Switches are HMAC-signed markers, and the server reads them on every
call — changes apply instantly, no restart:
| Switch | Marker file | Off means |
|---|---|---|
| Approval dialog | .approval-off |
risky actions return pending_safety_check instead of asking you |
| Deny lists | .guard-off |
the deny lists, the allow list and the rate limit are skipped |
| Audit log | .audit-off |
nothing is written to audit.jsonl |
| Physical input | .physical-off |
the dialog accepts injected keystrokes/clicks again |
They are independent: turning off the deny lists does not silently turn off
the dialog.
The markers are signed with guard.key (or COMPUTER_USE_GUARD_SECRET in the
launcher's environment). A marker that is unsigned or hand-edited is ignored —
the protection stays on — and the attempt is written to the audit log
(op=guard_tamper) and surfaced in the next tool result. Anything that can write
files in this directory can still read guard.key; see
SECURITY.md §4.2 for the honest version of what that means.
Layers of protection
| Layer | What it does | Can the model bypass it? |
|---|---|---|
Policy engine (policy.json) |
Refuses to touch deny-listed processes / window titles, and refuses shells/LOLBins as launch_app targets. Optional allow-list. Rate limit. Applies to every batch step too. |
The deny lists ignore confirm entirely. Editing policy.json widens them |
Approval gate (approval.ps1) |
Risky action → real dialog → waits for a human decision | Only a physical Alt+A / click counts. Not by confirm, not by injected input, not by posted messages (BM_CLICK), not by UIA InvokePattern, and not while another dialog is open |
Gate lock (src/approval.js) |
Refuses input-injecting tools while a dialog is open, re-checked after every await (including inside batch) |
No — it is server-side state |
Signed switches (src/guard.js) |
Forged, hand-edited or replayed markers are ignored and reported | Cannot be forged or replayed without the key; guard.key is readable by your user, and the accepted-marker watermark can be rolled back by whoever can write it |
Audit log (audit.jsonl) |
Every action + its target process, redacted, hash-chained, with a chain head recording how far the segment got | Detects edits, deletions, truncation and hash-stripping (npm run audit:verify); a determined writer can still rewrite log and head together |
Target resolution uses WindowFromPoint — which window a click actually
lands on, not the foreground window. Actions with no coordinates (click,scroll at the cursor) resolve the real cursor position instead of falling back
to the foreground window, and a drag is checked at both ends:
{ "blocked_by_policy": true, "reason": "target process is on the deny list",
  "detail": { "process": "ApplicationFrameHost", "title": "计算器",
              "matched": "applicationframehost" } }
What is on the lists
Four lists, all substring matches (case-insensitive), all in policy.json:
| List | Behaviour | Default coverage |
|---|---|---|
deny_processes (49) |
hard refusal, no override | password managers, crypto wallets, regedit/diskmgmt/diskpart/gpedit |
deny_window_titles (31) |
hard refusal | password, bank, pay, wallet, 转账, 验证码, seed phrase, UAC |
approval_processes (32) |
every action pops the dialog | messaging (WeChat/QQ/Telegram/Slack…), mail, remote desktop (RDP/TeamViewer/AnyDesk…) |
approval_window_titles (8) |
every action pops the dialog | send, 发送, remote desktop |
The split matters: a messaging app is not denied outright — you may want the
agent to read or summarise it — but nothing is clicked there without you saying
yes.
npm run test:policy checks the lists against 29 samples and fails on false
positives (a browser, Notepad, Blender and this repo's own harness must all pass
cleanly).
Install
Requirements: Windows 10/11, Node.js ≥ 18.
git clone https://github.com/be1st6666/guarded-computer-use-mcp
cd guarded-computer-use-mcp
npm install
Optional but recommended: PowerShell 7 (better UTF-8 and JSON handling).
The server falls back to Windows PowerShell 5.1 automatically.
Optional: OCR needs uv on PATH. Everything
else works without it.
Verify it works
npm test              # read-only tools; no side effects, safe to run any time
npm run test:unit     # unit tests for the policy/guard/audit/approval core
npm run test:smoke    # MCP handshake + tool schemas, no desktop needed
npm run test:policy   # the deny/approval lists, 29 samples
npm run test:typing   # type_text round-trip in its own temp Notepad window (skips if Notepad is open)
npm run test:inject   # shows the real dialog and proves injected input cannot answer it
npm run test:lock     # protocol-level: parallel tool calls cannot answer the dialog
npm run verify        # everything that does not need an interactive desktop
npm test prints a tick per tool plus its latency. If it lists tools andscreenshot returns an image, the server is wired up correctly.npm run test:inject and npm run test:lock take over your screen for a few
seconds (they open the real dialog) and must both end with all checks passed.
Configure your MCP client
Claude Desktop / Cursor / any stdio MCP client{
"mcpServers": {
"computer": {
"command": "node",
"args": ["D:/path/to/guarded-computer-use-mcp/server.js"]
}
}
}
Add to $DSH_HOME/profiles/web/cordis.patch.yml:
- insert:
    - id: mcp-computer-use
      name: '@deepseek-ai/dsh-mcp-client'
      config:
        serverName: computer
        transport: stdio
        command: C:/Program Files/nodejs/node.exe
        args:
          - D:/path/to/guarded-computer-use-mcp/server.js
Tools appear as mcp__computer__<name>.
Performance
Measured on a 2560×1600 display, median of 5–8 runs:
| Operation | Latency | Tokens returned |
|---|---|---|
cursor_position / active_window |
1 ms | 7–39 |
ui_tree |
12 ms | 38 |
zoom region 480×150 |
25 ms | 96 |
screen_hash |
44 ms | 9 |
screenshot 900×562 |
58 ms | 674 |
screenshot 1600×1000 |
116 ms | 2133 |
batch (3 steps + screenshot) |
134 ms, one round trip | 674 |
find_elements |
209 ms | 640 |
ocr (warm worker) |
457 ms | 554 |
The ~55 ms capture floor is the GPU→CPU readback of a full frame over GDI.
OCR latency scales with the number of recognised text boxes, not with the
capture rectangle: a text-heavy full 2560×1600 screen measured ~6.9 s / 105
boxes, while a 1280×800 region measured ~3.3 s / 45 boxes (~2×). Downscaling
the image first does not help — RapidOCR's detector normalises its input to a
fixed size internally, so pre-scaling costs accuracy for almost no time — and a
larger recognition batch is slower, not faster. So pass a region
(x/y/width/height) instead of OCRing the whole screen whenever you do not
need all of it.
Token economics
A screenshot costs ~2133 tokens. The alternatives cost far less:
| Instead of a full screenshot | Tokens | Saving |
|---|---|---|
screen_hash — "did anything change?" |
9 | 237× |
zoom — only the region you need |
96 | 22× |
find_elements — text, not pixels |
640 | 3.3× |
batch also collapses N actions into one model turn, which is the bigger
win: a model turn costs 2–10 s of inference, a tool call costs 1–457 ms.
Three-tier targeting
Coordinates fail silently when a window moves. So try in order:
find_elements/click_element— UI Automation. Clicks by name viaInvokePattern(no mouse movement at all). Either finds the element or says
it isn't there.ocr— no control tree, but there is text. RapidOCR (PaddleOCR models on
ONNXRuntime, ~14 MB) reads it and returns screen-space boxes, so a recognised
word can be clicked directly.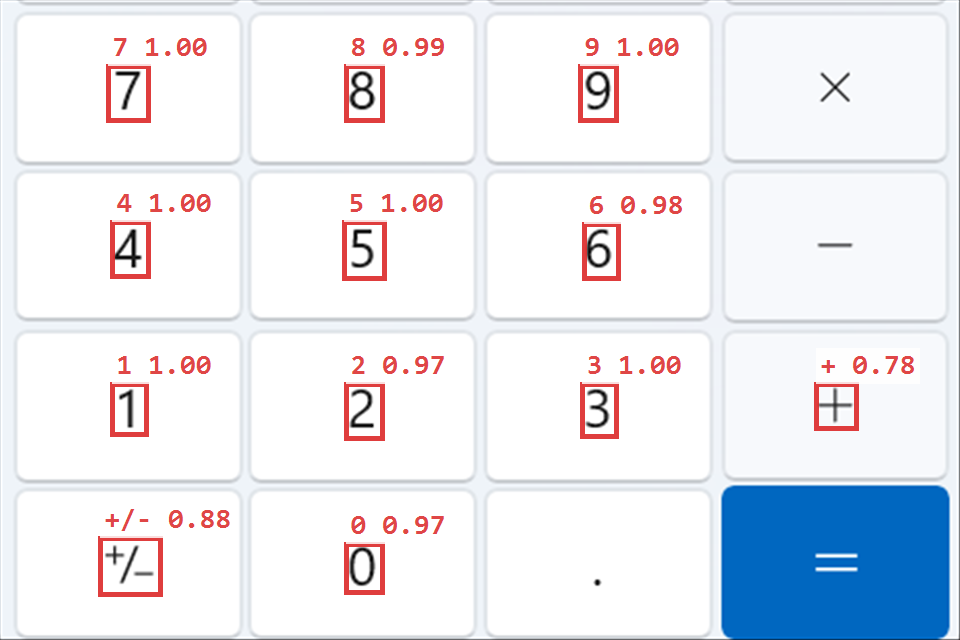
Real output against the Windows Calculator: every digit located with a
confidence score. The built-in Windows OCR engine returns zero words for
this same region.screenshot+ coordinates — last resort for canvas/self-drawn UI.
What the accessibility tree actually covers. It is easy to assume browsers
expose nothing and reach for pixels too early. In practice Edge/Chromium does
publish the page: a single find_elements on a 4399.com game index returned 22
hyperlinks with exact rects, including ones thousands of pixels offscreen — all
clickable by name with no mouse movement.
What it still cannot see:
| Accessible? | |
|---|---|
| Static HTML links/buttons/inputs | yes |
| Native Win32 / WPF / UIA apps | yes |
canvas / WebGL / game frames |
no |
| Virtualised lists not yet mounted | no |
| Custom-drawn toolbars (many Chinese desktop apps) | no |
When it is not, ocr and then plain coordinates are the fallbacks — in that
order.
Measured on the same task (click a button):
| Method | Latency | Tokens | Reliability |
|---|---|---|---|
| screenshot + vision + click | 116 ms | 2133+ | medium |
| UIA semantic | 309 ms | ~700 | high |
| OCR + click | 459 ms | 554 | medium-high |
Tools (26)
| Group | Tools |
|---|---|
| Observe | screenshot zoom screen_hash wait_for_change cursor_position list_displays list_windows active_window clipboard_read |
| Semantic | find_elements click_element ui_tree |
| OCR | ocr |
| Mouse | mouse_move click drag scroll |
| Keyboard | type_text key hold_key |
| Window / launch | activate_window launch_app |
| Orchestration | batch wait |
| Other | clipboard_write bench |
Coordinates are physical pixels of the virtual desktop. type_text injects
Unicode per character via SendInput, so CJK, quotes and emoji go through
verbatim with no escaping anywhere in the path.
Event-driven, not a video stream
Codex-style computer use is not a continuous stream either — it is
act → screenshot → decide. Three primitives make that loop cheap:
screen_hash— 64×40 perceptual fingerprint, 44 ms, 9 tokenswait_for_change— blocks until the screen actually changes; no polling
from the model, no wasted turnsbatch—[click, wait, screenshot]in one call, one round trip
Architecture
MCP client
   │  stdio, JSON-RPC
   ▼
server.js ──── one base64(UTF-8 JSON) line per request ────▶ host.ps1 (resident)
   ▲                                                              │
   └─────────── one base64(UTF-8 JSON) line per reply ◀──────────┘
                                                                  │
                                                    C# class Dsh (compiled once)
                                                                  │
                                              StretchBlt / SendInput / UIAutomation
| File | Role |
|---|---|
server.js |
MCP server, 26 tools, policy + approval + audit |
host.ps1 |
Resident PowerShell host + C# helper (must stay pure ASCII) |
approval.ps1 |
The approval dialog |
ocr.ps1 |
Windows OCR backend (Windows PowerShell 5.1 only — .NET Core has no WinRT projection) |
ocr_rapid.py |
RapidOCR backend, one-shot or --serve (warm worker, idle-exits) |
policy.json |
Deny lists, rate limit, approval settings |
test-client.js |
Standalone test client (read, uia, advanced, policy, rapid, …) |
bench.js |
Per-op latency and token benchmark |
Design notes:
- Resident host, compiled once. The C# helper is
Add-Typed at startup, so
a call costs 1–12 ms instead of 300–500 ms. StretchBltcapture + downscale in one GDI call. Capture-then-resample
spent 57 ms just on resampling — more than encoding.- JPEG by default. PNG encode of 1600×1000 costs 19–33 ms; JPEG q88 costs
4–8 ms and is half the size. - base64 transport. Every line on the wire is ASCII, sidestepping Windows
PowerShell 5.1 console-encoding entirely.
Safety model in depth
What it protects against
- The model deciding on its own to touch a password manager, banking or payment
window → refused by policy, no override. - A destructive click (
关闭/Close/Delete/Send) or key chord
(alt+f4,ctrl+w,win+*,shift+delete) → approval dialog. - The model answering its own approval dialog — a parallel tool call can no
longer injectalt+aor click Allow: input tools are locked out while the
dialog is open, and the dialog discards injected input entirely. batchskipping the deny lists — every step is now policy-checked and
audited individually.- Turning the guards off with a stray file — switches are signed; a forged or
hand-edited marker is ignored and reported asguard_tamper. - Runaway loops →
max_actions_per_minute. - "What did it actually do?" →
audit.jsonlwith the target process per action,
sensitive argument values redacted, and a hash chain that makes quiet edits
detectable (npm run audit:verify).
What it does not protect against
- A mis-click in an app that is not on a deny list. If the model clicks the
wrong thing in Notepad, nothing stops it. - A second desktop-control server, or any other local process, that can write
files as you: it can replaceguard.key, roll backguard.state.json/audit.head.json, widenpolicy.json, or runhost.ps1directly. It cannot
answer the dialog — that needs a physical event — but it does not have to.
See SECURITY.md §4.1. - Same-user file access:
policy.json,guard.keyandhost.ps1are all
reachable by anything running as you. - It is not a sandbox. The agent runs with your user's privileges on your
real desktop. There is no VM. "Control the real machine" and "full isolation"
are architecturally mutually exclusive — Codex's sandbox works because it
drives a desktop inside a VM, not yours. - Elevated windows: UIPI blocks input injection into admin windows, and the UAC
secure desktop is unreachable. This is a Windows boundary, not a feature.
Risks and disclaimer
What can go wrong
This is not a toy permission. An agent driving this server can:
- send a message, email or payment as you
- delete or overwrite files it was never asked to touch
- read whatever is on your screen, including other people's private data
- change application or system settings
There is no undo. Ctrl+Z does not cover "sent", "paid" or "deleted".
Prompt injection
The agent reads your screen and the documents on it. Anything it reads can carry
instructions: a web page, a PDF, an email, a chat message, a code comment. A
hostile page can tell the agent to do something you never asked for.
The approval gate catches actions matching the safety patterns and the approval
lists. It does not catch a plausible-looking click in an app that is on
neither list. Treat everything the agent reads as untrusted input.
Your screen leaves your machine
Screenshots, OCR output, clipboard contents and window titles are sent to
whichever model provider your MCP client uses. That is the whole point — the
model has to see the screen — but it means:
- everything visible while the agent runs is transmitted off-device
- that includes other people's messages, documents and personal data
- check your provider's data-retention policy before pointing this at anything
sensitive - prefer
zoomon a small region over a full screenshot when you can
OCR runs locally and sends nothing itself, but its output is returned to the
model, so it is transmitted too.
What the guard does not do
- It is not a sandbox. The agent runs as you, on your desktop, with your
sessions and tokens. - It does not stop a wrong action in an app that is on neither list.
- It does not survive anyone who can also edit
policy.jsonor create the.guard-offmarker — those are plain files in this directory. - The deny lists are substring matches: a speed bump, not a boundary.
You are responsible
You choose what to point this at, which lists to keep enabled, and whether to
leave the approval gate on. Run it with the gate on until you have watched it
work on your own machine. Do not expose the stdio transport to a network.
Provided under the MIT licence, without warranty of any kind — see
LICENSE. The authors are not liable for any loss or damage arising
from its use.
Known limits
- Windows only.
- ~55 ms per full screenshot — the GDI readback floor. A DXGI Desktop
Duplication backend could cut it, at the cost of a native addon. - No continuous vision. By design; see the event-driven section.
- OCR costs ~0.5–2.5 s depending on whether the warm worker is alive.
type_textneeds focus —activate_window+clickfirst.- The dialog needs a physical decision. If
alt+aon the keyboard or a click
on Allow does not approve it, the injected-input filter is not seeing your
hardware as physical — runnode src/guard.js set physical off(or untick
物理输入校验 in the panel) to fall back to ordinary button clicks, and please
report it. - Anything that can write files as you can still win. It can replace
guard.key, roll backguard.state.json/audit.head.json, editpolicy.json, or runhost.ps1directly. The signing, the watermark and the
chain head raise the bar and leave a trail; they are not a boundary. - The audit chain is tamper-evident, not tamper-proof.
verifycatches edits,
a deleted tail, a missing file and stripped hashes against the chain head; a
writer who rewrites the log and the head together is not detected.
Development
npm run verify                # lint + unit + policy + smoke + audit chain check
npm run test:unit             # unit tests: guard, audit, policy, approval lock
npm run test:smoke            # MCP handshake + tool schema smoke test (headless-safe)
npm run test:inject           # real dialog + injected Alt+A / click (needs a desktop)
npm run test:lock             # protocol-level gate-lock regression (needs a desktop)
npm test                      # read-only tools, no side effects
npm run test:uia              # accessibility tree + semantic search
npm run test:policy           # deny/approval lists, 29 samples, fails on false positives
npm run test:typing           # activate_window focus + multi-line/tab type_text
npm run bench                 # latency + token table
npm run audit:verify          # walk the audit hash chain, report edited/deleted records
npm run guard                 # print the four protection switches
node src/guard.js set guard off   # what the panel does under the hood (signed marker)
node test-client.js policy    # policy + audit behaviour end to end
node test-client.js rapid     # Windows OCR vs RapidOCR on the same region
node test-client.js newtools  # launch_app, approval gate, OCR-driven click
src/ holds the safety core as separate, unit-testable modules — guard.js
(signed switches), audit.js (redaction + hash chain + rotation), policy.js
(lists, rate limit, approval decision), approval.js (dialog + gate lock).server.js is the MCP wiring and the tool definitions.
test/ is the headless suite CI runs (unit tests + the MCP smoke test);e2e/ holds the two scripts that drive the real desktop (approval injection and
the protocol-level gate-lock regression).
docs/make-*.ps1 regenerate the README figures from a live screen, so the
screenshots can be kept honest rather than hand-drawn.
host.ps1 and ocr.ps1 must stay pure ASCII: Windows PowerShell 5.1 reads.ps1 as ANSI when there is no BOM, and a single non-ASCII byte can swallow a
newline and corrupt the embedded C#. Verify with:
((Get-Content .\host.ps1 -AsByteStream) | Where-Object { $_ -gt 127 }).Count # must be 0
approval.ps1, approval-toggle.ps1 and guard-panel.ps1 are the exception:
they show Chinese to the user, so they are saved with a UTF-8 BOM, which
both shells honour.
Contributing
Issues and PRs welcome. Three rules keep this repo reviewable:
- No third-party automation code. The whole point is that every line that
touches your machine can be read in one sitting.host.ps1is C# + Win32 and
nothing else. - Measure, don't claim. If you change something for speed, put a number in
the PR —npm run benchexists for that. - A security fix needs a test that fails without it.
npm run test:inject
andtest/*.test.mjsare the examples;npm run verifymust stay green.
Security-relevant behaviour is documented in SECURITY.md — if you
change what a guard does, change that file in the same PR.
License
MIT — see LICENSE.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found