roost
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Spec-driven development that doesn't stop at the code: coding agents take an idea to release, and you make the calls.
roost

Spec-driven development that doesn't stop at the code.
roost takes a product idea all the way to production. It shapes the epic, builds it slice by slice with one coding-agent session per repo, reviews the whole epic, QAs it in a real browser, and walks you through the rollout one command at a time.
- The whole cycle, not just the build. Most spec-driven kits hand off once the code is written. roost carries on through review, close-out, release QA and the rollout.
- You make the calls. Agents do the work and stop at named checkpoints: the plan, each slice's findings, what's deferred, and each rollout gate. You run every rollout command yourself.
- Nothing lives only in a chat. Plans, kickoffs, carry-over and test results go in your tracker, so any run can be picked up where it left off.
- One agent per repo. An orchestrator session drives a worker session in each repo, in order, against your real local stack.
- Its behavior is tested. Eval cases check what the skills do, run with and without roost.
roost is a set of skills, not an agent: it hosts nothing and runs inside your coding agent. It's opinionated about how the work goes: test-first, small PRs on a stack, your decisions at named checkpoints, nothing left only in a chat, and a rollout runbook you run yourself. It's open about which tools you use: your tracker, test tool, repos, local stack, branching and deploy rules come from one team config file, and each tool plugs in through an adapter. Today roost runs fully in Claude Code with Jira, Xray and gh stack on GitHub. Other trackers, test tools, git hosts and coding agents are on the roadmap.
Brought to you by Beakpoint. Beakpoint built roost and uses it every day to build its own product. Winston, the bird at the top of this page, is Beakpoint's mascot.
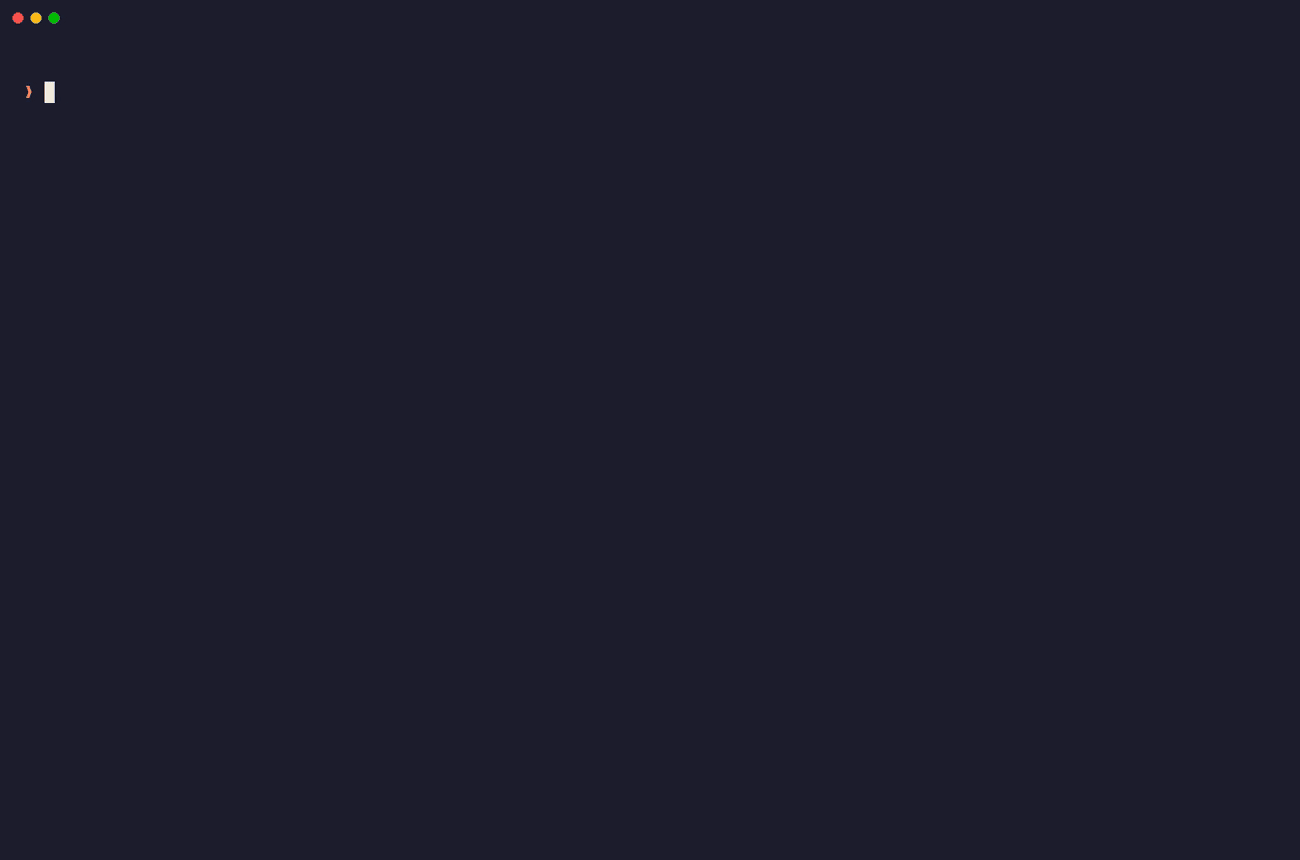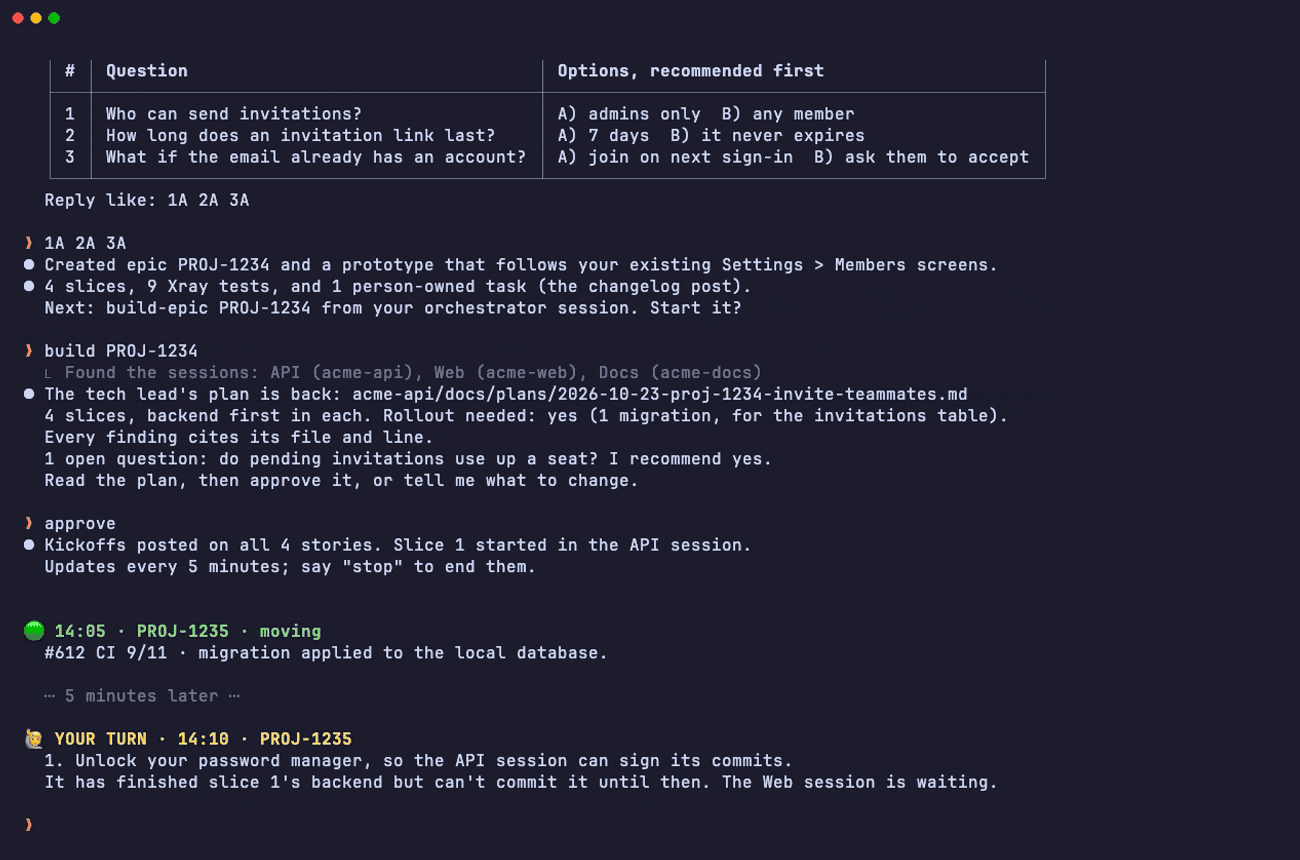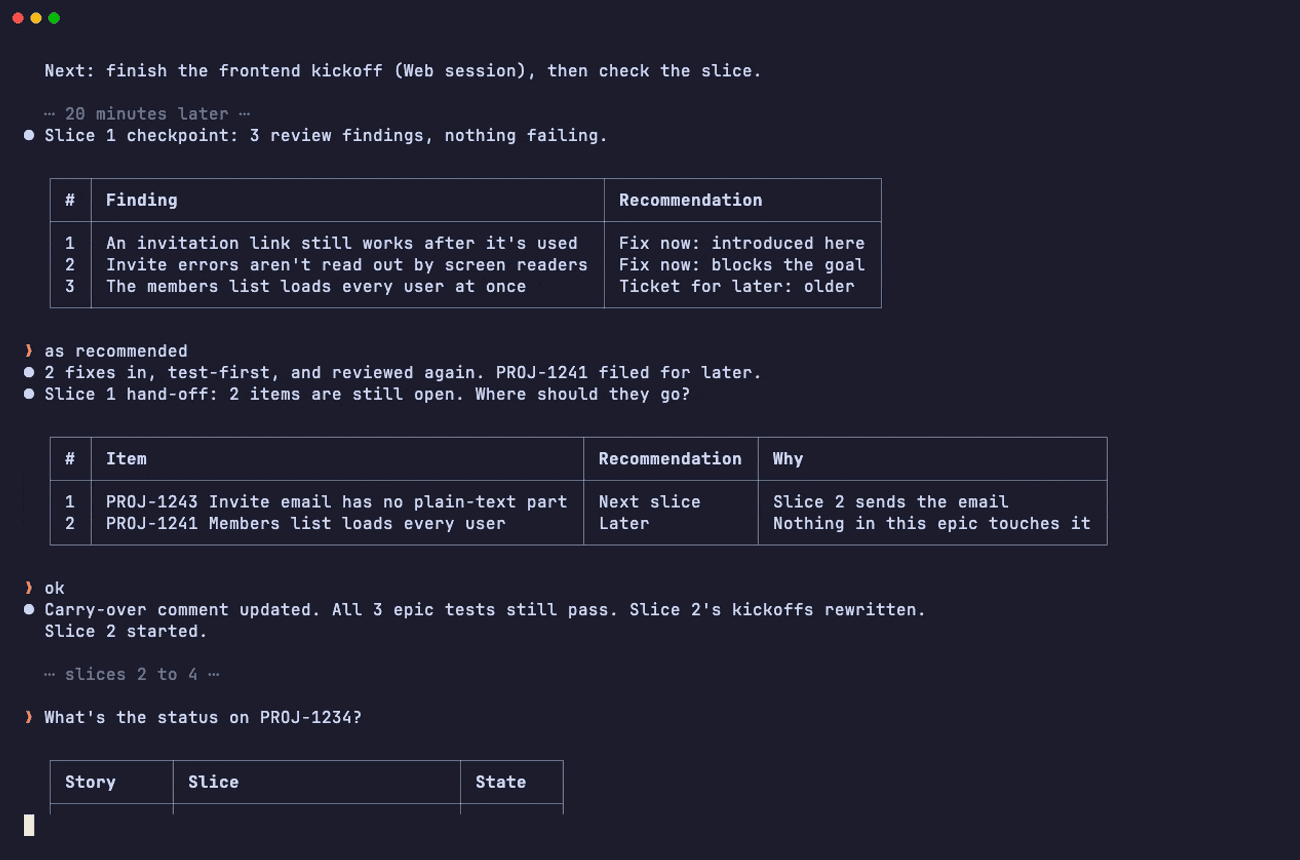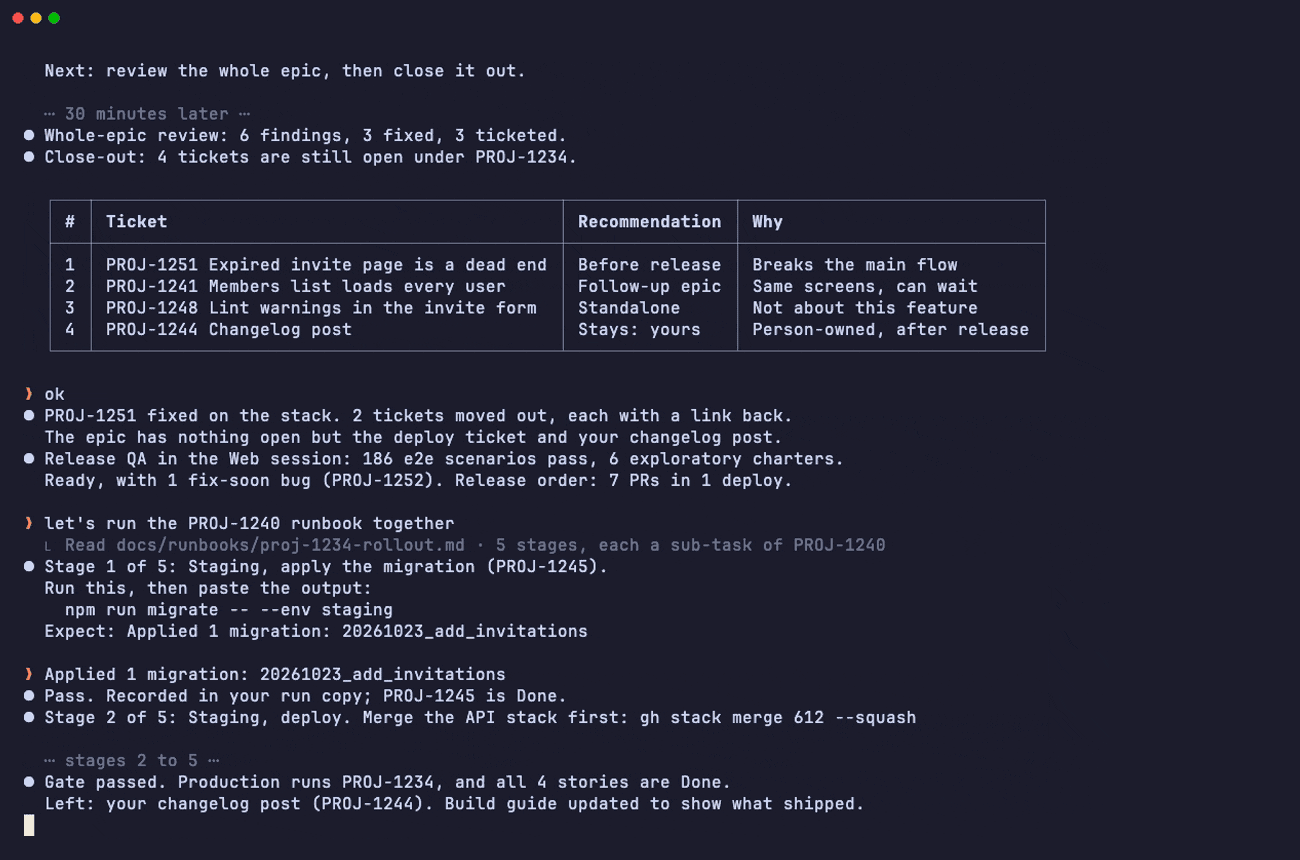
A made-up session, sped up. Re-record it with VHS and gifsicle: vhs demo/roost.tape && gifsicle -b -O3 --colors 64 --lossy=30 demo/roost.gif.
What you need
roost runs fully today with:
- Claude Code, with a session open for each repo. Most skills also work in Cursor.
- A tracker: Jira, through the Atlassian MCP, or GitHub Issues, through the
ghCLI. - Tests: Xray test cases (Cucumber scenarios), or eval cases in the repo for a Claude Code plugin.
- GitHub, with the
ghCLI, and itsgh stackextension if you stack PRs. - For an app: Playwright MCP, for checking prototypes and testing in a real browser, and a local stack you can start with a command (Aspire, Docker Compose or your own scripts). A plugin or a library needs neither.
Each skill needs only part of this; What each skill needs has the details. Not on Jira or GitHub? The roadmap shows what's coming.
Install
/plugin marketplace add Beakpoint-Insights/roost
/plugin install roost@roost
Skills are then available as roost:<skill>, for example roost:shape-epic.
Configure it for your team
Every skill reads one team config before it does anything. Run:
/roost:setup
It links your team's shared config if you have one, or asks about your tracker, repos, local stack, branching and deploy rules and writes one. examples/config.example.yml is a complete example, and skills/roost-config/references/config-schema.md says what every key means.
roost looks for the config in this order: a path you name, $ROOST_CONFIG, .roost/config.yml in the current repo, then ~/.claude/roost/config.yml. To work for more than one team on one machine, start each session with ROOST_CONFIG=<that team's config> claude: orchestrators run outside the repos, so they never see a repo's .roost/config.yml. They record the config they started with and stop if a resumed run loads a different one. Most teams keep one config in a private repo, next to any skills of their own, and link it into ~/.claude/roost/config.yml on each machine so git pull keeps everyone in step.
A machine that differs from the rest (its own database, other ports) keeps just those values in ~/.claude/roost/local/<team.name>.yml, which overrides that team's shared config on that machine only.
The config never holds secrets: it names where a secret comes from, never its value.
What's supported
| Area | Config key | Supported now | Planned |
|---|---|---|---|
| Tracker | tracker.kind |
Jira (Atlassian MCP), GitHub Issues (gh) |
Linear |
| Test management | tests.kind |
Xray (Cucumber scenarios), eval cases in the repo | Gherkin files in the repo |
| Branching | vcs.stacking |
gh stack, plain PRs |
Graphite |
| Git host | vcs.host |
GitHub | GitLab |
| Coding agent | Claude Code. Most skills also work in Cursor (see Using roost in Cursor) | Cursor in full, Codex, GitHub Copilot, Gemini CLI | |
| Repos | repos |
Any number, each with its own agent session, in an order you set | |
| Local stack | stack |
Anything you run locally (Aspire, Docker Compose, scripts): you give its commands and URLs. Optional, like deploy, design and qa: leave out what you don't have |
Each supported tool has an adapter: notes in skills/roost-config/references/ that say how to do each operation in that tool. Adding a tracker or test tool means adding an adapter file and a row here. The work to support more tools is grouped in three milestones: Works without Jira, Works without gh stack and Works outside Claude Code.
From idea to release: the happy path
This is how one epic usually goes through roost. The example team has two repos in its config, a backend and a frontend, so it runs three Claude Code sessions on one machine, each with roost installed:
- the API session, opened in the backend repo;
- the UI session, opened in the frontend repo;
- the orchestrator, a third session opened anywhere. It never edits a repo; it sends the work to the other two and brings their results back to you.
A team with one repo has one worker session; a team with three has three. The made-up epic is PROJ-1234, "New customers can send data minutes after signing up".
1. Shape the epic
In any session:
/roost:shape-epicNew customers should be able to send data within minutes of signing up.
shape-epic works through seven phases: problem, epic, design, slices, tests, build guide and handoff. It asks you about the problem first, and checks with you as each phase finishes. If your config has a roadmap, it asks whether the epic goes on it. At the end, PROJ-1234 has:
- a description with the problem, goals and scope;
- a prototype built from your design system;
- ordered stories, one per slice, each small enough to ship on its own;
- the tests for each story, in your test tool;
- a build guide and a tech lead prompt, attached to the epic.
2. Plan the build
In the orchestrator:
Build PROJ-1234.
build-epic starts without asking. The stories have no kickoff comments yet, so it plans first:
- It sends the epic's tech lead prompt to the lead repo's session, which writes the implementation plan on a new
gh stack. - You approve the plan, or ask for changes. The plan ends with Rollout needed: yes or no: yes when merging and deploying isn't enough on its own (a migration, a backfill, a feature flag, setup in an outside service).
- The lead session posts a kickoff comment for each repo on each story, which the build runs from, and a Release order comment on the epic. If a rollout is needed, it also creates the epic's deploy ticket and runs
write-runbook, so each stage of the runbook becomes a sub-task of that ticket, with the same number and name.
3. Build the slices
build-epic then builds each story in order with run-slice:
- Each repo's session builds its part from its kickoff comment, in the config's order. The stack's owner starts the local stack between them, so a later repo builds against the earlier one's real work.
- The session with the e2e suite checks the story's tests with
verify-slice-tests, and every session runs/code-reviewon its stack. - Checkpoint: you get one list of test results and review findings, each with a recommendation (fix now, ticket for later, or skip), and you decide.
- The sessions fix the "fix now" items test-first, and the e2e session tests the slice by hand in a real browser. Any bugs it finds come back to you the same way.
slice-handoffsorts what's left over into the next slice, before release, or later (you confirm the sorting), runs every test in the epic so far, and rewrites the next story's kickoff comments to match what was actually built.
Then the next story starts, with no need to ask. Each repo's part of each slice, and each bug fix, is its own PR on the epic's stack, and the Release order comment lists every PR in the order to merge. A migration added along the way goes on the deploy ticket too.
4. Get it ready to release
After the last slice, build-epic carries on:
- The "before release" items are fixed (bugs through
run-bugandbug-bash), and every test in the epic runs once more. review-epichas every session review the whole epic againstmain, plus a security review of the server code, looking hardest at code no slice review saw. You decide each finding.close-out-epicgives every open ticket a place: fixed before release, moved to a follow-up epic, or standalone. You confirm the places. Once the release ships, it checks production runs the epic and offers to draft its release note.- The e2e session runs
release-qa: the full e2e run, exploratory testing, and a release call.
5. Ship
roost doesn't merge or deploy for you, but it runs the rollout with you. Ask "let's run the PROJ-1234 runbook together" and pair-runbook takes you through the deploy ticket's runbook one step at a time: it gives you the command and what to expect, you run it and paste the output, and it checks the result, fills in the run's record and closes the step's sub-task. It stops at each stage's gate for your go-ahead. Merging the stacks is one of the runbook's steps (stacked-prs helps with conflicts).
Where you come in
The skills start work without asking and stop only for your decisions:
- answering
shape-epic's questions and approving the tech lead's plan; - each slice's checkpoint, and each handoff's sorting;
- the
review-epicfindings and theclose-out-epicplaces; - each command of the rollout, which you run yourself, and each stage's gate;
- anything only you can do, such as unlocking commit signing or answering a permission prompt in one of the sessions. Those are listed first, under 🙋 Your turn.
At any point, ask the orchestrator "where are we on PROJ-1234?" for a status table. A bug found later, in this epic or anywhere else, goes to "fix PROJ-5678", which runs run-bug.
Skills
The skills are grouped by where they fit in the development cycle, in order.
0. Setup
| Skill | What it does |
|---|---|
setup |
Links your team's config, or makes one by asking about your tracker, repos, stack, branching and deploy rules, then checks it |
roost-config |
Loads the team config and the adapter notes for its tools. Every other skill uses it first; you don't call it yourself |
1. Requirements and design
| Skill | What it does |
|---|---|
shape-epic |
Shapes an idea into a buildable epic: problem statement, design (a UI prototype, an architecture PR, or both), slices, tests, build guide, and a tech lead prompt attached to the epic |
2. Test design
| Skill | What it does |
|---|---|
live-verified-bdd |
Writes Cucumber scenarios and checks them against the running app with Playwright before they're finalized |
create-xray-test |
For teams on Xray: files Cucumber scenarios into new or existing Xray Test issues, with the parent epic, Components and story link. shape-epic and live-verified-bdd hand off to it |
3. Engineering
| Skill | What it does |
|---|---|
build-epic |
Builds an epic through the repo sessions: has the lead session plan it from the tech lead prompt (you approve the plan) and post the kickoffs, then runs every slice in order with slice-handoff between them, then the before-release work and release-qa. Starts and keeps going without asking; stops only for your decisions and real blockers |
run-slice |
Drives one slice from kickoff to done through the repo sessions: kickoff prompts, the local stack, test checks, code review, fixes and exploratory testing, stopping for your decisions |
slice-handoff |
Closes out a finished slice before the next starts: sorts its carried-over work, runs every test in the epic so far, rewrites the next slice's kickoffs, and checks every stack |
run-bug |
Fixes one or more bugs through the repo sessions: triages each, assigns it to you, puts the fix on the epic's stack or on its own PR from main, builds each repo's part in order, and checks the test, the test scenario and CI. Starts without asking |
review-epic |
Before release, has every session run a whole-epic /code-review at high effort against main (plus /security-review on the server code), marks code that was never reviewed, and brings the findings to one checkpoint |
close-out-epic |
Before an epic is released, gives every open ticket a place (fix before release, the epic's follow-up epic, or standalone), moves the deferred ones out with a link back, and after the release checks every ticket ended done |
stacked-prs |
Puts branches and PRs on the right gh stack, with the "Stacked on" banner, and fixes conflicts on the one branch that has them |
cross-repo-handoff |
Writes a prompt another repo's agent can run cold, posted as a comment on the ticket |
triage-ticket |
Decides whether a finding in the tracker is accurate and needs fixing, then fixes it test-first if asked |
bug-bash |
Fixes a list of bugs in one repo, one branch each, test-first, moving each ticket through the tracker; hands off work that needs another repo |
4. Test automation and verification
| Skill | What it does |
|---|---|
automate-tests |
Writes the missing automation for a story's tests, then marks the fully passing ones automated (automate-xray-tests still works as its old name) |
verify-slice-tests |
After a slice is pushed, proves which of its story's tests are automated and passing, marks those, and proposes splits |
5. Release and operations
| Skill | What it does |
|---|---|
release-qa |
QA for an epic before release: e2e run with every failure sorted, exploratory testing, bugs filed, and a release call |
write-runbook |
Writes a recordable, gated runbook with literal commands, kept one to one with the rollout ticket's sub-tasks (one per stage, same number and name) |
pair-runbook |
Runs a rollout runbook with you one step at a time: gives the next command, you run it and paste the output, it checks the output, fills in the run's record and updates the step's sub-task. Never runs a rollout command itself |
release-notes |
Drafts a shipped epic's customer-facing release note, ready to paste: dated by when production first carried it, with the evidence in a table, written from what the slices built, and with anything the evidence doesn't give left for you to fill in. Never publishes |
What each skill needs
Every skill needs the team config. Install fails quietly if a skill's tools aren't there, so check this first. Two terms in the table:
- Tracker access: for Jira, the Atlassian MCP and a Jira API token (
JIRA_EMAIL,JIRA_API_TOKEN), or else Playwright MCP with a signed-in Jira session; for GitHub Issues, theghCLI, signed in. - Test access: for Xray,
XRAY_CLIENT_IDandXRAY_CLIENT_SECRET, or else Playwright MCP with a signed-in Jira session; for eval cases,claude plugin eval.
| Skill | Needs |
|---|---|
shape-epic |
Tracker access, test access, Playwright MCP to check a prototype, the tools that read your design system (for Claude Design, its Design tools), and the plan skill your config names (for example the superpowers plugin). Publishing the build guide needs claude.ai artifacts, so run it in Claude Code |
live-verified-bdd |
Playwright MCP and the app running locally |
create-xray-test |
Tracker and test access, for Jira and Xray |
run-slice |
Claude Code, run from a separate orchestrator session, with a session open for each repo on the same machine; tracker access; roost in every session |
build-epic, run-bug, review-epic |
Everything run-slice needs; build-epic also needs what slice-handoff and release-qa need |
slice-handoff |
Tracker access, the gh CLI, and the repo sessions open for the epic test run |
close-out-epic |
Tracker access |
release-notes |
Tracker access, and the gh CLI to read PRs, deploy runs and releases |
stacked-prs |
The gh CLI with the gh stack extension, and commit signing if your config requires it |
cross-repo-handoff |
Tracker access to post the prompt; works without it by returning the text |
triage-ticket |
Tracker access |
bug-bash |
Tracker access, the gh CLI (gh stack if you stack PRs), and the local stack if there is one |
automate-tests, verify-slice-tests |
Tracker access, test access, and the local stack if there is one |
release-qa |
Tracker access; for an app, Playwright MCP and the local stack already running; otherwise test access |
write-runbook, pair-runbook |
A checkout of the repo your runbooks live in, and tracker access for the sub-tasks |
Your own skills
Skills that only make sense for your team (a roadmap in your company's format, a report for your board) belong in a private plugin of your own, next to your config. roost's skills can call them: for example, shape-epic asks the skill in roadmap.skill to put an epic on the roadmap.
Using roost in Cursor
Cursor reads skills in the same SKILL.md format from ~/.cursor/skills/. Clone this repo and link the skills there:
git clone https://github.com/Beakpoint-Insights/roost.git ~/src/roost
~/src/roost/scripts/link-skills.sh
The links point at your clone, so git pull in it updates the skills. To use another tool's folder, pass it: scripts/link-skills.sh ~/.agents/skills. To undo, run scripts/link-skills.sh --remove. Put your config at ~/.claude/roost/config.yml or set ROOST_CONFIG.
The skills were written for Claude Code. In Cursor, set up the same MCP servers (Atlassian for Jira, and Playwright) so their tool names match, then expect this:
| Skill | In Cursor |
|---|---|
setup, create-xray-test |
Work |
live-verified-bdd |
Works. Its hand-off for filing goes through your tests adapter; on Xray that's create-xray-test by name, so ask for that skill if Cursor doesn't pick it up. |
stacked-prs, bug-bash, cross-repo-handoff, triage-ticket, write-runbook, pair-runbook, close-out-epic, release-notes |
Work |
release-qa, automate-tests, verify-slice-tests |
Work, with the Playwright MCP set up for an app |
run-slice, build-epic, run-bug, review-epic |
Don't work. They message other Claude Code sessions, which Cursor can't do. |
slice-handoff |
Partly. Sorting, tracker updates and stack checks work; the epic test run needs the repo sessions, so run that step in each repo by hand. |
shape-epic |
Partly. The problem statement, slices and tests work. The prototype may need your design system's tools, the build guide is published as a claude.ai artifact, and the tech lead handoff uses your plan skill. Run those phases in Claude Code. |
Contributing
Contributions are welcome. CONTRIBUTING.md explains how to add a skill, open a PR, run the evals and write commit messages. Please follow the code of conduct, and report security issues privately, as SECURITY.md describes. Questions and ideas go in Discussions.
License
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found