mem-forge
Health Uyari
- License — License: NOASSERTION
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Basarisiz
- rm -rf — Recursive force deletion command in admin-ui/package.json
- network request — Outbound network request in admin-ui/package.json
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Give every agent your team's brain on day one. The memory layer for AI agents. Everything your team knows. Cited, and always up to date.
 MemForge
Give every agent your team's brain on day one.
The memory layer for AI agents. Everything your team knows. Cited, and always
up to date. Built from your docs, tickets and chat.


The open-source edition runs on your machine. The Team Cloud Edition is on the way: we host it and provide the models, your team just subscribes. Join the waitlist.
Why MemForge
On day one, your agent knows what your team knows. A new hire picks up a
ticket, and their agent reads the code and guesses. The answer the team
settled months ago sits in a Notion page nobody linked. With MemForge, the
agent checks team memory before it acts and finds the convention, decision or
known issue that applies, from Confluence, Jira, Notion, GitHub and Teams in
one search call.
When a doc changes, memory follows. The team changed a rule last week, and
agents still repeat the old one. With MemForge, the next sync rechecks every
memory built on the changed page: each is kept, replaced or retired, and the
earlier version stays as history. Memories that repeat, update or contradict
each other are linked, so the agent sees which one replaced another and where
two disagree.
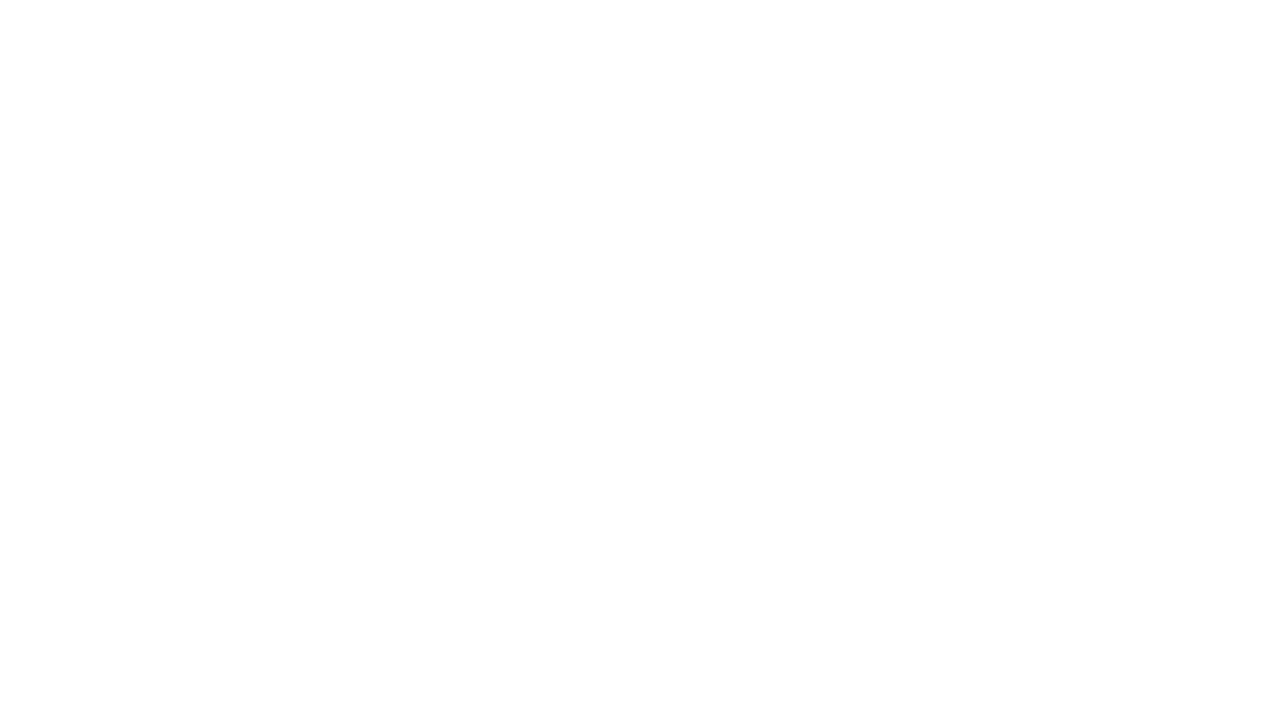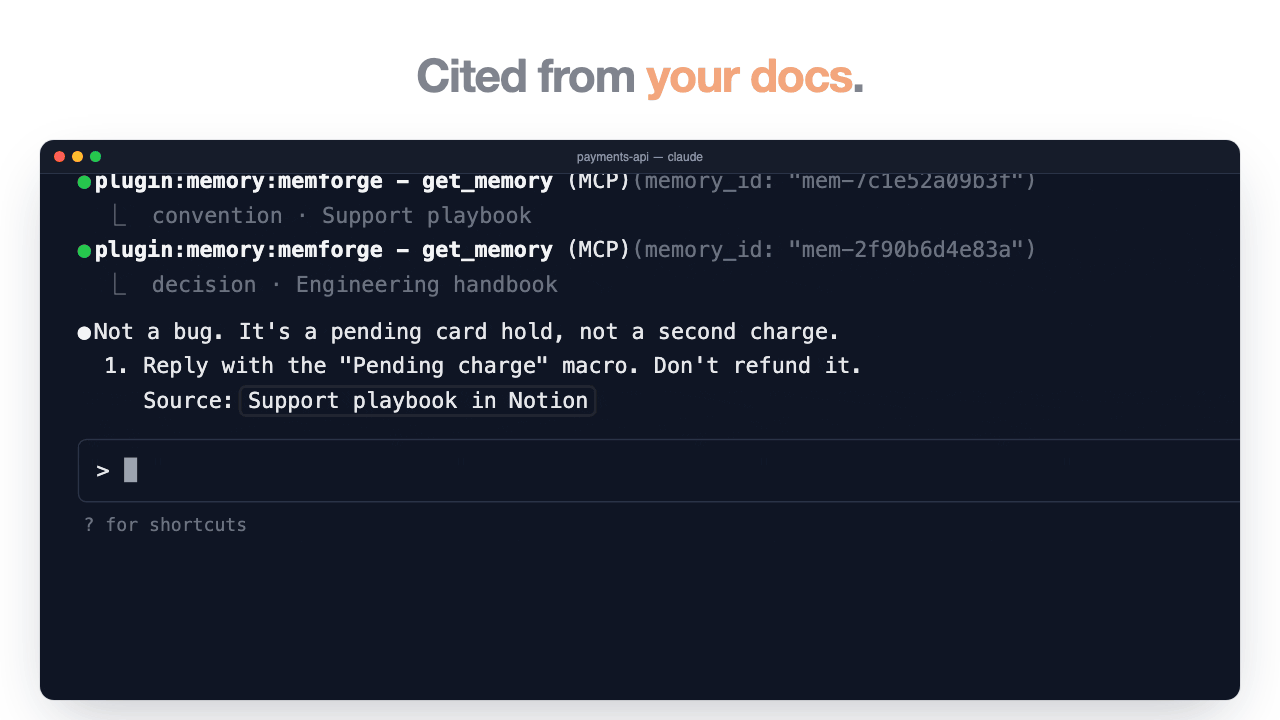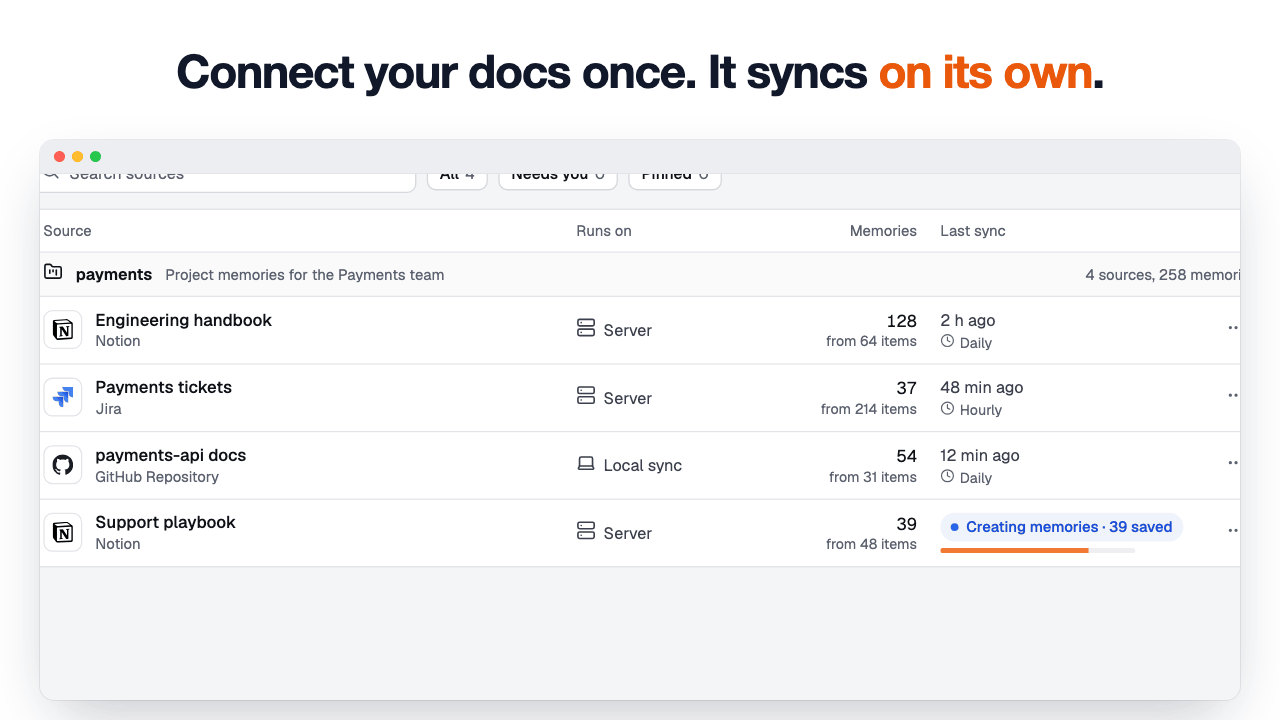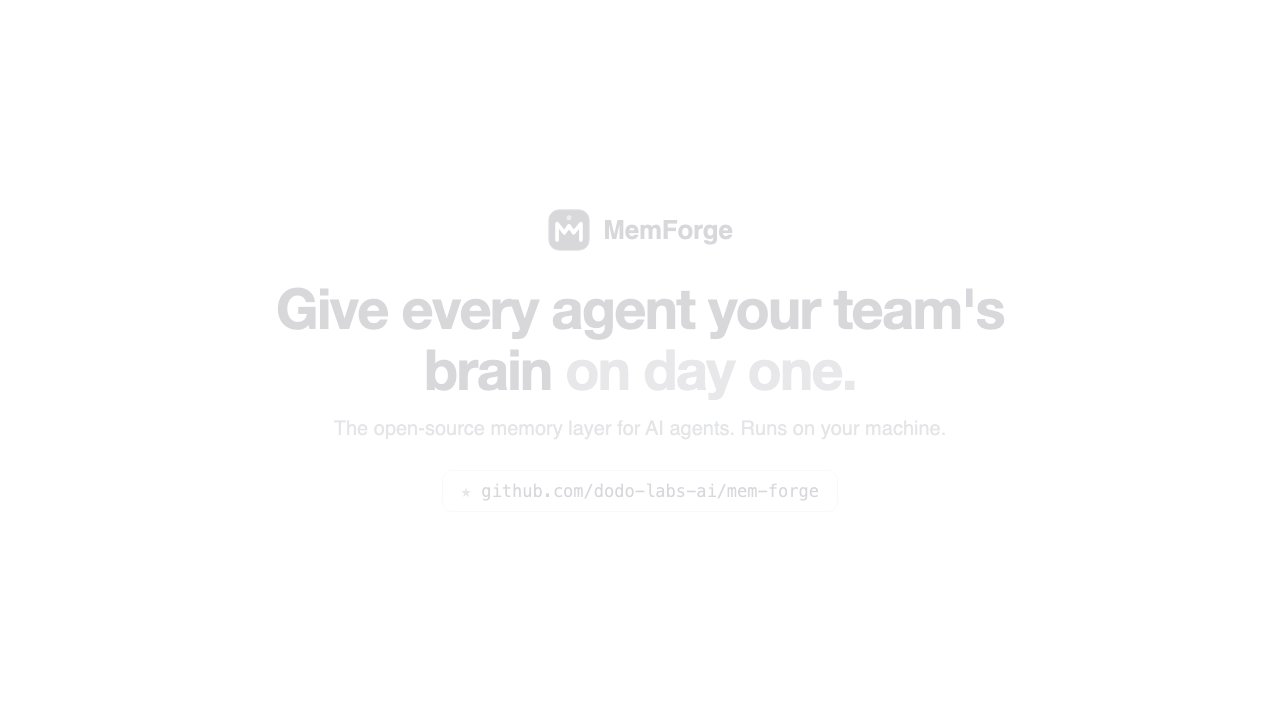
Every answer shows where it came from. A confident answer you cannot check
is a liability. With MemForge, each memory comes with its supporting text and
a link to the page, ticket or file. Where the source allows it, the citation
is pinned to the revision and passage that was read, and the agent can open
the original. The supporting text can be the model's focused wording, not
always a verbatim quote.
It runs on your machine. Apache-2.0, with local storage (SQLite, FTS5 and
Chroma). You bring your own model keys, and those providers receive only what
is sent for inference. The plugins send no session transcripts.
See how MemForge compares with Mem0, Zep, claude-mem and
Unblocked.
Quick start
Beta. APIs, storage formats and plugin packaging may change. An upgrade
that migrates your data saves a recovery point first
(Upgrading).
You need Docker with Compose v2 and an API key for OpenRouter, OpenAI or
Anthropic.
Let your agent set it up. Paste this into Claude Code or Codex:
Set up MemForge for me. Fetch this guide with curl and follow it exactly:
https://raw.githubusercontent.com/dodo-labs-ai/mem-forge/main/docs/agent-setup.md
The agent starts MemForge and installs its plugin, then hands you the admin UI
to enter your model key and connect a source, so your keys never pass through
the agent.
Or set it up yourself:
Start MemForge.
git clone https://github.com/dodo-labs-ai/mem-forge.git && cd mem-forge
cp .env.example .env
docker compose up --build
The admin UI is at http://localhost:5174.
Choose models. In Settings, choose a generation model, which writes
the memories, and optionally an embedding model for semantic search. After
Save and validate, each one shows Ready.Connect a source. In Sources, add Notion pages, a Confluence
space, a Jira project or a GitHub repository, and run a sync. Turn on
Sync automatically to keep it current. The source shows the memories it
made as the sync runs.Install the agent plugin.
# Claude Code (inside a session)
/plugin marketplace add dodo-labs-ai/mem-forge
/plugin install memory@memforge
# Codex codex plugin marketplace add dodo-labs-ai/mem-forge codex plugin add memory@memforgeAsk. Start a new agent session in your project and ask:
Before you change this, check MemForge for decisions and conventions that
apply, and show the source for each one you rely on.
The agent answers with the memories that apply and names the source of each.
The quickstart covers every model provider,
local folders, the host CLI and network details.
How it works
flowchart LR
  subgraph You["Your machine"]
    CC["Claude Code / Codex"]
    Plugin["MemForge plugin"]
    API["MemForge"]
    Extract["Write short memories,<br/>each citing its source"]
    Recheck["Recheck when a source changes,<br/>link related memories"]
    Store[("Local storage")]
  end
  Docs["Confluence, Jira, Notion,<br/>GitHub, Teams, local files"]

  CC --> Plugin
  Docs -- "sync" --> API
  API --> Extract --> Recheck --> Store
  Plugin -- "search, read a memory,<br/>open its source" --> API
  API -- "read" --> Store
- Sync. Connectors read your docs, tickets and chat, on a schedule or
when you ask. - Extract. A model turns each source into short memories, each citing the
passage it came from. - Recheck. When a source changes, the memories built on it are kept,
replaced or retired, and related memories are linked. - Recall. Agents search memory and open its sources over MCP.
More detail: architecture overview.
Integrations
MemForge sits between the systems where your team writes things down and the
agents that do the work.
Agent integrations
 Claude Code
 Codex
Memory sources
| Docs and wikis |
 Confluence  Notion  GitHub Pages
GitHub repo docs  Local folders |
| Tickets |  Jira |
| Chat |  Teams |
| Planned |
 Obsidian |
Add a source lists what each one syncs and
how to scope it. Need one that is missing?
Vote for the next source.
Limits
- The open-source edition runs for one person on one machine. It has no
accounts or authentication and listens on127.0.0.1only, so do not expose
it on a network. For memory your whole team shares, join the
Team Cloud Edition waitlist. - Model extraction and semantic judgments can miss useful knowledge or make
mistakes. Check the cited Evidence before relying on a consequential claim. - A generation model is required; without one, syncs store content but create
no memories.
Documentation
- Quickstart: setup, models, plugins, sources, CLI,
development from source - Docs index: quickstart, architecture, API and release guides
- Contributing
License
Apache License 2.0. See LICENSE.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi