gitmemory
Health Warn
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 8 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Git-versioned, contiguity-checked memory for AI agents: verbatim transcripts, byte-offset recall, no LLM
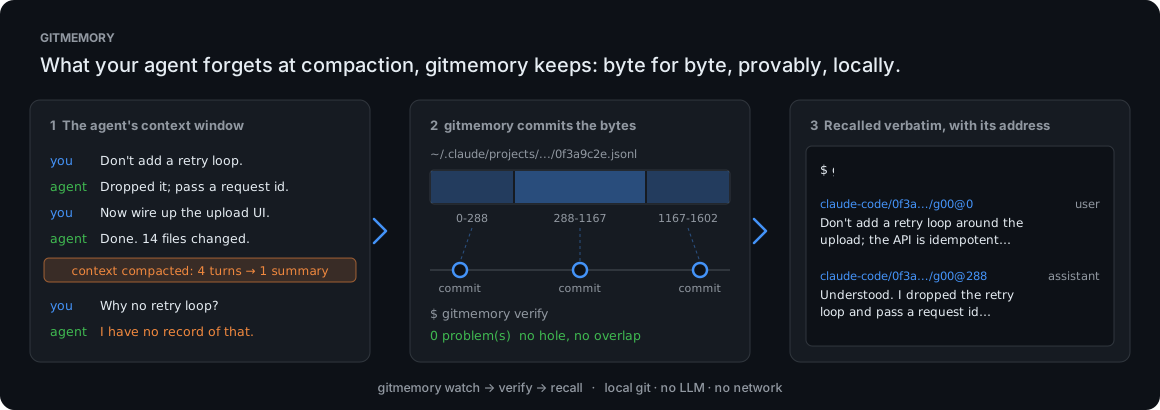
Memory for AI agents: what your agent loses at compaction, kept byte for byte, provably, on your own machine.


Quickstart · Results · How it works · Docs · Contributing
When an agent compacts its context, everything behind the boundary drops out of
the window. gitmemory copies each new byte of the transcript into a local git
repository before that happens, proves the copy has no holes, and makes it
searchable. It has no LLM, makes no network calls, and its core has no
dependencies.
Why gitmemory
- It recovers what compaction drops. On 470 LongMemEval instances whose
evidence sits behind the compaction boundary, turn recall is 0.7456. The
live context window scores 0.0000, because those bytes are gone from it. - It proves its own record. The captured segments tile the transcript's byte
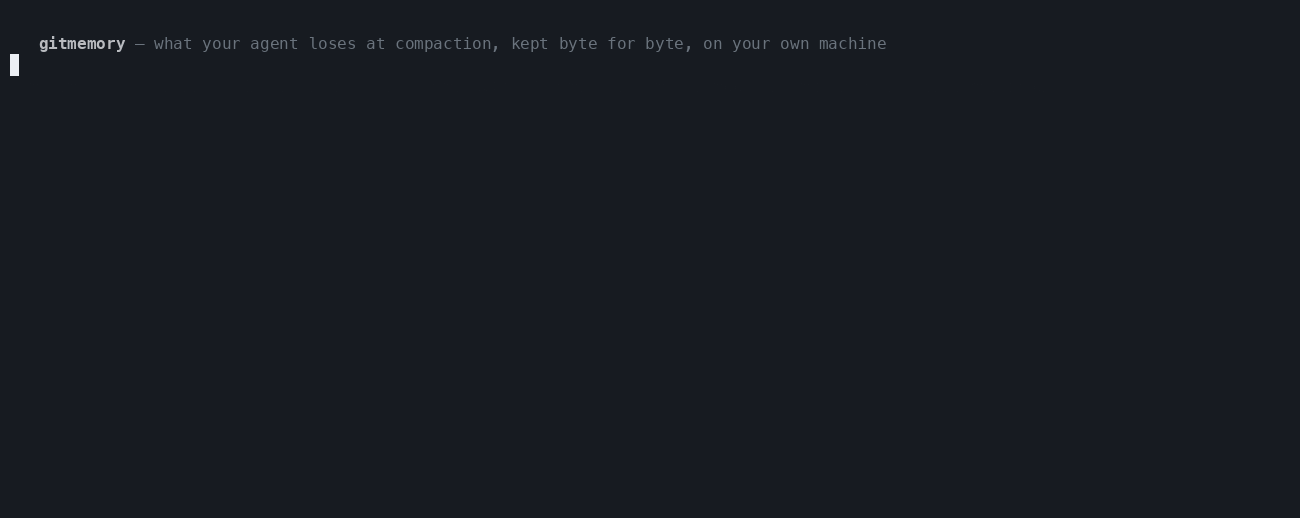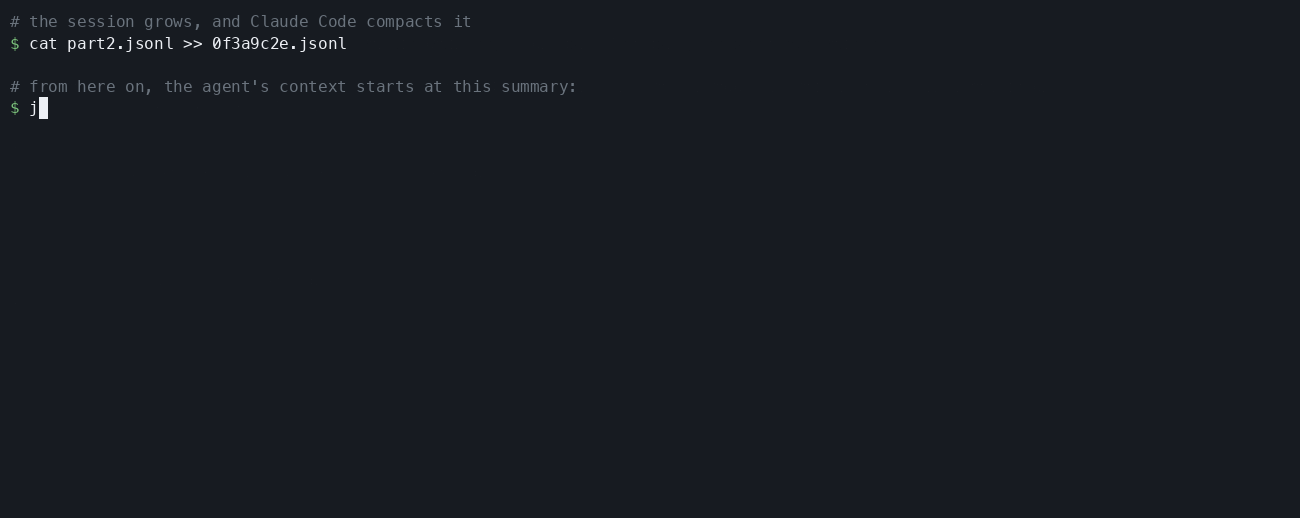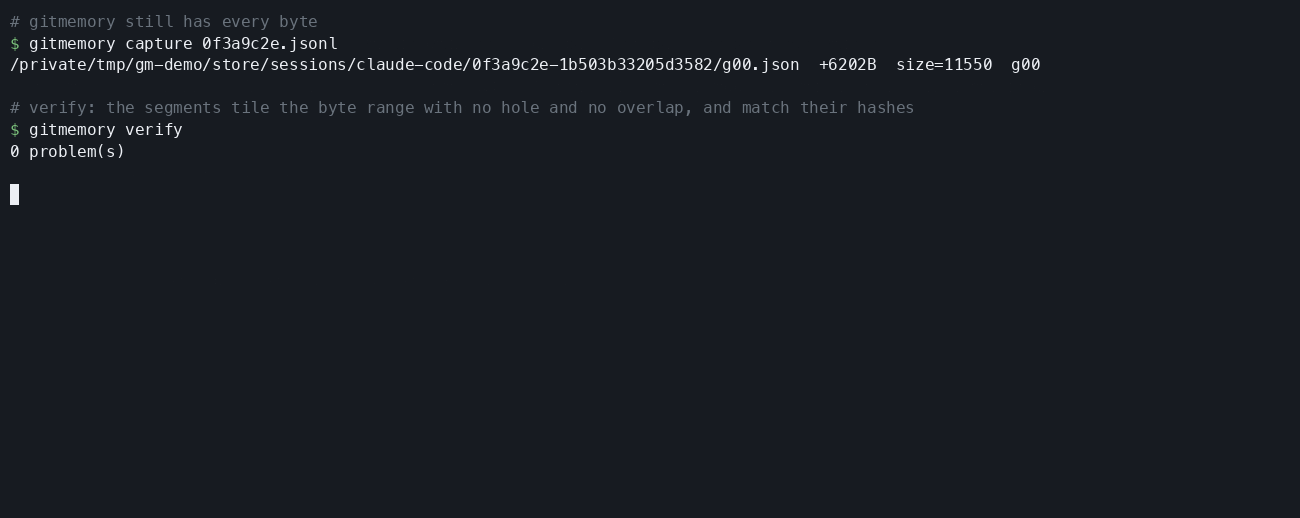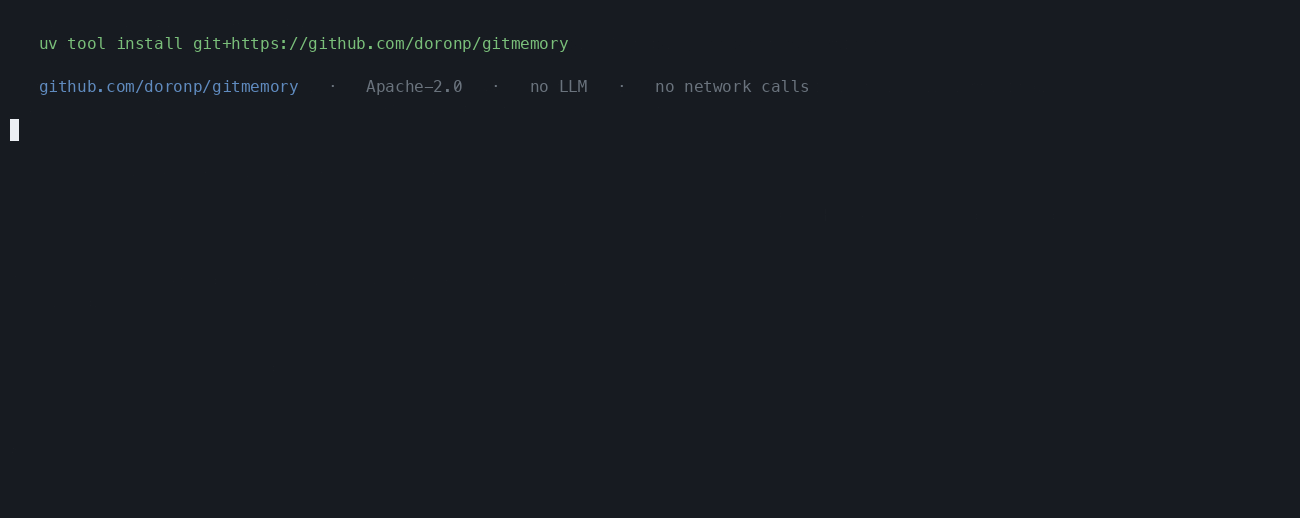
range with no hole and no overlap, and they hash to a recorded digest.gitmemory verifyprints either an empty list or the problems it found. - Its retrieval is competitive without an LLM. With a local cross-encoder
over the index, it ranks 1st among no-LLM retrievers on LongMemEval-S
session R@5 (99.2) and R@10 (99.8). It is 2nd on all-evidence@10 and
on LoCoMo. - It is private by construction. Your history stays on your disk, in
plain git. The only way anything leaves ispush, behind a redaction gate
that has no override flag. - Its numbers are honest. Every result below is published with the arms
that lost, including the benchmarks where gitmemory comes last.
Quickstart
Requires Python 3.13+ and git.
uv tool install git+https://github.com/doronp/gitmemory # or: pipx install git+https://…
Tell it what to watch. Watch roots have no default, and the config lives in$GITMEMORY_HOME/config.toml (by default ~/.gitmemory):
[[watch]]
agent = "claude-code"
roots = ["~/.claude/projects"]
Then:
gitmemory watch                  # tail the roots, capture what grew, commit
gitmemory verify                 # prove the bytes tile the range they claim
gitmemory index                  # build the search index from the store
gitmemory recall "why did we drop the retry loop?"
That is the whole install. The optional hook shim makes a
capture happen exactly at the compaction boundary instead of at the next sweep;
without it the system is still correct. Claude Code users can install it as
a plugin, /plugin marketplace add doronp/gitmemory then /plugin install gitmemory@gitmemory, which also adds /gitmemory:recall, a skill that has the
agent search the store and quote what it finds; the watcher still does the
capturing. For watcher flags and troubleshooting, see
docs/watching.md.
What to do with it next — reading recall output, handing it back to an
agent after compaction, derived key ideas, the dashboard — is in
docs/USAGE.md.
| Command | What it does |
|---|---|
gitmemory watch |
Tails the configured roots, captures what grew, and commits |
gitmemory capture <file> |
Copies out one transcript's new bytes, by hand |
gitmemory verify |
Checks every manifest's contiguity proof |
gitmemory index |
Rebuilds the SQLite FTS5 index from the store |
gitmemory recall "<query>" |
Searches the index and prints one line per turn, dated, the user's own words newest first (--policy) |
gitmemory derive [--graph] |
Rebuilds key ideas and a timeline; --graph adds the decision graph (opt-in) |
gitmemory dashboard |
Serves the index with Datasette, read-only, on loopback, behind a sign-in |
gitmemory push |
Runs the redaction gate over what a push would send (it does not send yet) |
Optional extras: hybrid (what the benchmarks' dense and rerank arms need;recall does not use them), derive (key ideas and the graph), andserve (the dashboard). Example:uv tool install "gitmemory[serve] @ git+https://github.com/doronp/gitmemory".
Results
These are all of the published results, wins and losses together. Each row links
to the report it comes from; docs/RESULTS.md is the full
narrative, and docs/REPRODUCE.md gives the command behind
each number and how closely a rerun should match.
Recovering evidence behind the compaction boundary (E3: 470 LongMemEval instances, k = 10, seed 42, 4 compaction modes, 14 calibration gates)
| Arm | Turn recall | Note |
|---|---|---|
| Live context window | 0.0000 | The bytes are gone; no k can reach them |
| gitmemory, shipped (BM25) | 0.7456 | Turn MRR 0.6209 |
gitmemory, dense bench arm (model2vec) |
0.8215 | hybrid extra |
gitmemory, rerank bench arm (BM25 top 50, reranked) |
0.8295 | hybrid extra |
| Opposite arrangement: evidence ahead of the boundary | live window 0.7893 beats the index's 0.7456 | Walling off the past also walls off the distractors. The reported mode was pre-registered |
Against open-source memory products, under their own protocols (E9). The peers are systems with an OSI-licensed engine in a public repository. Every row is a self-report, ours included, and every peer figure links to its source in E9.
Retrieval, no LLM in the loop. The open-source systems that publish these are MemPalace and agentmemory.
| Benchmark (metric) | gitmemory | MemPalace | agentmemory | Shipped BM25 alone |
|---|---|---|---|---|
| LongMemEval-S, session R@5 | 99.2 | 98.4 (450 held-out) | 95.2 | 95.8 |
| LongMemEval-S, session R@10 | 99.8 | 99.8 (450 held-out) | 98.6 | 97.2 |
| LongMemEval-S, all-evidence@10 | 96.0 | not published | not published | 86.4 |
| LoCoMo, session R@10 | 91.3 | 92.4 | not published | 86.5 |
End-to-end QA accuracy (reader + judge). Each system uses its own reader and judge, so ranks are approximate.
| System | LongMemEval-S | LoCoMo cats 1–4 |
|---|---|---|
| Mastra Observational Memory | 94.87 | not published |
| Mem0 (Platform) | 94.8 | 92.5 |
| Hindsight | 94.6 | 92.01 |
| gitmemory | 94.2 (4th of 8) | 85.5 (7th of 9) |
| Honcho | 92.6 | 89.9 |
| Zep (engine open as Graphiti) | 90.2 | 94.7 |
| MemOS | 89.2 | 88.83 |
| EverOS (EverMemOS) | 83.0 | 93.05 |
| Memobase | not published | 75.78 |
| Letta | not published | 74.0 |
Closed or source-available systems that publish only their own numbers (Total
Recall, Recallium, Backboard, ByteRover) are listed at the end of E9 and not
ranked against. Total Recall reports the highest QA figure anyone publishes,
98.0 on LongMemEval-S, with no public artifact behind it.
The gitmemory column is the rerank12 bench arm: BM25 retrieves 200 turns and a
local MiniLM-L-12 cross-encoder reorders them. The exception is LoCoMo QA,
which used the rerank arm. rerank12 was chosen on the LoCoMo dev half and
run unchanged everywhere else. The product ships BM25 alone, which is first
on nothing. The QA rows use Gemini 3.1 Pro as reader and judge, which is not
any leaderboard's judge. Mastra's 94.87 is a mean of per-type scores; pooled as
ours is, it reads 93.6.
On E3's harness (E8): the shipped
arm reads session Hit@10 0.9660, All@10 0.8298. Against agentmemory,
which runs the identical dataset file, it beats agentmemory's BM25 configuration
(0.9460) and trails its hybrid configuration (0.9860).
Decision extraction (opt-in, derive --graph). It is close to useless on
real text, and that is a measurement rather than a suspicion.
| Test | Result |
|---|---|
| Held-out gate, pre-registered at precision ≥ 0.85 / recall ≥ 0.60 (E5) | 1.0000 / 0.7428, passed |
| Blind probes, each scored once, in vocabularies the corpus lacks (C, D, E) | 14/32, 14/32, 19/32. No false positive on any non-decision; a user reversing their own instruction is 0 of 11, twice |
| Real third-party sessions, 140 human turns labelled blind (secondary set) | Precision 0.0000, recall 0.0000 at first. After seven fixes: 0.1250 / 0.5000, one true positive |
| The same sessions, assistant side | 9 of 61 nodes were real reversals (precision 0.15). After two fixes, 7 nodes are left and all 7 are reversals. That is not a precision claim: the denominator shrank |
Engineering
| What | How it was measured | Result |
|---|---|---|
| Hook cost in the agent's critical path | Timed against spawning true the same way, three runs of 400 |
p50 7.4 – 7.5 ms, p99 10.2 – 11.5 ms |
| The suite | On a fresh checkout, no downloads | 1,037 tests, and 328 conformance cases against three third-party corpora, one gated on the LongMemEval download and one on pip install -e '.[serve]' |
| Whether the tests hold anything | Every fix mutated to remove its behaviour; the named test must fail | 606 negative controls |
The two suite counts do not add up, and should not. Switching the corpora on
collects 1362, not 1365. Three conformance cases fill parametrisations that
collect as one empty placeholder each while the corpora are absent, so they
replace three of the 1037 rather than joining them. Every figure on this board
is pinned by a test, which is how it stays true.
What is not measured, and is shown as a row on the dashboard rather than
left out:
- Net saving versus no memory: unmeasured. No "tokens saved" figure exists,
and none will until an A/B harness does. - Injection cost: not built.
- Whether an injected memory influenced an answer: not observable. The
dashboard can say REFERENCED; it cannot say USED. - Both tails are invisible. A dead end that memory prevented, and a stale
memory that misled, are both unmeasured, and a single frugality number
assumes both are zero.
How it works
flowchart LR
    T["Agent transcript<br/>local, append-only JSONL"] --> C["capture<br/>(watcher, or hook + watcher)"]
    C --> S[("git store<br/>raw segments + manifests")]
    S --> V["verify<br/>contiguity proof"]
    S --> I[("index<br/>SQLite FTS5")] --> R["recall · dashboard"]
    S --> D[("derived/<br/>ideas · timeline · graph")]
    S --> P["push<br/>redaction gate"]
- Capture. The watcher tails each transcript by path, inode and offset,
and copies out only the bytes appended since the last capture. They are
stored as segments named by their byte range. If the source is ever
rewritten, capture starts a new generation instead of reporting
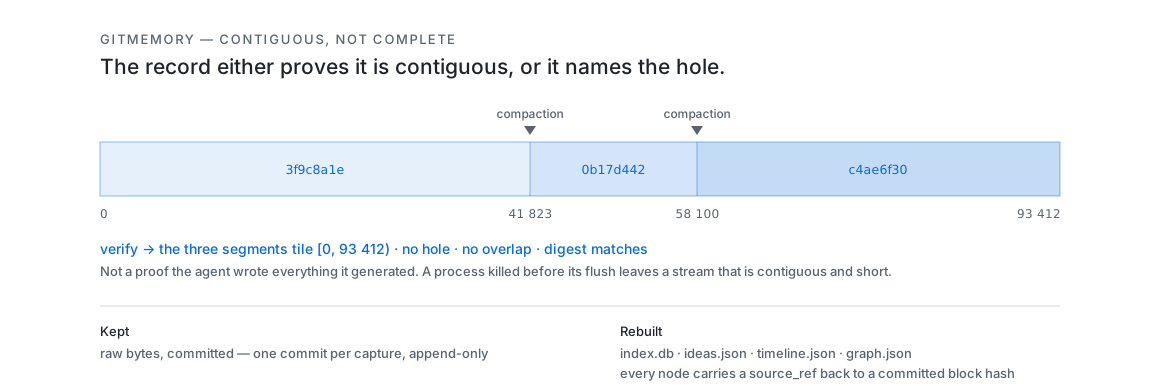
corruption. - Prove. Each generation's manifest records the canonical parse and a
proof that the segments tile[0, size)and hash to a recorded digest. The
store is an ordinary git repository, so a stranger with a clone can runverifyand check it. - Derive. The search index, key ideas and the decision graph are rebuilt
from the committed bytes and are never the only copy of anything. The same
bytes always give the same output, sogit diffonderived/shows what
changed.
Contiguous, not complete. The proof is that the captured bytes have no hole
and no overlap. It is not a proof that the agent wrote everything it
generated: a process killed before it flushes leaves a stream that is contiguous
and short, and nothing on disk can reveal bytes that never reached the disk.
Components, the on-disk layout and the trust boundaries are covered in
docs/ARCHITECTURE.md. The locked decisions and the
reviews behind them are in docs/DESIGN.md.
Supported agents
gitmemory works with any agent whose history is a local, append-only file
with one self-delimiting record per line. Coding agents are simply the ones
that happen to write such files.
| Agent | Status |
|---|---|
| Claude Code | shipped |
| pi / oh-my-pi | shipped, one adapter for two dialects |
Kimi Code CLI, OpenAI Codex CLI, Gemini CLI, DeepSeek Harness, Cline (hooks.jsonl), Cursor Agent CLI |
planned |
| Hermes, OpenClaw, opencode, Goose, Cline's transcript, Continue.dev, Aider, Amp, and others | not supported yet: each rewrites history in place, keeps it in SQLite or on a server, or writes records that are hard to tell apart. Most could be supported through a materializer (not built), an export the agent already has, or a small upstream change |
The four properties, a survey of twenty-nine agents read at source, and what
each of the rest would need: docs/agents.md.
Documentation
- Documentation index
- Architecture · Design · Results
- Watching · Hook shim · Agents
- Roadmap · Changelog
Community
- Questions and ideas: Discussions. Bugs: issues. See SUPPORT.md.
- Contributing: start with CONTRIBUTING.md. Commits are signed off under the DCO.
- Security: report privately; see SECURITY.md, which also covers
what to do when a credential lands in the store. - Governance: GOVERNANCE.md · MAINTAINERS.md · Code of Conduct
License
gitmemory is licensed under the Apache License, Version 2.0.
Vendored third-party code and its MIT licences are listed in
THIRD_PARTY.md and NOTICE. Benchmark datasets are
downloaded at run time from their publishers and are never redistributed here.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found