agentic-patterns
Health Warn
- No license — Repository has no license file
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 16 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Patterns and runnable examples for AI coding agents: stack tests, guardrails, containment, a repair loop with a deterministic gate, and Earned Autonomy, which sets how far one workflow may run without a person. TypeScript and Python.
Agentic Patterns
How much can you let an AI coding agent do without a person checking? This repo answers with layered checks, runnable
examples, and a rule for earning more freedom as evidence builds. Without those checks, agents pass their own tests,
swallow errors to turn checks green, and edit the rules that constrain them.
Written for teams using Claude Code or a similar agent harness.
The Pattern Layers
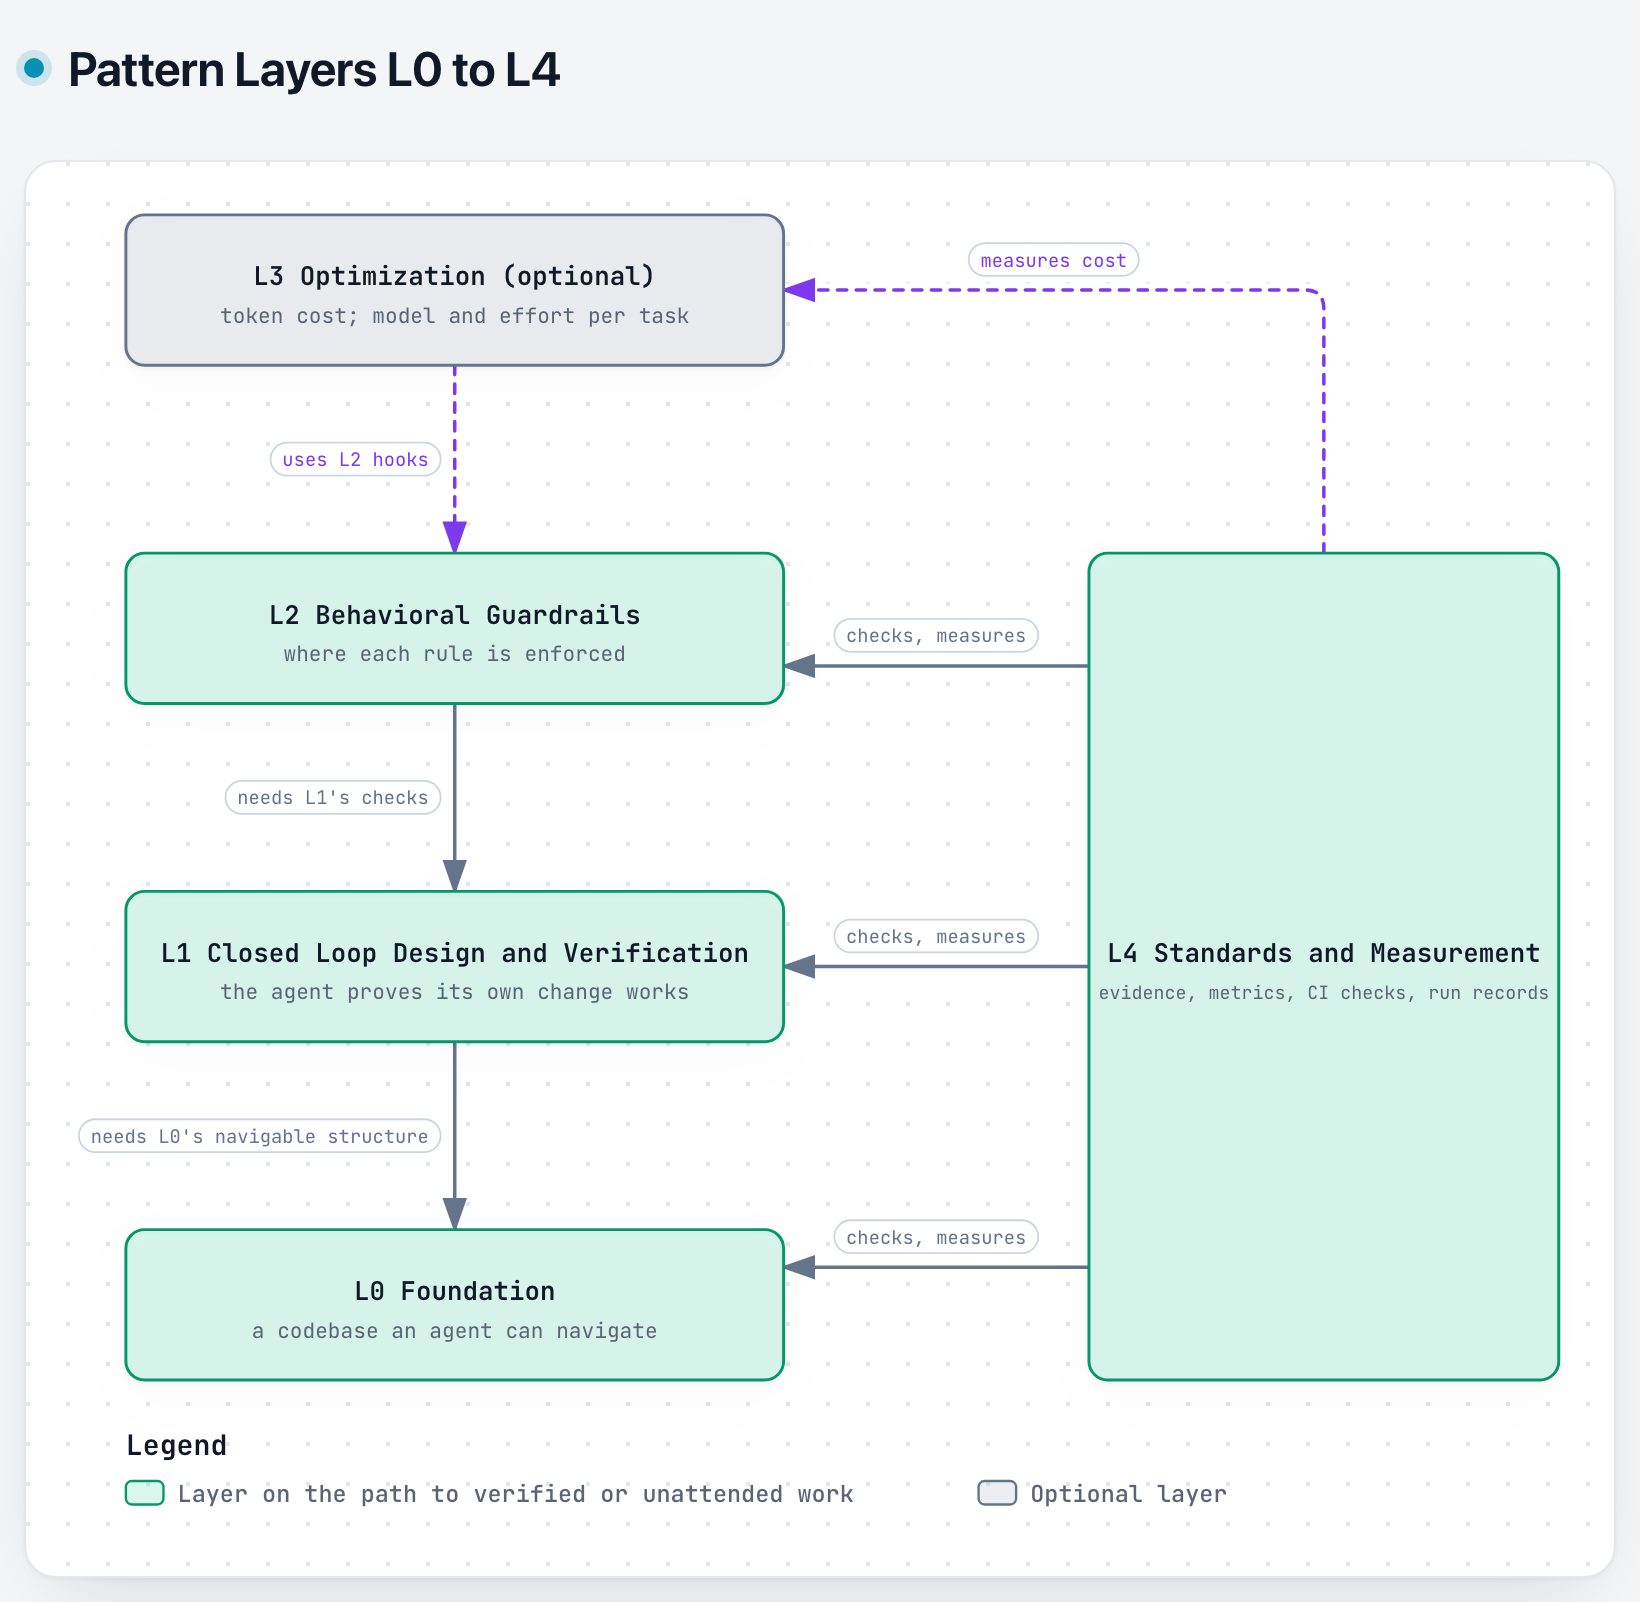
L1 verification needs L0's navigable structure, L2 enforcement needs L1's checks, and L4 checks and measures L0 to L2. L3 is optional and uses L2's hooks.
Layer Overviews
L0: Foundation — A codebase an agent with no prior context can navigate: deep modules, progressive disclosure, one AGENTS.md for every harness, unit tests as contract and aggressive cleanup.
L1: Closed Loop Design and Verification — How an agent proves its own change works. Stack tests run the whole application in Docker with real dependencies and assert each journey's effects; tests that can pass silently are forbidden. Patterns 1.7 to 1.12 extend the loop to incidents in code you own.
L2: Behavioral Guardrails — Enforcement points stack. Prose is guidance, command hooks are deterministic policy inside the harness, containment and credentials are the boundary, and skills guarantee nothing. Name the enforcement point for every constitutional rule.
L3: Optimization (optional) — Lower token cost: native structured tools, blocking destructive shell edits, a scout sub-agent, model and effort per task. Not on the path to verified or unattended work.
L4: Standards & Measurement — Evidence-based claims, metrics, CI guardrails, context eval, ownership of agent-written code, the team's skill to supervise and run records.
Earned Autonomy
Finishing the layers does not let an agent run unattended. Earned Autonomy sets that limit
per workflow. A named person gives a workflow a grant, from A1 (suggest only) to A5 (merge low-risk changes with no
person), on CI evidence. The repository caps every grant at what it has in place, and a grant falls when the evidence
stops. examples/autonomy runs the register check, census, ledger and stop drill. The
scales, grants and approval rules are in How the Scales Fit
Together.
Where to Begin
- Not sure where your gaps are: the adoption guide assessment.
- One person running attended sessions: Path E.
- A team moving to unattended work: Path D.
- A maintainer adding agents to a repository with CI: Pattern 0.4 and Pattern 4.5.
What's in This Repo
docs/                 # Layers L0-L4, Earned Autonomy and guides
  cross-cutting/      # Anti-patterns, adoption guide, threat model, FAQ, glossary
  references/         # Case study, further reading, sources, task bank
examples/             # Working code (TypeScript and Python; L3 is TypeScript only)
  stack-test/         # Pattern 1.1: Docker stack tests (typescript/ with Playwright, python/ with pytest)
  repair-loop/        # Patterns 1.7-1.11: incident to reproduction to gate decision, no LLM
  containment/        # Pattern 2.9: policy layer vs container boundary, with tests
  autonomy/           # Patterns A.1-A.6: register check, census, ledger, stop drill, hook
  guardrails/         # Pattern 3.1: optional token-optimization middleware
  project-structure/  # L0: before and after directory layouts (documentation only)
What This Library Does Not Cover
- Production ownership, in part. Pattern 4.7 names an author of record and Pattern A.5 rehearses the stop. On-call, rollback, deployment and production telemetry are not covered; the FAQ states the contract with operations.
- Comparing outcomes against a baseline. Pattern 4.4 shows the baseline file the census reads, not how to compare against it.
- Data handling and incident response. Run records: Pattern 4.10. The rest of security and governance: Patterns 2.9 to 2.13 and the threat model.
- Docker stack tests inside the sandbox. The FAQ compares three options; no example runs one.
- Monorepos. The census computes one cap per repository, not per package (FAQ).
Covered: the development-time loop (L0 to L4) and the seam where production incidents enter it (Patterns 1.7 to 1.12, with a runnable gate in examples/repair-loop). Unattended repair of data-forward or irreversible changes is not supported at any grant.
Origin and Disclosure
The ideas are established (Ousterhout's deep modules, Matt Pocock's graybox modules, progressive disclosure, evidence-based engineering); this library states them as patterns with a check for each.
The patterns were extracted from a Telegram trading bot: a private application by this library's author that moves funds on blockchains, developed with Claude Code. That project developed Stack-First Development: the entire application stack in Docker, tested through API endpoints only, each stack test an atomic user journey. It is one project with no independent replication.
The author also built rig, a guardrails framework on the L2 to L4 patterns with L3 tool routing; superpowers provides L2 base skills. rig demonstrates the patterns and does not validate them. Both install hooks, skills and commands that run with your agent's privileges: read and pin before installing (Pattern 2.12).
Contributing
Welcome: new or challenging patterns, examples from other domains, corrections with the exception documented, and bindings for other harnesses (each L2 pattern's Bindings section states the contract).
Background and Further Reading
- Reference Telegram Trading Bot Case Study — the project these patterns came from
- Further Reading — articles, videos, and tools that informed this work
- Glossary — terminology reference
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found