fyrr
Health Gecti
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 10 GitHub stars
Code Basarisiz
- rm -rf — Recursive force deletion command in .github/workflows/ci.yml
- rm -rf — Recursive force deletion command in .github/workflows/release.yml
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
The serverless, permission-aware context layer for AI agents. No database. Just a bucket.
The serverless, permission-aware context layer for AI agents. No database. Just a bucket.
Website · Docs · Use cases · Compare · Changelog


Pre-1.0. Cloud connectors are tested against synthetic APIs only.
Why fyrr
- Find: works in the AI you already use. Plug fyrr into Claude, Cursor or
any MCP app. Ask there, and it searches your docs, chats, tickets and code
over stdio or Streamable HTTP (MCP tools). - Protect: only what each person may read. fyrr syncs each document's
access rules with its content and checks them inside the search, before
anything is ranked. A forbidden document looks exactly like one that does
not exist, and missing permission data refuses rather than guesses
(how, security). - Scale: as many readers as you need. Readers only read from the bucket
and never coordinate, so you add more as you grow
(topology). - Own: your data stays yours. It runs in your own cloud. Text leaves it
only for the embedding model you choose.
Connectors for local files, Google Drive, Notion, GitHub, Slack and Jira; a
Python SDK lets you write your own.
16 milliseconds. Among the best results.
Fast enough for an agent to search at every step: a 16 ms median search, 25 ms
at p95. Accurate enough to trust what comes back: a 90+ score on
EnterpriseRAG-Bench, among the best of 43 systems tested. The
open comparison measures quality, latency, ingest
and running cost against self-hosted alternatives, with its full protocol.
No database. Just a bucket.
Everything fyrr knows lives as files in one S3 bucket, or in a private local
directory. Small teams run nothing around the clock; a whole company adds one
small service. The reader also runs on AWS Lambda
(experimental): no always-on reader server, pay per request.
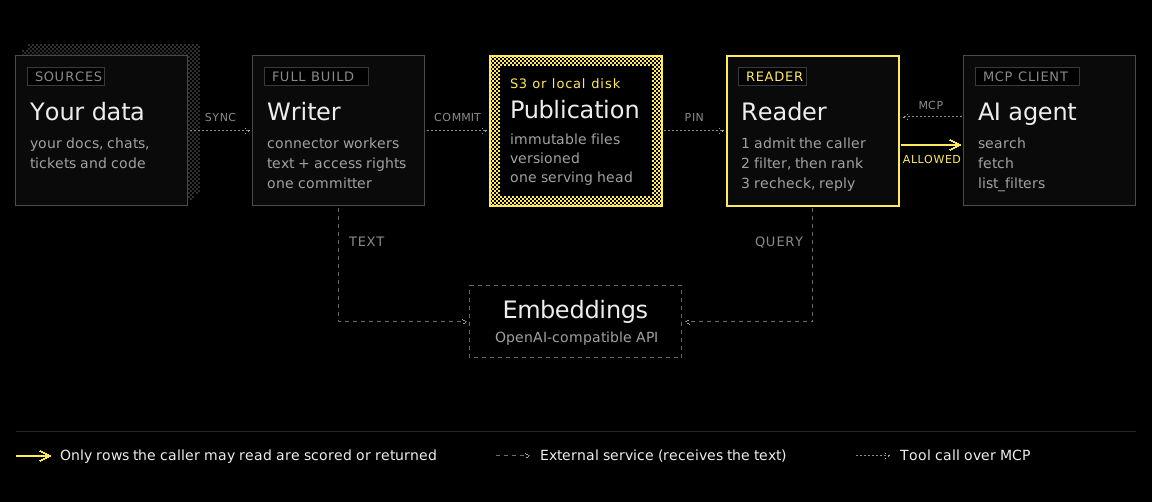
From one laptop to the whole company.
| Way | What runs |
|---|---|
| Just you | Your files, notes and repos, searched by your coding agent. |
| A team | One shared index, no server. Each teammate's agent searches it directly. |
| The company | One index and one server, behind your company login. |
| Training & evals | A fixed index that changes only when you update it. Search it in parallel. |
Every way: no database. See use cases and
deployment.
Quick start
Follow the quickstart to search a Markdown folder from
Claude Code using a private local directory. It needs Linux x86-64 and the
tools git, curl, unzip, openssl, Python 3.11+, rustup, uv, a C compiler, jq,
binutils, network access and about 10 GiB free; no accounts
or embedding keys are needed. The guide also covers adding Slack and trying
Ada/Grace permissions. For shared deployments, see
deployment.
After setup in the quickstart:
fyrr writer namespace create
fyrr writer sync
fyrr writer commit
claude mcp add fyrr --scope user -e FYRR_IDENTITY_KEY="$FYRR_IDENTITY_KEY" -- "$PWD/target/debug/fyrr" --config "$FYRR_CONFIG" reader serve
Ask Claude:
Use fyrr search and fetch to answer: How do I restore a backup? Quote the handbook.
The example's top hit is notes/backup.md, with the answer:
"To restore a backup, run the restore job and verify the checksum."
Limits
- You need a stable release. fyrr is pre-1.0: storage formats and the
MCP schema may break before 1.0; data is then republished, not migrated.
Releases (binaries, images, the SDK wheel) will be published fromv*tags. - You need proven cloud connectors. Google Drive, Notion, GitHub, Slack
and Jira have been tested only against synthetic APIs, not real workspaces. - Your documents are not text. There is no PDF, Office or image
extraction. - You cannot send text to an embeddings service. You provide an
OpenAI-compatible/embeddingsendpoint, and document and query text is
sent to it. - You do not run Linux. Linux (x86_64, aarch64) is the only supported
platform, for builds, binaries and images. - You need phrase queries. The full-text index stores no term positions.
- You want TLS built in. The HTTP listener speaks plain HTTP; outside
loopback it needs a TLS-terminating proxy.
Documentation
| Page | Content |
|---|---|
| Quickstart | Build, configure and search a local folder |
| How fyrr works | Terms, publication, authorization and retrieval |
| Security model | Trust boundaries, permissions and secrets |
| HTTP login and users | Authenticate and enroll HTTP users |
| Deployment | Production setup, images and scheduling |
| AWS Lambda | Experimental reader deployment |
| Operations | Monitor, restore, retire and upgrade |
| Configuration | Storage, embeddings, sources and secrets |
| Identity | Users, directories, keys and OIDC |
| Tuning | Namespace and retrieval settings |
| Reader and writer settings | Serving, retention and maintenance settings |
| CLI | Commands, flags and exit statuses |
| MCP tools | Tool arguments, results and transport |
| Connectors | Setup and limits per source |
| Writing a provider | Connector SDK contract and example |
Contributing
Bug reports, connector requests and pull requests are welcome; for larger
changes, open an issue
first. CONTRIBUTING.md covers the build, scripts/ci and
the contract rules. Report vulnerabilities privately as described in
SECURITY.md, and follow the
code of conduct. Notable changes are listed in the
changelog.
License
fyrr is licensed under the Apache License 2.0; see NOTICE.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi