codegraph-rust
Health Warn
- No license — Repository has no license file
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 888 GitHub stars
Code Fail
- fs module — File system access in .github/workflows/benchmark.yml
- fs module — File system access in .github/workflows/performance-validation.yml
- rm -rf — Recursive force deletion command in .github/workflows/release.yml
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
100% Rust implementation of code graphRAG with blazing fast AST+FastML parsing, surrealDB backend and advanced agentic code analysis tools through MCP for efficient code agent context management
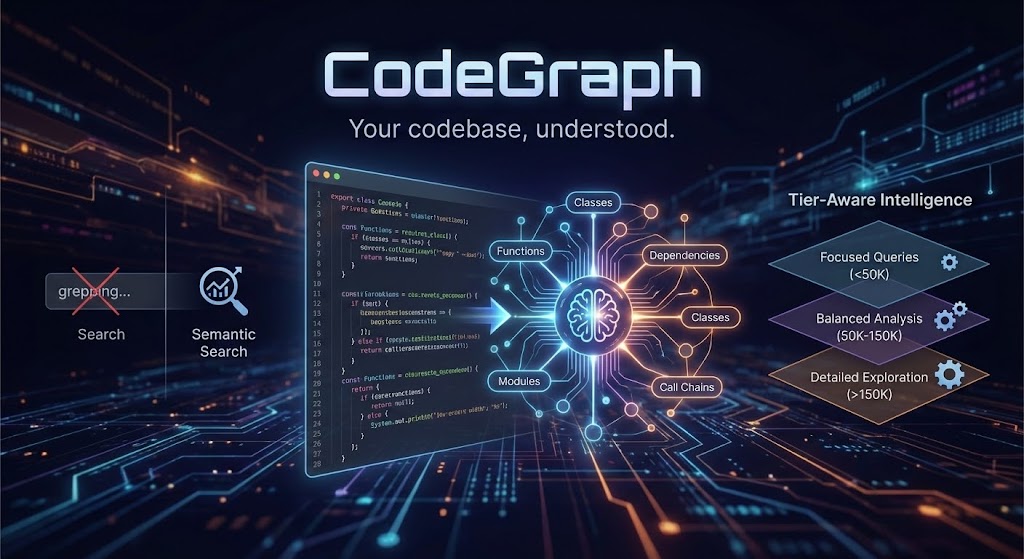
CodeGraph (with updates)
Your codebase, understood.
CodeGraph transforms your entire codebase into a semantically searchable knowledge graph that AI agents can actually reason about—not just grep through.
Ready to get started? Jump to the Installation Guide for step-by-step setup instructions.
Already set up? See the Usage Guide for tips on getting the most out of CodeGraph with your AI assistant.
Prefer shell commands? Run
codegraph agent context "your question". The same four
agentic tools are available through the CLI, with project-local Claude Code/Codex hooks.codegraph initoffers hook setup and adds agent instructions before indexing.
The Problem
AI coding assistants are powerful, but they're flying blind. They see files one at a time, grep for patterns, and burn tokens trying to understand your architecture. Every conversation starts from zero.
What if your AI assistant already knew your codebase?
What CodeGraph Does Differently
1. Graph + Embeddings = True Understanding
Most semantic search tools create embeddings and call it a day. CodeGraph builds a real knowledge graph:
Your Code → Build Context → AST + FastML → LSP Resolution → Enrichment → Graph + Embeddings
              ↓               ↓              ↓              ↓              ↓         ↓
          Packages        Nodes/edges    Type-aware     API surface      Graph    Semantic
          Features        Fast patterns  linking        Module graph   traversal   search
          Targets         Spans          Definitions    Dataflow/Docs             (hybrid)
When you search, you don't just get "similar code"—you get code with its relationships intact. The function that matches your query, plus what calls it, what it depends on, and where it fits in the architecture.
Indexing enrichment adds:
- Module nodes and module-level import/containment edges for cross-file navigation
- Rust-local dataflow edges (
defines,uses,flows_to,returns,mutates) for impact analysis - Document/spec nodes linked to backticked symbols in
README.md,docs/**/*.md, andschema/**/*.surql - Architecture signals (package cycles + optional boundary violations)
Indexing tiers (speed vs richness)
Indexing is tiered so you can choose between speed/storage and graph richness. The default is fast.
| Tier | What it enables | Typical use |
|---|---|---|
fast |
AST nodes + core edges only (no LSP or enrichment) | Quick indexing, low storage |
balanced |
LSP symbols + docs/enrichment + module linking | Richer navigation and documentation with moderate analyzer cost |
full |
All analyzers + LSP definitions + dataflow + architecture | Maximum graph richness and analyzer coverage |
Agent answer accuracy is evaluated separately; see the CLI accuracy results.
Tier behavior details:
fast: disables build context, LSP, enrichment, module linking, dataflow, docs/contracts, and architecture; filters outUses/Referencesedges.balanced: enables build context, LSP symbols, enrichment, module linking, and docs/contracts; filters outReferencesedges.full: enables all analyzers and LSP definitions; no edge filtering.
Configure the tier:
- CLI:
codegraph index /path/to/project --index-tier balanced - Env:
CODEGRAPH_INDEX_TIER=balanced - Config:
[indexing] tier = "balanced"
Directory indexing scans subdirectories by default, socodegraph index --languages Rust --index-tier balanced . finds Rust sources in workspace crates. Use--no-recursive for an intentional root-only scan; -r/--recursive remain accepted.codegraph estimate uses the same traversal defaults.
Indexing prerequisites (LSP-enabled tiers)
When the tier enables LSP (balanced/full), indexing fails fast if required external tools are missing.
Rust indexing also runs rust-analyzer --version from the target project before parsing:
an existing rustup shim does not guarantee that its active toolchain has the component.
With rustup, run rustup component add rust-analyzer from that project directory,
then verify rust-analyzer --version. Language-server failures retain the final 4 KiB
of stderr so startup and runtime errors include the server's diagnostic.
Required tools by language:
- Rust:
rust-analyzer - TypeScript/JavaScript:
nodeandtypescript-language-server - Python:
nodeandpyright-langserver - Go:
gopls - Java:
jdtls - C/C++:
clangd
Warm language-server sessions retain versioned documents and deduplicate/pipeline
definition requests. Symbol and definition requests retry transient ContentModified
(-32801) responses up to five times with backoff within one 30-second deadline.
Changed document versions, exhausted retries and other errors still fail indexing,
with the request method and file URI in the diagnostic. CODEGRAPH_LSP_REQUESTS bounds
outstanding requests per server (default 32). CODEGRAPH_ANALYZERS=0 disables analyzers
independently of tier. CODEGRAPH_SCIP_INDEX=/path/index.scip can substitute a compiler
index for LSP; source validation and sidecar requirements are described in the
indexing implementation guide.
Incremental indexing and inference policies
--batch-size sets the maximum number of embedding texts per batch for both local
and cloud providers. An explicit value wins over CODEGRAPH_EMBEDDINGS_BATCH_SIZE,
its legacy alias CODEGRAPH_EMBEDDING_BATCH_SIZE, and [embedding] batch_size in
TOML, in that order; the default is 64. Memory-based tuning does not change explicit
values, including --batch-size 100.
codegraph index --languages Rust --index-tier balanced --batch-size 512 .
Token/byte budgets, cache hits and provider API limits can produce smaller actual
requests. For larger requests, adjust CODEGRAPH_EMBEDDING_BATCH_TOKENS (default at
least the resolved input context, with local/remote floors of 8192/32768) andCODEGRAPH_EMBEDDING_BATCH_BYTES (default 1 MiB) as needed.
Logs show these inference limits separately from database write batches;CODEGRAPH_CHUNK_DB_BATCH_SIZE defaults to at most 32 rows and is capped at 512.
Ollama and LM Studio have no extra fixed 256-text cap.
Full, single-file and watch indexing share complete-project reconciliation. Unchanged
sources reuse cached AST/analyzer artifacts while the full catalog retains callers
across edits, renames and deletions. Only changed graph records and file metadata are
written. Source snapshots, parsing, inference and writer queues have independent
resource bounds; completion follows durable acknowledgements and final input checks.--force prepares and reconciles again without trusting the previous catalog.
Embedding and semantic-resolution work is independent of extraction tier. Each acceptssync (default when its feature is compiled), deferred or off:
CODEGRAPH_EMBEDDING_POLICY=deferred CODEGRAPH_SEMANTIC_RESOLUTION=off \
  codegraph index /path/to/project --index-tier fast --stats-json indexing.json
codegraph index /path/to/project --complete-deferred --stats-json completed.json
Deferred runs persist a resumable job and distinguish graph readiness from pending
inference. Prepared-text embedding caches include model/task/tokenizer/runtime identity;
chunking preserves Unicode and enforces provider token budgets. Mutable model aliases
expire; CODEGRAPH_MODEL_REVISION declares an immutable revision.
Embedding inputs and chunking
Chunk planning starts from AST node source spans, such as functions and classes.
A unit that fits the complete input budget stays intact. Oversized units split at
Tree-sitter statement/block boundaries, then merge adjacent pieces while they fit.
Oversized leaves and unsupported syntax use UTF-8-safe line/token splitting.
Unicode and structural whitespace are preserved; overlap uses token counts.
For Ollama, the budget follows model metadata and serving context. Qwen3 embedding
models support 32K inputs;
nomic-embed-text-v2-moe
supports 512 tokens. Counting includes document/query prefixes and special tokens.
Nomic text models receive search_document: / search_query: ; Qwen3 queries
receive a retrieval instruction. Every Ollama request uses truncate=false:
context mismatch fails visibly instead of silently dropping source.
Recognized models automatically load their matching publisher tokenizer, cachingtokenizer.json and downloading it on first use if absent. Model weights are not
downloaded. Custom/offline models can supply CODEGRAPH_TOKENIZER_PATH; an unknown
model requires that path or CODEGRAPH_TOKENIZER_REPO.
| Control | Behavior |
|---|---|
CODEGRAPH_CHUNK_MAX_TOKENS |
Lower the complete-input target; capped by serving context. Legacy CODEGRAPH_MAX_CHUNK_TOKENS has lower precedence. |
CODEGRAPH_CHUNK_SMART_SPLIT=0 |
Use token splitting instead of AST boundaries for oversized units. Default: AST splitting. |
CODEGRAPH_CHUNK_OVERLAP_TOKENS |
Maximum suffix overlap in tokens; default 64, zero disables. Shrunk to fit the next input. |
CODEGRAPH_EMBEDDING_SKIP_CHUNKING=1 |
Keep nodes intact; fail before inference if any exceeds the configured input limit. |
CODEGRAPH_OLLAMA_NUM_CTX |
Set request context, bounded by the model maximum. Otherwise use Modelfile/running context when reported. |
CODEGRAPH_MODEL_MAX_TOKENS |
Supply missing model context metadata or lower the advertised maximum. |
CODEGRAPH_TOKENIZER_PATH |
Use a matching local tokenizer.json, without downloading it. |
CODEGRAPH_TOKENIZER_REPO, CODEGRAPH_TOKENIZER_REVISION |
Override publisher tokenizer repository/revision; default revision main. |
CODEGRAPH_EMBEDDING_DOCUMENT_PREFIX, CODEGRAPH_EMBEDDING_QUERY_PREFIX |
Override retrieval prefixes for custom models. |
--batch-size controls texts per inference request, independently of chunk length.
Default request token budgets grow to accommodate the resolved input context
(local floor 8192; remote floor 32768). Explicit CODEGRAPH_EMBEDDING_BATCH_TOKENS
and CODEGRAPH_EMBEDDING_BATCH_BYTES remain separate bounds; an input exceeding
one fails with advice to raise that bound or lower the chunk target.
Reindex after upgrading: tokenizer/task/context and chunk-policy changes invalidate
old artifacts and embeddings. Offline mocks verify preparation and request limits;
retrieval quality and indexing speed still need measurements on your project.
CODEGRAPH_VECTOR_INDEX_MODE=all|selected|deferred|off controls HNSW construction for
fresh embedded stores. The default retains all schema dimensions; selected builds the
active dimension, deferred builds after durable ingestion, and off reports vector
readiness false. Existing shared indexes are preserved. Alternate splitters, candidate
caps and runtime/precision choices remain opt-in.
See configuration and invariants and
reproducible speed/quality benchmarks. The offline debug
fixture results verify behavior; production throughput and model quality require
representative measurements.
Semantic relationship scoring caches vector norms and scores independent unresolved
names in the existing worker-limited CPU pool, outside async runtime workers. Candidate
order, the cosine threshold and ambiguous-tie handling remain unchanged. --stats-json
now separates exact/lexical matching, semantic candidate selection, symbol embedding,
CPU scoring, and edge preparation/writes within relationship resolution.
If LSP resolution fails immediately and the error includes something like Unknown binary 'rust-analyzer' in official toolchain ..., your rust-analyzer is a rustup shim without an installed binary. Install a runnable rust-analyzer (e.g. via brew install rust-analyzer or by switching to a toolchain that provides it).
Optional architecture boundary rules
If you want CodeGraph to flag forbidden package dependencies, add codegraph.boundaries.toml at the project root:
[[deny]]
from = "your_crate"
to = "forbidden_crate"
reason = "explain the boundary"
Indexing will emit violates_boundary edges when a depends_on relationship matches a deny rule.
2. Agentic Tools, Not Just Search
CodeGraph doesn't return a list of files and wish you luck. It ships 4 consolidated agentic tools that do the thinking:
| Tool | What It Actually Does |
|---|---|
agentic_context |
Gathers the context you need—searches code, builds comprehensive context, answers semantic questions |
agentic_impact |
Maps change impact—dependency chains, call flows, what breaks if you touch something |
agentic_architecture |
The big picture—system structure, API surfaces, architectural patterns |
agentic_quality |
Risk assessment—complexity hotspots, coupling metrics, refactoring priorities |
Each tool accepts an optional focus parameter for precision when needed:
| Tool | Focus Values | Default Behavior |
|---|---|---|
agentic_context |
"search", "builder", "question" |
Auto-selects based on query |
agentic_impact |
"dependencies", "call_chain" |
Analyzes both |
agentic_architecture |
"structure", "api_surface" |
Provides both |
agentic_quality |
"complexity", "coupling", "hotspots" |
Comprehensive assessment |
Each tool runs a reasoning agent that plans, searches, analyzes graph relationships, and synthesizes an answer. Not a search result—an answer.
View Agent Context Gathering Flow - Interactive diagram showing how agents use graph tools to gather context.
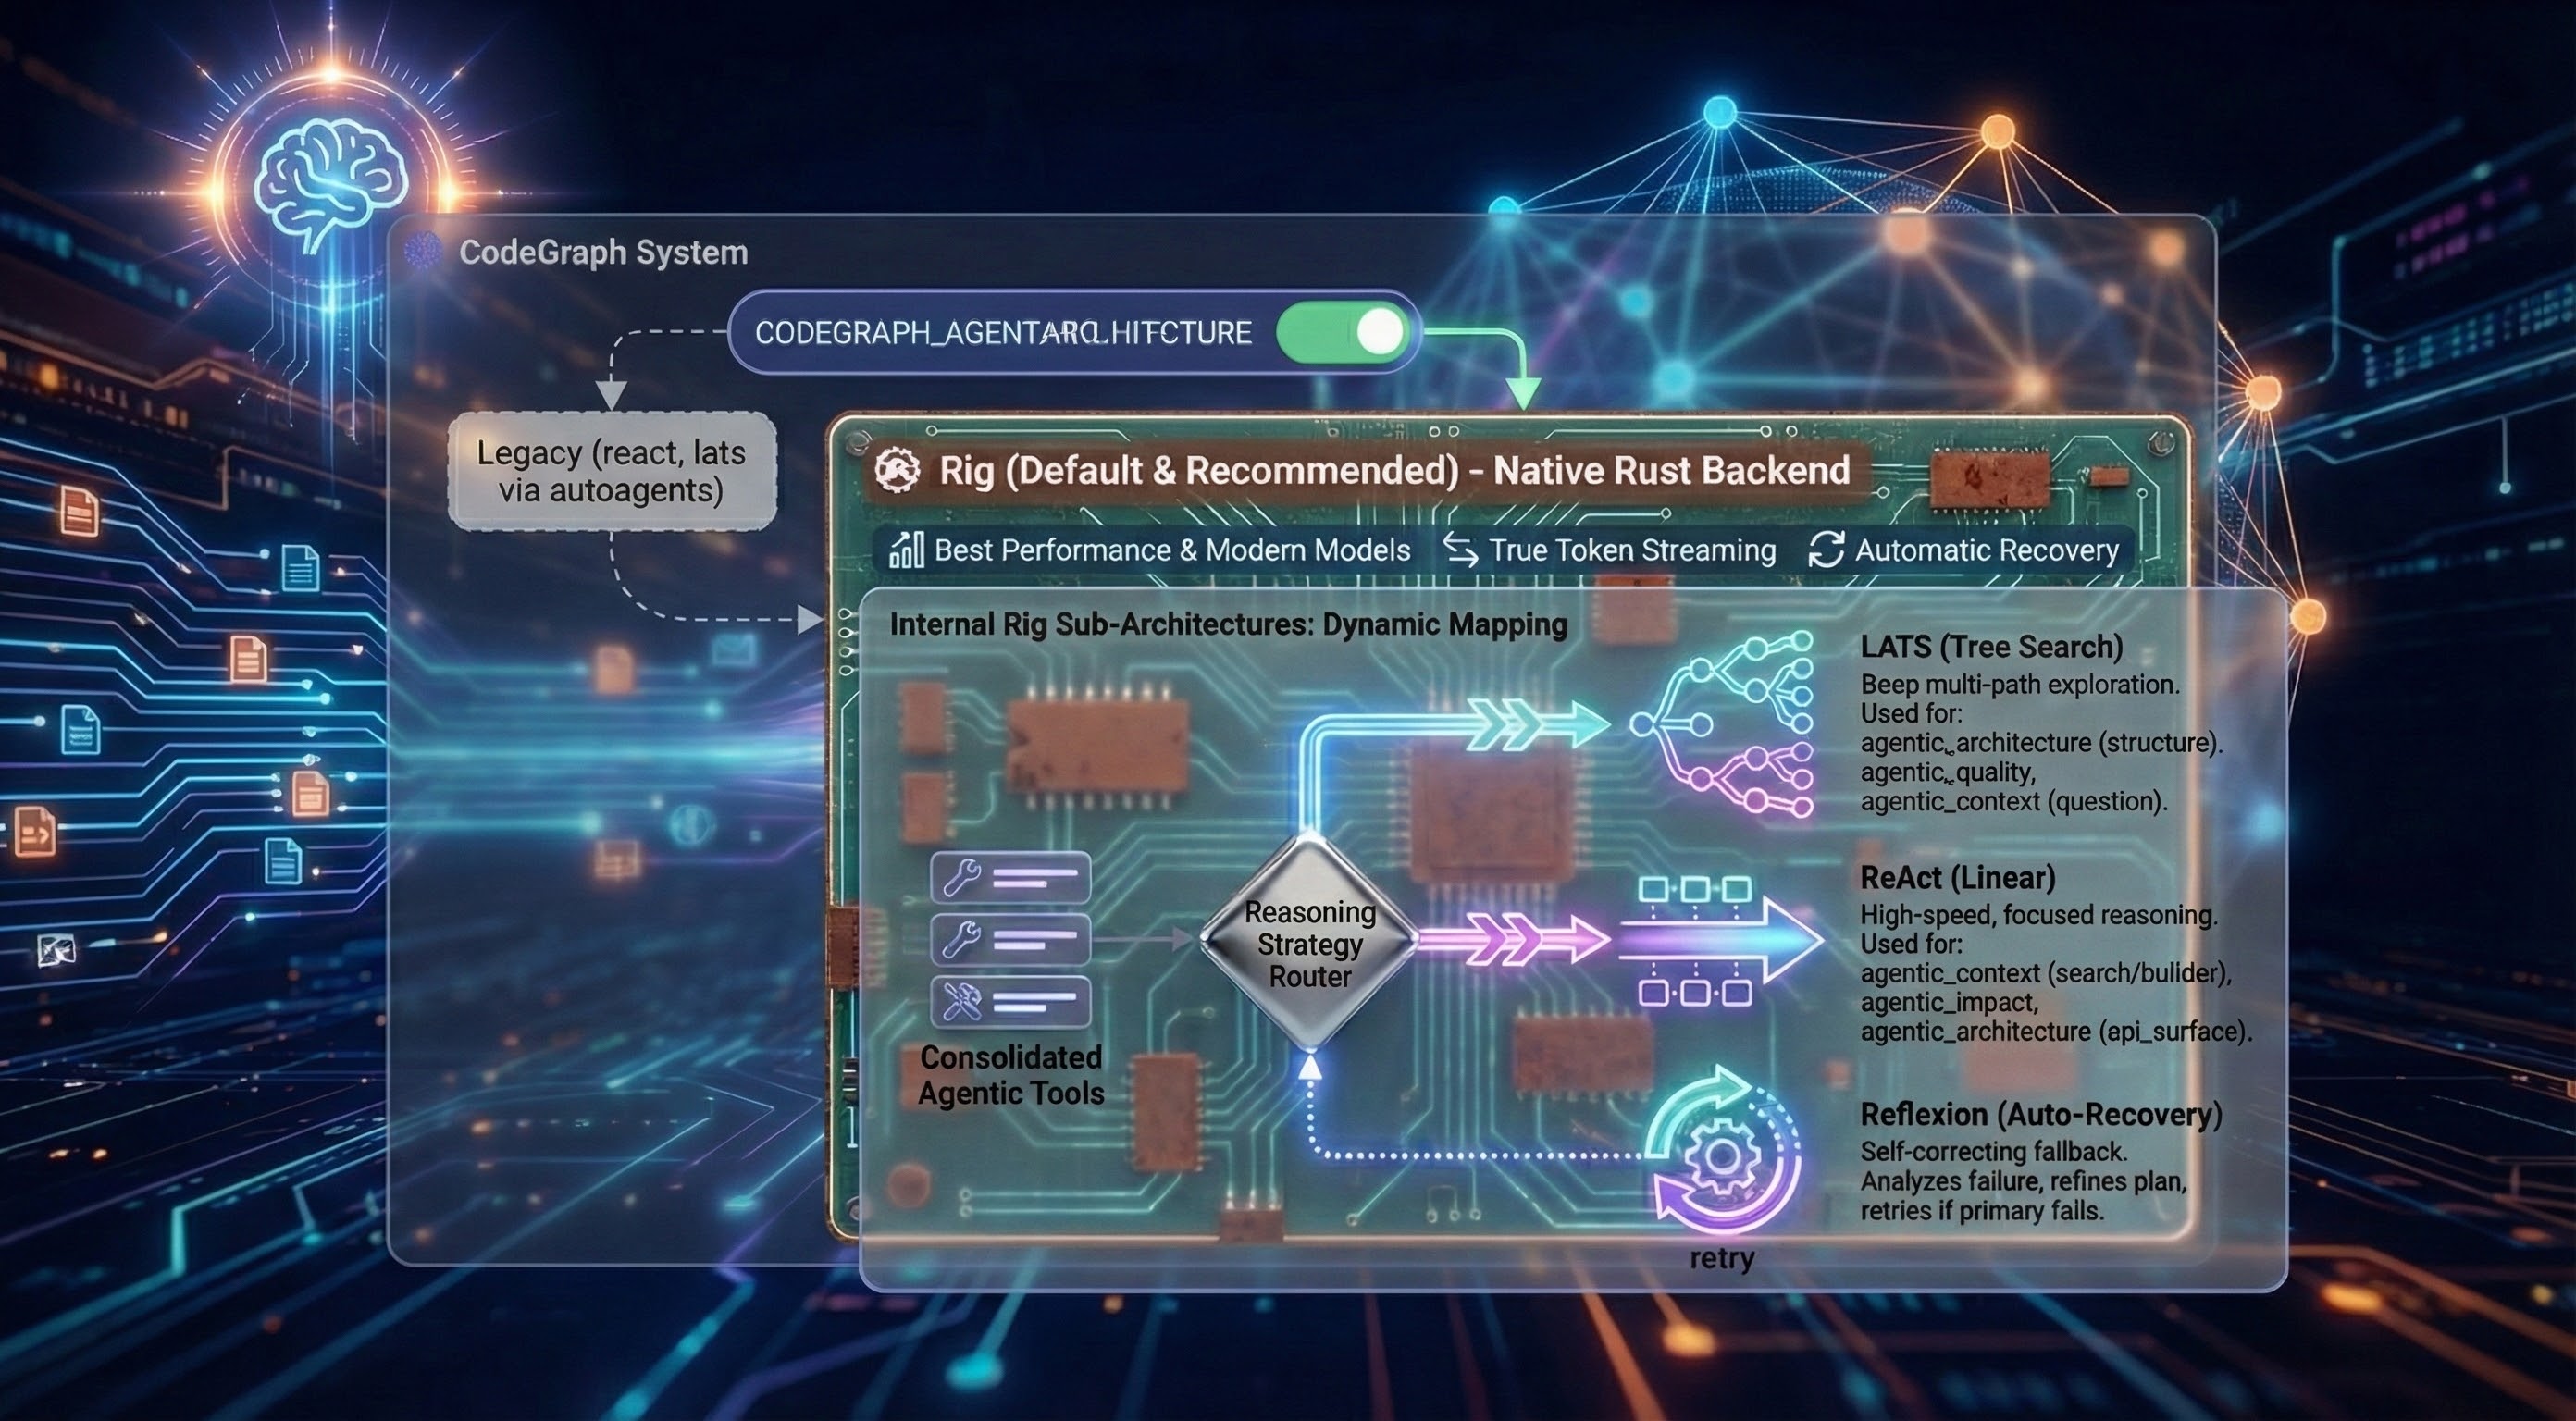
Agent Architectures
CodeGraph's agents are built on the Rig framework. The agent that runs is selected at runtime with CODEGRAPH_AGENT_ARCHITECTURE (in .env or the environment):
react(default;rigis accepted as an alias): a tool-calling loop over the graph tools.lats: tree search over candidate reasoning steps. It does not call the graph tools, so its answers are not grounded in the index.reflexion: ReAct wrapped in a retry that feeds the previous error back to the agent.
Whichever agent is selected, a failed run is retried automatically with the error as context.
# Default: ReAct
./codegraph start stdio

# Tree search over reasoning steps
CODEGRAPH_AGENT_ARCHITECTURE=lats ./codegraph start stdio
All agents serve the same 4 consolidated agentic tools and use tier-aware prompting.
3. Tier-Aware Intelligence
Here's something clever: CodeGraph automatically adjusts its behavior based on the LLM's context window that you configured for the codegraph agent.
Running a small local model? Get focused, efficient queries.
Using a model with 200K context? Get comprehensive, exploratory analysis.
Using gpt-6, Opus-5.5 or Grok-4.7 with 1-2M context? Get detailed analysis with intelligent result management.
The Agent only uses the amount of steps that it requires to produce the answer so tool execution times vary based on the query and amount of data indexed in the database.
During development the agent used 3-6 steps on average to produce answers for test scenarios.
The Agent is stateless it only has conversational memory for the span of tool execution it does not accumulate context/memory over multiple chained tool calls this is already handled by your client of choice, it accumulates that context so codegraph needs to just provide answers.
| Your Model | CodeGraph's Behavior |
|---|---|
| < 50K tokens | Terse prompts, max 3 steps |
| 50K-150K | Balanced analysis, max 5 steps |
| 150K-500K | Detailed exploration, max 6 steps |
| > 500K (gpt-6, etc.) | Comprehensive analysis, max 8 steps |
Hard cap: Maximum 8 steps regardless of tier. This prevents runaway costs and context overflow while still allowing thorough analysis.
Same tool, automatically optimized for your setup.
4. Context Overflow Protection
CodeGraph includes multi-layer protection against context overflow—preventing expensive failures when tool results exceed your model's limits.
Per-Tool Result Truncation:
- Each tool result is limited based on your configured context window
- Large results (e.g., dependency trees with 1000+ nodes) are intelligently truncated
- Truncated results include
_truncated: truemetadata so the agent knows data was cut - Array results keep the most relevant items that fit within limits
Context Accumulation Guard:
- Monitors total accumulated context across multi-step reasoning
- Fails fast with clear error message if accumulated tool results exceed safe threshold
- Threshold: 80% of context window × 4 (conservative estimate for token overhead)
Configure via environment:
# CRITICAL: Set this to match your agent's LLM context window
CODEGRAPH_CONTEXT_WINDOW=128000  # Default: 128K

# Per-tool result limit derived automatically: context_window × 2 bytes
# Accumulation limit derived automatically: context_window × 4 × 0.8 bytes
Why this matters: Without these guards, a single agentic_impact query on a large codebase could return 6M+ tokens—far exceeding most models' limits and causing expensive failures.
5. Hybrid Search That Actually Works
We don't pick sides in the "embeddings vs keywords" debate. CodeGraph combines:
- 70% vector similarity (semantic understanding)
- 30% lexical search (exact matches matter)
- Graph traversal (relationships and context)
- Optional reranking (cross-encoder precision)
The result? You find handleUserAuth when you search for "login logic"—but also when you search for "handleUserAuth".
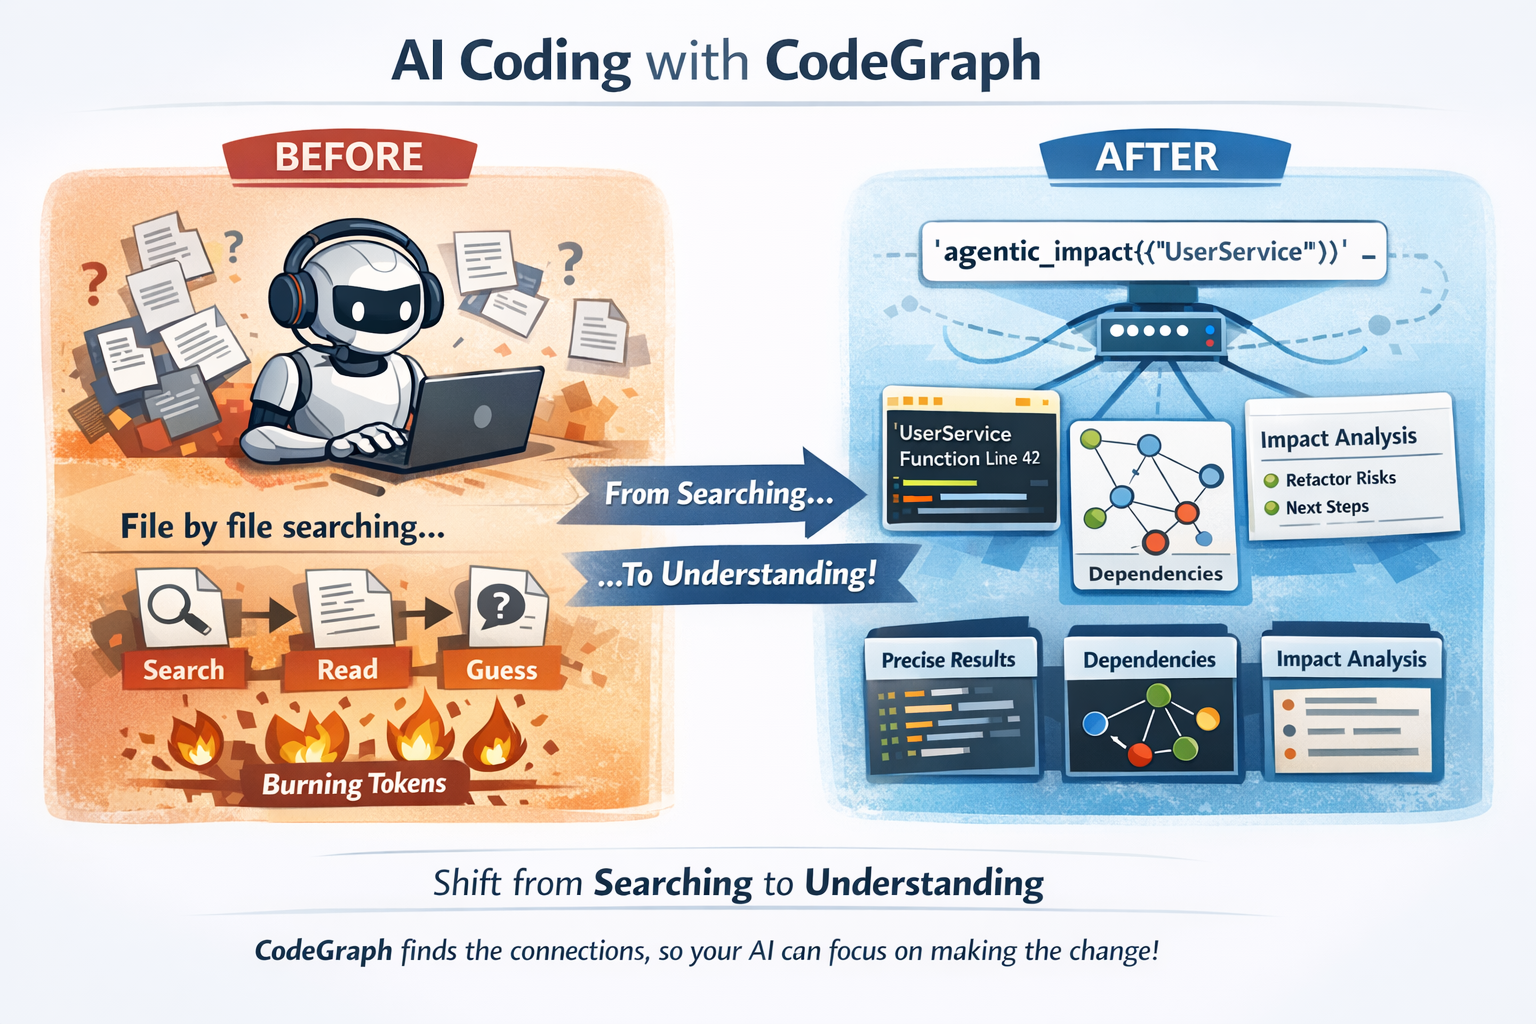
Why This Matters for AI Coding
When you connect CodeGraph to Claude Code, Cursor, or any MCP-compatible agent:
Before: Your AI reads files one by one, grepping around, burning tokens on context-gathering.
After: Your AI calls agentic_impact({"query": "UserService"}) and instantly knows what breaks if you refactor it.
This isn't incremental improvement. It's the difference between an AI that searches your code and one that understands it.
Why this is powerful for code agents
CodeGraph shifts the cognitive load (search + relevance + dependency reasoning) into CodeGraph’s agentic tools, so your code agent can spend its context budget on making the change, not discovering what to change.
What an agentic tool returns (example)
agentic_impact returns structured output (file paths, line numbers, and bounded snippets/highlights) plus analysis:
{
  "analysis_type": "dependency_analysis",
  "query": "RigAgentBuilder",
  "structured_output": {
    "analysis": "…what depends on RigAgentBuilder and why…",
    "highlights": [
      { "file_path": "crates/codegraph-mcp-rig/src/agent/builder.rs", "line_number": 48, "snippet": "pub struct RigAgentBuilder { … }" }
    ],
    "next_steps": ["…"]
  },
  "steps_taken": "5",
  "tool_use_count": 5
}
What a code agent would otherwise have to do
Without CodeGraph’s agentic tools, a code agent typically needs multiple “single-purpose” calls to reach the same confidence:
- search for the symbol (often multiple strategies: text + semantic + ripgrep-style search)
- open and read multiple files (definition + usages + callers + related modules)
- reconstruct dependency/call graphs mentally from partial evidence
- repeat when a guess is wrong (more reads, more tokens)
This burns context quickly: reading “just” a handful of medium-sized files + surrounding context can easily consume tens of thousands of tokens, and larger repos can push into hundreds of thousands depending on how much code gets pulled into context.
With CodeGraph, the agent gets pinpointed locations and relationships (plus bounded context) and can keep far more of the context window available for planning and implementing changes.
Quick Start
1. Install
# Clone and build with all features
git clone https://github.com/Jakedismo/codegraph-rust
cd codegraph-rust
./install-codegraph-full-features.sh
macOS faster builds (LLVM lld)
If you develop on macOS, you can opt into LLVM's lld linker for faster linking:
# Install LLVM so ld64.lld is on PATH (Homebrew)
brew install llvm

# Use the repo-provided Makefile targets
make build-llvm
make test-llvm
2. Configure Your Providers
CodeGraph needs an embedding model for indexing and an LLM for the agentic tools. Put the
settings in a .env file in your project (or export them); codegraph init loads it.
# Embeddings
CODEGRAPH_EMBEDDING_PROVIDER=ollama          # ollama | lmstudio | jina | openai | onnx
CODEGRAPH_EMBEDDING_MODEL=qwen3-embedding:0.6b
CODEGRAPH_EMBEDDING_DIMENSION=1024

# Agent LLM
CODEGRAPH_LLM_PROVIDER=anthropic             # ollama | lmstudio | anthropic | openai | xai | openai-compatible
CODEGRAPH_LLM_MODEL=claude-sonnet-4
CODEGRAPH_CONTEXT_WINDOW=200000              # your model's real limit; selects the prompt tier
ANTHROPIC_API_KEY=sk-ant-...
Set the model explicitly: without one the agent requests its provider's built-in default.
The same settings can live in the [llm] section of a config file instead (see
Configuration); environment variables win. .env.example lists every
supported variable, and AI_PROVIDERS.md has per-provider examples.
3. Database
There is nothing to start. SurrealDB runs embedded inside codegraph, and each project gets
its own SurrealKV store at <project>/.codegraph/db, created with the bundled schema
(schema/codegraph_v2.surql) the first time you index. The directory is written with a.gitignore, so it stays out of version control.
Because the store is per project, one project's data never mixes with another's, and removing
a project's index is rm -rf <project>/.codegraph/db.
Only one process can hold a project's store open at a time. The MCP server opens it on its
first tool call and keeps it until it exits, so stop a running codegraph start before
running codegraph index on the same project, and connect one client per project.
A shared SurrealDB server (self-hosted or Surreal Cloud) is still supported for teams that want
one database: set CODEGRAPH_SURREALDB_URL and apply the schema yourself. See
Setting Up SurrealDB.
4. Initialize and Index Your Project
codegraph init /path/to/project
Init first offers Claude Code, Codex, both, or none for project-local hooks.
It preserves existing settings and skips the prompt when CodeGraph hooks are already
configured. Next it adds a managed # codegraph section to both AGENTS.md andCLAUDE.md, preserving other instructions, then recursively indexes the project.
The guidance directs agents to start exploration with CodeGraph's context, impact,
architecture and quality CLI tools and verify findings against current source.
For scripts, pass the hook choice explicitly; setup can also run without indexing:
codegraph init /path/to/project --hooks both --index-tier balanced
codegraph init /path/to/project --hooks none --no-index
# Existing index-only workflow, with explicit language filters:
codegraph index /path/to/project -r -l rust,typescript,python
--hooks none leaves existing hooks in place and still updates both instruction
files. Setup never modifies user-level harness configuration. Ensure codegraph
is on the harness's PATH and reload/review the project hooks after setup; see
init and hook details.
After indexing, python3 test_cli_agentic.py tests all four CLI agent tools with
the same eight questions as test_http_mcp.py, printing full answers and saving
responses/timings under test_output_cli/. Replay saved answers without new queries
with python3 test_cli_agentic.py --replay test_output_cli. See
CLI testing options.
🔒 Security Note: Indexing automatically respects
.gitignoreand filters out common secrets patterns (.env,credentials.json,*.pem, API keys, etc.). Your secrets won't be embedded or exposed to the agent.
5. Connect to Claude Code
Add to your MCP config:
{
  "mcpServers": {
    "codegraph": {
      "command": "/full/path/to/codegraph",
      "args": ["start", "stdio", "--watch"]
    }
  }
}
That's it. Your AI now understands your codebase.
Agent CLI accuracy by indexing tier
The CLI evaluation uses the same eight questions as the HTTP MCP test, defined in
agentic_test_cases.py. They cover configuration loading,
prompt selection, caching, dependencies, call chains, architecture, public APIs and
complexity across all four agent tools. test_cli_agentic.py
saves full responses for manual comparison with source.
The fast entry below predates the current model-aware tokenizer/context/chunk policy.
Future tier comparisons should use the same current input policy and model settings;
the historical entry remains a record of that run.
| Indexing tier | LLM / request model | Evaluation date | CLI response checks | Manual accuracy findings |
|---|---|---|---|---|
fast |
gpt-6-luna (confirmed by the project owner; not captured by the runner) |
2026-10-06 | 8/8 OK |
Mixed: useful findings, incomplete answers and at least two source-confirmed incorrect answers; no overall accuracy score assigned |
balanced |
gpt-6-luna (explicit request model) |
2026-10-06 | 8/8 OK |
Useful configuration/cache/call-chain answers and public-method list; incorrect direct-caller classification, incomplete hub results and metric caveats; no overall accuracy score assigned |
full |
gpt-6-luna (explicit request model) |
2026-10-06 | 7/8 OK, 1 TIMEOUT |
Source-aligned configuration, cache, call-chain and public-API answers with verified locations; weak substitute for the missing symbol; hub ranking unavailable and instability values unreliable; the tier-aware prompt case timed out twice; no overall accuracy score assigned |
OK measures command/response success, not factual correctness. It means the
command returned a valid JSON answer without a reported timeout or partial-result
marker. It does not require every inner graph tool to succeed. All eight fast-tier
responses passed this check despite factual mistakes. The response fieldtier: Massive describes the agent's context-window budget, independently of the
indexing tier.
Source review of the fast-tier answers found:
- Call chain (case 5): incorrect active implementation. The answer selected
the#[cfg(not(feature = "ai-enhanced"))]error stub forexecute_agentic_workflow
and concluded the workflow did not reach graph tools. The
AI-enabled implementation
createsGraphToolExecutorand invokes the Rig agent executor. The answer did not
distinguish the two conditional implementations. - Public API (case 7): incomplete API and incorrect usage conclusion. The answer
describedGraphToolExecutoras having no direct usage and suggested changes were
isolated and low-risk. Its public methods
include constructors,execute, cache controls and tool metadata accessors; it is
used by both the server workflow
and the Rig tool factory. - LRU cache (case 3): useful but incomplete. The answer correctly identified
tool-result caching by function and parameters, but did not explain the cache-hit,
miss, eviction or clearing behavior requested by the question. - Missing symbol (case 4): appropriately uncertain. The answer reported that
PromptSelectorcould not be found rather than inventing its dependencies. No
Rust definition with that name exists in the reviewed source; this question needs
that caveat when interpreting the results.
The balanced run 20261006_041913_884481 explicitly selected gpt-6-luna throughCODEGRAPH_LLM_MODEL. All eight commands returned answers in 462.8 seconds.
The stored index reported 250 files, 22,496 nodes, 48,224 edges and 22,496 chunks,
with embedding and semantic stages ready. It used Ollama qwen3-embedding:0.6b
with 1,024-dimensional vectors and a resolved 32,768-token serving context.
Full balanced answers, run details and source review
are retained separately from the README summary.
Source review of the explicit-model balanced answers found:
- Configuration, prompts and cache (cases 1–3): useful source-aligned explanations.
The answers covered multiple configuration systems, dotenv/TOML precedence, the
active Rig prompt builder, and cache hits/misses, successful-result insertion,
eviction, clearing and lack of TTL. The prompt answer also identified separate
server/Rig tier-resolution paths. Its claim of an eight-round "hard cap" needs
qualification: the public builder override
accepts other values. - Missing symbol and call chain (cases 4–5): appropriate caveats and active flow.
The answer did not inventPromptSelector, stated its alternate target, and
distinguished the AI-enabled workflow from the feature-disabled stub. It traced
the active path through Rig tools,CountingExecutor,GraphToolExecutorandGraphFunctionsto SurrealDB. - Public API (case 7): complete method names, incorrect caller classification.
The answer listed all ten public inherent methods and recognized real consumers.
However, it called the eight Rig tool adapters direct callers ofGraphToolExecutor::execute. They callCountingExecutor::execute,
which then delegates toGraphToolExecutor; those adapters are indirect callers. - Architecture/metrics (cases 6–7): incomplete evidence despite
OK. Hub queries
failed five times across these cases with SurrealDB'sarray::concat()
1,048,576-byte limit. The architecture answer disclosed the missing hub ranking
and flagged inconsistent coupling values and misleading zero struct-level counts.
For example, reported Ca=19/Ce=66 with instability=0.0 does not match the intended
Ce/(Ca+Ce) ratio. These metrics cannot support a reliable stability conclusion. - Complexity (case 8): useful reported ranking with measurement limits. The
answer rankedreconcile_projectfirst at complexity 108/risk 1,404. The
query computes risk as complexity × (incoming
dependency-edge count + 1), after preselecting high-complexity candidates. It is
a heuristic, not a calibrated failure probability or a guaranteed global risk
ranking; incoming edge counts also need not equal distinct caller counts.
The full run 20261006_060847_378162 also selected gpt-6-luna explicitly. Seven
commands returned answers and case 2 (tier-aware prompts) hit the 300-second deadline;
the run took 648.4 seconds including that timeout. The stored index reported
238 files, 34,494 nodes, 104,224 edges and 34,494 chunks, marked complete with
embedding and semantic stages ready, and includes dataflow, LSP, module and
documentation analyzer output. Embedding settings match the balanced run.
Full answers, run details and source review
are retained separately.
Source review of the full-tier answers found:
- Configuration, cache, call chain and public API (cases 1, 3, 5, 7): source-aligned,
with every checked location matching. The configuration answer inventories the
main loader, dotenv initialization, the agent's[llm]overlay, the MCP-core and
advanced-config loaders, a JSON pipeline loader and direct environment readers;
its list of callers of the main loader is incomplete. The cache answer covers hits,
misses, post-truncation insertion, eviction and clearing, with one line range off
by a function. The call-chain answer follows the AI-enabled workflow rather than
the feature-disabled stub. The API answer lists all ten public methods and, unlike
the balanced answer, correctly describes the Rig adapters as indirect callers
throughCountingExecutor. - Tier-aware prompts (case 2): no answer. The command timed out in the run and in
a single-case rerun. In both, the agent finished its tool calls within a minute and
the remaining time was spent waiting for a model response. The cause was not
established; the balanced run answered this case in 72 seconds. - Missing symbol (case 4): honest about absence, weak substitute. The answer says
PromptSelectordoes not exist, then analyzesprompt_selection, the
hook-selection prompt ofcodegraph init, which is unrelated to tier prompts. Its
statements about that function are correct. - Architecture (case 6): accurate structure, no hub ranking. Both hub queries
failed with the samearray::concat()1,048,576-byte limit as in the balanced run,
and the failure reproduces when the
function is called directly on this index. The
answer discloses the gap and flags that instability is reported as0.0for nodes
with outgoing dependencies. Direct calls for five sampled nodes all returned0.0: the expression divides two integer counts,
and integer division truncates the ratio.
Coupling counts are unaffected, but stability conclusions cannot be drawn. - Complexity (case 8): consistent arithmetic, different ranking. All 20 risk
scores match complexity × (incoming dependency-edge count + 1). Parserwalk
functions now lead (Rust walker: risk 3,131 from complexity 31 and 100 incoming
edges) andreconcile_projectdrops to eighth, because the full index has more
than twice the edges and the query counts edge rows, not distinct callers.
All seven completed full-tier cases and all eight balanced cases logged typed-answer parse warnings; the server synthesized
structured evidence from tool traces instead. The runner accepted the resulting
JSON responses. Neither those fallbacks nor inner-tool errors are a factual accuracy
score. The initial balanced diagnostic run 20261006_041408_086869 is retained
separately because it did not explicitly select the intended request model.
The fast baseline is local run 20261006_013512_392882. Its indexing tier comes from
the test session and its gpt-6-luna model label from the project owner; the runner
does not capture either setting automatically. During balanced evaluation, source review found that the Rig adapter
selected its model from CODEGRAPH_LLM_MODEL, then CODEGRAPH_AGENT_MODEL; at that time
it did not read the core configuration's CODEGRAPH_MODEL, so with only the latter set the
OpenAI Rig path defaulted to requesting gpt-4o. (The adapter has since been changed to
fall back to CODEGRAPH_MODEL and then [llm] model.) The fast run's saved responses do not
record the request model, so that label rests on the owner's confirmation.
Set CODEGRAPH_LLM_MODEL explicitly for reproducible agent comparisons. These labels
identify configured/requested models; the runner does not attest provider-side routing.
These observations do not isolate the effect of indexing tier from model reasoning
or establish a numerical accuracy rate. The three runs also differ in checkout,
installed binary and file count.
For subsequent comparisons, keep questions, model, agent context budget and inference
settings consistent; record the source revision and index configuration, and disclose
changes between runs. Review source locations, active conditional code, completeness
and unsupported conclusions before assigning accuracy scores.
The Architecture
View Interactive Architecture Diagram - Explore the full workspace structure with clickable components and layer filtering.
┌─────────────────────────────────────────────────────────────────┐
│                         Claude Code / MCP Client                │
└─────────────────────────────────┬───────────────────────────────┘
                                  │ MCP Protocol
                                  ▼
┌─────────────────────────────────────────────────────────────────┐
│                        CodeGraph MCP Server                     │
│  ┌───────────────────────────────────────────────────────────┐  │
│  │                    Agentic Tools Layer                    │  │
│  │  ┌─────────┐ ┌─────────┐ ┌─────────┐ ┌─────────────────┐  │  │
│  │  │  ReAct  │ │  LATS   │ │Reflexion│ │ Tool Execution  │  │  │
│  │  │  (Rig)  │ │  (Rig)  │ │  (Rig)  │ │    Pipeline     │  │  │
│  │  └────┬────┘ └────┬────┘ └────┬────┘ └────────┬────────┘  │  │
│  └───────┼───────────┼───────────┼───────────────┼───────────┘  │
│          └───────────┴───────────┴───────────────┘              │
│                              │                                  │
│  ┌───────────────────────────┼───────────────────────────────┐  │
│  │                  Inner Graph Tools                        │  │
│  │  ┌──────────────┐ ┌──────────────┐ ┌──────────────────┐   │  │
│  │  │ Transitive   │ │    Call      │ │     Coupling     │   │  │
│  │  │ Dependencies │ │   Chains     │ │     Metrics      │   │  │
│  │  └──────────────┘ └──────────────┘ └──────────────────┘   │  │
│  │  ┌──────────────┐ ┌──────────────┐ ┌──────────────────┐   │  │
│  │  │   Reverse    │ │    Cycle     │ │       Hub        │   │  │
│  │  │    Deps      │ │  Detection   │ │      Nodes       │   │  │
│  │  └──────────────┘ └──────────────┘ └──────────────────┘   │  │
│  └───────────────────────────┬───────────────────────────────┘  │
└──────────────────────────────┼──────────────────────────────────┘
                               │
┌──────────────────────────────┼──────────────────────────────────┐
│                         SurrealDB                               │
│  ┌─────────────┐  ┌─────────────┐  ┌─────────────────────────┐  │
│  │   Nodes     │  │    Edges    │  │   Chunks + Embeddings   │  │
│  │  (AST +     │  │  (calls,    │  │   (HNSW vector index)   │  │
│  │   FastML)   │  │   imports)  │  │                         │  │
│  └─────────────┘  └─────────────┘  └─────────────────────────┘  │
│                                                                 │
│  ┌────────────────────────────────────────────────────────────┐ │
│  │              SurrealQL Graph Functions                     │ │
│  │   fn::semantic_search_nodes_via_chunks                     │ │
│  │   fn::semantic_search_chunks_with_context                  │ │
│  │   fn::get_transitive_dependencies                          │ │
│  │   fn::trace_call_chain                                     │ │
│  │   fn::calculate_coupling_metrics                           │ │
│  └────────────────────────────────────────────────────────────┘ │
└─────────────────────────────────────────────────────────────────┘
Key insight: The agentic tools don't just call one function. They reason about which graph operations to perform, chain them together, and synthesize results. A single agentic_impact call might:
- Search for the target component semantically
- Get its direct dependencies
- Trace transitive dependencies
- Check for circular dependencies
- Calculate coupling metrics
- Identify hub nodes that might be affected
- Synthesize all findings into an actionable answer
Supported Languages
CodeGraph uses tree-sitter for initial parsing and enhances results with FastML algorithms and supports:
Rust • Python • TypeScript • JavaScript • Go • Java • C++ • C • Swift • Kotlin • C# • Ruby • PHP • Dart
Provider Flexibility
Embeddings
Use any model with dimensions 384-4096:
- Local: Ollama, LM Studio, ONNX Runtime
- Cloud: OpenAI, Jina AI
LLM (for agentic reasoning)
- Local: Ollama, LM Studio
- Cloud: Anthropic Claude, OpenAI, xAI Grok, OpenAI Compliant
Database
- SurrealDB 3.x embedded (SurrealKV, one store per project, no server to run) with HNSW vector indexes
- Optional: a shared SurrealDB server or Surreal Cloud via
CODEGRAPH_SURREALDB_URL
Configuration
Building requires Rust 1.95 or newer and uses edition 2024. Direct registry
dependencies target current stable releases; Cargo.lock records the resolved graph. Bincode stays on 2.0.1, its last
functional release; 3.0.0 deliberately fails compilation. ONNX Runtime bindings use
the latest release candidate, 2.0.0-rc.13, because no stable 2.0 release exists.
The CLI loads project or user dotenv configuration before starting worker threads.
Library callers should initialize their environment at process startup; ConfigManager::load()
only reads configuration and never changes the process environment.
codegraph init configures the selected project and loads its environment before
indexing. codegraph config init is the separate command for creating global
application configuration; project init does not configure model providers.
Config files are read from ./.codegraph.toml (project) and then ~/.codegraph/config.toml
(user); a .env in the working directory and CODEGRAPH_* environment variables override
them:
[embedding]
provider = "ollama"
model = "qwen3-embedding:0.6b"
dimension = 1024

[llm]
provider = "anthropic"
model = "claude-sonnet-4"
context_window = 200000

[indexing]
tier = "fast"
The built-in agent resolves each LLM setting in three steps: the environment variable (a project .env counts), then the key in the config file's [llm] section, then a default. enabled = false in [llm] makes the agent ignore the section, and API keys are read from the environment only. codegraph config agent-status shows the provider, model and tier in effect; AI_PROVIDERS.md lists every variable and key.
Storage needs no configuration: the embedded per-project store is used unlessCODEGRAPH_SURREALDB_URL (plus the other CODEGRAPH_SURREALDB_* variables) points at a
server. CODEGRAPH_SCHEMA=v1 selects the original schema/codegraph.surql for new stores.
See INSTALLATION_GUIDE.md for complete configuration options.
Experimental graph schema (optional)
CodeGraph can run against an experimental SurrealDB graphdb-style schema (schema/codegraph_graph_experimental.surql) that is interoperable with the existing CodeGraph tools and indexing pipeline.
Compared to the default schema (schema/codegraph_v2.surql), the experimental schema is designed for faster and more efficient graph-query operations (traversals, neighborhood expansion, and tool-driven graph analytics) on large codebases.
To use it with the embedded store, set the flag before the project's store is first created
(or delete <project>/.codegraph/db and re-index):
CODEGRAPH_USE_GRAPH_SCHEMA=true
With a SurrealDB server, load the schema into a dedicated database once and point CodeGraph at it:
surreal sql --conn ws://localhost:3004 --ns ouroboros --db codegraph_experimental < schema/codegraph_graph_experimental.surql
CODEGRAPH_USE_GRAPH_SCHEMA=true
CODEGRAPH_GRAPH_DB_DATABASE=codegraph_experimental
Notes:
- The schema file defines HNSW indexes for multiple embedding dimensions (384–4096) so you can switch embedding models without reworking the DB.
- An existing store keeps the schema it was created with; switching schemas means a fresh store.
CODEGRAPH_GRAPH_DB_DATABASEonly applies in server mode.
Daemon Mode
Keep your index fresh automatically:
# With MCP server (recommended)
codegraph start stdio --watch

# Standalone daemon
codegraph daemon start /path/to/project --languages rust,typescript
Changes are detected, debounced, and re-indexed in the background.
With the embedded per-project store, use --watch: the watcher then runs inside the MCP
server process. A standalone daemon is a separate process and cannot share a project's store
with a running server, so use it only when no server is running for that project or when you
use a SurrealDB server.
What's Next
- More language support
- Cross-repository analysis
- Custom graph schemas
- Plugin system for custom analyzers
Philosophy
CodeGraph exists because we believe AI coding assistants should be augmented, not replaced. The best AI-human collaboration happens when the AI has deep context about what you're working with.
We're not trying to replace your IDE, your type checker, or your tests. We're giving your AI the context it needs to actually help.
Your codebase is a graph. Let your AI see it that way.
License
MIT
Links
- Installation Guide
- SurrealDB Cloud (free tier)
- Jina AI (free API tokens)
- Ollama (local models)
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found