model-switcher
Health Uyari
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Gecti
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Per-prompt model routing and offline cost tracking for Claude Code — keep simple prompts cheap, delegate complex work to a stronger model.
model-switcher



Per-prompt model routing and deterministic offline cost tracking for local Claude Code sessions.
Keep simple prompts cheap. Delegate complex work to a heavier model. Track turn and session cost offline.
model-switcher is an experimental Claude Code setup that scores every prompt locally before Claude sees it.
Simple prompts stay on your cheaper session model, such as Sonnet. Complex prompts are delegated to a heavy-task-* subagent running your configured heavier model, such as Fable 5.
After every response, the statusline shows the token cost of the current turn and the whole session, computed offline from the local Claude Code session transcript using your own pricing table.
Local routing is offline by default. Optional Jev evaluation can assess each request before routing, with a local fallback and inspectable logs.
Works with local Claude Code sessions: CLI, VS Code extension, and desktop local tabs. Does not apply to claude.ai cloud sessions.
Why this exists
Not every Claude Code prompt needs the most expensive model.
Some prompts are simple:
- "What does this function do?"
- "Explain this error"
- "Rename this variable"
- "Summarise this file"
Some prompts need a stronger model:
- "Refactor this module and add tests"
- "Debug this cross-file issue"
- "Migrate this auth flow"
- "Review this architecture and suggest changes"
model-switcher routes those differently inside local Claude Code sessions.
Use cheaper models for simple work, use stronger models when the task actually needs it, and keep a local view of session cost.
Demo
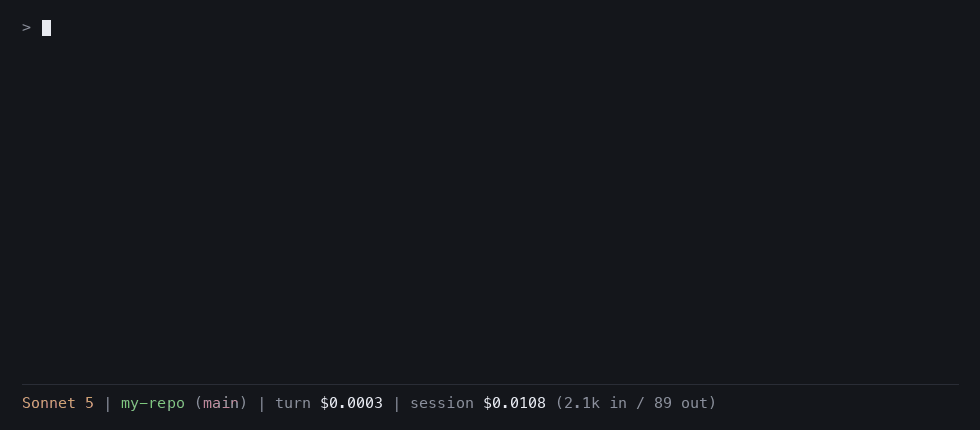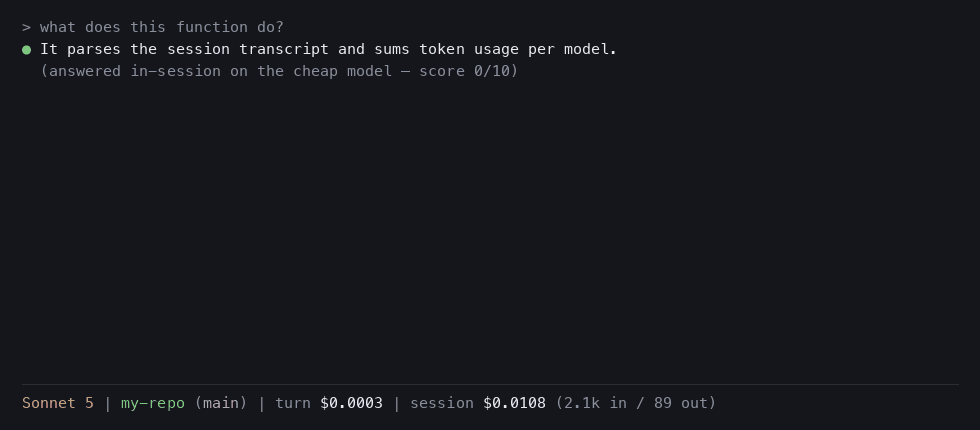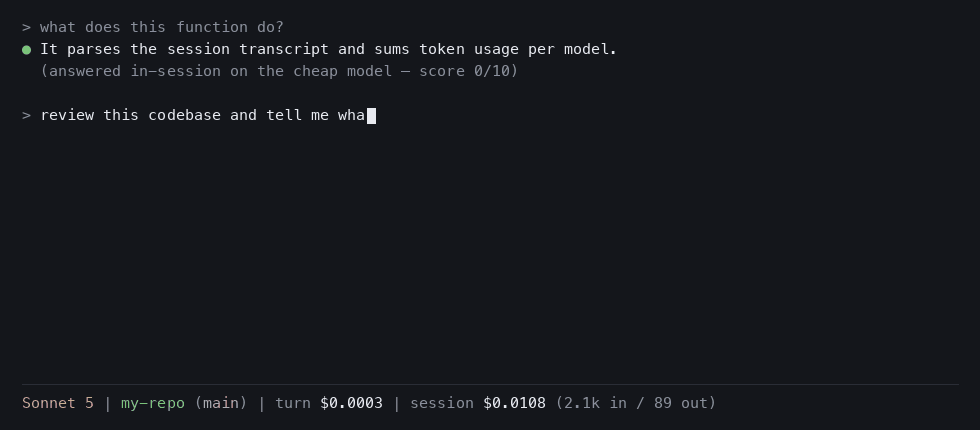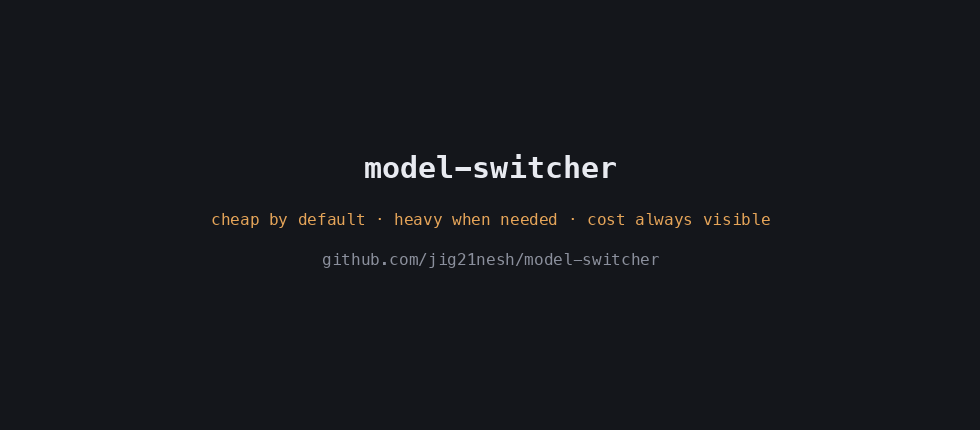
Scripted replay of a real captured session (prompts, agent spawn, and costs are from live transcripts).
Example statusline:
Sonnet 5 | Context: 45% used / 55% left | my-repo (main) | turn $0.0042 | session $0.19 (26.0k in / 1.0k out)
Example complex prompt:
User:   refactor the auth module, migrate the schema and add tests
Claude: Delegating this to the heavy-task-fable agent...
        [heavy-task-fable(Refactor auth module and add tests) runs]
When delegation happens, the statusline model name does not change — Claude Code has no hard per-prompt model switch. Instead, Claude spawns the configured heavy-task-* subagent (its name shows the model, e.g. heavy-task-fable) and relays its answer.
Installing
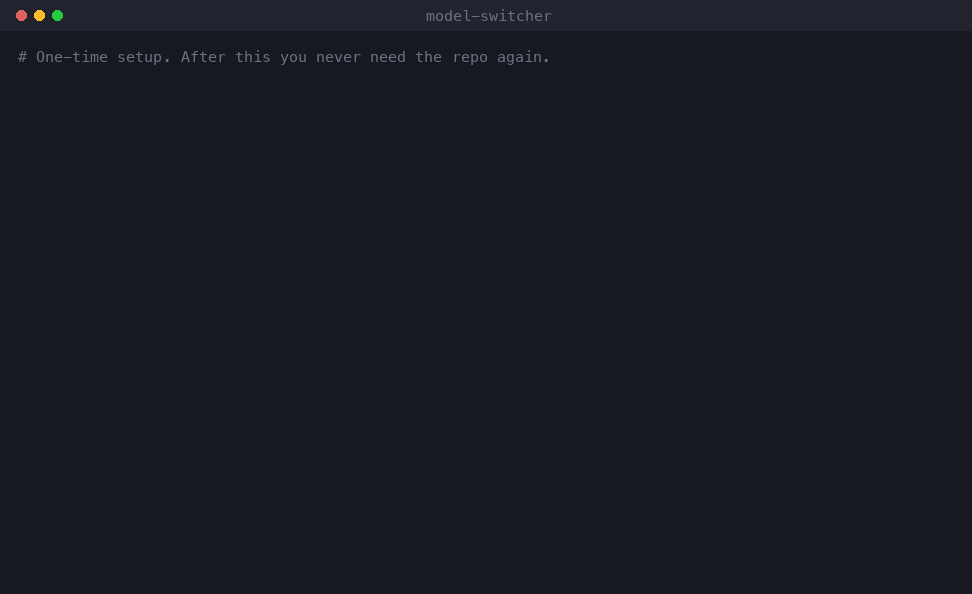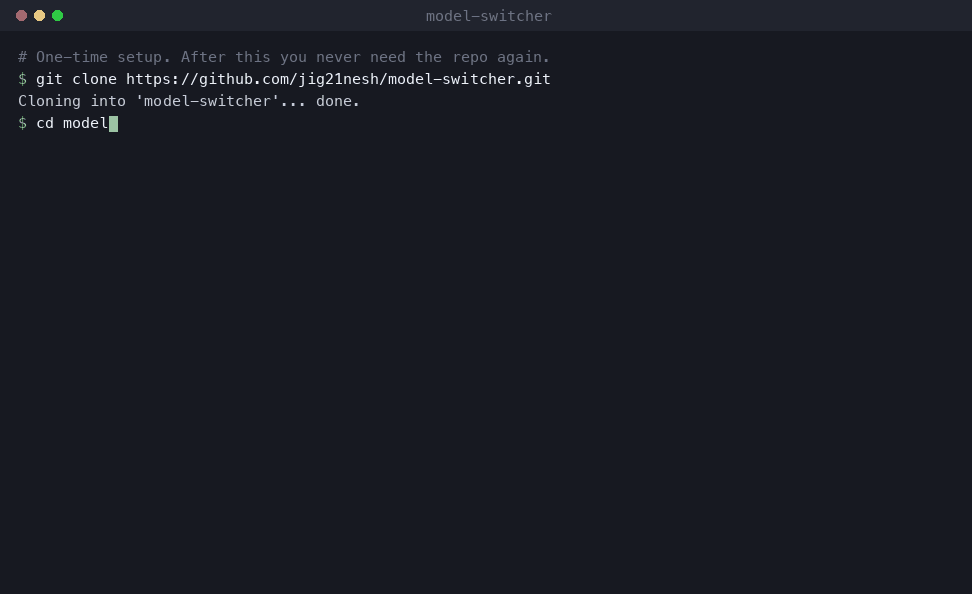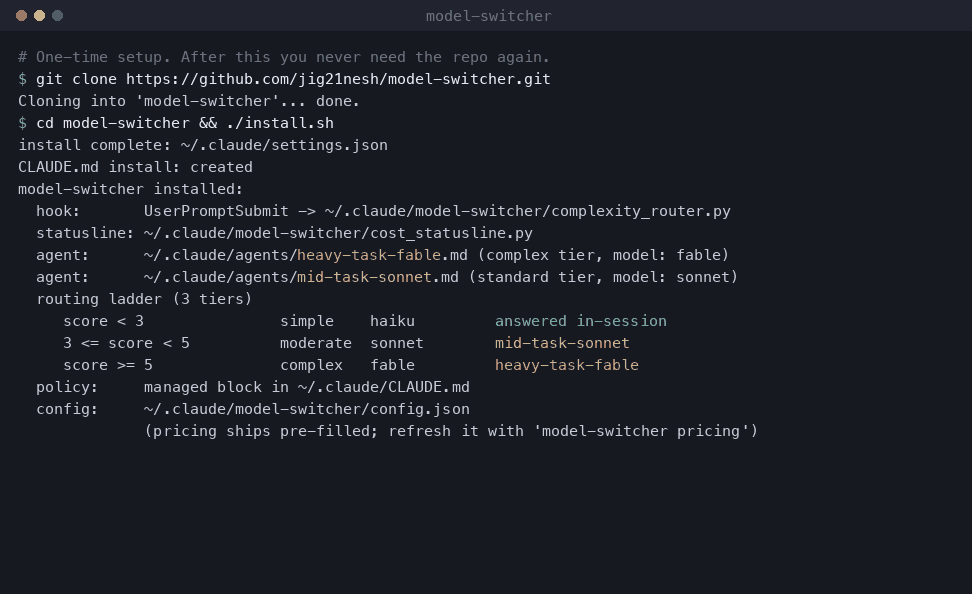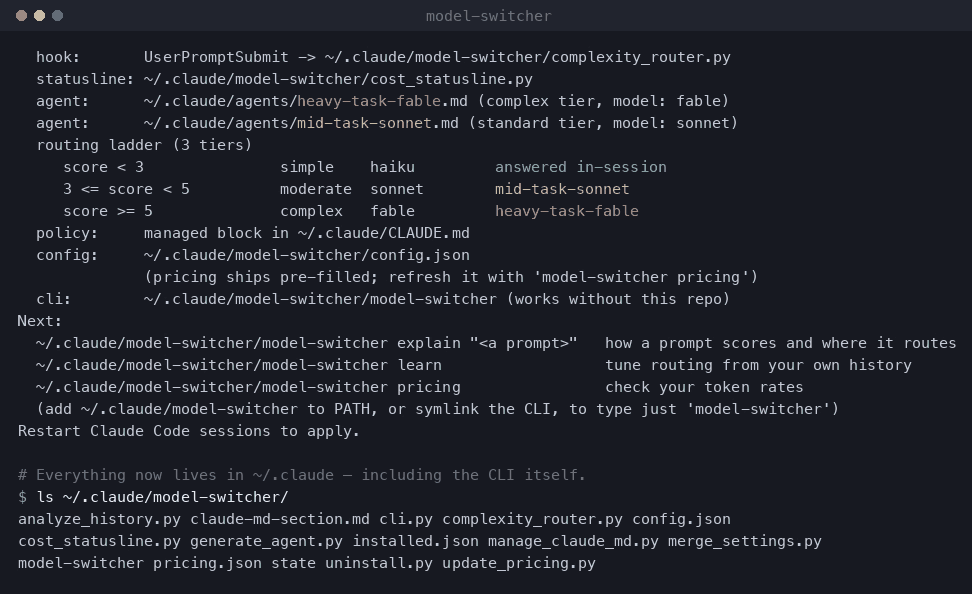
One command. The hook, statusline, both tier agents, the policy block and the model-switcher
command all land in ~/.claude — after which the repo is no longer needed.
Using it — there is nothing to run
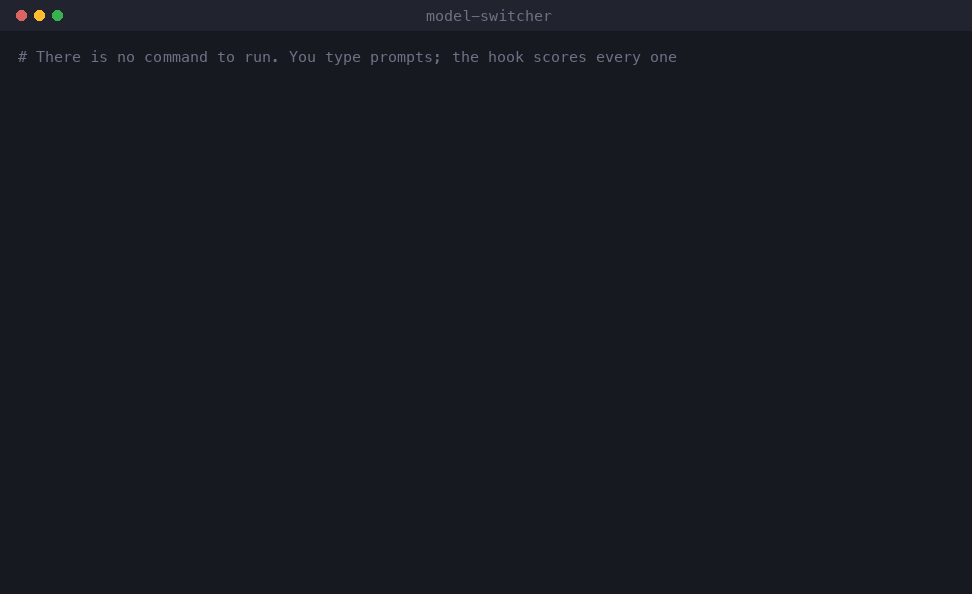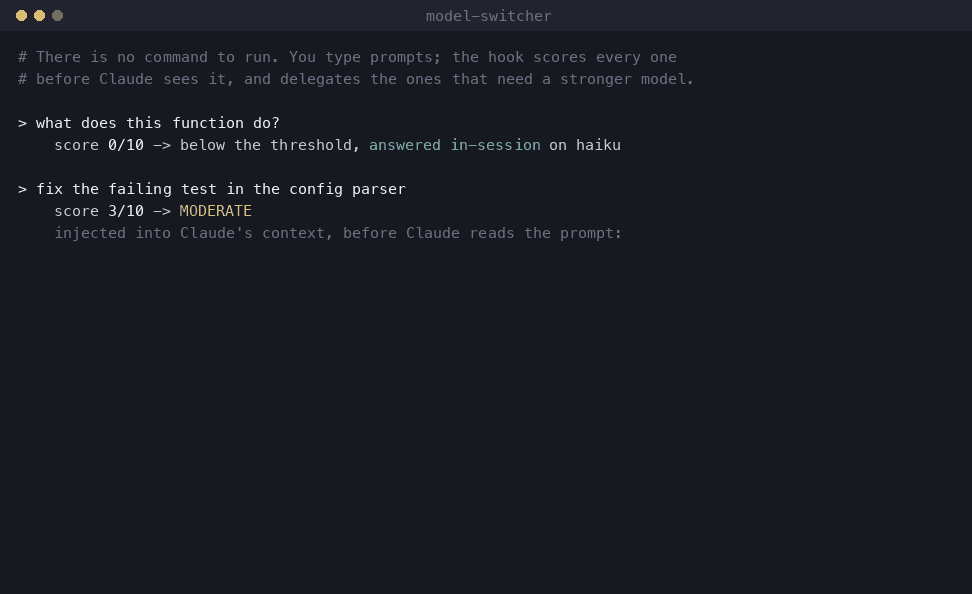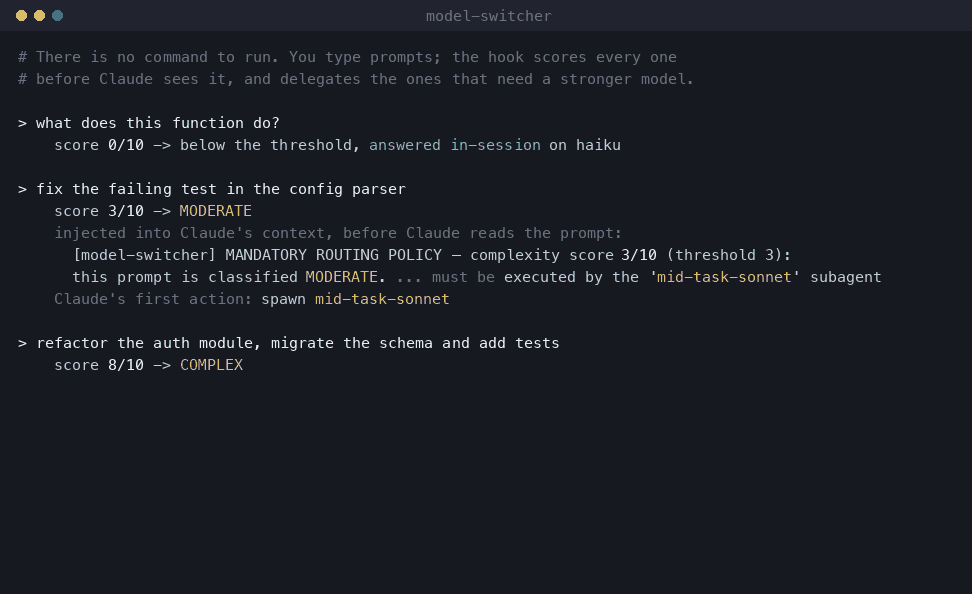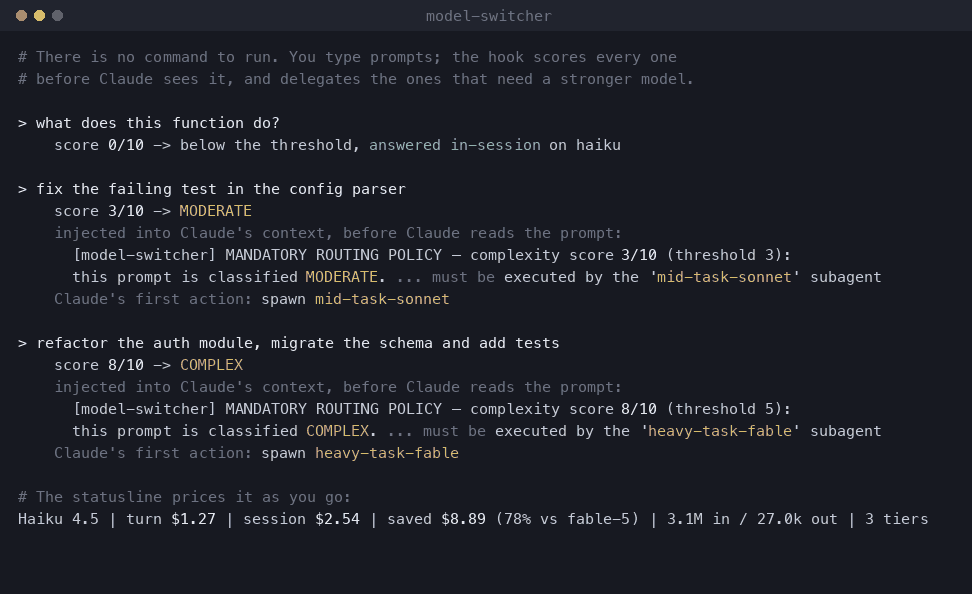
You never invoke model-switcher to route a prompt. You type prompts as you always have. TheUserPromptSubmit hook scores every one before Claude reads it, and injects a routing directive
only when the score clears a threshold. Simple prompts are answered in the session on your cheap
model; harder ones are delegated to mid-task-* or heavy-task-*.
The CLI, for maintenance only
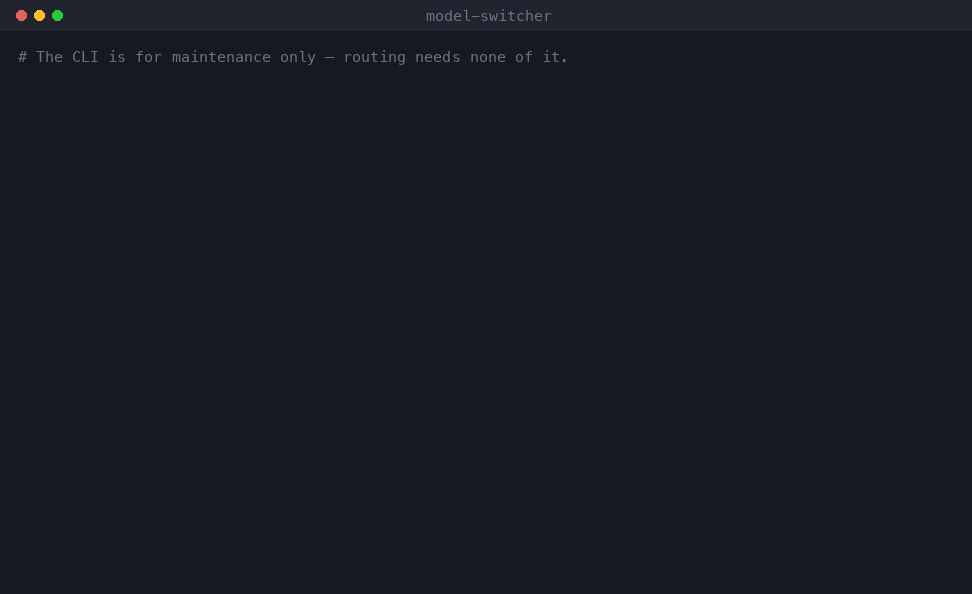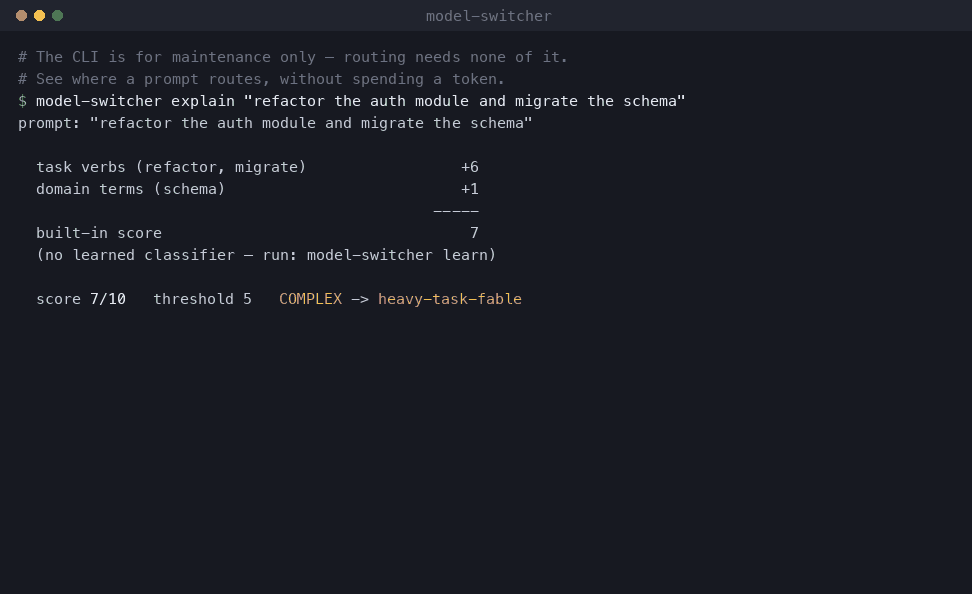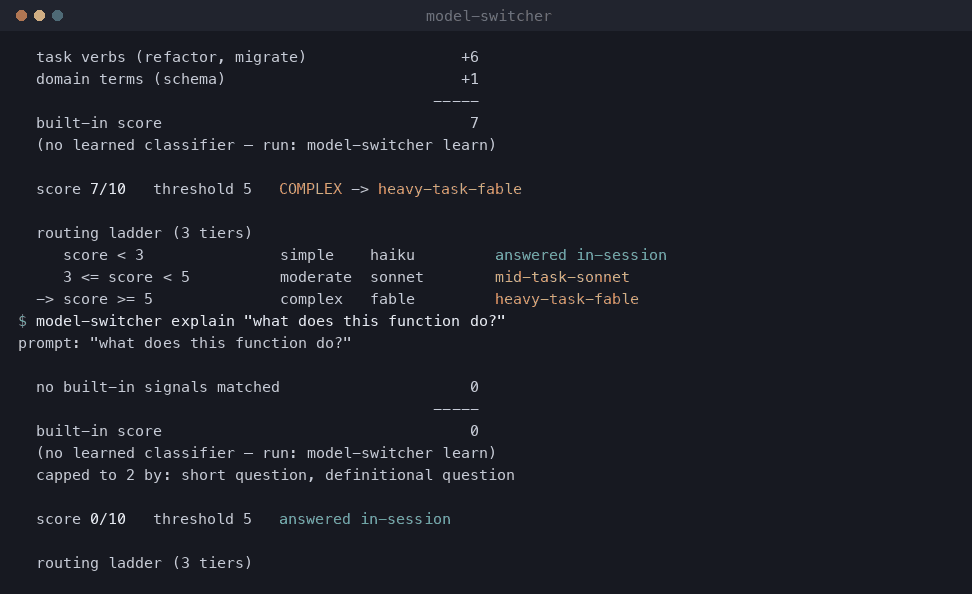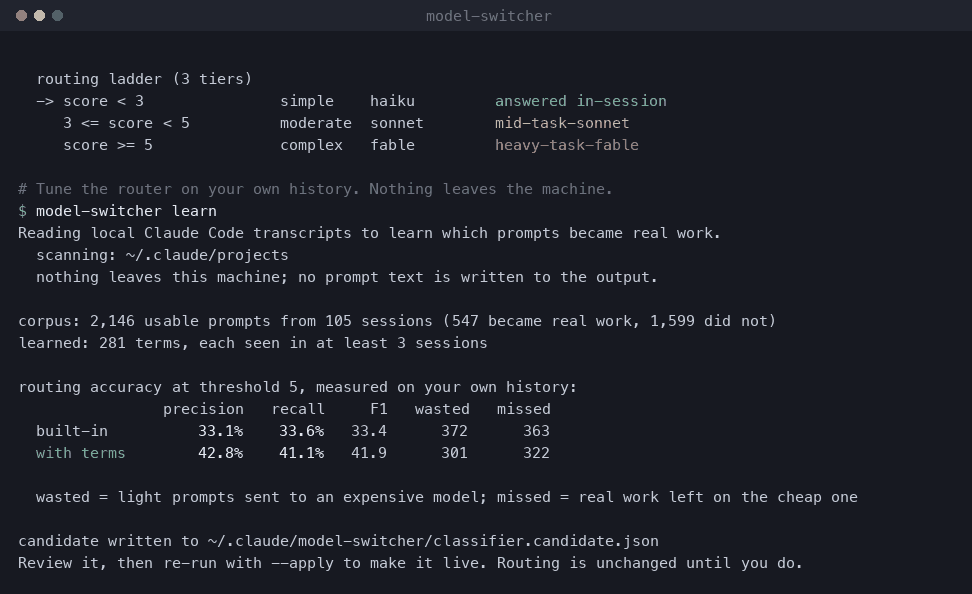
None of these are needed for routing to work — they are for inspecting and tuning it. explain
shows where a prompt routes and why, how close the call was and what would have changed it, before
you spend a token. tiers prints your routing ladder. learn tunes the router on your own history
and reports the accuracy change. classifier shows what that produced — how much of the learned
table is noise, and which of your projects taught it each word. tune shows what that history says
about your complexity.threshold. status reports what the install is configured to do and what is
wrong with it. pricing refreshes your rate table.
All three recordings replay genuine captured output — tools/capture_demo.sh runs the real
installer, the real hook and the real CLI in a sandbox, and tools/make_demo_gif.py types the
result back. In the session recording, every score and every directive comes from driving the
actual hook; only the > prompt framing and the indented labels are added. The learn term lists
are withheld because they derive from whatever the operator happened to be working on.
What it does
- Scores each prompt locally before Claude sees it
- Keeps simple prompts on your configured session model
- Delegates complex prompts to a
heavy-task-*subagent - Applies the same policy when Claude spawns its own agents — a
general-purposeagent handed complex work is rewritten onto the configured tier, so delegated work does not quietly escape the ladder - Includes a third tier on fresh installs: Opus between Sonnet and Fable, using
mid-task-opusfor moderate work - Names each subagent for its configured model, e.g.
heavy-task-fable, so the model is visible in the task line - Learns from your own history which prompts actually become work, and reports the accuracy change before you apply it
- Explains the local routing baseline without spending a token; optionally evaluates with Jev
- Tracks turn and session cost from the local transcript and every subagent this session spawned — priced by cache TTL, so 1-hour cache writes are not billed at the 5-minute rate
- Shows what routing saved, measured against the dearest model the session actually used — and shows nothing until a session has genuinely spanned two models
- Uses your own pricing table, refreshable with one command — no network calls from the statusline or local scorer
- Can be switched off globally or overridden per project, without uninstalling
- Preserves an existing custom statusline if you already have one
- Adds a marker-delimited routing policy block to
~/.claude/CLAUDE.md - Needs the repo only to install or upgrade — the CLI installs alongside everything else, and can even uninstall itself
What it does not do
- It does not directly switch the main Claude Code session model per prompt
- External evaluation is disabled unless you opt into Jev
- It does not calculate your official Anthropic bill
- It does not work in
claude.aicloud sessions - It does not provide a hard platform-level guarantee that Claude must delegate every complex prompt
[!IMPORTANT]
Claude Code hooks cannot directly switch the main session model per prompt.model-switcherworks by keeping the main session on a cheaper model and delegating complex tasks to a heavier subagent.
Who this is for
Developers who:
- Use Claude Code heavily
- Want better control over model cost
- Want simple prompts to stay cheap and complex prompts to use a stronger model
- Like experimenting with Claude Code hooks, subagents, and statusline commands
Quick start
git clone https://github.com/jig21nesh/model-switcher.git
cd model-switcher
./install.sh
The installer puts a model-switcher command in ~/.claude/model-switcher/ alongside everything
else, so the commands below keep working after you delete the clone. Add that directory to yourPATH (or symlink the binary) to type just model-switcher; otherwise call it by full path, or
run ./bin/model-switcher from the repo.
Then:
- Restart your Claude Code sessions (CLI and VS Code) — settings load at startup.
- Verify the token rates in
~/.claude/model-switcher/config.jsonagainst the official pricing pages (see Configure pricing). - Try a simple prompt:
what does this function do? - Try a complex prompt:
refactor the auth module, migrate the schema and add tests— Claude should announce it is delegating toheavy-task-*. - Check the statusline cost output.
Requires python3 (3.10+) on PATH.
Optional Jev evaluation before routing
Jev is TypeSafe's typed decision model. The offline classifier scores your request first; Jev
then independently chooses a tier, and the router records both recommendations before selecting
a model. Jev evaluates the task; your configured Claude model still performs it.
Jev is disabled by default. Enabling it sends the current prompt, model choices and routing
question to https://api.typesafe.ai/v1/systemone. It does not read or send repository files,
transcripts or earlier conversation turns. Anything pasted into the current prompt is part of
that request. The offline classifier continues to work without a Jev account or network access.
1. Install the integration and get a key
Run ./install.sh from this checkout. The runtime and CLI are installed under~/.claude/model-switcher/. For the short commands used below, add that directory to your
terminal's PATH:
export PATH="$HOME/.claude/model-switcher:$PATH"
Alternatively, use ~/.claude/model-switcher/model-switcher instead of model-switcher in
every command. The installed CLI works without the repository checkout.
Sign in to TypeSafe API Keys and create or copy a TypeSafe
API key. This is a separate credential from your Claude login.
2. Store the key outside the repository
The recommended location, including for desktop launches, is:
~/.claude/model-switcher/jev-api-key
Create the private file, then open it in an editor:
mkdir -p "$HOME/.claude/model-switcher"
touch "$HOME/.claude/model-switcher/jev-api-key"
chmod 600 "$HOME/.claude/model-switcher/jev-api-key"
nano "$HOME/.claude/model-switcher/jev-api-key"
Paste only the key into the file and save it: no quotes, JSON, Bearer prefix orTYPESAFE_API_KEY= assignment. A trailing newline is fine. Use a regular file rather than a
symlink; the loader rejects symlinks, non-files, files over 1,024 bytes, and files granting any
group or other-user access. chmod 600 gives the expected owner-only permissions.
As an alternative, supply TYPESAFE_API_KEY in the environment of the process launching
Claude. This example prompts without echoing the key or putting its literal value in shell
history:
export TYPESAFE_API_KEY="$(python3 -c 'import getpass; print(getpass.getpass("TypeSafe API key: "))')"
claude
A non-empty environment value takes precedence over the file. If an old environment key masks
your saved key, run unset TYPESAFE_API_KEY before launching Claude again. Desktop apps may not
inherit terminal environment variables, so the private file is usually simpler for them.
Do not put the key in config.json, project overrides or committed files. The repository
ignores jev-api-key, .env, .env.* and logs/; .env files are not automatically loaded.
If you set MODEL_SWITCHER_HOME, the key belongs at $MODEL_SWITCHER_HOME/jev-api-key, beside
that installation's config.json. The private key and logs are retained on uninstall.
3. Configure Jev and the model choices
Merge these fields into ~/.claude/model-switcher/config.json. Preserve the existing pricing,
statusline and other settings rather than replacing the whole file:
{
  "models": {"simple": "sonnet", "standard": "opus", "complex": "fable"},
  "routing": {
    "enabled": true,
    "tiers": "auto",
    "show_decisions": true,
    "show_exchange": false
  },
  "complexity": {"standard_threshold": 3, "threshold": 7},
  "jev": {
    "enabled": true,
    "mode": "route",
    "model": "jev-1.13.0",
    "timeout_seconds": 3,
    "min_confidence": 0.7,
    "log_content": false
  }
}
Fresh installs already configure cheap = Sonnet, middle = Opus, expensive = Fable, with
offline score bands < 3, 3–6, and >= 7. Existing installs keep their previous config.
After changing models.*, rerun ./install.sh to generate the matching mid-task-opus andheavy-task-fable agents. Restart Claude after installation to load the hook settings and
progress spinner. Model aliases require access in your Claude account; the installer cannot
verify that access.
| Setting | Behavior |
|---|---|
jev.enabled: false |
Offline classification only; no automatic Jev calls |
jev.enabled: true, mode: "shadow" |
Both evaluators run and are logged; the offline result controls routing |
jev.enabled: true, mode: "route" |
A valid, sufficiently confident Jev answer controls routing; otherwise the offline choice is retained |
jev.model |
Evaluation model ID; this integration pins jev-1.13.0 |
jev.timeout_seconds |
API deadline, including the worker and network; default 3 seconds, supported range 0.1–10 |
jev.min_confidence |
Acceptance threshold from 0 to 1; default 0.7 |
jev.log_content: false |
Log decision metadata without prompt, request or response bodies |
jev.log_content: true |
Also log the prompt, exact routing question, outbound request and received response |
Missing keys, timeouts, invalid responses, service errors and low confidence retain the offline
choice. Automatic evaluation skips Jev for prompts over 10,000 characters. There are no retries
on the interactive path. Slash commands, nested-agent prompts and deliberately chosen specialists
retain their routing exclusions.
4. Check the setup before using a Claude session
model-switcher status
model-switcher tiers

# Preview the exact request JSON without a network call or API key.
printf '%s' 'What does this function do?' | model-switcher jev --offline

# Send one synthetic prompt to Jev and print the selected route.
printf '%s' 'Add validation and tests to this endpoint' | model-switcher jev
model-switcher logs --limit 1
status reports whether a key is available without displaying it or making an API call. The
live jev command explicitly requests one evaluation, even when routing or Jev is disabled
for automatic hooks. It reads the prompt from stdin and does not change your settings.jev --offline only previews the API request; explain "<prompt>" runs the offline classifier.
After setup, submit prompts normally inside Claude Code. The hooks evaluate eligible requests
automatically. Testing via model-switcher jev checks the evaluator; testing inside Claude also
checks whether Claude follows the resulting delegation directive.
Every eligible request records the offline recommendation, Jev recommendation, and final route.
The offline result includes its own tier/model, score, base score, learned adjustment, lookup
caps, classifier-loaded flag and threshold settings. Jev's result includes its own tier/model,
confidence, probabilities, latency and status. agreement is true/false when both produced a
valid choice, or null when Jev did not. The final decision records which evaluator won and why.
Jev does not replace or erase the offline result, even when the two disagree.
5. Show summaries or the full exchange inside Claude
With routing.show_decisions: true, Claude shows Evaluating model routing while the hook
runs, then a notice like this before answering:
UserPromptSubmit says: [model-switcher] Offline: sonnet (0/10) | Jev: sonnet (100%, 491 ms; accepted) | Selected: sonnet via Jev (agree)
The summary appears for simple requests too, and explains disagreements or fallback reasons.
The selected model is the routing recommendation; a heavier model runs in a delegated agent,
so the parent session's model name in the cost statusline can remain Sonnet.
To see the actual Jev request and response in that same session notice, first setjev.log_content to true in your config, then use the display switch:
model-switcher display --details      # show the Jev request and response inside Claude
model-switcher display --no-details   # hide the bodies; retain the summary and logs
model-switcher display                # show the current flag
--details also enables summary notices and requires the existing jev.log_content: true
opt-in. It sets routing.show_exchange: true; --no-details turns only that flag off, keeping
the summary preference and logs. These commands make no API call and take effect on the next
prompt, without restarting Claude. They do not retroactively expand earlier notices.
The detailed notice has Jev request (POST ...) and Jev response (HTTP ...) sections, showing
your prompt, the routing question and criteria, model choices, response JSON and a request ID.
API credentials are redacted. Each body has a 3,800-character preview limit to fit Claude's
notice limit; larger bodies are marked as truncated, with the complete stored exchange available
in the local log. Set routing.show_decisions: false to hide all session notices. To stop storing
content as well, separately set jev.log_content: false.
6. Inspect local logs
| File | Purpose |
|---|---|
~/.claude/model-switcher/config.json |
Routing, Jev and display settings; never the API key |
~/.claude/model-switcher/jev-api-key |
Private TypeSafe key, mode 0600 |
~/.claude/model-switcher/logs/jev.jsonl |
Current request/result and offline decision records |
~/.claude/model-switcher/logs/jev.jsonl.1 |
Previous rotated log |
With MODEL_SWITCHER_HOME set, these paths are relative to that directory instead.
model-switcher logs --limit 10             # readable comparisons
model-switcher logs --json --limit 1       # full stored exchange for the latest result
model-switcher logs --follow --limit 1     # watch evaluation start and finish
model-switcher logs --follow --json        # stream raw JSONL records
model-switcher logs --json --request-id <id>
Replace <id> with the full request ID shown in the notice or log. --follow waits for new
logs and follows rotation; press Ctrl+C to stop. The viewer reads local files without API calls.
With content logging off, --json still contains metadata only. See
routing log fields and examples for the schema and sample comparisons.
Logs pair jev.request and jev.result records using request_id. With content logging on,
you also see the prompt, exact question instructions and criteria, JSON request, JSON response,
matched scoring signals and learned terms. Otherwise logs contain metadata and decisions only.
When routing is on but Jev is disabled, routing.decision records the offline result and Jev's
disabled status, without prompt text. When routing is off, neither evaluator writes new records.
Auth headers are excluded and the actual API key and
recognizable bearer credentials are redacted. Arbitrary secrets in prose can remain, so keep
content logs private. Files are owner-only and rotate at 2 MiB, retaining one backup (each file
can exceed the limit by one bounded record). Logs and the credential file survive uninstall.
Jev's token usage appears in content logs; the Claude cost statusline excludes Jev charges.
Disable Jev or troubleshoot a result
To keep offline routing while stopping automatic Jev calls, set jev.enabled: false. To stop
both routing evaluators, set routing.enabled: false. An explicit model-switcher jev command
still performs the one evaluation you requested unless --offline is supplied.
A project can opt out with {"jev":{"enabled":false}} in .claude/model-switcher.json.
Project config cannot enable Jev, content logging or the detailed exchange display. These
settings take effect on the next eligible prompt.
| What you see | What to check |
|---|---|
missing_api_key |
Confirm the filename, plain-key contents and chmod 600; remove a stale TYPESAFE_API_KEY override and check the installation directory |
http_error with HTTP 401 or 403 |
Verify the TypeSafe key and account access in the console |
timeout or transport_error |
Check connectivity; the offline recommendation remains in use |
low_confidence or invalid_response |
Inspect the logged Jev result; the offline choice is intentionally retained |
| A summary but no request/response | Set jev.log_content: true, run display --details, and submit a new prompt; check for a project opt-out |
--details says content logging is required |
Explicitly enable jev.log_content in the global config; the display switch does not enable it for you |
| No automatic evaluation records | Check routing.enabled, then submit a normal user prompt; excluded commands and nested agents do not generate records |
For API background and contribution guidance, see the research analysis,
ADR-0016, and
dual-result observability design.
Example routing behaviour
| Prompt | Expected route |
|---|---|
what does this function do? |
Simple session model |
explain this TypeScript error |
Simple session model |
rename this variable across the file |
Simple session model |
summarise this file |
Simple session model |
refactor the auth module and add tests |
Heavy-task subagent |
debug this issue across these 5 files |
Heavy-task subagent |
migrate this API from v1 to v2 |
Heavy-task subagent |
review this architecture and suggest implementation changes |
Heavy-task subagent |
Routing is heuristic-based. You can tune the threshold in the config.
When does it delegate?
A prompt is routed to the heavy model when its complexity score reaches complexity.threshold (fresh three-tier installs use 7; the legacy two-tier fallback is 3). Real scored examples:
| Score | Verdict | Prompt |
|---|---|---|
| 8/10 | COMPLEX | build a REST API with auth and database schema |
| 6/10 | COMPLEX | review this codebase and tell me what is missing |
| 6/10 | COMPLEX | fix the race condition in the payment processor |
| 5/10 | COMPLEX | analyse the code and tell me what is missing |
| 5/10 | COMPLEX | why does the app deadlock under load? |
| 2/10 | simple | explain what a database migration is |
| 1/10 | simple | fix the typo in the header |
| 0/10 | simple | what does this function do? |
| 0/10 | simple | yes go ahead |
The score is a hand-written signal sum — every signal, what triggers it, and its points:
| Signal | Examples | Points |
|---|---|---|
| Strong task verbs and incident vocabulary | refactor, implement, migrate, debug, audit, race condition, deadlock, memory leak — inflections like refactoring count; a negation just before (don't refactor) cancels the hit |
5 for the first, +1 each for the second and third (max 7) |
| Domain terms | test, database, api, schema, security, fix, bug |
+1 each, max 3 |
| Pasted stack trace | Traceback (most recent call last), at app.js:12, SomeError: |
+3 |
| Numbered multi-step list (2+ items) | 1. … 2. … |
+2 |
| Chained requests (2+ connectives) | then, and also, as well as, finally |
+1 |
| Fenced code block | +1 | |
| Multiple file paths (2+) | auth.py utils.py |
+1 |
The base score is that sum. The learned adjustment — clamped to ±3, see
the learning algorithm — is added, and the total
is rounded and clamped to 0–10. If a lookup cap matched, the score is cut to 2 whatever else
it earned; the caps run after the learned adjustment, so learned weights can never talk a
lookup into being delegated.
Vocabulary is scored from the first 80 words — the request — while the structural signals
(lists, code blocks, stack traces) read the whole text: a long paste full of task verbs cannot
route itself, but a stack trace counts wherever it appears. Prompt length itself scores nothing.
Capped back to simple: short pure questions with no task verb, definitional questions, short affirmations, and negated verbs (don't refactor).
Ignored by scoring: slash commands, local command output, agent-relay messages, and subagent contexts. The router reads at most the first 10 KB of a prompt, so huge pastes cannot stall submission — put your request before a large paste, because an ask that lands past the 10 KB cutoff is not scored and the prompt may route as simple.
Teaching it from your own history
The built-in list is a fixed guess. learn reads your local transcripts and asks a different
question of every past prompt: did it actually become work? Tool calls, file edits and spawned
subagents are all recorded, so the answer is observable rather than assumed.
model-switcher learn          # analyse and write a candidate — routing unchanged
model-switcher learn --apply  # promote the candidate to live
It prints a before/after comparison measured on your own history, so you can see whether it
helps before committing:
corpus: 2,124 usable prompts from 101 sessions (533 became real work, 1,591 did not)

routing accuracy at your configured threshold, measured on your own history:
                precision   recall     F1   wasted   missed
  built-in          33.0%    34.3%   33.6      372      350
  with terms        41.9%    42.4%   42.1      314      307
Nothing changes until you pass --apply, and nothing leaves your machine. The output is a JSON
weight table — no prompt text, no hashes, no paths — filtered so a term must recur across at least
three separate sessions and ten occurrences before it can appear, and shaped to exclude hostnames,
identifiers and API keys. Full detail, including the exact tokenization other tools need in order
to consume it: docs/classifier-schema.md.
[!NOTE]
The label is a proxy. A hard question answered correctly in two tool calls counts as "light", so
the weights optimise for became work, which correlates with needed the better model without
being identical to it. Review the candidate before applying it.
The learning algorithm, and its alternatives
What learn runs is a smoothed, evidence-shrunk log-odds model — the scoring half of a
naive-Bayes text classifier, kept small enough to audit by eye. Five steps:
Label. A prompt is heavy when the turn it started spawned a subagent, made 3+ file
edits, or made 12+ tool calls; otherwise light. Output tokens are deliberately not a
signal — thinking models inflate them, and verbosity is not work. Prompts that cannot be
judged on their own ("yes go ahead", slash commands, turns with no observable outcome) are
dropped; roughly a quarter of a real corpus.Count. For every usable word (3–24 characters, at most one hyphen, not secret-shaped,
not a stopword), count how many heavy and how many light prompts contain it — distinct per
prompt, so repetition inside one prompt counts once.Weight.
weight(term) = log( p_heavy / p_light ) x n / (n + 40)where
p_heavyandp_lightare the term's add-0.5-smoothed share of heavy and light
prompts, andnis its total occurrences. Then / (n + 40)shrinkage is the part that
matters: raw log-odds pins any word that happens to appear only in heavy prompts to the
ceiling — the first run put "acer" there. Shrinking toward zero by evidence means a term seen
ten times keeps a fifth of its raw weight and one seen two hundred times keeps five sixths.Gate. A term must appear in 3+ separate sessions and 10+ times overall (also the
privacy floor — nothing pasted once can reach the file), carry |weight| ≥ 0.35 to be worth
storing, and is clipped to ±1.5. At most 400 terms are kept. Below 150 usable prompts the
tool refuses to emit anything at all.Bound at apply time. The router sums the weights of distinct matched terms and clamps
the sum to ±3, so the learned table can nudge a score but never overrule the built-in
signals. Constants and rationale: ADR-0006; portable format:docs/classifier-schema.md.
Alternatives for the local baseline. Local scoring runs on every prompt and stays offline,
deterministic, fast and stdlib-only. Jev is an optional separate evaluation layer (ADR-0016);
it does not change the learned artifact or make offline reports call a model.
| Alternative | What it would buy | Why it is not used |
|---|---|---|
| Full naive Bayes (replace the scorer) | One principled model instead of two halves | The learned table would gain unbounded authority; the ±3 clamp deliberately keeps the auditable built-in signals in charge, and the structural signals (stack traces, lists) have no term to hang a weight on |
| Logistic regression on bag-of-words | Correct handling of correlated terms — today ten synonyms of "deploy" each add weight independently | Needs an optimizer and training infrastructure; on a ~2k-prompt personal corpus the gain over shrunk log-odds is marginal, and per-term evidence gates (the privacy floor) are harder to express |
| TF-IDF + linear model / SVM | Standard text-classification machinery | Third-party dependencies; the runtime is stdlib-only by hard rule, because these scripts run on every prompt in every session |
| Sentence embeddings + small classifier | Synonyms, paraphrase, and non-English prompts (the scorer's real blind spot) | A model download and per-prompt inference on the interactive path; scoring must stay offline, deterministic, and dependency-free |
| Online model evaluator | Semantic judgment beyond vocabulary | Available as opt-in Jev evaluation, with latency and data-sharing trade-offs; explain remains the local baseline |
Two honest limitations follow from the choice: term independence (correlated vocabulary
over-counts, bounded by the ±3 clamp) and literal matching (no stemming, so refactor andrefactoring are learned separately, and a prompt in a language with no learned terms scores 0
adjustment). If a constraint ever falls — say a local embedding model becomes acceptable on this
path — the artifact, not the Python, is the interface: a stronger producer can replace learn
and write the same file, and the router would not change at all.
Pick a threshold from evidence
The original two-tier threshold was 3 (ADR-0014). Fresh three-tier installs use 3 for Opus
and 7 for Fable as starting boundaries, not newly calibrated results. tune
answers the question the default was standing in for: on your history, what did prompts at each
score actually turn into, and what would a different threshold have delegated, caught and cost?
model-switcher tune                          # your whole corpus
model-switcher tune --max-sessions 50        # cap how much history is read
model-switcher tune --transcripts ~/elsewhere/projects   # repeatable
It changes nothing. It prints two tables and you edit config.json yourself if you want to.
corpus: 1,152 usable prompts from 24 sessions (551 became real work, 601 did not)
scored: built-in signals only

what prompts at each score actually did:

  score   prompts   became real work
      0       249   #                      6%
      1       166   ######                31%
      2       101   ##########            48%
      3       122   #########             44%
      4         0                           -
      5         0                           -   <- current threshold (5)
      6       109   ############          61%
      7       108   ################      79%
      8       180   ###############       73%
      9        53   ################      81%
     10        64   ##################    91%

what each candidate threshold would do:

  threshold  delegated  precision   recall     F1   $/1k prompts
          3      55.2%      68.7%    79.3%   73.6        $268.41
          4      44.6%      74.5%    69.5%   71.9        $240.69
          5      44.6%      74.5%    69.5%   71.9        $240.69   <- current
          6      44.6%      74.5%    69.5%   71.9        $240.69
          7      35.2%      78.3%    57.5%   66.3        $208.67
          8      25.8%      78.1%    42.1%   54.7        $172.92

no recommendation: nothing beats your current 5 by enough to matter (best is 3 at F1 73.6 vs 71.9). Leave it alone.
The calibration table is the raw evidence: how many prompts landed at each score, and what
share of them went on to spawn a subagent, make three or more edits, or run twelve or more tool
calls. That is the same "became real work" label learn
uses — imported, not reimplemented, so the two commands cannot disagree. Scoring runs through the
router with your learned classifier applied, so the table describes the routing you actually have.
Empty score bands are normal and worth reading: the built-in scorer awards 5+ points for a task
verb and up to 3 for domain terms, so some totals are simply hard to reach. A threshold sitting in
a gap (5, above) behaves identically to the nearest score that prompts actually land on — which is
why three rows of the sweep are the same, and why moving it by one may do nothing at all.
The threshold sweep shows the trade. delegated is the share of prompts that would go tomodels.complex; precision is how many of those were real work; recall is how much of the real
work got there. A recommendation is printed only when the corpus supports one: below 150 usable
prompts, or when no candidate beats your current threshold by a clear margin, it says so rather
than naming a number.
[!IMPORTANT]
$/1k promptsis an estimate, not a quote. It re-prices each historical prompt's own
recorded tokens at the tier it would route to under that threshold —models.simplerates when
it stays in-session,models.complexwhen it delegates. That assumes the same prompt burns the
same tokens on either model, which is not true: a stronger model may finish in fewer turns, or
think for longer. Unlike thesavedstatusline segment, which
deliberately under-reports, this one has no known direction of error. Compare rows against each
other; do not read any of them as a bill. The column is dropped entirely — with the reason
printed — when pricing is not configured, a tier has no rates, or the transcripts recorded no
token usage, rather than being guessed. See
ADR-0012.
Nothing leaves your machine, and no prompt text is printed or written — only counts, rates and
scores. A three-tier install is swept as in-session versus models.complex only, and says so.
Look at what it learned before you trust it
learn reports how much the weights improved routing. It does not tell you what they are, and a
weight table that improves accuracy on your history can still be measuring the wrong thing.classifier opens the artifact up:
model-switcher classifier                     # the live one
model-switcher classifier --config ~/.claude/model-switcher/classifier.candidate.json
  learned      2026-07-25T03:39:15+00:00
  generator    model-switcher/analyze_history, schema version 1
  corpus       2,143 prompts from 105 sessions
               544 became real work, 1,599 did not (25% heavy)
  terms        25 in effect, weights -0.72 to +1.12, bounded to +-3 per prompt

  weight distribution
    |w| < 0.5              12   48%  ###########             weak — six of these move a score by one point
    0.5 <= |w| < 1         11   44%  ##########              moves a score on its own
    1 <= |w| < 1.35         2    8%  ##                      strong
    |w| >= 1.35             0    0%                          at or near the +-1.5 clamp, so cut off
                                                            12 positive, 13 negative

  evidence floor  5 terms share exactly -0.390
                  a weight that many terms agree on is the minimum-evidence floor showing
                  through, not a measurement: they are indistinguishable from each other

  strongest evidence a prompt becomes real work
    implement +1.12, ensure +1.05, migrate +0.94, confirm +0.83, endpoint +0.71, schema +0.66

  vocabulary by project   3 projects, 3 transcripts, 180 prompts read
    project                                   terms  only here
    -Users-you-code-payments-api                 15          3
    -Users-you-code-mobile-app                   14          8
    -Users-you-code-data-pipeline                12          2

  topic, not difficulty
    a term whose prompts all come from one project measures which project you are in, not
    how hard the prompt is; it will mis-score the day you start working somewhere else
    one project only      13 of 25 terms (52%)
      retry +0.63, colour -0.61, checkout +0.52, wording -0.52, onboarding +0.47, invoice +0.44
Three things are worth knowing about your own table, and none of them are visible from an accuracy
figure:
- How much of it is noise. A weight below ±0.5 needs six matching terms to move a score by a
single point. If most of the table sits there, most of the table is doing nothing. - Where the evidence floor is. Terms that share one exact weight all hit the minimum evidence
the producer accepts and nothing more. They are indistinguishable from each other by
construction, so their ranking against each other means nothing. - Whether it learned difficulty or subject. Transcripts are stored per project, so every term
can be traced to the projects whose prompts contained it. A term found in only one project — or
taking 90%+ of its prompts from one — is that project's vocabulary. It will route on which repo
you are in, and it will be wrong somewhere else. Words likenaplan,stravaorcheckout
are the tell.
Both lists are printed in full so you can decide. If too much of the table is topical, learn again
with a wider corpus (learn --transcripts), or keep routing on the built-in signals alone.
Point --transcripts somewhere else to attribute against a different corpus. Nothing here writes
anything: it reads the artifact and your transcripts, and prints.
Ask why a prompt routes the way it does
explain scores a prompt and shows its working, without spending a token:
model-switcher explain "ensure the deployment pipeline works end2end"
  domain terms (pipeline, deployment)            +2
                                              -----
  built-in score                                  2
  learned terms                                +2.0
    ensure +1.16, end2end +0.88

  score 4/10   threshold 5   MODERATE -> mid-task-sonnet

  decision boundary
    1 point clear of the MODERATE threshold (3)
    what carried it there
      domain terms (pipeline, deployment)           +2.00
      learned term "ensure"                         +1.16
      learned term "end2end"                        +0.88
    without domain terms (pipeline, deployment) (+2) it scores 2 — answered in-session

  routing ladder (3 tiers)
     score < 3               simple    haiku         answered in-session
  -> 3 <= score < 5          moderate  sonnet        mid-task-sonnet
     score >= 5              complex   fable         heavy-task-fable
Add --no-classifier to see the built-in signals alone. The explanation comes from the same code
path that does the routing, so it cannot disagree with what actually happens — and the ladder
underneath shows the other bands, so you can see what a slightly harder prompt would have done.
The decision boundary block answers "was that close?" A score on its own does not tell you
whether the prompt sailed over the threshold or scraped it. This does:
- how far it landed from the threshold that decided it — the one it crossed, or the nearest one above
- for a prompt that routed: what carried it there, and what it would have scored without the
largest of those (the counterfactual runs through the router's own scoring, so it cannot drift) - for a prompt that stayed in-session: which real signals would have flipped it, each measured by
re-scoring the prompt with that signal in it, and where it would then have gone - what is holding it back — the negative learned terms, and any lookup cap, which is applied
after learned weights and so cannot be argued away by them
For a prompt that stayed in-session because of vocabulary you only use in one repo:
  score 0/10   threshold 5   answered in-session

  decision boundary
    5 points short of the COMPLEX threshold (5), the nearest routing edge
    what would flip it
      + the learned term "implement" (+1.12)            scores 6   COMPLEX -> heavy-task-fable
      + a built-in task verb, e.g. "refactor"           scores 5   COMPLEX -> heavy-task-fable
    what is holding it back
      learned term "wording"                        -0.52   topical: seen in only one project
      learned term "screen"                         -0.41   topical: seen in only one project
      no built-in signal matched, so the score started at 0
topical means that term's prompts were only ever found in one of your projects, which makes it
a subject rather than a difficulty — see below. explain samples a couple of transcripts per
project to answer that quickly; model-switcher classifier reads all of them.
Learned weights are bounded: they can move a score by at most ±3, and the lookup caps are applied
after them, so no weight table — however skewed or hand-edited — can turn a short question into a
delegation. A missing or corrupt classifier is ignored and routing proceeds as if it were not there.
Or run the hook exactly as Claude Code does:
echo '{"prompt":"review this codebase and tell me what is missing","session_id":"test"}' \
  | python3 ~/.claude/model-switcher/complexity_router.py
How it works
model-switcher is made of three cooperating pieces:
| Piece | Mechanism | Why |
|---|---|---|
| Complexity routing | UserPromptSubmit hook |
Runs on every prompt before Claude sees it |
| Heavy execution | heavy-task-* subagent |
Runs complex work on a configured heavier model |
| Cost display | Statusline command | Shows deterministic local cost output |
Hooks cannot switch the main session model directly — that is a Claude Code platform constraint. So routing works through delegation:
- You submit a prompt.
- The
UserPromptSubmithook scores the prompt locally. - Below the threshold: the prompt stays in the main session.
- At or above the threshold: Claude receives a mandatory routing directive to delegate the task to
heavy-task-*. - The standing routing-policy block in
~/.claude/CLAUDE.mdreinforces the delegation rule at system-prompt level. - The
heavy-task-*subagent performs the complex work on the configured heavy model. - Claude relays the result back to you.
- The statusline reads the local transcript and shows turn/session cost.
How routing is enforced, and its limits
Routing is enforced in two layers: the per-prompt directive injected by the hook, and the standing routing-policy block in ~/.claude/CLAUDE.md. This makes delegation highly reliable in practice, but it is still ultimately the model following instructions — a hard per-prompt guarantee is not possible on this platform. The statusline is your audit trail: a complex turn billed only at the cheap model's rates means a delegation was skipped.
Full decision records: ADR-0001 (hooks + subagent routing) and ADR-0002 (delegation compliance).
Architecture
flowchart TD
    U[User prompt] --> H["UserPromptSubmit hook<br/>complexity_router.py<br/>(offline heuristic score 0-10)"]

    C[("config.json<br/>models · threshold · pricing")] -.-> H

    H --> J["Optional Jev evaluation<br/>confidence gate; local fallback"]
    J -->|"simple tier"| S["Answered in-session<br/>simple model"]
    J -->|"standard tier (3-tier only)"| M["additionalContext:<br/>delegate to mid-task"]
    J -->|"complex tier"| D["additionalContext:<br/>delegate to heavy-task"]
    H -->|"models not configured"| Q["Claude asks you to confirm<br/>models and saves config.json"]
    H -->|"routing disabled<br/>(global or project override)"| S

    M --> B["mid-task-* subagent<br/>configured standard model"]
    D --> A["heavy-task-* subagent<br/>configured heavy model"]
    A --> R[Result relayed to user]
    B --> R

    S --> T[Assistant message]
    R --> T

    T --> SL["Statusline<br/>cost_statusline.py"]

    TR[("session transcript<br/>.jsonl with per-message token usage")] -.-> SL
    C -.-> SL

    SL --> OUT["model | turn $0.0042 | session $0.19"]
    SL -->|"pricing not configured"| WARN["cost n/a: set pricing in config.json"]
Lifecycle of one complex prompt:
sequenceDiagram
    actor U as You
    participant CC as Claude Code session
    participant H as complexity_router.py
    participant A as heavy-task agent
    participant SL as cost_statusline.py

    U->>CC: "refactor the auth module and add tests"
    CC->>H: UserPromptSubmit hook
    H-->>CC: additionalContext: score >= threshold, delegate to heavy-task
    CC->>A: Agent tool: full task + context
    A-->>CC: completed work + summary
    CC-->>U: response (relayed result)
    CC->>SL: statusline refresh
    SL-->>U: model | turn cost | session cost
What gets installed where
| Path | Purpose |
|---|---|
~/.claude/model-switcher/complexity_router.py |
UserPromptSubmit hook |
~/.claude/model-switcher/cost_statusline.py |
Statusline command |
~/.claude/model-switcher/config.json |
Your configuration — created from config/config.example.json if absent, never overwritten |
~/.claude/model-switcher/installed.json |
Manifest of your pre-install model/statusLine/agent, used by uninstall |
~/.claude/model-switcher/model-switcher |
The status / tiers / explain / learn / classifier / tune / pricing CLI, plus the modules and rate table it needs — so it keeps working if you delete the clone |
~/.claude/model-switcher/classifier.json |
Learned routing weights, once you run learn --apply. Kept on uninstall, like your config |
~/.claude/agents/heavy-task-<model>.md |
The subagent, named for and stamped with your configured complex model, e.g. heavy-task-fable |
~/.claude/agents/mid-task-<model>.md |
The middle-tier subagent — only when models.standard is set, e.g. mid-task-sonnet |
~/.claude/settings.json |
Hook and statusline entries merged in; session model set to your simple model unless --skip-model is used |
~/.claude/CLAUDE.md |
Marker-delimited routing-policy block (<!-- model-switcher:begin/end -->) |
Your existing setup is never clobbered. Every touchpoint is merge-based and reversible:
settings.jsonentries are merged, not overwritten; your previousmodelandstatusLineare recorded in the manifest and restored on uninstall; one-time backup atsettings.json.model-switcher.bak.CLAUDE.md: if you don't have one, the installer creates it with only the policy block (and uninstall deletes it again). If you do, the block is appended after your content with a one-time backup atCLAUDE.md.model-switcher.bak; re-installs update only the text between the markers; uninstall removes only the block.- A custom statusline is preserved: the installer records it as
statusline.wrap_commandand the cost statusline runs it first, appending the cost segment. - Your config and pricing survive re-installs and uninstalls.
Installer options:
./install.sh                # full install (also sets session model to models.simple)
./install.sh --skip-model   # install hook/statusline/agent but leave your session model alone
./install.sh --uninstall    # remove everything it added; restores your previous statusline and model
You do not need the repo to remove it later — the installed CLI can do it:
model-switcher uninstall          # show what would be removed, change nothing
model-switcher uninstall --yes    # do it
./install.sh --help         # full option reference and what gets installed where
Command reference
Routing itself needs no commands — the hooks do everything per prompt. This is the complete
surface for when you want to inspect, tune, or switch things. model-switcher below is the
installed CLI at ~/.claude/model-switcher/model-switcher; add that directory to PATH or
symlink the script once to type just model-switcher.
The CLI
| Command | What it does | Useful flags |
|---|---|---|
model-switcher status |
Config summary (models, routing state, pricing age, classifier) plus health checks: broken agent files, price inversions, failed delegations with their last error | --transcripts |
model-switcher tiers |
The routing ladder your config actually produces — each score band and the model that serves it | --config |
model-switcher explain "<prompt>" |
Scores a prompt without spending a token: the verdict, what carried it there, how close the call was, and what would flip it | --no-classifier |
model-switcher classifier |
What the learned classifier contains: every term and weight, which of your projects taught it each word, and how much of the table is noise | --transcripts |
model-switcher learn |
Rebuilds the learned weights from your own transcript history and reports before/after routing accuracy; writes a candidate only | --apply to promote, --max-sessions |
model-switcher tune |
What your history says complexity.threshold should be, with cost and precision at each candidate value |
--transcripts, --max-sessions |
model-switcher jev |
Evaluates a prompt from stdin with Jev and logs the result | --offline (request preview), --config |
model-switcher display |
Shows or switches detailed Jev request/response notices inside Claude | --details, --no-details, --config |
model-switcher logs |
Shows offline and Jev recommendations, disagreement, and the final model choice | --follow / -f, --limit, --json, --request-id |
model-switcher pricing |
Compares your rate table against the maintained one | --offline (bundled table), --yes (apply) |
model-switcher uninstall |
Dry run of a full removal; your config.json and learned classifier survive |
--yes (actually do it) |
Analysis commands work offline. pricing fetches rates unless --offline; jev sends the supplied
prompt to TypeSafe unless --offline. Hook evaluations require jev.enabled: true.
From inside a session
Everything below is a small edit to ~/.claude/model-switcher/config.json or a CLI call — you can
make the edits yourself or simply ask Claude to. Config changes take effect on your next prompt
with no restart; only changes to models.* need ./install.sh re-run, because the tier agent
files are generated from them.
| I want to… | Do this |
|---|---|
| Turn routing off (statusline and cost tracking keep working) | "routing": {"enabled": false} — see §4 |
| Turn routing back on | "routing": {"enabled": true} (or remove the key) |
| Stop only the agent-spawn rewrites | "routing": {"agents": false} — see §1b |
| Turn routing off (or on) for one project only | .claude/model-switcher.json in that project — see §4 |
| Remove model-switcher entirely | model-switcher uninstall --yes — restores your settings byte-for-byte |
| Configure expensive / middle / cheap models | models.complex / models.standard / models.simple, then re-run ./install.sh — see §1 and §1a |
| See which model serves which score band | model-switcher tiers |
| Check the whole install and what is wrong with it | model-switcher status |
| See the learned terms and their weights | model-switcher classifier |
| See why one prompt routes where it does | model-switcher explain "the prompt" |
| Update the learned weights from my history | model-switcher learn, review, then model-switcher learn --apply |
| Pick a threshold from evidence instead of guessing | model-switcher tune |
| Keep the cost figures honest | model-switcher pricing --yes when rates change |
The classifier: format and algorithm
The learned half of scoring lives in one file, ~/.claude/model-switcher/classifier.json
(schema_version 1). Its payload is scoring.terms: a flat map of word → weight, where a
positive weight means prompts containing that word historically became real work and a negative
one means they resolved as lookups. No prompt text, hashes, or paths are ever stored.
How it is built (learn): every past prompt in your local transcripts is labelled by what
actually followed it — tool calls, file edits, and spawned subagents mean it became work.
Per-word weights come from how strongly the word separates the two groups, and a term must
survive support filters before it can appear at all: seen in ≥3 separate sessions and ≥10 times,
shaped to exclude identifiers, hostnames, and API keys. learn writes a candidate and changes
nothing until --apply.
How it is applied (every prompt, deterministically, offline): built-in signals score the
request — vocabulary from the first 80 words, structure (stack traces, code blocks, lists) from
the first 10 KB — then the learned adjustment is added: the weights of distinct matched terms
are summed and the sum clamped to ±max_adjustment (3.0), so the learned table can never
overrule the built-in signals entirely. The total is clamped to 0–10 and the threshold bands
pick the tier.
The exact tokenization, the filter table, and the rules another tool must follow to consume the
file are specified in docs/classifier-schema.md — the file, not
the Python, is the interface. model-switcher classifier shows you everything currently in it;model-switcher explain shows both halves working on any prompt you give it. The precise weight
formula, and the alternatives that were considered and rejected, are in
The learning algorithm, and its alternatives.
Configuration
All configuration lives in ~/.claude/model-switcher/config.json.
1. Choose your models
{
  "models": {
    "complex": "fable",
    "simple": "sonnet",
    "standard": "opus"
  }
}
Three models can be configured, from dearest to cheapest:
| Key | Role | Runs on |
|---|---|---|
complex |
the expensive tier — hardest prompts | heavy-task-* subagent |
standard |
the middle tier, optional | mid-task-* subagent |
simple |
the cheap tier — everything else | your session itself |
- Aliases (
opus,sonnet,haiku,fable) or full model IDs (claude-opus-4-8) are accepted. complexis the model theheavy-task-*agent runs on. After changing it, re-run./install.shso the agent file is regenerated (and renamed for the new model).simpleis the session model the installer writes intosettings.json.standardis optional and enables the third tier — see below. Set it tonullfor a two-tier setup; fresh installs useopus.- If
complexorsimpleis missing ornull, Claude asks you to confirm models at the start of your next prompt and saves your answer here.
Whatever you set, model-switcher tiers prints the ladder your config actually produces:
  routing ladder (3 tiers)
     score < 3               simple    haiku         answered in-session
     3 <= score < 5          moderate  sonnet        mid-task-sonnet
     score >= 5              complex   fable         heavy-task-fable
The installer prints the same ladder when it finishes, and explain prints it with -> against
the band your prompt landed in. All three come from one function, so what you are shown is what
the router will do.
1a. Optional: add a middle tier
With two tiers, everything above the threshold pays top-model rates — including work that is more
than the cheap model handles well but nowhere near worth Fable. Setting models.standard adds a
middle band:
{
  "models": { "complex": "fable", "standard": "sonnet", "simple": "haiku" },
  "complexity": { "threshold": 5, "standard_threshold": 3 }
}
This is an alternative ladder. Fresh installs use Sonnet / Opus / Fable with thresholds 3 and 7.
Existing configurations are preserved during upgrades.
| Score | Routes to |
|---|---|
>= threshold (5) |
heavy-task-fable |
>= standard_threshold (3), below 5 |
mid-task-sonnet |
| below 3 | answered in-session on simple |
Re-run ./install.sh after adding it — that generates the second agent. Removingmodels.standard and re-running deletes it again. Check the result with model-switcher tiers.
routing.tiers controls this explicitly: "auto" (the default — three tiers when models.standard
is valid, two otherwise), or a literal 2/3. A project can drop to two tiers with{"routing": {"tiers": 2}} in .claude/model-switcher.json without touching the global config.standard_threshold is always forced strictly below threshold; an overlapping pair is clamped
with a warning rather than silently making the middle band unreachable.
1b. Routing Claude's own agents
Your prompt is not the only thing that gets delegated. When Claude spawns a general-purpose
agent, that agent has no model of its own — it inherits your session model — so the work runs
outside the ladder entirely. In one measured corpus, agent transcripts held 44.5% of all input
tokens and 73% of all output tokens, and Task was called with general-purpose 72 times
against a configured tier agent once.
A PreToolUse hook on Task closes that gap: it scores the delegated prompt with the same scorer
and moves generic agents onto the tier the policy says the work belongs to.
Claude spawns:  general-purpose  "refactor the auth module and migrate the schema"
model-switcher: score 8/10 -> COMPLEX -> runs as heavy-task-fable instead
Deliberately narrow, because rewriting a tool call is intrusive:
| Rule | Why |
|---|---|
| Upgrade only, never downgrade | A caller that named a specific agent knows something the score does not |
Only general-purpose and claude are eligible |
They have no model of their own. Set routing.generic_agents to change the list |
Explore is never promoted |
It is a cheap read-only search agent; the heavy tier would spend a lot to do little |
| Top-level spawns only | Inside an agent, promoting would let a tier agent escalate its own helpers |
| Never rewrites to a missing agent | That would turn a working call into a failing one |
| Never silent | Every rewrite explains the score, the tier and how to switch it off |
Disable with {"routing": {"agents": false}}; it is also off whenever routing.enabled is false.
Note: a rewrite sends work to
models.complex. If that model has no available quota the
delegation fails, and that is not detectable offline — the agent file exists and the config is
valid.model-switcher statusreports failed delegations with their reason.
2. Configure pricing
pricing_usd_per_mtok ships pre-filled for every current model — $ per million tokens:
{
  "pricing_usd_per_mtok": {
    "claude-fable-5":  { "input": 10.00, "output": 50.00, "cache_write": 12.50, "cache_write_1h": 20.00, "cache_read": 1.00 },
    "claude-opus-5":   { "input": 5.00, "output": 25.00, "cache_write": 6.25, "cache_write_1h": 10.00, "cache_read": 0.50 },
    "claude-sonnet-5": { "input": 2.00, "output": 10.00, "cache_write": 2.50, "cache_write_1h": 4.00, "cache_read": 0.20 }
  }
}
Four rates are required (input, output, cache_write, cache_read). Two are optional:
cache_write_1h— cache writes are billed by time-to-live: 1.25× input at a 5-minute TTL, 2× input at a 1-hour TTL.cache_writeis the 5-minute rate. Claude Code uses 1-hour caching heavily, so leaving this out under-reports cost substantially — on a real 3,200-transcript corpus, by about 60% of cache-write spend.fast— a nested rate block used when a turn reportsusage.speed == "fast". Fast mode runs the same model at premium rates.
Both are optional and their absence reproduces the previous behaviour exactly, so an older config keeps working.
Keeping rates current
model-switcher pricing              # compare your config against the maintained table
model-switcher pricing --yes        # apply the differences (backs up your config first)
model-switcher pricing --offline    # use the bundled table, no network
The check exits non-zero when your rates have drifted, so it works in a scheduled job. It fetchesconfig/pricing.json from this repo over HTTPS, validates every rate before writing anything, and
leaves models it does not recognise — including any you added yourself — untouched. The statusline stays offline. Jev evaluation is the other optional network path.
[!WARNING]
Model prices change.claude-sonnet-5currently shows introductory pricing that reverts to $3.00/$15.00 after 2026-08-31. Re-run the pricing check rather than trusting a table you installed months ago.
A model entry is used only when all four required rates are usable numbers — a true, a negative, or a non-numeric rate disqualifies the entry rather than being coerced. Dated IDs like claude-sonnet-5-20250929 match their base entry by prefix. Until at least one entry is complete, the statusline shows a pricing warning and Claude reminds you once per session.
3. Tune the threshold
{
  "complexity": {
    "threshold": 3
  }
}
Prompts scoring at or above the threshold (0–10, integer or float, clamped to 1–10) are delegated. Raise it if too much gets delegated, lower it for more heavy-model routing. Don't guess — model-switcher tune shows what your own history says. Pricing and threshold changes apply immediately — only models.complex needs a re-install.
Fresh three-tier boundaries (3 and 7) are starting policy choices. tune replaces the guess with your own
history — see Pick a threshold from evidence below.
4. Switch routing on and off
{
  "routing": {
    "enabled": false
  }
}
With routing.enabled set to false the hook stays silent: no scoring, no delegation directives, no setup nags. The statusline and cost tracking are unaffected. Takes effect on your next prompt — no re-install needed. Absent or true means routing is on.
The switch fails closed: an invalid routing.enabled value, a routing section that is not an object, or a config.json that exists but cannot be parsed all read as routing off, with a one-line stderr warning. Only a genuinely absent config (a fresh install) keeps the enabled default. Turning routing off cannot be undone by a typo in the same file.
Any project can override the switch and the threshold with a .claude/model-switcher.json in the project root:
{
  "routing": { "enabled": true },
  "complexity": { "threshold": 7 }
}
Only the routing and complexity sections can be overridden per project — models and pricing stay global, because the heavy-task agent is generated from the global config at install time. Typical uses: routing off globally but on for one expensive repo, or a higher threshold in a repo where most work is simple. Overrides apply to both hooks: a project that flips routing changes prompt delegation and agent-spawn rewrites alike.
Two things to watch:
- Values must be proper JSON types:
enableda baretrue/false,thresholda number. An invalid value (e.g."enabled": "false"as a quoted string) is ignored with a one-line stderr warning and the global setting stays in effect — a typo cannot silently flip routing. - The override is read from the session's working directory exactly (
<cwd>/.claude/model-switcher.json). There is no parent-directory search, so a repo-root override does not apply to a session started in a subdirectory of that repo.
What you will see
Statusline with pricing configured (appended to your existing statusline if you had one):
Sonnet 5 | my-repo (main) | turn $0.0042 | session $4.23 | saved $8.13 (66% vs fable-5) | 3.3M in / 33.0k out | 3 tiers
What each segment means
| Segment | Shows | Quiet when |
|---|---|---|
turn |
Cost of the current turn | never |
session |
Cost of the whole session | never |
saved |
What routing avoided versus the dearest model this session actually used | nothing was routed |
tokens |
Total tokens in / out | never |
routing |
routing off, or 3 tiers when a middle tier is active |
plain two-tier routing |
models |
Your model ladder, e.g. haiku > sonnet > fable |
not in the default set |
saved is a counterfactual, not a bill: it re-prices every token in the transcript at the rates
of the most expensive model the session actually ran on, and subtracts what you really spent. The
model it compares against is named in the output, so the percentage always has a stated denominator.
It stays silent until a session has genuinely spanned two or more priced models. One model means
nothing was ever delegated, so nothing was saved — and a baseline taken from your configuredcomplex model rather than from what actually ran will happily report a large saving for a session
where the router never fired. (A session on claude-opus-5 with complex: fable reported a
constant saved 50% for exactly this reason: fable is precisely twice opus on every rate, so the
figure came from the rate table, not from routing. See
ADR-0009.)
This under-reports rather than over-reports: an all-cheap session shows no saving even though the
heavy model would genuinely have cost more. For a number the tool computes about its own value,
that is the right direction to be wrong in.
Choose your own line with statusline.segments, in the order you want them:
{
  "statusline": {
    "segments": ["turn", "session", "saved", "tokens", "routing"],
    "savings_baseline": null
  }
}
savings_baseline pins the comparison to a specific pricing key instead of letting it float to
whatever the session's dearest model turned out to be. It picks among the models the session
actually ran — a model that never appears in the transcript is ignored, and it does not bypass the
two-model or material-share rules: a session that never left one model still reports no saving.
Unknown segment names are ignored with a warning rather than breaking the line.
Statusline before pricing is configured:
Sonnet 5 | cost n/a: set pricing in ~/.claude/model-switcher/config.json (rates: https://claude.com/pricing)
A model with tokens in the transcript but no pricing entry is flagged with no rate: <model-id> rather than silently dropped. Entries that billed nothing are not flagged — Claude Code writes <synthetic> placeholders for interrupts and error messages with every token field at zero, and warning about a missing rate for those would imply cost data you cannot supply. If the transcript carries no usage data at all, the line falls back to Claude Code's built-in estimate, labelled (builtin est.).
Verify the install
Run the pieces exactly as Claude Code will:
# Complex prompt — expect a delegation directive as JSON
echo '{"prompt":"refactor the auth module, migrate the schema and add tests","session_id":"check"}' \
  | python3 ~/.claude/model-switcher/complexity_router.py

# Simple prompt — expect no output
echo '{"prompt":"what does this function do?","session_id":"check"}' \
  | python3 ~/.claude/model-switcher/complexity_router.py

# Statusline — expect one line ending in a cost segment or the pricing warning
echo '{"model":{"display_name":"Sonnet 5"}}' | python3 ~/.claude/model-switcher/cost_statusline.py
In a live session: check the statusline at the bottom, give it a complex prompt — Claude should say it is delegating to heavy-task-<model> (e.g. heavy-task-fable) — and /agents should list the agent with your configured model.
Troubleshooting
Nothing changed after install
Restart the session — hooks, agents, and settings are loaded at startup. In VS Code the workspace must be trusted for hooks and statusline commands to run.
Statusline shows cost n/a
Pricing isn't configured yet — see Configure pricing.
Complex prompts are not delegated
Run the hook manually (see Verify the install) and check the score reaches the threshold; lower complexity.threshold if needed. Delegation is advisory: Claude follows the injected directive and the CLAUDE.md policy, but the platform has no hard per-prompt model switch.
I changed models.complex but the agent still uses the old model
Re-run ./install.sh — this regenerates the heavy-task-* agent and updates its name to the new model.
I want my old setup back
./install.sh --uninstall from the repo, or model-switcher uninstall --yes from the install
itself, restores your previous statusline and session model from the manifest and removes the
CLAUDE.md block. Both run the same code. Your config.json and any learned classifier.json are
kept — they are your data, not the tool's.
Lifecycle verification
Beyond the unit suite, the full session lifecycle was exercised end-to-end with simulated user sessions driving the real hook and statusline binaries in isolated sandboxes (MODEL_SWITCHER_HOME) — about 50 scenarios including hostile input, all passing with exit code 0:
| Lifecycle phase | Coverage |
|---|---|
| Session start | Setup nags fire once (missing config, null pricing); slash-command first prompts preserve the nag; garbage stdin, path-traversal session IDs, and corrupted config all fail open; statusline always prints one line |
| During session | 12-turn conversation mixing simple/complex/affirmation/negation/stack-trace prompts; subagent and command-tag contexts skipped; hostile shell-metacharacter prompts stay inert data; statusline turn/session math hand-verified incl. sidechains, streamed-duplicate dedupe, and unpriced-model flagging |
| Resume / restart | Nag state survives resume and re-fires only for new sessions; stale state cleanup touches only its own files; corrupted state self-heals; config flips apply on the next prompt; resumed transcripts never double-count |
| Routing switch | Global toggle and per-project overrides across every combination; malformed, oversized, injection, and wrong-typed overrides all fall open to the global config |
Full scenario tables and findings: docs/lifecycle-test-report.md.
How cost is calculated
statusline/cost_statusline.py stream-parses the session transcript (.jsonl), dedupes streamed assistant messages by message ID, and sums input, output, cache-creation, and cache-read tokens per model. Claude Code writes each spawned agent to its own file under <project>/<session-id>/, so those are read too and attributed to the turn by timestamp — without them, agent-heavy sessions under-report badly. Cost = tokens × your configured $/MTok rates, computed entirely offline. It is an estimate derived from transcript usage, not your official Anthropic bill.
Cache writes are split by TTL: the transcript reports ephemeral_5m_input_tokens and ephemeral_1h_input_tokens separately, and each bucket is priced at its own rate. Where that per-TTL breakdown is present it is treated as authoritative — a few entries carry a flat cache_creation_input_tokens total that disagrees with the breakdown beside it, and mixing the two would double-count. Entries reporting usage.speed == "fast" are priced from the model's fast rate block when one is configured.
Is this a subagent or a skill?
It uses a subagent, but the project is not only a subagent. model-switcher combines:
- A
UserPromptSubmithook for deterministic prompt scoring — the only thing that runs on every prompt - A
heavy-task-*subagent — the only supported way to run part of a session on a different model - A statusline command — the only always-visible, deterministic output surface
- A
CLAUDE.mdpolicy block that makes the delegation directives binding
A skill or subagent alone cannot do the whole job because they only run when invoked.
Development
python3 -m venv .venv
.venv/bin/pip install pytest pytest-cov
.venv/bin/python -m pytest tests/ -q                 # full suite
.venv/bin/python -m pytest tests/ -q -m lifecycle    # real install.sh against a temp CLAUDE_DIR
Runtime code is stdlib-only; pytest/pytest-cov are development-only dependencies. CI runs the
suite on Python 3.10–3.14, lints with ruff and shellcheck, enforces an 80% line-and-branch
coverage floor per file, and exercises a full install/uninstall cycle on Linux and macOS.
The router fails open (a hook error never blocks your prompt), the statusline always prints a line, and prompt text is treated as untrusted input everywhere. See CONTRIBUTING.md for the full check list, CLAUDE.md for project conventions, and docs/adr/ for decision records.
Contributing
Contributions are welcome, especially around:
- Better prompt scoring heuristics
- More test cases for edge-case prompts
- Cost reporting improvements
- Documentation and demo examples
- Safer install/uninstall behaviour
main is protected: all changes arrive as pull requests and are reviewed and merged by the maintainer. Open an issue first if you want to discuss a larger change. Start with CONTRIBUTING.md — it lists the checks CI runs and the hard rules for code on the per-prompt path. Security issues go through SECURITY.md, privately, rather than a public issue.
Roadmap
- Add CSV export for cost summaries
- Add per-project config override — shipped in v0.2.0
- Add a dry-run mode that only shows routing decisions —
model-switcher explain - Learn routing weights from your own history —
model-switcher learn - Calibrate the threshold against your own history —
model-switcher tune - Show what the learned weights contain and which projects taught them —
model-switcher classifier - Publish first tagged release — v0.1.0
Ideas to fork or extend
- Smarter complexity scoring
- Repo-specific or per-language routing rules
- Daily or weekly cost reports
- Ports to other agentic tools that expose similar hook mechanisms (opencode, Codex CLI, and Gemini CLI are the closest candidates)
FAQ
Does this really switch Claude Code models per prompt?
Not directly — Claude Code does not expose a hard per-prompt model switch from hooks. This project routes complex work by injecting a mandatory delegation directive, reinforcing it through a CLAUDE.md policy block, and using a heavy-task-* subagent configured with the heavier model.
Does this send my prompt to another service?
By default, no. Enabling Jev sends the current request and model menu to TypeSafe before routing.
The local scorer, transcript analysis and statusline remain offline. See Jev setup.
Does the cost tracker show my real bill?
No. It estimates cost from local transcript token usage and your configured pricing table. Treat it as a local estimate, not an official bill.
Does it work with claude.ai?
No. It only works with local Claude Code sessions where local hooks, agents, settings, and statusline commands are loaded.
Why not use only a subagent?
Because a subagent does not automatically run before every prompt. The hook is needed for deterministic pre-prompt scoring.
Why not use only a hook?
Because the hook cannot directly switch the main session model. The subagent is the supported way to run the complex part of the work on a different configured model.
Why add a policy block to CLAUDE.md?
The hook injects a per-prompt directive, but per-turn context is weighted less than system-prompt content. The CLAUDE.md policy block gives Claude a standing, system-prompt-level instruction that makes the routing directives binding in practice.
License
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi