titration
Health Uyari
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 6 GitHub stars
Code Basarisiz
- spawnSync — Synchronous process spawning in docs/deck/build.mjs
- process.env — Environment variable access in docs/deck/build.mjs
- process.env — Environment variable access in examples/ticket-triage/triage.mjs
- network request — Outbound network request in examples/ticket-triage/triage.mjs
- process.env — Environment variable access in ingest/embed-cards.ts
- process.env — Environment variable access in ingest/ingest-base.ts
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Let your coding agent fix a prompt until it actually works, and prove it did. A self-hosted MCP server: cross-vendor judges, frozen baselines and memory.
Titration
Let your coding agent fix a prompt until it actually works, and prove it did.
Point your agent at a prompt that misbehaves. It changes the prompt, reruns it, and Titration
grades every attempt against a baseline that doesn't move, with judges from other AI vendors.
The loop keeps going until the problem is gone, or until Titration tells you the prompt was never
the problem.
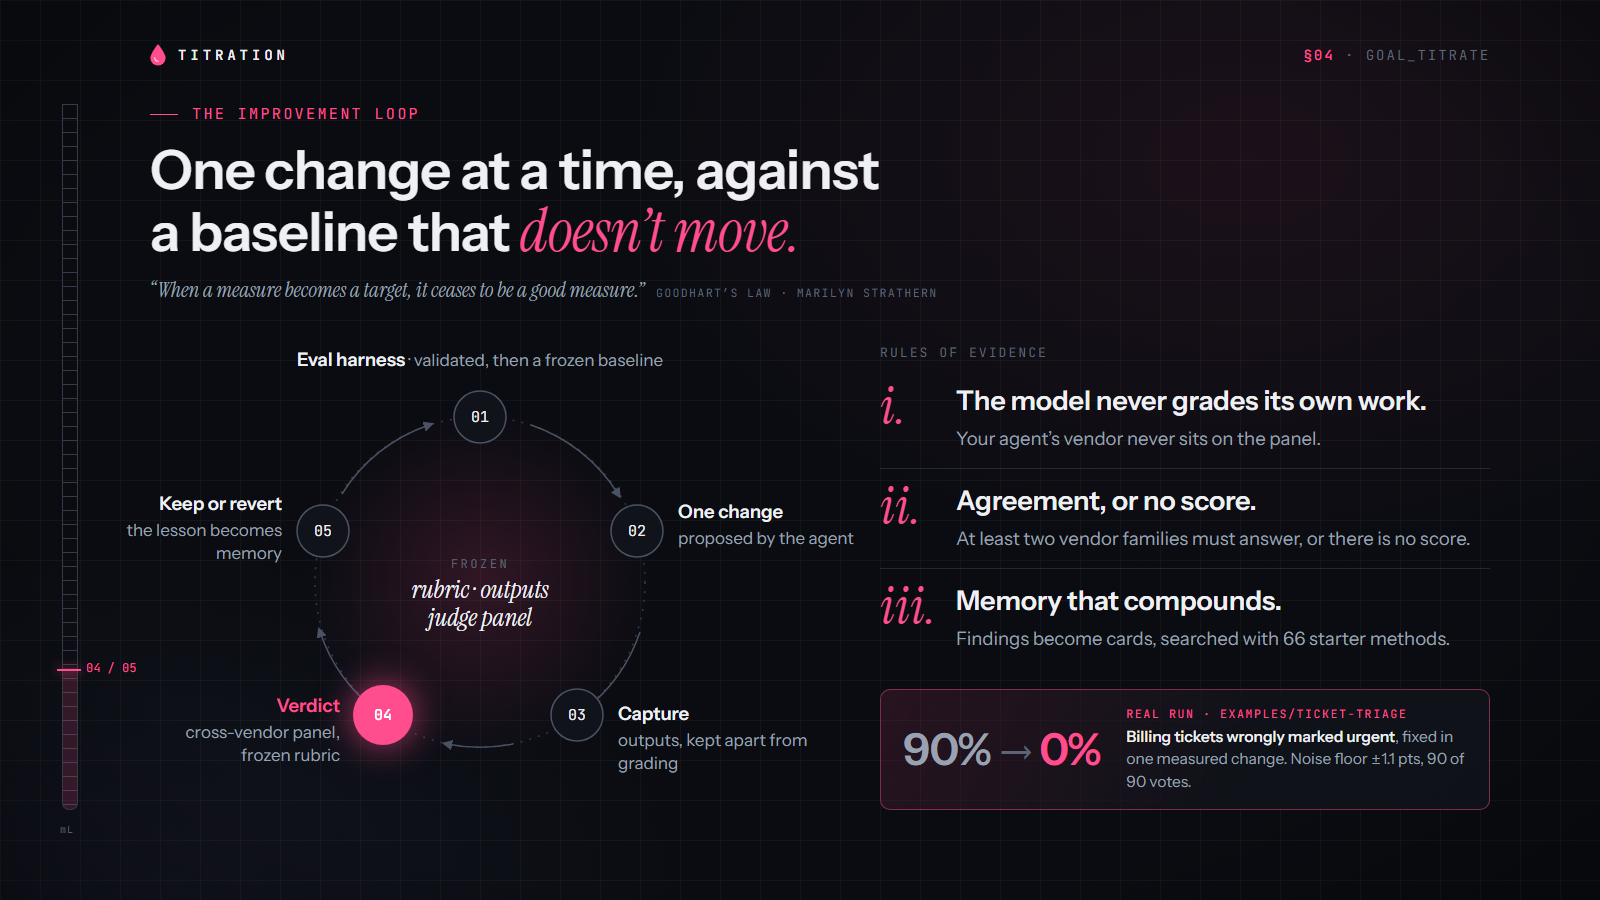
Real run: billing tickets wrongly marked urgent went from 90% → 0% in one measured change
(worked example).
An open-source MCP server with 18 tools. Self-hosted. Setup for Claude Code, Codex and Cursor.
Five-slide overview (PDF)
Why you can trust the loop
An agent that iterates against a score will happily game the score. Titration is built so it can't:
- Other vendors grade the work. Your agent's own vendor is never on the judge panel, and a
score needs judges from at least two vendor families to answer. Fewer, and the attempt is
refused with the reason and never scored. - The baseline doesn't move. A baseline freezes its rubric, its outputs and its judges, so
"better" always means better against the same yardstick. - Noise is not a win. A change inside the judges' disagreement band comes back
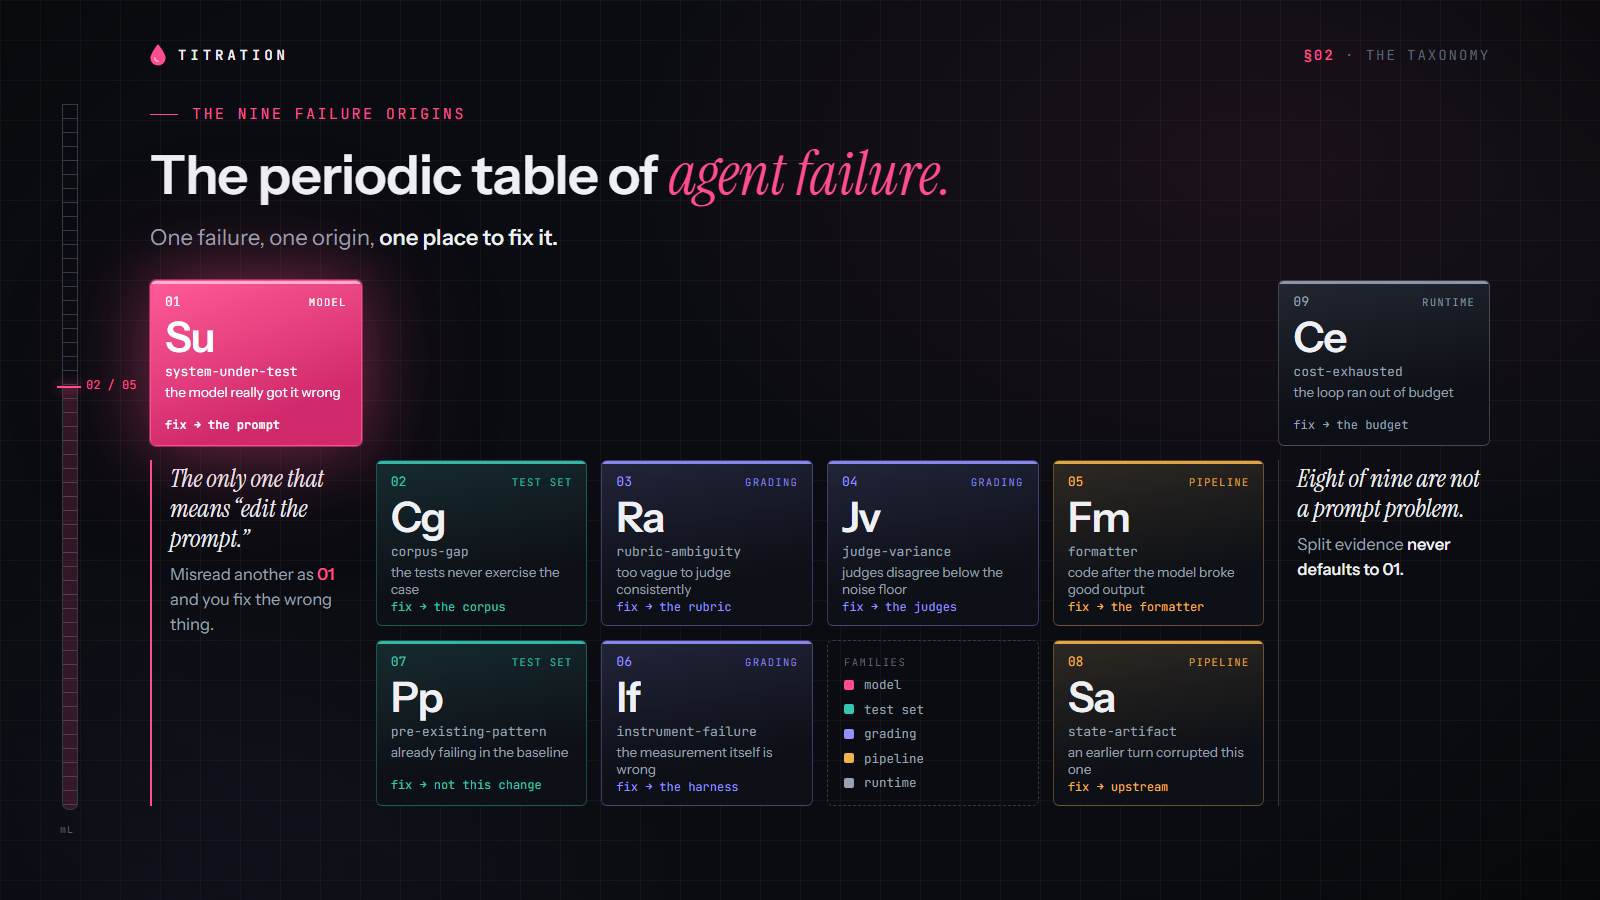
inconclusive, neverpassed, and a gain that breaks another group of cases doesn't ship. - It tells you when it isn't the prompt. Every failure is classified into one of nine
origins. Only one of them means "edit the prompt"; the others point at your test set, your
rubric, your judges or the code around the model. - Memory that compounds. What each run learns becomes searchable cards your agent can use
next time, alongside a starter pack of 66 evaluation methods. - Yours. Your Postgres, your keys, your judges. Nothing leaves your machine except the calls
to the judge and embedding providers you choose.
How it works
"The first principle is that you must not fool yourself, and you are the easiest person to fool."
(Richard Feynman)
"When a measure becomes a target, it ceases to be a good measure."
(Goodhart's law, as put by Marilyn Strathern)
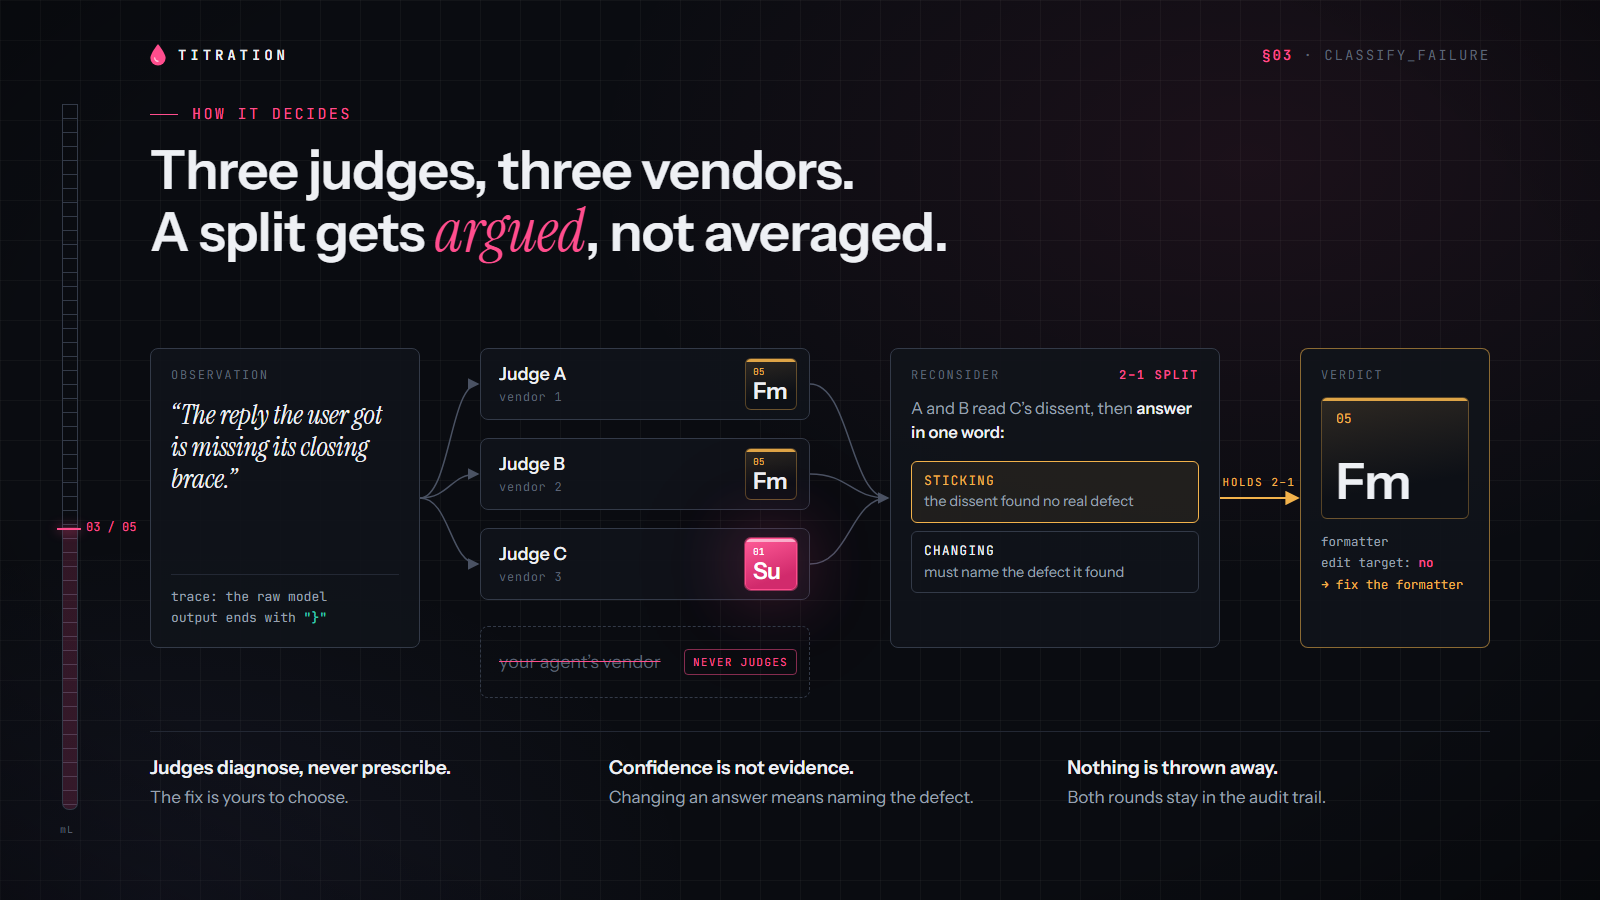
Titration never pulls or runs your code. Your agent sends the outputs it wants judged; Titration
grades only those declared outputs against the rubric. It runs as a local MCP server over stdio,
calls the judges you pick, and stores everything in your own Postgres.
Quickstart (about 5 minutes)
You need Node.js 22.11+, Docker, and access to judges from three vendor families
other than your agent's own (a panel is three judges from three families, and your agent's
family never judges its own work).
- An OpenRouter API key covers this on its own (12 models across 9
families) and also turns on memory search. This is the simplest start. - The subscription CLIs can fill up to two seats at no per-call cost:
claude
(npm i -g @anthropic-ai/claude-code),codex(npm i -g @openai/codex), andgrok.
With them, a panel is typically two CLIs plus one OpenRouter model.
git clone https://github.com/kaithoughtarchitect/titration.git
cd titration
docker compose up -d          # Postgres + pgvector on localhost:5432
npm install
cp .env.example .env          # then set OPENROUTER_API_KEY if you have one
npm run setup                 # applies the schema, loads the base starter pack
npm run setup is safe to re-run. Without an OpenRouter key it still loads the starter pack,
but card search (vector search) stays off until you add a key and run npm run embed.
Connect your agent
The server speaks MCP over stdio. Point your client at server/server.ts in your clone
(replace the path):
Claude Code
claude mcp add titration -- npx tsx /absolute/path/to/titration/server/server.ts
Codex (~/.codex/config.toml)
[mcp_servers.titration]
command = "npx"
args = ["tsx", "/absolute/path/to/titration/server/server.ts"]
Cursor (.cursor/mcp.json)
{
  "mcpServers": {
    "titration": { "command": "npx", "args": ["tsx", "/absolute/path/to/titration/server/server.ts"] }
  }
}
The server reads .env from the clone itself, so no secrets go into client config.
Restart your agent after adding the server.
Optional: agent skills
skills/ contains three skills that walk an agent through the whole flow —
scout (find what is worth measuring), harness (design and validate the measurement),
improve (baseline, then improve against it). See skills/README.md.
Choosing judges
The first time your agent establishes a baseline, it calls referee_panel_mint and a small
page opens in your browser (served on 127.0.0.1 only). Pick three judges from three
different vendor families; your agent's own family is greyed out, and so is the vendor of the
model your app calls, when the agent passes it as sut_model (a judge may favour its own vendor). The panel is locked to that
baseline, so every later comparison uses the same judges. (Diagnosing a failure withclassify_failure is not grading, so that panel may include your agent's own vendor.)
| Door | Cost | Notes |
|---|---|---|
claude CLI |
your Claude subscription | verified |
codex CLI |
your ChatGPT subscription | verified |
grok CLI |
your Grok subscription | built; unverified — help wanted |
| OpenRouter | pay per token | 12 curated models across 9 vendor families |
Edit judges-roster.json to change the pool. To add an OpenRouter model, first record its proof
calls with npx tsx scripts/record-openrouter-fixtures.ts <slug> (a fraction of a cent). For unattended runs or CI, setTITRATION_JUDGES in .env to a comma-separated list of roster ids, or to auto to let
Titration pick three families you have access to (subscription CLIs first, never the Player's
family).
What grading costs: each judged output is one call per judge. A 20-output baseline with a
three-judge panel is 60 judge calls — free on subscription CLIs (within their usage limits),
and billed per token on OpenRouter models.
Tools
| Area | Tools |
|---|---|
| Memory | card_search, card_get, card_create, card_relate, card_distill, run_capture, propose_cards, edge_propose |
| Measurement design | harness_design, harness_validate |
| Grading | referee_panel_mint, referee_panel_status, establish_baseline, verify, classify_failure, job_status |
| Improvement loop | goal_titrate, goal_titrate_step |
Every memory, grading and loop tool takes an optional project (default default) so one
database can keep several codebases apart. (harness_validate is stateless and takes none.) __base__ is the read-only starter pack.
Contributing
Issues and pull requests are welcome — see CONTRIBUTING.md. A good first
contribution is a new learning for the base starter pack in docs/core-learnings/, or
recording a verified fixture for the grok judge door.
License
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi