a11y-toolkit
Health Uyari
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 6 GitHub stars
Code Basarisiz
- rm -rf — Recursive force deletion command in .github/workflows/npm.yml
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
The accessibility layer for AI coding agents, WCAG 2.2: static and rendered audits (light AND dark), contrast over images, blindfold usability testing, PDF/DOCX screening, caption quality, prefers-reduced-motion audit, evidence packs a human can sign. Zero deps
a11y-toolkit — the accessibility layer for AI coding agents
🌐 English · Español
WCAG 2.2 for your coding agent — audit, fix, document and watch. Zero dependencies, es/en.
37 MCP tools, 5 prompts and a skill covering the whole WCAG 2.2 loop: audit, fix,
document, watch, hand off — and now blindfold usability testing, where the agent
attempts real tasks perceiving only what a screen reader exposes. 51 of 55 A/AA criteria carry automated signals (93%), every
finding ships with a concrete remediation your agent can apply, and the rendered tools
run on whichever browser you have — Chromium, Firefox, WebKit, Chrome or Edge.
The European Accessibility Act is in force since June 2025, ADA suits keep landing,
and AI agents now write most of the web. A scan is not a defence: the machine finds,
the human signs.

Quickstart
# MCP — one line, any MCP client (Claude, Cursor, Codex, Windsurf, …)
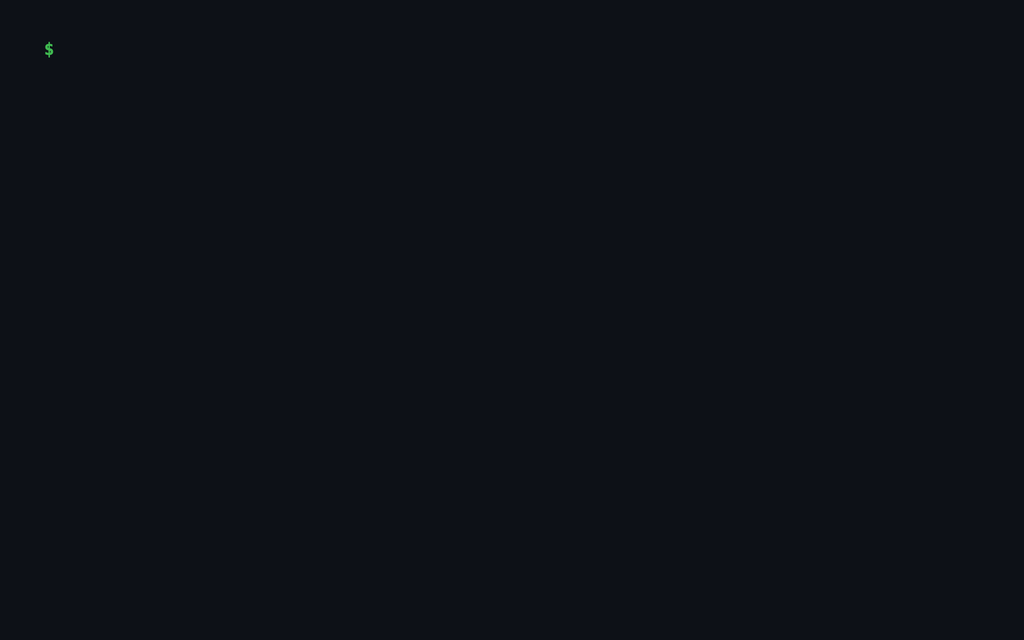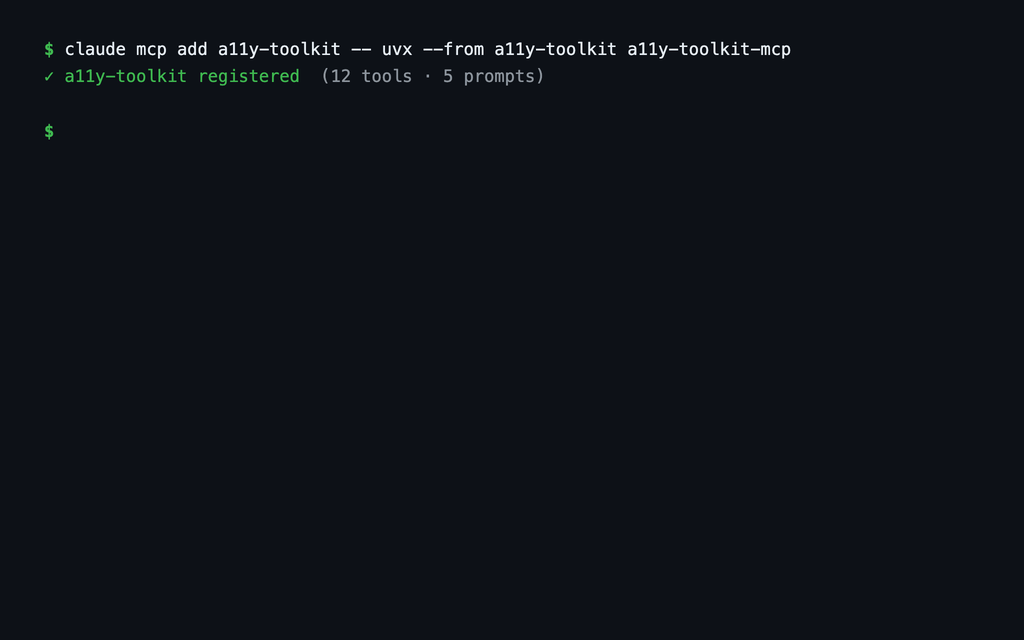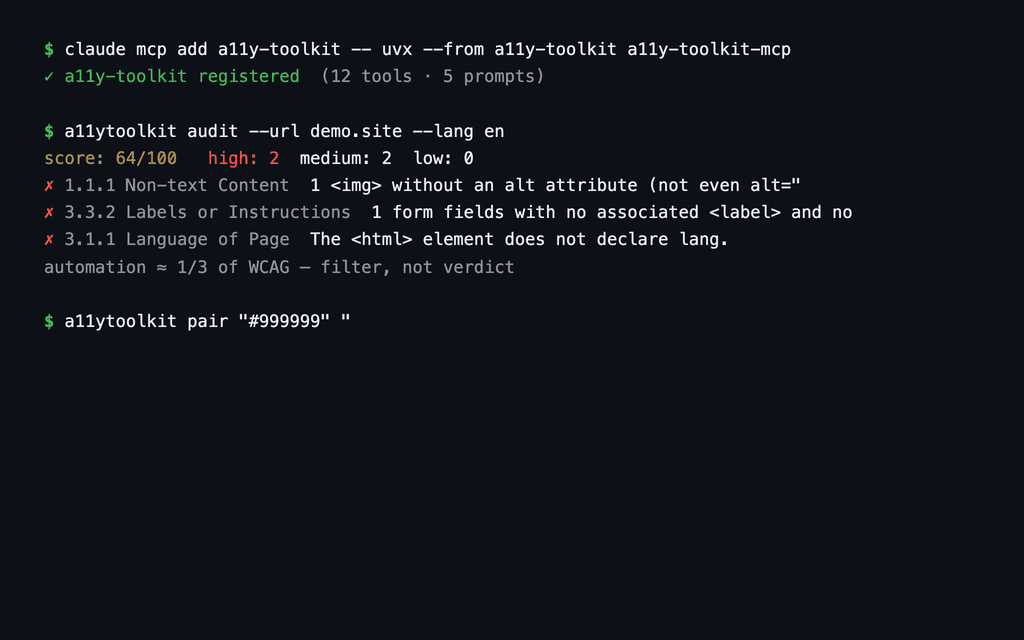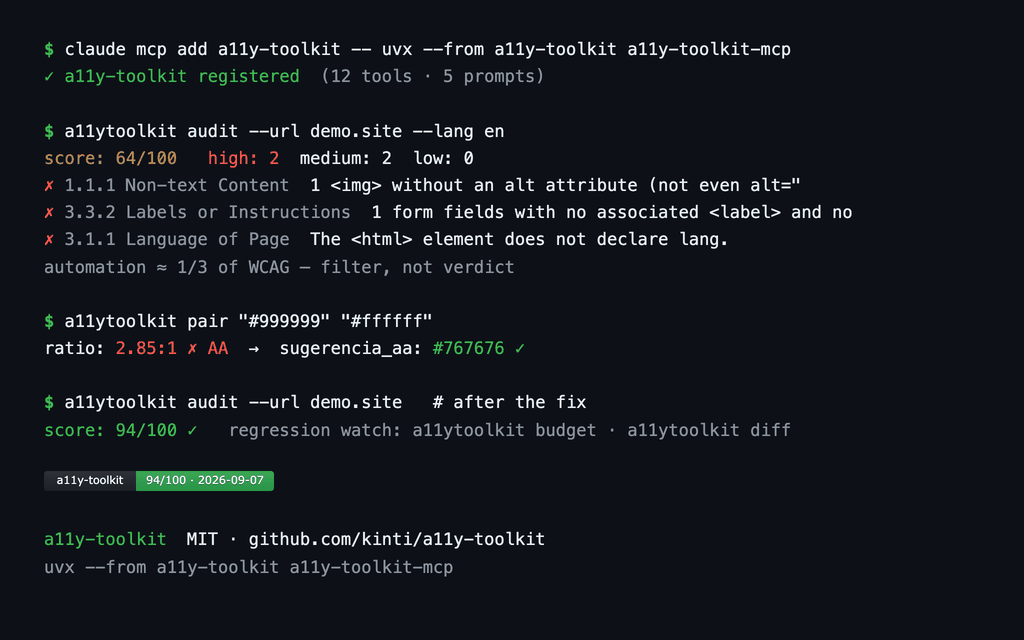
claude mcp add a11y-toolkit -- uvx --from a11y-toolkit a11y-toolkit-mcp

# CLI — same engine, one command
pip install a11y-toolkit
a11ytoolkit audit --url https://example.com
a11ytoolkit pair "#1f2328" "#fbfaf7"
Static audits, contrast math, PDF/DOCX screening and the evidence pack run with
zero dependencies. The rendered tools (real contrast over images, keyboard
traps, reflow, forms) additionally need Playwright:pip install playwright && playwright install chromium.






Features
| Capability | axe-core / Lighthouse / pa11y | a11y-toolkit |
|---|---|---|
| Text contrast over images and gradients (pixel sampling of the real background) | No | Yes |
| VPAT 2.5 (WCAG) draft from the evidence pack — US/ADA counterpart of the EAA statement | No | Yes |
| Form error testing: fills invalid data, really submits, judges what happens | No | Yes |
| Keyboard traps: real Tab walk + Escape-release test, plus focus/input-triggered navigation | No | Yes |
| Infinite-scroll audit: focus survival, announcements, feed end | No | Yes |
| Reflow at 320px and the WCAG text-spacing override, measured | No | Yes |
| Screen reader transcript: what a blind user hears, linearized | No | Yes |
| Tooltips that ignore Escape caught by actually hovering (1.4.13) | No | Yes |
| Legal statements for the EAA / RD 1112/2018, in Spanish and English | No | Yes |
| An evidence pack a human can sign — hashes, matrix, empty signature block | No | Yes |
| ACT Rules interop: EARL export + per-rule consistency report against official W3C test cases | No | Yes |
| WCAG 3 draft preview — regroup 2.2 findings under the draft's outcomes, no fake score | No | Yes |
| The engine examines itself: seeded WCAG mutant bank — regenerable exam, kill rate + false positives via placebos | No | Yes |
| Sequential diagnosis: pass a URL and the page's own evidence orders the exams (severity only breaks ties) | No | Yes |
| Runs with zero dependencies at core, speaks es/en, any browser you have | Heavy runtimes | Zero dependencies |
The tools (37)
Full reference — descriptions, arguments, return shapes and behavior — in docs/tools.md. All tools accept lang (en|es) unless noted; output is JSON unless noted. Generated from server.TOOLS by scripts/gen_readme.py.
| Tool | Category | What it does |
|---|---|---|
a11y_audit_url |
Audit | Express WCAG audit |
a11y_audit_dom |
Audit | Rendered WCAG audit |
a11y_audit_pdf |
Audit | PDF accessibility screening |
a11y_docx_screen |
Audit | DOCX accessibility screening |
a11y_locate |
Locate | Locate element by accessible name |
a11y_journey_verdict |
Blindfold testing | Blindfold journey verdict |
a11y_autofix |
Fix & contrast | Deterministic safe auto-fixes |
a11y_patches |
Fix & contrast | Sealed patch-set (sha-keyed) |
a11y_contrast_pair |
Fix & contrast | Contrast ratio + verdicts |
a11y_contrast_image |
Fix & contrast | Text-over-image contrast |
a11y_contrast_dom |
Fix & contrast | Live-element contrast sampling |
a11y_suggest_color |
Fix & contrast | Nearest passing color |
a11y_generate_declaration |
Document | Accessibility statement (EAA/RD 1112) |
a11y_generate_vpat |
Document | VPAT 2.5 report (WCAG edition) |
a11y_generate_openacr |
Document | OpenACR YAML report (GSA) |
a11y_badge |
Document | Honest SVG badge |
a11y_snapshot |
Watch (regressions) | A11y snapshot + tab order |
a11y_diff |
Watch (regressions) | Snapshot regression diff |
a11y_diff_urls |
Watch (regressions) | Staging vs production diff |
a11y_aria_live_snippet |
Watch (regressions) | aria-live monitor snippet |
a11y_criterion |
Knowledge & context | WCAG criterion explained |
a11y_html_validate |
Knowledge & context | W3C Nu validation |
a11y_keyboard |
Interactions | Keyboard-trap detector |
a11y_forms |
Interactions | Form error testing |
a11y_hover |
Interactions | Hover dismissibility (1.4.13) |
a11y_reflow |
Interactions | 320px reflow check |
a11y_scroll |
Interactions | Infinite-scroll audit |
a11y_sr_transcript |
Interactions | Screen reader transcript |
a11y_reduced_motion |
Interactions | prefers-reduced-motion honored? |
a11y_forced_colors |
Interactions | forced-colors survival heuristic |
a11y_vtt_check |
Interactions | WebVTT caption quality |
a11y_evidence |
Coverage & evidence | Evidence pack (verifiable handoff) |
a11y_disprove |
Coverage & evidence | Disprover: re-verify findings |
a11y_ledger |
Coverage & evidence | Coverage ledger (persistent) |
a11y_wcag3_preview |
Coverage & evidence | WCAG 3 draft preview (no score) |
a11y_scope |
Coverage & evidence | Applicability scope (semi-automatic) |
a11y_route |
Routing | Tool router (goal or page to steps) |
The 5 prompts
audit-page(url*,language): Full accessibility audit workflow for a URL: automated tools + what to verify manually (keyboard, screen reader, zoom). Every prompt exists in English and Spanish.fix-contrast(fg*,bg*,context): Guided contrast fix: verify the pair (or the text-over-image region), get the nearest passing color, apply it to the code. Every prompt exists in English and Spanish.pre-deploy-check(url*,baseline): Pre-deploy regression check: express audit of the URL plus snapshot diff against a baseline snapshot. Every prompt exists in English and Spanish.declaration-eaa(entity*,url*,status): Generate a European Accessibility Act / RD 1112/2018 accessibility statement, collecting any missing legal fields from the user. Every prompt exists in English and Spanish.blindfold-task(url*,goal*,kind,language): Blindfold usability test — the agent attempts a real task perceiving ONLY the accessibility tree and acting only by accessible name and keyboard, logging friction per step; closes with a11y_journey_verdict. The capability no other accessibility tool has: task-based non-visual testing where the agent IS the screen-reader user. Every prompt exists in English and Spanish.
Install
mcp-name: io.github.kinti/a11y-toolkit · PyPI: a11y-toolkit · Zenodo DOI:
10.5281/zenodo.22843722
Works with any MCP-capable client — Claude Code/Desktop, Cursor, Windsurf, VS Code,
Codex CLI, OpenCode, ZCode, Zed, Cline, Continue, Kimi Code… See
docs/clients.md for every verified config format.
Node-native? npx -y @kinti/a11y-toolkit mcp… — the npm launcher runs the
same engine (npm/). Composing it
with the popular servers (Playwright, GitHub, Filesystem, Fetch…) —
docs/interop.md.
Start-to-finish recipes (audit → fix → seal → CI):
docs/cookbook.md.
claude mcp add a11y-toolkit -- uvx --from a11y-toolkit a11y-toolkit-mcp
Or with JSON config:
{
  "mcpServers": {
    "a11y-toolkit": {
      "command": "uvx",
      "args": ["--from", "a11y-toolkit", "a11y-toolkit-mcp"],
      "timeoutMs": 60000
    }
  }
}
Rendered tools use Playwright if present and accept a browser parameter
(auto, chromium, firefox, webkit, chrome, msedge — auto-detects the first
available). Accept auth_state (Playwright storage_state path) to audit behind login.
Everything else works with zero dependencies.
The skill
git clone https://github.com/kinti/a11y-toolkit && cd a11y-toolkit
./skills/install-skill.sh     # → ~/.zcode/skills and ~/.claude/skills
Agent hook — a11ytoolkit init
Agents that read AGENTS.md on their own get the
rule that matters — after any UI change, re-audit before calling the work
done — with the exact commands:
cd your-project
uvx --from a11y-toolkit a11ytoolkit init     # writes/merges the AGENTS.md hook (idempotent)
It also prints the MCP config block and the optional skill install step.--check reports whether the hook is present (exit 1 if not — CI-friendly).
Languages — community locale packs
All user-facing messages (findings, remediations, legal wording) live in
locale packs — one JSON per language, es and en
ship today. Adding a language is a single-file PR: copy_template.json, translate keeping the{placeholders}, and python3 tests/test_locales.py validates it mechanically
(keys, placeholders, plural rule, completeness). Same community model as
axe-core's locales — with validation axe-core doesn't have. Guide:
docs/i18n.md. Downstream products can layer brand wording via
overlays without forking.
Claim an open language: French, Brazilian Portuguese and German have seeded
issues under good first issue
— one JSON file, mechanical validation, credit in the README and in the release
notes. Any other language: use the
Add a language template.
Human translation only — machine translation is rejected; the catalog IS the
product's voice.
CLI — same engine, one command
Install it with pip install a11y-toolkit (or uv tool install a11y-toolkit).
a11ytoolkit audit --changed                     # ONLY what changed since HEAD (CI gate)
a11ytoolkit audit --changed --base origin/main  # a branch's changes — exit 2 on high/medium
a11ytoolkit audit --url https://example.com --pages 5   # sitemap-first crawl
a11ytoolkit pair "#1f2328" "#fbfaf7"                    # contrast
a11ytoolkit image hero.jpg --text "#fff" --region 120,40,420,90
a11ytoolkit forms https://mysite/contact                # form errors
a11ytoolkit kbd https://mysite                          # keyboard traps + 3.2.1/3.2.2
a11ytoolkit reflow https://mysite                       # 320px reflow
a11ytoolkit scroll https://medium.com/feed              # infinite scroll
a11ytoolkit validate --url https://example.com          # W3C Nu
a11ytoolkit hover https://mysite                        # tooltip dismissibility
a11ytoolkit dom https://mysite                          # rendered audit (contrast, 2.5.8, focus)
a11ytoolkit fix --file page.html -o fixed.html          # safe autofix
a11ytoolkit declaration --entity "Acme" --url https://… --status partial --framework eaa
a11ytoolkit snapshot https://mysite --out before.json   # before deploy
a11ytoolkit diff before.json after.json                 # after deploy
a11ytoolkit evidence audit.json -o pack.json            # verifiable evidence pack
a11ytoolkit disprove --url https://mysite               # re-verify findings
a11ytoolkit budget --budget budget.json --audit audit.json  # only NEW findings block
a11ytoolkit budget --init-snapshot s.json > structural.json      # structural budget: today's structure is accepted
a11ytoolkit budget --budget structural.json --snapshot s2.json   # only NEW rendered structure blocks (exit 0/2)
a11ytoolkit engines https://mysite                        # same page in 3 engines: behavioral divergences, pairwise
a11ytoolkit trace https://mysite --script journey.json -o t.json  # scripted real journey, then: trace diff t_old.json t.json
a11ytoolkit patterns https://mysite                       # APG keyboard contracts, live: dialog / tablist / disclosure / combobox / menu / slider
a11ytoolkit ledger recurrence --ledger a11y-ledger.json   # chronic signals + hot urls: the review queue without ML
a11ytoolkit contrast-dom https://mysite --walk            # perceptual pass: per-element ratios, thresholds, suggestions
a11ytoolkit sarif --from-audit audit.json -o a11y.sarif # GitHub code scanning
a11ytoolkit badge --score 92 --out badge.svg            # honest SVG
a11ytoolkit contrast-dom https://mysite --selector ".hero h1"  # auto-region pixel sampling
a11ytoolkit vpat pack.json --product "Acme" -o vpat.html      # VPAT 2.5 (WCAG) draft
a11ytoolkit openacr pack.json --product "Acme" -o openacr.yaml # OpenACR YAML (GSA) draft
a11ytoolkit earl --from-audit audit.json -o earl.json          # ACT Rules / EARL export
a11ytoolkit wcag3 --from-audit audit.json                      # WCAG 3 draft preview (no score)
a11ytoolkit route --goal "gate my PR"                          # which tools for the task
a11ytoolkit route --file page.html                             # diagnosis: the page orders the exams
a11ytoolkit mutants --seed 7 --n 12                            # the engine's sealed self-exam
a11ytoolkit fingerprints pages/*.html -o templates.json        # twin pages → one audit per template
a11ytoolkit audit --url page.html --standard en301549          # EN 301 549 clause on every finding
a11ytoolkit annotate page.html --report r.json -o marked.html  # per-element marks on a byte-exact copy
a11ytoolkit locate --file page.html --query "Submit"           # element by accessible name → route selector
a11ytoolkit patches --file page.html -o patches.json           # sealed fix record (verify with --verify)
a11ytoolkit journey friction.json -o verdict.json             # blindfold journey: friction log -> scored verdict
a11ytoolkit scope audit.json --standard en301549 -o scope.json  # applicability scope, EN clauses, human-confirmed
a11ytoolkit criteria --list --level AA --new-in 2.2            # the offline Quick Ref, filterable
a11ytoolkit wizard --url https://client.web --lang es          # guided: 3 questions → standard, audit, scope, annex
a11ytoolkit corpus verify corpus                  # the frozen corpus, verified
Standards coverage
Which market's law each command serves: docs/standards-coverage.md
— EN 301 549 (EU-27 + EEA + Canada), Section 508 (US federal), RGAA 4.1
(France), WCAG-direct (Latin America and most ADA practice) — one engine,
the standard of 27+ countries.
Coverage: 51 of 55 WCAG 2.2 A/AA criteria (93%)
| With automated signal | Manual-only (genuinely human) |
|---|---|
| 1.1.1, 1.2.2, 1.2.3, 1.2.5, 1.3.1–1.3.5, 1.4.1–1.4.5, 1.4.10–1.4.13, 2.1.1, 2.1.2, 2.1.4, 2.2.1, 2.2.2, 2.4.1–2.4.7, 2.4.11, 2.5.1–2.5.4, 2.5.7, 2.5.8, 3.1.1, 3.1.2, 3.2.1–3.2.4, 3.2.6, 3.3.1–3.3.4, 3.3.8, 4.1.2, 4.1.3 | 1.2.1 (audio transcripts), 1.2.4 (live captions), 2.3.1 (flash detection), 3.3.7 (redundant entry) |
The 4 manual-only criteria each have a knowledge entry (a11y_criterion) telling the
agent exactly how to verify them by hand. The boundary is printed on every report.
The engine behind a11y.es
a11y.es is a Spanish-market accessibility service that runs
this engine. The service is a separate codebase; this repository is the engine.
Monitoring? You can absolutely build it yourself with this engine: a cron
running a11ytoolkit audit plus budget and diff is a legitimate path —
deliberately so, that is what the MIT license promises. a11y.es
exists for those who would rather not maintain it: scheduled audits with a real
browser, alerts on what breaks between releases, a sealed evidence vault anyone
can verify years later, and an agency portfolio — start free with 3 sites. And
the one thing no script can give: a human auditor's signature when you have to
prove it.
Validated against real pages
Benchmarked against axe-core 4.10 on real pages monthly (methodology and
results). Task-based agent benchmark on live sites,
including a stratified sample of Spain's most important pages
(method and results). Found a contrast finding on gov.uk that axe leaves incomplete
(search button at 3.91:1; manual review showed the visible part is an icon that passes the 3:1 non-text threshold, so it is not a conformance failure). Drove out our own false positives
(hidden skip links, honeypot fields, single-context generic links, image-alt accname
— each with a regression fixture).
Also run against the official W3C ACT test cases: scripts/act_report.py
regenerates the EARL implementation report
— 100% consistent with every published ACT rule it implements (355 official
test cases, 20/20 rules, zero inconsistencies, verified per release against the
w3c/wcag-act-rules repository; per-rule breakdown in
docs/act-report-summary.md). The WCAG 2.2 catalog
(86 criteria, A/AA/AAA) and the WCAG 3 outcome registry are likewise verified
against their canonical w3.org sources (scripts/wcag22_ingest.py,scripts/wcag3_ingest.py).
Why I built this
I have been auditing websites for accessibility since 2003. In twenty years the
tools got faster and the failures stayed the same: the same missing alt text, the
same keyboard traps, the same forms that swallow your work. When AI agents started
writing most of the web, the audit gap stopped being a staffing problem and became
an infrastructure one.
So I built the tool I always wanted next to me on an audit. Not another scanner —
scanners exist. A toolkit that does half the work, says exactly where it stops, and
packages the rest for the person who signs. The gov.uk finding you read about above
is not a synthetic benchmark case: this engine found it, and the manual review is what
caught the false positive before it shipped as a claim.
If it saves you an afternoon, leave a star — it genuinely helps the next auditor
find it. If it doesn't, open an issue and tell me what is missing.
Honesty, built in
Every audit says: automation covers 93% of the 55 A/AA criteria (roughly a
third of all WCAG once AAA and the genuinely-human checks are counted) — the
rest needs a human.
The audit-page prompt and the skill have the agent check what it can (keyboard,
focus, zoom, announced errors) using the manual
checklist. A filter, not
a verdict. The remaining human work is priced per criterion — MIN 23 (read and
confirm), MED 19 (verify in the browser), MAX 13 (real interaction and judgment);
full table. And the evidence pack is the handoff object
for the person who signs, screen reader transcript included, so the reviewer sees
what a blind user hears.
Security & scope
A local tool: runs on your machine as your user. a11y_audit_url accepts
http/https only (no file:// — use --file/html for local HTML). a11y_html_validate
in html mode POSTs content to the W3C service (url mode shares only the URL;
self-hosted vnu supported). path/output_path read/write local paths — use it in
MCP clients you trust.
Development
make test # every suite by discovery
tests/test_dom.py self-skips without Playwright. tests/test_solido.py enforces the design
invariants (catalog parity, version alignment, count coverage, hostile-HTML fuzz).
Releases: make release V=X.Y.Z — bumps, gates, tags and pushes atomically.
Generated surfaces — never edit by hand: this README's tool table and
docs/tools.md come from server.TOOLS
(scripts/gen_readme.py), and llms.txt — this repo's index for
agents, llmstxt.org convention — from the same source
(scripts/gen_llms.py). Both --check in the Makefile gates: adding a
tool and forgetting them fails the suite.
Roadmap
Done recently: rendered audit with shadow DOM and state contrast, form error
testing plus autofix, keyboard traps, infinite scroll, reflow, the W3C Nu
integration, SARIF and error budgets, the evidence pack (spec published,
self-verifying), sitemap crawling, behind-login auditing, browser
auto-detection, the screen reader transcript, and per-criterion effort
pricing. The full history lives in the changelog.
Next, roughly in this order:
- Attestation interlock: let an external auditor's signature reference the evidence pack by hash (their schema, my side adapts)
- Publish the monthly axe-core benchmark results from CI, run over real pages
- Screen-reader transcript cross-checks against NVDA and VoiceOver output
- More verified client configs (JetBrains AI, Gemini CLI), same treatment as docs/clients.md
Community
- Questions, ideas, show & tell → Discussions
- First contribution → the
good first issuequeue — translations are the designed entry point: no code, one file, validated mechanically (guide) - Bugs and features → the issue templates
A practical ladder: translate → docs → bug → feature. Everything you ship
is credited below and in the release notes.
Contributors
| Contributor | Contributions |
|---|---|
| @kinti | Engine, tests, docs, audits — everything so far |
The next name here is probably a translator's: claim an open locale issue and
your language ships in the next release with your name on it.
Author
Jesús Quintana Fernández (jquin.net) — SEO/GEO consultant and
web-accessibility practitioner since 2003. MIT © 2026.
License & name
The code is MIT — use it, sell it, embed it, fork it, including
in closed-source products. One thing MIT does not cover: the name.
"a11y-toolkit", the logo and the project marks are reserved and are not
part of the MIT grant — a fork or redistribution that modifies the code
ships under its own name, not ours. Same playbook as Debian and Firefox:
permissive code, protected brand.
Built something with a11y-toolkit? Tell us —
public tools get featured and credited.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi