awesome-jev
Health Pass
- License — License: NOASSERTION
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 27 GitHub stars
Code Warn
- Code scan incomplete — No supported source files were scanned during light audit
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
A curated list of Jev use cases, projects, SDKs, and resources. Jev is TypeSafe AI's System One model for fast, typed decisions in software — Choice, Score, and Noul with calibrated probabilities.
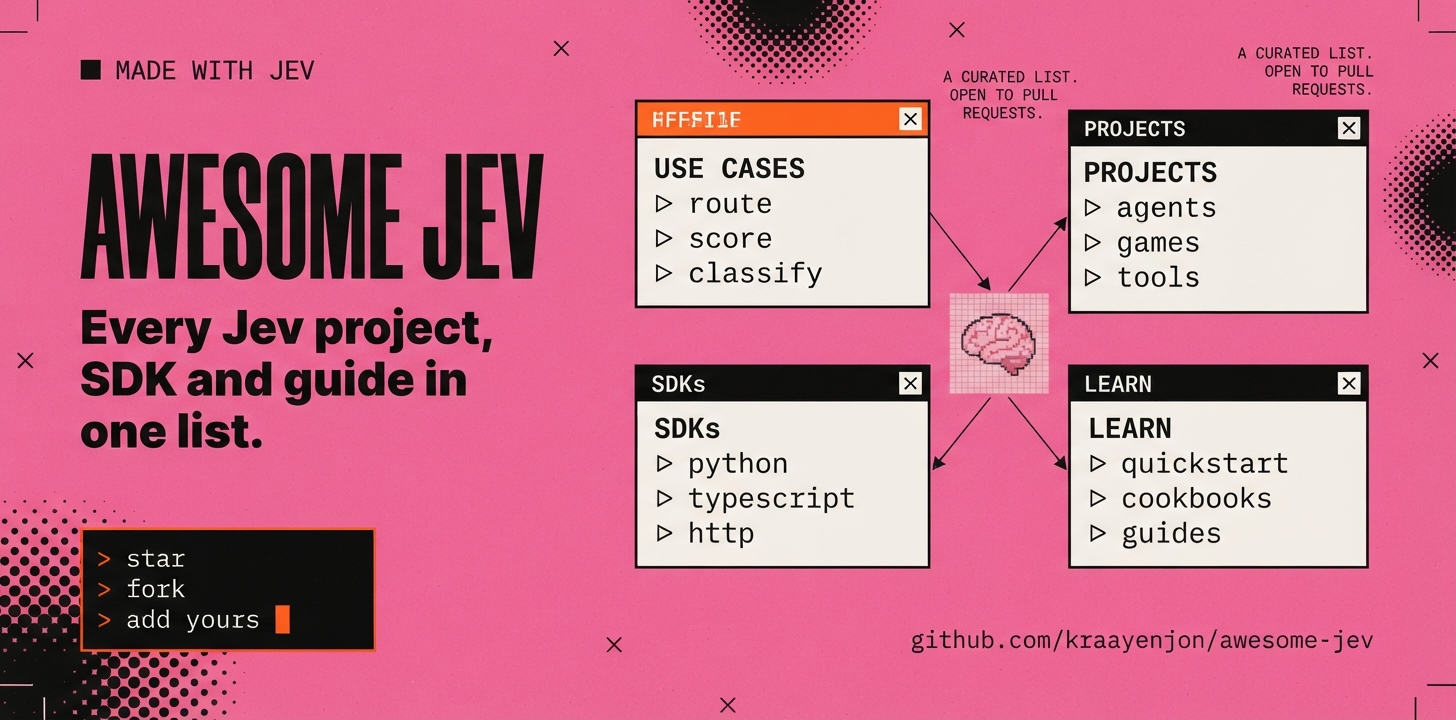
Awesome Jev

A curated list of Jev use cases, projects, SDKs, tools, and learning resources.
Jev is the first System One model from TypeSafe AI — an AI model that returns typed decisions (Choice, Score, Noul) with calibrated probabilities instead of generated text.
Looking for real-world Jev use cases with numbers? madewithjev.com is a directory of what people are building with Jev — every build with the cost, latency, and source the author reported. Submit yours →
Jev launched in early access on September 15, 2026. This list is unofficial and not affiliated with TypeSafe AI. Pull requests are welcome — the ecosystem is days old and growing fast.
Contents
- What is Jev?
- Jev vs LLM
- Pricing, limits, and access
- Quick start
- Official resources
- Community
- Featured builds with real numbers
- SDKs and clients
- Applications
- Demos and games
- Agent tools and MCP servers
- Use cases by industry
- Patterns
- Cookbooks
- Benchmarks and evaluations
- Research and open models
- Articles and coverage
- Discussions
- FAQ
- Related lists
- Contribute
What is Jev?
Large language models generate text. Jev does not. It evaluates typed questions against a state and returns values your code can branch on, sort by, and route with — plus calibrated probabilities and confidence. TypeSafe AI calls this model class a System One model: fast, structured decisions that software can use directly, trained with RLCD (Reinforcement Learning for Calibrated Decisions).
text or JSON state + typed questions → constrained answers + probabilities → your code
Jev exposes three question types. Questions in one request run in parallel against the same state.
| Question | Goal | Returns |
|---|---|---|
| Choice | Pick one option from a list | choice, probabilities, confidence |
| Score | Rate the state on a rubric | score, probabilities, confidence |
| Noul | Is this statement true? | noul (0–1) |
Use it to classify, route, score, detect, rank, extract, verify, and gate automation — anywhere you would otherwise write a brittle regex or pay an LLM to return JSON you then have to parse. Questions describe judgments; your code owns composition, thresholds, and side effects.
Jev vs LLM
From TypeSafe's launch post:
| Existing LLMs | System One + Jev | |
|---|---|---|
| Optimized with | RLHF / RLVR | RLCD (Reinforcement Learning for Calibrated Decisions) |
| Optimizes for | Human preference; verifiable rewards | Calibrated decisions with honest probabilities |
| Output | Strings that need parsing and validation | Type-safe structured values, defined in advance |
| Sampling | Sequential, token by token | Parallel, all outputs in a single query |
| Cost | $0.20–$10 / MTok input, output ~5x more | $0.042 / MTok input, output free |
| Speed (vendor-reported) | 3–329 s end-to-end for frontier models | 70–500 ms end-to-end |
| Confidence | Tends to be overconfident if asked | Calibrated confidence on every answer |
| Best at | Chat, writing, code, open-ended reasoning | Decisions inside software: classify, route, score, verify |
Jev is not a replacement for an LLM. When you need free-form text, pair them: let Jev route, retrieve, verify, or guard the call, then let the LLM write inside the boundaries your code enforces.
Pricing, limits, and access
Snapshot reviewed September 18, 2026. Check Models for current values — limits can change dynamically.
| Item | Current detail |
|---|---|
| Model alias | jev-latest (current version: jev-1.13.0) |
| Endpoint | POST https://api.typesafe.ai/v1/systemone |
| Price | $0.042 / 1M input tokens; output tokens free |
| Listed limits | 250,000 tokens/second, 1,200 requests/minute |
| Choice cardinality | Up to 255 options per Choice question |
| Modalities | Text only — no images, audio, or video |
| Direct access | Early access via waitlist at typesafe.ai |
| No-waitlist access | Vercel AI Gateway (typesafe-ai/jev) and Cloudflare Workers AI (typesafe/jev) |
Quick start
Get an API key from the TypeSafe console, then:
Python — pip install typesafe-sdk
from typesafe_sdk import Choice, Noul, Score, TypeSafeClient

state = {"ticket": "I was charged twice and need the duplicate refunded today."}

with TypeSafeClient() as client:  # reads TYPESAFE_API_KEY from the environment
    response = client.system_one(
        state=state,
        questions={
            "intent": Choice(
                instructions="What is the customer's main request?",
                criteria={
                    "refund": "The customer wants money returned.",
                    "technical_help": "The customer needs a bug or integration fixed.",
                    "information": "The customer is asking for information only.",
                    "other": "None of the other options clearly fits.",
                },
            ),
            "is_urgent": Noul(instructions="Does the ticket explicitly communicate time pressure?"),
            "frustration": Score(
                instructions="How frustrated does the customer appear?",
                criteria=["Calm and neutral", "Concerned but civil", "Very angry or using strong language"],
            ),
        },
    )

print(response.answers["intent"].choice)        # "refund"
print(response.answers["is_urgent"].noul)       # 0.0–1.0
print(response.answers["frustration"].score)    # probability-weighted rubric position
JavaScript / TypeScript — npm install @typesafe-ai/sdk
import { choice, noul, score, TypeSafeClient } from "@typesafe-ai/sdk";

const client = new TypeSafeClient();
const result = await client.systemOne({
  state: { ticket: "I was charged twice and need the duplicate refunded today." },
  questions: {
    intent: choice("What is the customer's main request?", {
      refund: "The customer wants money returned.",
      technical_help: "The customer needs a bug or integration fixed.",
      information: "The customer is asking for information only.",
      other: "None of the other options clearly fits.",
    }),
    isUrgent: noul("Does the ticket explicitly communicate time pressure?"),
  },
});
On Vercel AI Gateway, use experimental_evaluate from the AI SDK with the model id typesafe-ai/jev. See the official quick start for details.
Official resources
- TypeSafe AI - Company homepage, waitlist, and product overview.
- Introducing System One Models and Jev - Launch post by founder Diogo Almeida: architecture, RLCD, pricing, Doom and Wikiracing demos, FAQ.
- Documentation - Introduction, primitives, patterns, API, and SDKs. Start with the quick start.
- Playground - Paste a state, add questions, see typed answers in the browser.
- API keys - Dashboard for TypeSafe API keys (
TYPESAFE_API_KEY). - HTTP API reference -
POST https://api.typesafe.ai/v1/systemone. - Models, prices, and limits - Aliases, versions, and rate limits.
- Workflow evals - Published eval methodology and per-model results on automation workflows.
- GitHub org - Official open-source repositories.
- Agent skill - Drop-in skill for Claude Code, Codex, and other coding agents (typesafe-ai/skills).
- Jev 1.13 jaggedness - Known failure modes of the current public model.
- Manifesto - The case for machine-native intelligence built for software, not conversation.
- The Bitterest Lesson - Why optimizing the wrong task can dominate gains from scale.
- AI: too good to be true, too bad to be useful - Against preference-optimized chat models for automation.
- Jev on Vercel AI Gateway - Hosted
typesafe-ai/jevfor the AI SDK'sexperimental_evaluate, no TypeSafe waitlist required. - Jev on Cloudflare Workers AI -
typesafe/jevviaenv.AI.run, with worked support-routing and risk-escalation examples.
Community
- Discord - Official TypeSafe server; builder demos live in Show and Tell.
- X @typesafeai - Product and research updates.
- X @CompleteSkeptic - Founder Diogo Almeida.
- LinkedIn - Company announcements and hiring.
Featured builds with real numbers
Production-shaped uses with the cost and latency their authors reported. Each links to a full breakdown on madewithjev.com, the Jev use-case directory that maintains this list.
| Build | What it does | Reported numbers | Source |
|---|---|---|---|
| Jev plays Doom | Game loop asking Jev what to do ~10 times a second | ~10 queries/s, ~$7/hour | X |
| jev-ultrafast | Browser Use's agent with the next-action decision moved to Jev | ~2.9k stars | GitHub |
| Flight search with Browser Use | Booking flow driven end to end | ~7 s, ~$0.004 | X |
| Stagehand on a remote browser | Browser tasks at a tenth of a cent each | ~$0.001/task | X |
| jev-trader | Buy/sell decided inside a 300 ms Monad block, on Kuru's order book | 300 ms decision window | GitHub |
| Triage across 1,500 emails | A full inbox sorted in one pass | ~1,500 emails | X |
| Every's editorial vibe check | 37 documents, 21 questions each; 6 of 7 planted defects caught | 1,709 judgments, <$0.01, 0.35 s median | Every |
| 1kpapers | A corpus classified by topic and published as a site | 1,018 papers | Site |
| Jev plays chess | Legal moves as a Choice, compared with reasoning models | illegal moves impossible by construction | dev.to |
| 3,282 posts, eight questions each | Ian Nuttall's X back catalogue scored for what travels | 4.25M tokens, $0.1282, 8 m 34 s | X |
| Post scoring with SuperX | 61 questions about a draft before it ships | ~1 s, $0.0004/draft | X |
| 724 competitor ads, broken down | Hook, format, offer, CTA per ad across 37 brands | ~40 s, ~$0.09 | X |
| typesafe-computer-use | macOS computer use, one typed decision per step | ~$0.0002/step | GitHub |
| jev-drone | Tactical judgment loop flying on hardware | control at 2.5 Hz | GitHub |
| Wikiracing | Pick one link out of thousands until you arrive | 255-option Choice ceiling | TypeSafe |
All figures are as reported by each author, not measured by this list. → Browse the full directory at madewithjev.com
SDKs and clients
Official first, then community clients. Community packages are not affiliated with TypeSafe.
Official
- Python SDK -
pip install typesafe-sdk. Docs. - JavaScript / TypeScript SDK -
npm install @typesafe-ai/sdk. Docs. - System One adapter (Python) - Drop-in
TypeSafeClientreplacement backed by LLM APIs, to compare Jev against chat models on the same questions.pip install system-one-adapter. - Vercel AI SDK provider -
@ai-sdk/typesafe-aiwithexperimental_evaluate; usetypeSafeAi.evaluationModel('jev-latest')or the Gateway idtypesafe-ai/jev.
Community, by language
- Go: jev-go -
go get github.com/Gaurav-Gosain/jev-go. Also Stumble/jev-go - dependency-free, works against TypeSafe direct and Vercel AI Gateway, with an interactive CLI and an installable agent skill. - Elixir: typesafe_sdk - Hex package for
system_oneand model listing. Also Jev (OTP) - Jev as a peer GenServer; answers arrive as messages you pattern-match, with network-free tests. - Ruby: typesafe-sdk - Ruby 3.1+, retries, thread-safe pooled HTTP. Also RubyLLM TypeSafe - TypeSafe provider for RubyLLM 2. And typesafe-ai-rails - Rails integration with usage telemetry and opt-in confidence policies.
- Rust: typesafe-ai-rs - async and blocking client. Also Twister915/typesafe-ai - observable retries; typesafe-rs - latency-focused transport; s1-rs - derive layer for Choice / Score / Noul with confidence gates and network-free tests.
- PHP / Laravel: typesafe-sdk-php - typed DTOs and promises. Plus laravel-typesafe-jev - Laravel 12/13 config, facade, scoped DI, and a recording fake.
- Python: jevclient - async client (
pip install jevclient), separate from the official SDK. - Swift: swift-typesafe - Swift 6.4 client aligned with the Python SDK 0.6.0 API, including Linux.
- Scala / ZIO: zio-typesafe-ai - ZIO client with a small DSL for noul / choice / score.
- .NET: typesafe-dotnet-sdk - typed questions and confidence-scored answers.
- TypeScript: Advocaat - small client with tagged helpers for chances, choices, and scores.
- Cloud: typesafe-on-neon - Neon Function proxy for the Neon AI Gateway.
Applications
Open-source projects that put Jev in a real loop. Grouped by what Jev decides.
Browser and computer-use agents
- Jev Ultrafast - Browser agent from Browser Use. Jev picks an operation and a DOM element in one request; a small LLM writes text only for
TYPE_TEXT. Zürich → London on Google Flights in ~7 s. Library, local inspector, and measurements included. - jev-ego - Browser agent on ego lite: one TypeSafe request picks operation + indexed element; agent-facing observe/act/suggest/step CLI.
- jev-browser - An LLM plans the outcome, Jev decides each click/type on a Playwright snapshot (~300 ms/call). Ships as a library, CLI, and MCP server.
- Jev Browser (Vlad Terin) - Agent skill + runtime: Codex plans, Jev selects elements, a runner acts and verifies each step.
- typesafe-computer-use - macOS computer-use loop: OCR the screen, Jev classifies the next action, then click. About $0.0002/step.
- Mobile Jev - Android agent on Mobilerun: Jev decides each tap. Opens Uber, SFO → Golden Gate, payment screen in ~21 s / 9 actions. No ADB.
- Unclutter - Chrome / Firefox extension: Jev classifies nonessential page elements; local template rules hide them on later visits.
- TypeSafe AdBlock - Chrome extension: Jev judges whether a DOM element is an ad and removes it. BYOK, no backend; a demo, not a real ad blocker.
→ More agents and browsers on madewithjev.com
Search, retrieval, and data
- Every - Semantic code-search CLI: a yes/no question against every function, ranked by Noul probability.
- blink - Codebase search: an ensemble of walkers asks Jev which file answers a natural-language query.
- Jev Search - Web search app using Choice and Noul judgments to select sources, time ranges, and query candidates, then rank results retrieved through Search1API. Live demo: jev.s1.dev.
- neo4jev - Neo4j graph navigation: at each node Jev chooses which relationship to follow, with beam search over log-probabilities.
- jev-bfs - Finds link paths between Wikipedia articles; Jev ranks each page's outgoing links while Python controls the search.
- hono-jev-router - Experimental Hono router: Jev matches an incoming request to a plain-language route description.
- sqlite3-jev - SQLite C extension:
jev_noul/jev_choice/jev_scoreas SQL functions via libcurl. - jev-curate - High-throughput synthetic dataset sifter in Rust: Noul checks on JSONL and Parquet rows, streaming clean and rejected rows to disk.
- 1kpapers - 1,018 papers classified by topic and published as a browsable site.
→ More research and data builds on madewithjev.com
Developer tools and code review
- Jev Review - Staged code-review workflow and local dashboard driven by focused Jev calls.
- Foreman - Software-factory loop: Codex implements; Jev independently judges completeness, tests, and whether a human is needed.
- Clean Code Judge - Scores every PR file on 31 boolean Clean Code smells plus function size and nesting, then hands verdicts to a writing model for prose.
- OpenWork - Wires Jev into its eval testkit as a verification judge so agent-produced work is gated by typed verdicts.
- jev-shell-history - Fish-style zsh autosuggestions: Jev ranks recent history as you type.
- jev-secret-detection - Secret-in-diff detector with repeatable Jev verdicts.
- commit-miner - Rust CLI that classifies commit diffs: bug fixes, security/CWEs, and change types. HTML/CSV reports.
- Jev Logs - OpenTelemetry log triage: Jev scores diagnostic value and priority before an expensive LLM looks at the archive.
- typeful-triage - Multiplayer issue-triage dashboard: fixed typed questions per issue (kind, severity, urgency, duplicate, next step), with human corrections shown back to the model on later runs.
- jev-resilience - Spring WebFlux starter: a semantic circuit breaker that uses Jev to catch silent HTTP 200 failures.
- tripwire - AI SDK middleware and OpenAI-compatible proxy: seven Jev checks on every LLM response in ~100 ms, confidence-gated.
- ProgressGate - Detects semantic stagnation in agent loops: Jev judges the trajectory; code returns CONTINUE / WARN / REPLAN / HALT.
- jev-harness - Production layer around Jev: policy, confidence gate, shadow mode, recipes, and an eval CLI.
- jev-tree - Recursive Choice over a taxonomy so catalogs larger than Jev's 255-option cap still fit.
- Notra - Marketing analytics: its
NOTRA_JEV_CLASSIFIERSflag routes brand-visibility classifiers off an LLM and onto Jev boolean decisions at a 0.5 threshold, targeting 300 ms p50. - jev-eval-agent - Public eval harness for early Jev tests.
Model routing
- jev-router - Per-turn routing for Claude Code and Codex: simple work to the fast tier, hard work to the strong tier.
npm i -g jev-router. - jev-codex-router - Per-turn Codex routing: Jev picks model, thinking depth, and speed mode.
- jev-router (prismhq) - Open-source LiteLLM-based router where a Jev decision picks which model serves each request.
- pi-jev-router - Automatic per-request model routing for the Pi coding agent through Jev decisions on Vercel AI Gateway.
- jcm-router - Local proxy that picks the Claude model and reasoning effort per message while leaving the cached main chat untouched.
- jev-agent-skill-router - Routes agent skill selection through typed, confidence-aware decisions so weak matches are declined instead of guessed.
Business and vertical apps
- typesafe-jev CV screener - Screens a folder of CVs against an editable policy; re-scoring candidates is free when the policy changes.
- Jev email intent workflow - Async LangGraph workflow: a typed Choice (
invoiceorgeneral) routes each inbound email to the matching handler. - HA-Jev - Home Assistant integration: typed questions about entity state become sensors and automation actions, with usage, cost, and daily-budget entities.
- Jev Trader - One buy/sell decision per Monad block on Kuru's MON-USDC book. Live demo: jev-trader.vercel.app.
- Human Compiler - Paste corporate prose; Jev scores passive-aggression, urgency, and information density, then code emits rustc-style diagnostics. Live: human-compiler.asfarlab.fun.
- JEVMETER - Live Jev meter on any video: every sentence scored, rendered as a 16:9 edit.
- jev-audio-beeper - Low-latency audio insult detector: Jev decides, ffmpeg beeps in ~466 ms without rewriting the rest of the track.
- Jev Moderation Bot - Discord bot scoring incoming messages for phishing, spam, and social engineering, with a four-stage escalation ladder.
- citation-verifier - Checks whether each cited paper actually supports the sentence citing it: Claude locates the quote, Jev scores the support, a human makes the final call.
- LegalForecast-MTD - Benchmark that asks Jev to predict federal motion-to-dismiss rulings, scored with claim-defendant micro-Brier metrics.
- Smart home assistant demo - Official interactive demo of speculative fan-out: many questions in one call, code keeps the relevant answers, LLM only for splits and chit-chat.
Robotics and hardware
- Jev Drone - MuJoCo quadrotor: control and safety stay in code; Jev handles slower tactical judgments at 2.5 Hz.
- jev-askable-arm - Zero-shot English goals on a simulated Franka arm; Jev chains hardcoded primitives.
- robo-harness - SO-101 arm workbench: a Jev decision runner picks bounded joint steps from typed candidate actions under a spend budget.
→ More robotics and devices on madewithjev.com
Demos and games
Toys, live sites, and realtime agents. Most shipped in the first days after launch.
- Yes / No - Free no-signup Noul demo. Ask a question, get yes / no / maybe, with web search when needed.
- Jev Tetris - Jev picks rotation and column from holes, stack height, and bumpiness.
- Jev Pac-Man - Maze as JSON; Jev picks the turn at each junction in realtime.
- typesafe-mario - Super Mario Bros. from structured emulator state.
- jev-doom-agent - Browser-native Doom with Chocolate Doom WASM, spatial state, and live decision telemetry.
- jev-gomoku - MoonBit client plus Jev-vs-Jev gomoku.
- jev-t-rex-runner - The Chrome dinosaur game, played by Jev.
- snake-jev - Snake: hundreds of typed direction decisions per run. Also typesafe-snake.
- Jev Plays StarCraft - Structured-state harness for the original StarCraft shareware campaign, with verified run and probability traces.
- Jev × Civilization II - Original Civ II in a browser; Jev chooses empire, city, research, and unit actions. Experimental; no verified win yet.
- Jev Guard - Comment-moderation playground.
- Hollow Creek - Village NPCs that judge you each tick instead of chatting.
- Jev mood demo - Talk nicely or nastily over time; structured state tracks mood.
- Jev Room - One sentence → six room settings. Jev chooses, the app renders.
- TypeSafe Typewriter - Live Val Town demo: 16 typed judgments update as you type.
- got-jev - Game of Thrones roleplay: a story model writes the scene; Jev answers where Jon Snow is, how much danger, and what should play under it.
- Little Airways - Toy archipelago air-traffic control: divert / emergency / who lands first, ~150 ms.
→ More games and real-time builds on madewithjev.com
Agent tools and MCP servers
Tools that expose Jev to coding agents and MCP clients.
- TypeSafe agent skill - Official skill: primitives, patterns, and how to structure evaluations. Claude Code:
claude plugin marketplace add typesafe-ai/skillsthenclaude plugin install typesafe@typesafe-ai. Other agents:npx skills add typesafe-ai/skills --skill typesafe-ai. - eve - Vercel's agent framework. Experimental
autoModeldefaults to Gatewaytypesafe-ai/jevto pick a language model from an allowlist. - AI CLI - Vercel Labs CLI that can run Jev as the evaluation model for its
evaluatecommand. - jev-mcp (jkudish) - Node MCP wrapping three cookbook patterns:
jev_verify(citation check),jev_screen(prompt-injection guardrails),jev_find(semantic ranking without embeddings).npx -y github:jkudish/jev-mcp. - jev-mcp (blakestone-x) - Python MCP server: classify, score, check, match, and screen tools.
- Jev Review MCP - Local-first MCP: Claude Code, Codex, Cursor, and OpenCode get structured quality review from Jev while they write.
- typesafe-mcp - Go CLI and single-binary MCP for Claude Desktop, Claude Code, and Codex.
- Jevbridge - ACP/MCP adapter: typed Jev decisions and computer use beside Codex, Claude, Grok, and OpenCode.
- fast-jev-compaction - Claude Code plugin and npm library: Jev scores tool calls and drops stale ones instead of summarizing context.
- SkillRanker - Rust CLI: Jev ranks which agent skill fits the next step from live session context, with Claude Code hooks.
- pi-typesafe - Pi extension: one consented, key-managed TypeSafe client, batched
typesafe_evaluate, offline-testable transport. - pi-jev - Pi extension with a shadow-mode tool-call gate, output judge, and typed
jev_ask. - pi-warden - Pi guardrails on pi-typesafe: held tool results instead of a dialog; write checks against a project rules file.
- pi-jev-auto-mode - Pi auto mode: Jev semantically approves
bash/write/edit, and fails closed when it cannot decide. - Bicameral - Pi coding harness: LLM writes, Jev supplies typed reflexes for policy, loop detection, and review. Explicitly not a sandbox.
- ask-jev-skill - Hermes skill: ask Jev whenever the agent needs a bounded decision.
- jev-system-architect - Skill that hunts for brittle semantic logic and turns it into Choice / Score / Noul boundaries.
- augustus - Design-judgment skill: maps Choice/Score/Noul onto classical methods with a composition algebra, question-design diagnosis, and falsifying validation gates.
- jev-judgment - Agent skill that sends closed coding-agent judgments to Jev so verdicts stay typed, cheap, and comparable across runs.
- pi-typesafe-jev - Exposes System One judgments as five Pi tools; code and users keep control of thresholds, weights, and actions.
- limpet - Stop hook that keeps an agent from finishing too early by judging plain-language completion rules with Jev.
- jev-guard - Prompt-injection and dangerous-action guard for Claude Code, Codex, Pi, and ACP agents.
- dsh-auto-mode - DeepSeek Harness permission preset whose end-prompt step has Jev answer the open questions an agent leaves in its final message.
Use cases by industry
Decision shapes that recur across domains. Each is a small decision system: a state object, atomic questions, and a code-owned review branch. Expanded from TypeSafe's use-case map and workflow evals.
| Domain | Example Jev workflow |
|---|---|
| Customer support | Classify intent, detect urgency and refund intent, score frustration; route with ordinary code and escalate low-confidence tickets. |
| Security operations | Join an alert with asset context and authorizations; ask whether the activity is unauthorized, then let a deterministic playbook close, queue, notify, or contain. |
| Finance and payments | Match invoices against POs and contracts; Jev flags duplicate/fraud/wrong-vendor signals while code owns totals, dates, and execution. |
| Insurance | Run a claims rubric as independent Nouls — coverage, exclusions, fraud indicators — and map the middle band to human review. |
| Legal and compliance | Find missing clauses, prohibited claims, and policy violations in contracts, filings, and marketing material. |
| Recruiting | Evaluate job-related evidence, match candidates to roles, route applications, escalate uncertain cases. |
| Sales and lead gen | Score ICP fit, buyer relevance, pain points, and purchase intent before routing leads. |
| E-commerce | Normalize listings, extract product attributes, detect counterfeit or prohibited-listing signals, route exceptions. |
| Moderation and trust & safety | Apply org-specific criteria to toxicity, spam, fraud, and personal-data exposure, with an explicit uncertain outcome. |
| Advertising | Check brand safety, audience suitability, regulatory claims, and ad-to-landing-page alignment. |
| Gaming | Moderate chat, score engagement or frustration, detect abuse and churn signals, route player support. |
| Financial crime | Evaluate transaction narratives and KYC material; match entities and prioritize investigator queues. |
| Scientific discovery | Screen papers, label themes in qualitative research, check manuscript citations, link entities to evidence. |
| Risk and forecasting | Turn incident reports and transaction descriptions into probabilistic features for a supervised model. |
| Knowledge graphs | Classify entity types and relationships, detect contradictions, support probabilistic traversal. |
Recurring architectures worth stealing:
- Support inbox triage - Fan out intent, urgency, severity, and frustration questions in one call; act on the confident answers, route the rest.
- RAG passage filtering - Score relevance, contradiction, and injection risk per passage before the answering model sees it.
- LLM guardrails - Screen prompts, replies, and tool calls with hazard Nouls and a harm Score; policy passes, reviews, or blocks.
- Confidence-gated actions - Lower thresholds for reversible read-only actions, higher ones for risky operations, humans for the rest.
- Model routing - Let a fast typed decision choose between deterministic code, a cheap LLM, a frontier LLM, or a person.
- Structured extraction cascades - A small model extracts candidate fields; Jev verifies each value; only failures escalate to a reasoning model.
- Composite scoring - Score independent dimensions, then combine with weights you own in code — leads, candidates, vendors, risk.
- Corpus map-reduce - Ask the same questions of every document: 1,018 papers, 3,282 posts, 724 ads, 1,500 emails. Read the aggregate, not the documents.
- Real-time control - When the deadline is a frame, a block, or a tick, code generates legal actions and Jev picks one.
Patterns
Architectural recipes from the official docs.
- Speculative fan-out - Ask many questions, including ones that may not apply; filter in code.
- Confidence-gated routing - The answer is what; confidence is whether to act.
- Composite scoring - Atomic scores, weights you own in code.
- Intent routing - Classify, then hand off to logic, a specialist LLM, or a human.
See also: How to build with System One, the use-case map, and confidence.
Cookbooks
Official, copy-pasteable workflows. Full index: console cookbooks and the docs index.
- Parallel questions - Batch many questions over one state; one call instead of N.
- Line-by-line search - Score hundreds of line ids against a query with Choice + a Noul "does an answer exist?" check.
- Re-ranking - BM25 shortlist, then one TypeSafe question per query–candidate pair.
- Guardrails for LLMs - Screen messages in and out of an LLM; threshold probabilities in code.
- Double-checking citations - Whether a quote's context supports the claim; confidence gates human review.
- Classifying RAG passages - Keep, flag, or drop retrieved passages before the answering model.
- Function calling - Map natural-language requests onto ordinary typed functions with closed-set arguments.
- Skill suggestion - Rank an agent skill catalog, then read only the top few.
- Hierarchical classification - Beam search over deep taxonomies with Choice probabilities.
- SDE cascade - Two-stage structured-data-extraction cascade (mini → verify → reasoning).
- Date extraction - Ask for named date parts, resolve and validate in code.
- Pre-parsed value extraction - Regex candidates, then Jev selects the requested span.
- Knowledge graph entity alignment - Score merge / leave unlinked / send to a curator.
- Autoresearch feature discovery - Propose TypeSafe questions as numeric features for a supervised model.
- Classification using confidence - Report a fine label only when confidence is high; otherwise climb the hierarchy.
- Structure recovery - Reconstruct Markdown from de-formatted plain text.
- Self-consistency: nouls / choices - Route uncertain probabilities to review without hiding the raw values.
Benchmarks and evaluations
Official numbers are vendor-reported; these community efforts measure for themselves.
- Workflow evals - Official: four automation workflows, accuracy/cost/time per case, Jev vs frontier models.
- typesafe-ai-benchmark - Jev vs Qwen 3.8 27B on Cerebras for the same System One questions.
- Jev Rerank Bench - Reranking comparison with raw provider responses, scoring code, and uncertainty intervals.
- Jev Spam Eval - Zero-shot spam study vs trained TF-IDF baselines, with post-hoc-tuning caveats.
- Jev Phishing Bench - 2,000 emails: Jev vs Claude Haiku 4.5 on click-or-not, with calibration, latency, and cost. Haiku wins accuracy here.
- jev-agent-failure-benchmark - Who&When Pro (injected agent failures): Jev vs a strong LLM on who / which step / error category.
- jev-sec-bench - Blind prompt-injection and vulnerable-code detection benches on public corpora.
- Jev DSPy Lab - DSPy companion that records and replays TypeSafe calls while measuring calibration, selective risk, abstention, latency, and cost.
- jevcal - CLI that fits a per-question confidence threshold to a target accuracy on your own labeled data, and fails CI when a Jev update breaks locked thresholds.
- ASSAY-001 - Independent pre-registered check of Jev calibration and type safety on Banking77 / CLINC150. Split verdict, full logs. Write-up.
- Jev search rerank eval - 9,831 labelled pairs: Jev rerank vs BM25 / bge-m3. Fusion wins; Jev alone does not beat embeddings.
- Smoking-history extraction benchmark - 1,000 synthetic notes: Jev vs OpenAI structured outputs on accuracy, cost, and latency.
- Jev Playground - Benchmarks Jev against Luna, Haiku, and Gemini at choosing validated legal moves in explicit-state games.
- jev-research-eval - Reproducible eval harness plus field note for Jev Ultrafast research-browser tasks.
Research and open models
Independent work inspired by Jev's interface. These are not TypeSafe models.
- jevlike - Train a small one-pass scorer mapping context + N text options to a probability per option. Doom / chess vision demos and a Wikispeedia example. Explicitly not a reproduction of TypeSafe's architecture or RLCD.
- openjev - Can we run something Jev-like on a home RTX 3090? Reads option logits instead of generating text. Also zhihz/openjev - an independent local preview answering bilingual probability questions.
- PocketJev - On-device iPhone visual decisions with MLX + Qwen3-VL option logits. Camera + 3-choice, no text generation, ~1 s, no photo saved.
- jev-visual - Educational Jev-like visual inference on Apple Silicon: shared multimodal context, candidate scoring, sorting-factory / Breakout / gesture demos.
- jevmlx - Jev-style parallel constrained decisions for any MLX model on Apple Silicon: schema-valid JSON in one forward pass.
- JEVfire - Jev-inspired parallel decisions for CUDA LLMs via vLLM, with a browser Mario demo (~71 ms/action locally).
- decider - Qwen3.5-2B fine-tune that emits typed decisions with calibrated probabilities in one pass.
- Parallel Constrained Decoding (Qwen2.5-1B-RLCD) - Hugging Face space exploring open-source RLCD-style parallel constrained decoding.
Articles and coverage
- TypeSafe AI debuts model for machines that plays Doom - The Register's launch coverage.
- Mini-Vibe Check: TypeSafe's Jev Judged Everything I've Written in 0.7 Seconds - Every's Mike Taylor runs Jev over his writing corpus: 1,709 judgments for under a cent.
- Building a harness with Jev - LangChain on model routing and gating dangerous tool calls behind a typed decision.
- Jev, from a developer's angle - Flavio Copes on triage, RAG filtering, citation checks, and confidence gates.
- Jev, Sorted - What the launch claims survive a reading of the primary sources, and what is still vendor-reported.
- TypeSafe Jev played chess (and landed next to reasoning models) - Maxim Saplin constrains chess to legal-move Choices.
- Jev: one judge call, or twelve dimension scores? - Independent measurement on three classification tasks, with token costs and false-positive rates.
- Testing Jev on public and private data: classifier or filter? - 16,000 calls vs gpt-5.4-mini and gpt-5.6-luna; where it wins, where it breaks, and a threshold procedure.
- Jev vs Mistral and Gemini for event validation - Head-to-head at validating local event listings.
- TypeSafeのJevを正しく驚く、それってLLMでできませんか? - (Japanese) Reproduces the JSON-vs-logit shortcut on Gemma and compares Jev with LLMs on the public Mario harness.
- jev 同士に五目並べで対戦させた - (Japanese) Jev vs Jev gomoku with source and timing logs.
- Jev on AI Wiki - Community-maintained reference page.
Discussions
- Introducing System One Models and Jev - The 1,800-point Hacker News launch thread; the sceptical reading of the benchmarks lives here.
- Launch thread by Diogo Almeida - TypeSafe's founder argues RLCD-trained decision models are a shorter path to economic value than chat models.
- TypeSafe AI releases Jev (r/singularity) - Reddit frames Jev as a low-hallucination, low-cost decision model for software rather than chat.
- Testing Jev for Pi extensions (r/PiCodingAgent) - Builders using Jev as an agent tool-use safety layer.
- Jev "playing" Minecraft (r/accelerate) - Work-in-progress demo, including fleeing zombies at night.
- Model router built with Jev - Jev decides which model should serve a request before it is forwarded.
- MLP on Qwen 4B mimicking Jev - A small MLP on top of Qwen 4B reproduces Jev-like decision behaviour.
- Running a local TypeSafe Jev - (Japanese) Local Jev-style decision model attempt.
- Jev as an AI agent safety monitor - Checking each agent action first reportedly catches most attacks with almost no false blocks.
- Rethinking security engineering with Jev - Argues purely engineering decisions in security work belong to Jev rather than a chat model.
- Ask Jev anything, it will judge - Public Convex-backed demo inviting one million judged questions.
- First Jev use case in a Mac app - A shipped Mac app routes setup and troubleshooting questions to Jev when no language model is loaded.
- Jev 中文解读 - (Chinese) The System One category explained as a calibrated, typed decision layer for code.
- Launch roundup - Browser, papers, email, trading, and games in one thread.
FAQ
What is Jev?
Jev is an AI model from TypeSafe AI, launched in early access on September 15, 2026. It is the first "System One" model: instead of generating text, it evaluates typed questions (Choice, Score, Noul) against a state and returns structured answers with calibrated probabilities, in 70–500 ms (vendor-reported).
What is TypeSafe AI?
TypeSafe AI is a San Francisco AI lab founded by Diogo Almeida, previously at OpenAI, where he worked on instruction-following methods. The company raised $40M and works on "machine-native" intelligence: models built for software to consume, not for people to chat with.
Is Jev an LLM?
No. It reads natural language but never generates text. The answer space is defined in advance by your questions, so outputs are type-safe by construction and cannot hallucinate a value outside the space you gave it. See Jev vs LLM.
What is RLCD?
Reinforcement Learning for Calibrated Decisions — TypeSafe's training method for System One models. Where RLHF optimizes for responses humans prefer, RLCD optimizes for decisions with epistemically honest probabilities: higher confidence should mean higher accuracy.
How much does Jev cost?
$0.042 per million input tokens; output tokens are free. A typical typed question costs a tiny fraction of a cent, which is why the featured builds above report numbers like 1,709 judgments for under a cent.
How do I get access to the Jev API?
Three ways: join the early-access waitlist at typesafe.ai, use Vercel AI Gateway (model id typesafe-ai/jev, no waitlist), or use Cloudflare Workers AI (typesafe/jev).
What are Jev's limits?
Choice questions cap at 255 options. Text only — no images, audio, or video. Listed rate limits are 250,000 tokens/second and 1,200 requests/minute, and TypeSafe says they can change dynamically. Known failure modes of the current model are documented in Jev 1.13 jaggedness.
What is a System One model?
TypeSafe's name for a model class built for fast, structured decisions inside software — as opposed to chat models that generate text for humans. Named after the fast, intuitive "System 1" mode of thinking. Jev is the first public one.
Related lists
- awesome-jev (AnotiaWang) - Community list of Jev applications, libraries, and resources. English and 简体中文.
- awesome-jev (yibie) - Jev projects and discussions organized by application domain.
- awesome-jev-by-typesafe (Anil-matcha) - Evidence-backed use cases, patterns, and starter code.
- typesafe-ai on PyPI - Community redirect shim; the real package is
typesafe-sdk. Registered to block slopsquatting.
Contribute
See CONTRIBUTING.md. In short: open a pull request that adds a project with a link and a one-line description. It should be useful, interesting, and actually built on Jev (or clearly inspired by its interface). Mark experimental or dry-run-only paths (trading, home automation) explicitly.
Built something with Jev? Also submit it to madewithjev.com/submit to get it in the directory with your reported numbers.
License
CC0 1.0 — this list is dedicated to the public domain.
Maintained by @kraayenjon as part of madewithjev.com — a directory of what people are building with Jev. Not affiliated with TypeSafe AI.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found