agent-mcts
Health Warn
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 9 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
agent-mcts: a test-time search harness that runs Monte Carlo Tree Search over coding agents such as Claude Code and Codex CLI.
agent-mcts 🌳
Turn any coding agent into a tree-searching agent.
agent-mcts is an open-source (MIT) test-time search harness that wraps a coding agent CLI with Monte Carlo Tree Search. It is verified with Claude Code; see Supported agents for the rest. Instead of a single trajectory that either works or doesn't, your agent explores multiple solution branches, backtracks from dead ends, and concentrates budget on the most promising path.
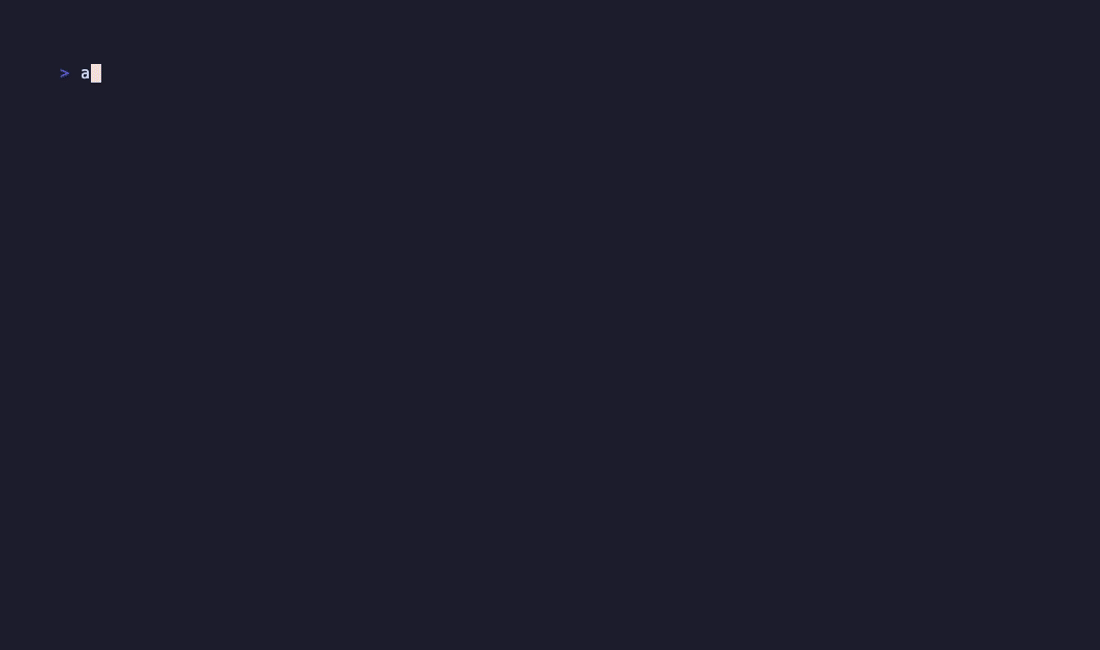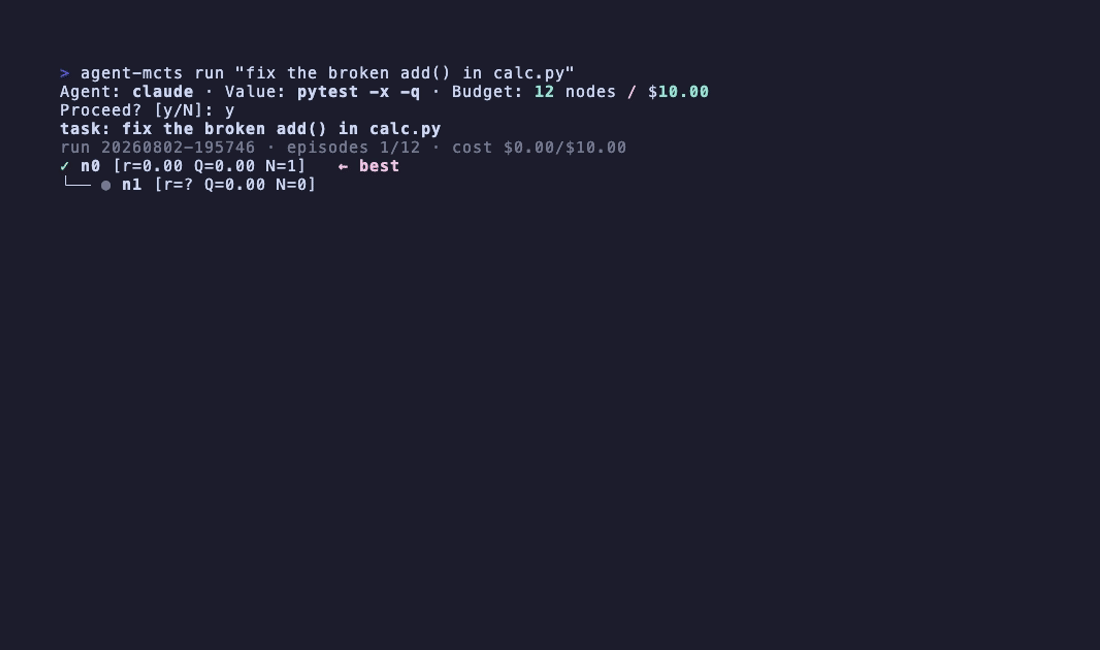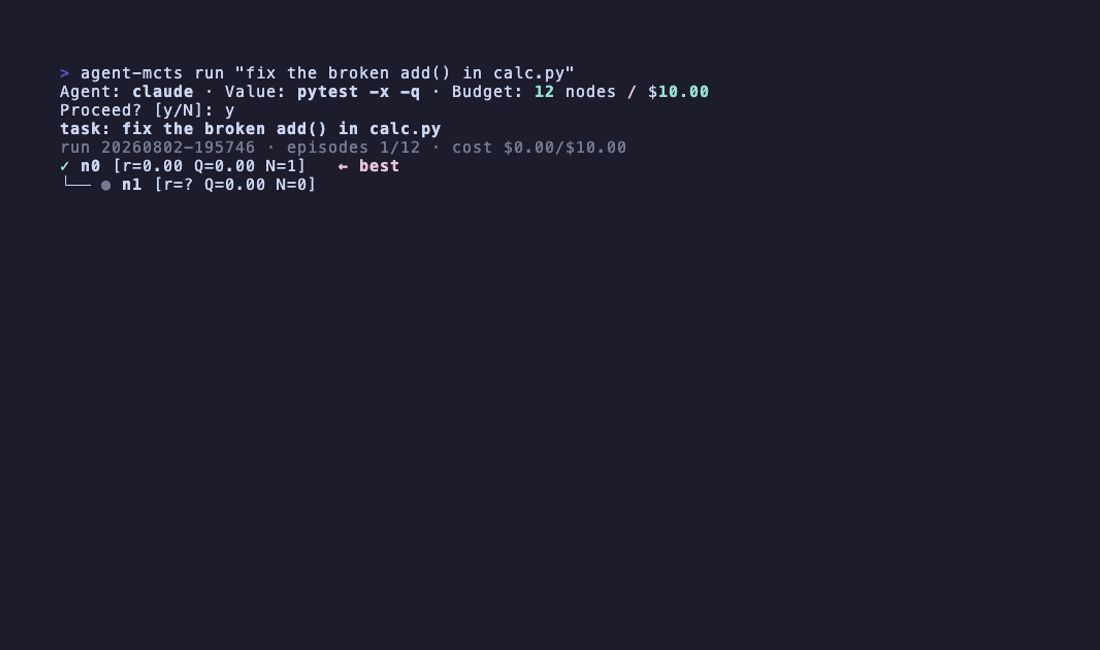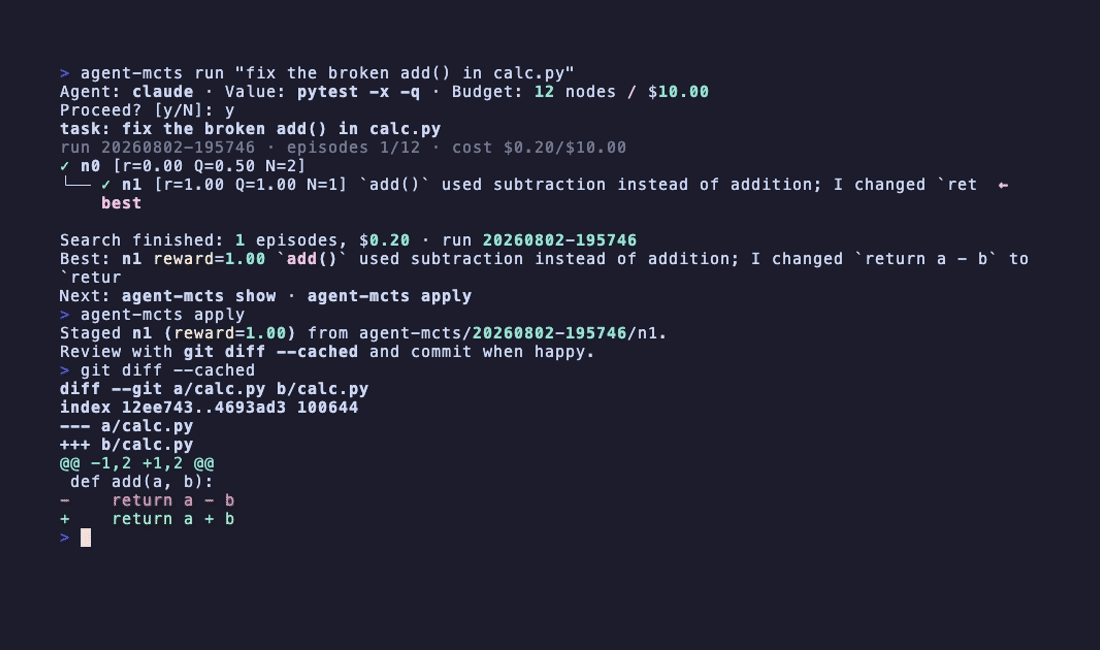
Status: v0.3. Early but real — the full loop (search → live tree → apply) works today with Claude Code. A Codex CLI adapter ships too, but so far it has only been tested against a fake
codexbinary. Built in the open; star the repo to follow along, or jump in — early contributors shape the architecture.
Does it help?
With generated tests, yes, on the two tasks measured so far (bench/, Claude Code with haiku, 5-episode budget). Each answer is scored on hidden tests the agent never sees, and compared with the first attempt of the same run, which is what a single agent run would have returned. Two tasks (npm semver ranges, ISO 8601 durations), 20 runs per setting:
| answer better than the first attempt | same | worse | mean change | worst answer | wall time | cost per run | |
|---|---|---|---|---|---|---|---|
| agent-mcts, tests only | 1 | 18 | 1 | −0.6 pt | 39% | ~5 min | $0.43 |
agent-mcts, with --judge |
11 | 5 | 4 | +5.4 pt | 68% | ~21 min | $1.81 |
agent-mcts, with --generate-tests |
16 | 2 | 2 | +4.8 pt | 81% | ~19 min | $2.44 |
What the per-run numbers show:
- Generated tests beat a single run. Before the search, an agent writes tests from the task and the code as it stands; every attempt is then scored on them. The answer improved in 16 of 20 runs and got worse in 2, by 1 and 4 points. Mean share of hidden tests passed: 88% for the first attempt, 93% for the answer returned.
- The gain mostly comes from revisions. A failing generated test tells the next attempt what to fix: 32 of 40 revisions raised the hidden score, against 13 of 40 with the judge. In 13 of 20 runs the answer beat all three first attempts.
- The judge reads diffs, and that is not enough. Its mean gain comes from rescuing two broken first attempts (19% and 37%). Over the other 18 runs it averaged +0.0 pt, and in one it replaced a 91% first attempt with a 68% one.
- Tests-only search is close to a single run. It stops at the first attempt that passes the visible tests.
Caveats: two tasks, both with a precise written spec, which is where writing tests from the task works best; one model; 20 runs per setting. Details in the full report.
Why
Production coding agents (Claude Code, Codex, Kimi, ...) run a single linear loop: act, observe, retry in place. No branching, no backtracking, no principled exploration.
Research shows search helps: SWE-Search (ICLR 2025) reported a ~23% relative improvement on SWE-bench by adding MCTS on top of software agents. But that result lives in a research framework — there is no tool that brings it to the agent you already use.
agent-mcts closes that gap:
- Bring your own agent. A thin adapter layer speaks to each agent's headless mode (
claude -p;codex execuntested against the real CLI;kimi -pplanned). The search engine never knows which agent it's driving. - Real MCTS, not best-of-N. UCT selection, expansion, evaluation, backup. Budget flows toward branches that look promising, away from dead ends.
- State you can trust. Every node is an isolated
git worktree+ a forked agent session. Your working tree is never touched until you apply a result. - Terminal-native. Watch the tree grow live in your terminal. 100% Python, no browser required.
Quickstart
uv tool install agent-mcts
cd your-project
agent-mcts run "fix the flaky test in tests/test_auth.py"
agent-mcts run --agent codex "fix the flaky test in tests/test_auth.py"   # untested with the real Codex CLI
The run auto-detects your installed agent and your test command, then shows the plan before spending anything:
Agent: claude · Value: pytest -x -q · Budget: 12 nodes / $10.00
Proceed? [y/N]
While searching, the tree grows live in your terminal (real output):
task: fix the flaky test in tests/test_auth.py
run 20260802-190219 · episodes 3/12 · cost $0.31/$10.00
✓ n0 [r=0.00 Q=0.42 N=4]
├── ✓ n1 [r=0.67 Q=0.78 N=2] mocked the clock in the auth fixture
│   └── ● n3 [r=? Q=0.00 N=0] expanding…
└── ✗ n2 [r=0.00 Q=0.00 N=1] sleep-based fix (tests timed out)
When it finishes (or when you Ctrl-C — MCTS is anytime, the partial tree is saved):
agent-mcts show        # inspect the tree; `show n3` prints a node's prompt, summary, evaluation
agent-mcts resume      # continue the latest run where it stopped (`resume -n 20` raises the budget)
agent-mcts apply       # stage the best node's changes (squash merge — you review and commit)
agent-mcts apply n2    # ...or pick a different branch
How it works
                ┌─────────────────────────────┐
                │        search engine        │   UCT selection · expansion
                │   (agent-agnostic, Python)  │   hybrid value fn · backup
                └──────────────┬──────────────┘
                               │ AgentBackend protocol
            ┌──────────────────┼──────────────────┐
            ▼                  ▼                  ▼
     claude adapter      codex adapter      kimi adapter
      (claude -p)        (codex exec)        (kimi -p)
       verified          fake-tested          planned
- Node = (git worktree, agent session). Filesystem state branches via worktrees; conversation state branches via session forking (native on Claude Code, context-injection fallback elsewhere).
- Value function = your tests. Exit 0 scores 1.0; a failing run earns partial credit by pass ratio (read from pytest, jest, cargo test, go test and JUnit-style summaries), and the failing output is fed into children's revision prompts.
pytest/npm test/make testare picked up automatically. Add--generate-teststo have an agent write extra tests from the task before the search and score every attempt on them too (generated tests), or--judgeto have an LLM score each attempt's diff (LLM judge). - Every node is a git branch (
agent-mcts/<run>/<node>), soapplyis an ordinary squash merge and everything is auditable after the fact. Worktrees are disposable; branches are the record. - Every state change is journaled (append-only jsonl per run), so an interrupted search is still a valid, inspectable tree.
Supported agents
| Agent | Headless | Session fork | Status |
|---|---|---|---|
| Claude Code | claude -p |
native (--fork-session) |
✅ v0.1, verified |
| Codex CLI | codex exec --json |
context injection | v0.2, tested only against a fake codex binary |
| Kimi CLI | kimi -p |
context injection | planned (v0.4) |
| Gemini CLI, OpenCode, ... | adapter PRs welcome! |
Configuration
Zero config required. When you need it, .agent-mcts.toml:
agent = "claude"                  # or "codex"

[value]
command = "pytest tests/ -x -q"   # exit code + pass ratio → score in [0, 1]
generate_tests = true             # also score on tests an agent writes from the task

[search]
max_nodes = 20                    # episode budget
max_cost_usd = 10.0
parallelism = 3                   # episodes in flight at once (`-j`)
CLI flags (--agent, -n, --max-cost, --value, --model, --agent-timeout, --generate-tests, --judge, -j/--parallel) override the file.
Python projects managed with uv: the value command runs inside fresh worktrees, which don't inherit your virtualenv — use
command = "uv run pytest -q"(or pass--value "uv run pytest -q") so each worktree resolves its own environment.
Every option, generated tests, the LLM judge, parallel runs, resuming and how failures, cost and timeouts are handled: docs/configuration.md.
Search hyperparameters are first-class: this is built by an MCTS researcher and meant to double as a research harness for test-time search over real software tasks.
Roadmap
- v0.1 — Claude Code adapter, UCT engine, worktree state, test-based value fn, live TUI
- v0.2 — Codex CLI adapter, episode-count budget for agents that report no dollar cost, recoverable timed-out and interrupted episodes
- v0.3 — LLM-as-judge value fn, final head-to-head selection, sibling ranking,
resume, parallel expansion, selection policy knobs - next — generated-tests value fn (
--generate-tests, onmain, not yet released) - v0.4 — Kimi CLI adapter, in-agent activation (
/treeinside Claude Code via MCP), search-tree export + richer visualization, benchmark mode (same task, N agents, compare trees)
Contributing
This project is open source under the MIT license and developed fully in the open — issues, design discussions, and PRs all happen here on GitHub. Contributions are welcome from day one.
The highest-impact contribution is an agent adapter: a few hundred lines implementing the AgentBackend protocol for your favorite CLI agent, with no need to touch the search core. Use the Claude Code adapter as the reference, and the fake-binary pattern in its tests to keep CI free of API calls. See CONTRIBUTING.md for setup.
Also welcome: bug reports, docs, benchmark tasks, and arguing with our UCT constants.
License
MIT — do whatever you want, just keep the notice.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found