transponder
Health Uyari
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Gecti
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
LLM gateway: one API in front of Anthropic, OpenAI, Gemini and Ollama, with fallback, budgets and cost tracking. Free, no paid tier.



Quick start · Docs · Demo · Contributing
An LLM gateway that knows who is spending what. One Go binary in front of OpenAI, Anthropic, Gemini, Ollama and a dozen more. It speaks the OpenAI and Anthropic APIs, falls back across providers, signs people in with your own OIDC provider, counts tokens and cost per user, team and key, and enforces budgets that hold across replicas. Every feature is free, under Apache-2.0.
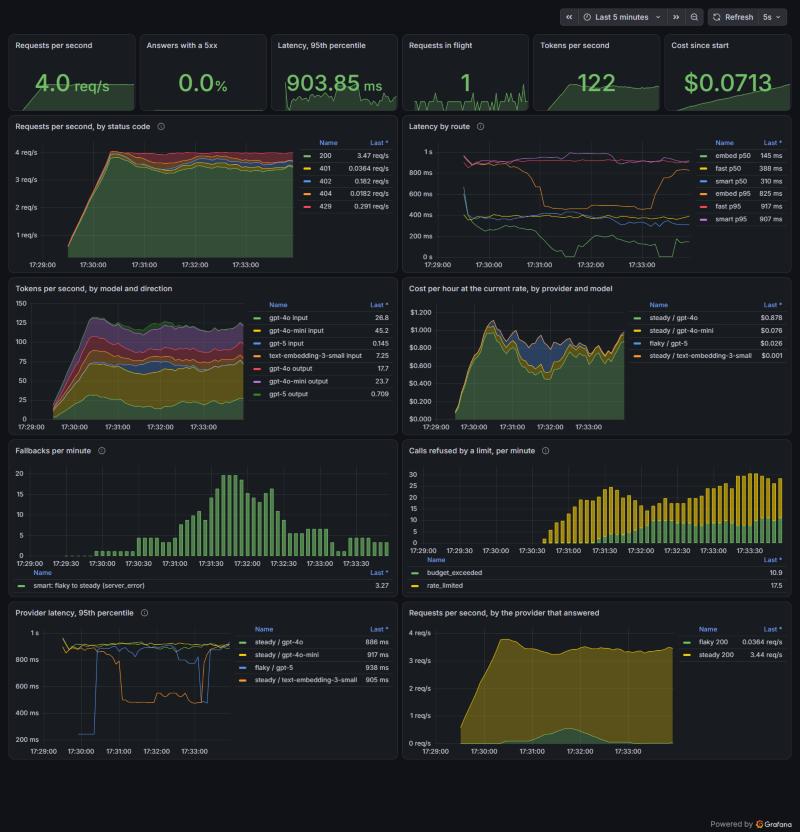
The demo: transponder in front of a fake provider, with this dashboard and traces in Jaeger. One docker compose up, no provider key.
[!TIP]
New in v0.3.0: sign-in with OIDC and roles, access per route, a JSON admin API with an audit log, Postgres with several replicas sharing budgets, Prometheus metrics, OTLP tracing, images in chat, the OpenAI Responses API, and a five-minute demo. It is also faster than v0.2.4 on the same machine:
Measured with bench/v0.2.4 v0.3.0 Chat calls a second at full load 5,836 12,235 (2.1 times) p99 latency added at full load 47.0 ms 11.6 ms (75% lower) Streamed calls that failed at full load 56% 0 CPU time of one streamed call 199 µs 141 µs (29% lower) Allocations of one streamed call 1,281 770 (40% fewer) Method, machine and every number: docs/benchmarks.md. Upgrading from v0.2.4? One change can break a config:
${VAR}no longer adds YAML structure.
Contents
- Quick start
- How it works
- Features
- Providers
- How it compares
- Use it with your tools
- Reference: configuration, fallback, images, Responses API, sign-in and roles, access per route, admin API, provider keys at rest, limits, Postgres and several replicas, metrics, tracing, updates
- Documentation
- Part of mothership
- Roadmap
- How to help
Quick start
Three ways, each a copy and paste.
1. The binary. Download one for Linux, macOS or Windows from the releases page, or build it with Go 1.26 or later:
go install github.com/raven-clown/transponder/cmd/transponder@latest
transponder
It starts with no config: SQLite in the working directory, and a one-time admin key on stderr (transponder: created an admin API key. It is shown once, so save it now:). Every model is answered by echo, a built-in test provider, so you can try it at once:
export TRANSPONDER_KEY=<the key it printed>
curl localhost:8080/v1/chat/completions -i \
  -H "Authorization: Bearer $TRANSPONDER_KEY" \
  -d '{"model": "any", "messages": [{"role": "user", "content": "hi"}]}'
# X-Usage-Input-Tokens, X-Usage-Output-Tokens and X-Usage-Cost-USD come back with the answer
To use real models, add a provider and a route, in a file or through the admin API:
# transponder.yaml
providers:
  - name: openai
    type: openai
    api_key: ${OPENAI_API_KEY}
  - name: claude
    type: anthropic
    api_key: ${ANTHROPIC_API_KEY}
routes:
  - match: "gpt-*"
    targets:
      - provider: openai
  - match: "claude-*"
    targets:
      - provider: claude
      - provider: openai     # if Anthropic fails, the call falls back here
        model: gpt-5
transponder --config transponder.yaml
2. Docker. The image is on GHCR. The database lives in the /data volume, and the admin key is in the container's log:
docker run -d --name transponder -p 8080:8080 -v transponder:/data ghcr.io/raven-clown/transponder:latest
docker logs transponder
Image tags follow the releases: v0.3.0 for one release, v0.3 for the newest patch of a minor line, and latest. To use a config file, mount it and pass --config:
docker run -d -p 8080:8080 -v transponder:/data -v "$PWD/transponder.yaml:/etc/transponder.yaml:ro" \
  -e OPENAI_API_KEY -e ANTHROPIC_API_KEY ghcr.io/raven-clown/transponder:latest --config /etc/transponder.yaml
3. The demo. To see it all running before you set anything up: transponder in front of a fake provider, calls flowing through it, the Grafana dashboard above and traces in Jaeger. It needs Docker with Compose v2 and no provider key:
git clone https://github.com/raven-clown/transponder.git
cd transponder/demo
docker compose up --build -d --wait
# then open http://localhost:3000
demo/README.md says what runs and what each panel shows.
How it works
flowchart TB
    callers["Callers: OpenAI and Anthropic SDKs, Claude Code, Codex CLI"]
    subgraph gw["transponder"]
        auth["Sign-in: API key or OIDC token"]
        router["Router: route and allow list"]
        limits["Limits: budgets, rates, tokens"]
        fallback["Fallback: targets in order, cooldown"]
        auth --> router --> limits --> fallback
    end
    subgraph providers["Providers"]
        p1["OpenAI and compatible"]
        p2["Anthropic"]
        p3["Gemini"]
        p4["Ollama, vLLM, LM Studio"]
    end
    store[("SQLite or Postgres<br/>keys, config, usage, audit")]
    obs["/metrics and<br/>OTLP traces"]
    callers --> auth
    fallback --> p1 & p2 & p3 & p4
    gw -. usage and cost .-> store
    gw -. requests, latency, spend .-> obs
- A caller sends an OpenAI or Anthropic request with an API key or an OIDC token. transponder knows the user, their teams and their role.
- The first route whose
matchfits the model is chosen, if the caller is on itsallowlist. - The limiter reserves the call's estimated tokens and cost against every budget and limit that applies, or refuses it with 402 or 429.
- The route's targets are tried in order. A target that is down, rate limited or out of credit hands the call to the next one, until output reaches the caller. When the caller and the target speak the same API, the body goes through with only the model changed; otherwise it is translated.
- The real usage is priced, sent back in
X-Usage-*headers, settled against the limits, and recorded for the user, team, key and project.
docs/architecture.md follows the same call through the code.
Features
Routing and fallback
- Routes by model name with wildcards, first match wins, each with an ordered list of targets. Fallback
- Falls back on errors, timeouts, rate limits and content a target cannot take, and never after output has reached the caller. Fallback
- Puts a target that keeps failing last for a while, and says which target answered in
X-Transponder-*headers. Fallback
Providers and APIs
- 18 provider types, plus any OpenAI-compatible server. Providers
/v1/chat/completions,/v1/responses,/v1/embeddings,/v1/modelsand/v1/messages, plain and streamed, with tools and images translated between dialects. Use it with your tools- Claude Code through
/v1/messages, unchanged for Anthropic and translated for other targets. Claude Code
Sign-in and roles
- API keys, and OIDC tokens from Okta, Entra ID, Keycloak, Zitadel, Google, Auth0 or any other standard provider. Sign-in and roles
- Roles
admin,memberandviewer, mapped from token claims. Sign-in and roles - Access per route by user, team, key or role. Access per route
Limits and budgets
- Daily and monthly budgets in USD per user, team or key. Limits
- Request rates, concurrency, token allowances and caps on input, output and reasoning tokens, in the profile format the mothership projects share. Limits
- Usage and cost on every response, and
GET /v1/usagefor what a caller has left. Limits
Admin API
- Keys, providers, routes, budgets and profiles through a JSON API under
/admin/v1/, described in OpenAPI, so you never have to write YAML. Admin API - An audit log of every write, provider keys sealed at rest, and changes live on every replica within 2 seconds. Admin API
Observability
- Prometheus metrics: requests, latency, tokens, cost, fallbacks, refusals and reloads, with labels that stay bounded. Metrics
- OTLP traces with a span per call and per provider tried, and never the prompt or the answer. Tracing
- JSON logs, a request id on every response, and
/healthzand/readyzfor probes.
Deployment
- One static binary of about 18 MB, or a distroless image. No runtime, no sidecar.
- SQLite with no setup, or Postgres for several replicas that share keys, config, usage and limits. Postgres
--config-testchecks a config without starting, and--check-updatesays what a newer release changes for your config. Updates
Providers
Provider and type |
Dialect | Default base URL | Tools | Images | Embeddings | Responses API |
|---|---|---|---|---|---|---|
OpenAI openai |
openai |
https://api.openai.com/v1 |
yes | URL, inline | yes | yes |
Anthropic anthropic |
anthropic |
https://api.anthropic.com/v1 |
yes | URL, inline | no | no |
Google Gemini API gemini |
gemini |
https://generativelanguage.googleapis.com/v1beta |
yes | inline | yes | no |
Ollama ollama |
openai |
http://localhost:11434/v1 |
yes | URL, inline | yes | yes |
vLLM vllm |
openai |
http://localhost:8000/v1 |
yes | URL, inline | yes | yes |
llama.cpp server llamacpp |
openai |
http://localhost:8080/v1 |
yes | URL, inline | yes | yes |
LM Studio lmstudio |
openai |
http://localhost:1234/v1 |
yes | URL, inline | yes | yes |
OpenRouter openrouter |
openai |
https://openrouter.ai/api/v1 |
yes | URL, inline | yes | yes |
LiteLLM Proxy litellm |
openai |
http://localhost:4000/v1 |
yes | URL, inline | yes | yes |
Cloudflare AI Gateway cloudflare |
openai |
set base_url |
yes | URL, inline | yes | yes |
Vercel AI Gateway vercel |
openai |
https://ai-gateway.vercel.sh/v1 |
yes | URL, inline | yes | yes |
xAI (Grok) xai |
openai |
https://api.x.ai/v1 |
yes | URL, inline | yes | yes |
Mistral AI mistral |
openai |
https://api.mistral.ai/v1 |
yes | URL, inline | yes | yes |
NVIDIA NIM nvidia |
openai |
https://integrate.api.nvidia.com/v1 |
yes | URL, inline | yes | yes |
Groq groq |
openai |
https://api.groq.com/openai/v1 |
yes | URL, inline | yes | yes |
Cerebras cerebras |
openai |
https://api.cerebras.ai/v1 |
yes | URL, inline | yes | yes |
SiliconFlow siliconflow |
openai |
https://api.siliconflow.com/v1 |
yes | URL, inline | yes | yes |
built-in test provider echo |
none | built in | no | ignored | yes | no |
- Every type serves chat, plain and streamed. A test builds every registered provider type and checks this table against what its adapter does, so the table cannot fall behind the code.
- Dialect is the API the provider speaks. A caller of the same dialect is passed through with only
modelchanged; any other is translated./v1/responsesgoes only toopenai-dialect targets. - Embeddings and Responses API say what transponder sends; whether a server has that endpoint is up to it. A target that answers 404, 405 or 501 to
/v1/responsesis skipped. base_urloverrides the default for any type: a self-hosted NIM is usuallyhttp://localhost:8000/v1, SiliconFlow in China ishttps://api.siliconflow.cn/v1, and Cloudflare is your gateway's compatibility endpoint,https://gateway.ai.cloudflare.com/v1/<account_id>/<gateway_id>/compat. llama.cpp's server listens on 8080 by default, as transponder does, so on one host move one of them.- Local types (
ollama,vllm,llamacpp,lmstudio,echo) count as free in usage records. Prices for the others are ininternal/pricing/prices.yaml; a model without a price is recorded as unpriced and counted intransponder_unpriced_requests_total.
Missing one? A provider that speaks the OpenAI API is a twenty-line package and one line in the registry: see Add a provider.
How it compares
LiteLLM Proxy and bifrost are good projects, and if you need dozens of providers, a web UI today, or caching, they are the better choice. transponder is for a team that wants to share one gateway: who spent what, from your own identity provider, with budgets that hold across replicas, and none of it behind a license.
| transponder | LiteLLM Proxy | bifrost | |
|---|---|---|---|
| Runs as | one Go binary, about 18 MB | a Python app with Uvicorn workers, or its Docker image | |
| Memory | 19 MiB idle, 52 MiB after the full-load runs | its production guide starts load tests at 1 vCPU and 4 GiB per worker | |
| Latency added, as each project measures it | p50 0.37 ms, p95 0.96 ms at 500 calls a second; p99 11.6 ms at 12,235 calls a second, on one desktop machine shared with the load tool | p50 2 ms, p95 8 ms, p99 13 ms at 1,170 calls a second across 4 instances of 4 vCPU | |
| Several replicas sharing budgets | Free, with Postgres | Free, with Postgres, and Redis from the second instance | Enterprise |
| Sign-in with OIDC tokens for API calls | Free | Enterprise (JWT auth) | Enterprise |
| Budget per user from their token | Free | Enterprise | No, budgets hang off virtual keys |
| Admin roles | Free | Enterprise | Enterprise |
| Audit log of admin changes | Free | Enterprise | Enterprise |
| Admin API | Free, described in OpenAPI | Free, with a web UI | |
| Circuit breaker for failing providers | Free (cooldown) | Enterprise |
The latency rows come from two different setups and methods, so they show the order of magnitude, not a winner: transponder's from docs/benchmarks.md, the time to the last byte minus a fake provider's fixed delay; LiteLLM's from its benchmarks page, the overhead it reports in a response header, against a mock endpoint. Other sources: LiteLLM's production guide, enterprise page and JWT auth docs; bifrost's enterprise overview and budget docs. Read in November 2026. Blank cells are ones we have not checked; corrections are welcome.
transponder has no paid edition and never will. SSO, roles, the audit log, replicas and the admin API are all in the Apache-2.0 build.
Use it with your tools
Anything that speaks the OpenAI or Anthropic API works with a base URL change and a transponder key.
OpenAI SDKs, with base_url="http://localhost:8080/v1" and the key as api_key.
Claude Code:
ANTHROPIC_BASE_URL=http://localhost:8080 ANTHROPIC_AUTH_TOKEN=$TRANSPONDER_KEY claude
/v1/messages sends the request to Anthropic as it came, with only the model changed, so thinking, prompt caching and beta features keep working, and usage and cost are recorded for the key. A route can also send Claude Code's requests to Gemini, OpenAI or a local model. Those are translated, tools and images included, though features only Anthropic has, such as its server tools, PDF documents and images in tool results, are refused on those routes.
Codex CLI, through the Responses API. Add a provider to ~/.codex/config.toml and export a transponder key as TRANSPONDER_KEY:
model = "gpt-5"
model_provider = "transponder"

[model_providers.transponder]
name = "transponder"
base_url = "http://localhost:8080/v1"
env_key = "TRANSPONDER_KEY"
wire_api = "responses"
Reference
Each part starts with what most people need. The details are folded away; click to open them. Every key, default and environment variable is in docs/configuration.md.
Configuration
transponder reads a YAML file (--config), then TRANSPONDER_ environment variables, which win: store.postgres is TRANSPONDER_STORE__POSTGRES. Providers, routes, budgets and profiles can also be made through the admin API instead.
transponder --config-test --config transponder.yaml
checks a file for syntax errors, missing variables and bad routes without starting the server, opening a port or creating a database file. It prints transponder: config ok and exits 0, or prints the error and exits 1.
providers:
  - name: claude
    type: anthropic       # https://api.anthropic.com/v1 unless base_url is set
    api_key: ${ANTHROPIC_API_KEY}
  - name: gemini
    type: gemini          # Gemini API with an API key
    api_key: ${GEMINI_API_KEY}
  - name: openai
    type: openai
    api_key: ${OPENAI_API_KEY}
  - name: local
    type: ollama          # http://localhost:11434/v1 unless base_url is set
  - name: proxy
    type: litellm         # http://localhost:4000/v1 unless base_url is set
  - name: siliconflow
    type: siliconflow     # China is https://api.siliconflow.cn/v1
    api_key: ${SILICONFLOW_API_KEY}
  - name: vllm
    type: vllm            # http://localhost:8000/v1 unless base_url is set
  - name: llamacpp
    type: llamacpp        # llama-server listens on :8080 by default, as transponder does
    base_url: http://localhost:8081/v1
  - name: router
    type: openrouter
    api_key: ${OPENROUTER_API_KEY}
  - name: xai
    type: xai
    api_key: ${XAI_API_KEY}
  - name: vercel
    type: vercel
    api_key: ${VERCEL_API_KEY}
  - name: mistral
    type: mistral         # embeddings, including mistral-embed, use the same base URL
    api_key: ${MISTRAL_API_KEY}
  - name: nvidia
    type: nvidia          # a self-hosted NIM is usually http://localhost:8000/v1
    api_key: ${NVIDIA_API_KEY}
  - name: groq
    type: groq
    api_key: ${GROQ_API_KEY}
  - name: cerebras
    type: cerebras
    api_key: ${CEREBRAS_API_KEY}
  - name: lmstudio
    type: lmstudio        # api_key is optional
  - name: cf
    type: cloudflare      # your AI Gateway compatibility endpoint
    base_url: https://gateway.ai.cloudflare.com/v1/<account_id>/<gateway_id>/compat
    api_key: ${CLOUDFLARE_API_TOKEN}
routes:
  - match: "claude-*"
    targets:
      - provider: claude
  - match: "gemini-*"
    targets:
      - provider: gemini
  - match: "gpt-*"
    targets:
      - provider: openai
  - match: "grok-*"
    targets:
      - provider: xai
  - match: "anthropic/claude-opus-5"
    targets:
      - provider: vercel
  - match: "mistral-*"
    targets:
      - provider: mistral
  - match: "nvidia-llama"
    targets:
      - provider: nvidia
        model: meta/llama-3.1-8b-instruct
  - match: "groq-llama"
    targets:
      - provider: groq
        model: llama-3.3-70b-versatile
  - match: "cerebras-gpt-oss"
    targets:
      - provider: cerebras
        model: gpt-oss-120b
  - match: "siliconflow-deepseek-r1"
    targets:
      - provider: siliconflow
        model: deepseek-ai/DeepSeek-R1
  - match: "lmstudio-*"
    targets:
      - provider: lmstudio
  - match: "fast"
    targets:
      - provider: openai
        model: gpt-4o-mini
  - match: "*"
    targets:
      - provider: local
Routes are tried in order and the first match wins.
Environment variables in the file${NAME} and $NAME in a value or a key are replaced from the environment. A missing variable is an error that names it. Comments are left as written, so a commented-out key does not require its variable, while a line that starts with # inside a | or > block or a quoted value is part of the value and is still replaced. The variable's value is used as it is, so a #, a quote or a newline in a password stays part of it. A variable fills in part of one value; it cannot add keys or list items. Up to v0.2.4 it could, so move any list or map kept in a variable into the file.
Fallback
A route can list several targets. They are tried in order, and the first that answers serves the call:
providers:
  - {name: claude, type: anthropic, api_key: "${ANTHROPIC_API_KEY}"}
  - {name: openai, type: openai, api_key: "${OPENAI_API_KEY}"}
  - {name: local, type: ollama}
routes:
  - match: "claude-*"
    targets:
      - provider: claude
      - provider: openai
        model: gpt-5
      - provider: local
        model: qwen3:8b
settings:
  cooldown_failures: 3   # failures in a row before a target goes last
  cooldown: 30s          # for how long
- The next target takes over when one is unreachable or times out, answers 408, 429, any 5xx or Anthropic's 529, rejects the gateway's own key (401, 403), fails a stream before its first output (events that carry none yet, such as a role chunk,
message_startor a ping, are held back until then), or cannot take the request, such as an image at a URL going to Gemini, which takes inline images only. - A request the provider rejects as wrong (any other 4xx) is not sent elsewhere. Nor is anything retried once output has reached the caller, after the caller has gone, or past
request_timeout. The same target is never tried twice in one call. - After three failures in a row a target is put last for 30 seconds, so calls stop waiting on it. It is still tried when every other target has failed. This is kept per process, by provider and upstream model, and survives config reloads.
- A call that is not streamed has no timeout of its own per target, so a target that hangs holds it until
request_timeout. Streams move on afterattempt_timeout. X-Transponder-Provider,X-Transponder-ModelandX-Transponder-Fallbackssay which target answered and how many were tried before it. The usage record has the same.- With limits on, a call reserves the price of the route's dearest target and settles at what the answering target cost.
POST /v1/messages/count_tokensgoes to the first Anthropic target of the route.
Images
Chat requests can carry images on both endpoints: image_url parts on /v1/chat/completions, as a URL or a data:image/...;base64, URL, and image blocks on /v1/messages, as a url or base64 source. Text and images reach the provider in the order they were sent.
| Target | Image at a URL | Inline image |
|---|---|---|
| OpenAI and OpenAI-compatible | yes | PNG, JPEG, WebP, GIF |
| Anthropic | yes | PNG, JPEG, WebP, GIF |
| Gemini | no | PNG, JPEG, WebP, HEIC, HEIF |
| echo | ignored | ignored; it answers with the text |
- A target that cannot take an image is skipped and the next one is tried. When none can, the caller gets a 400 that says why.
- An inline image the gateway translates may be at most 5 MiB once decoded; a larger one is a 400
image_too_large. A request that goes to a provider of its own dialect is sent on unopened, so the provider's own limit applies. - Images go only in user messages.
- For limits, each image counts as 1,000 input tokens until the provider reports the real usage. That is about what a 1024 by 1024 picture costs on OpenAI, Anthropic and Gemini.
Responses API
POST /v1/responses is the OpenAI Responses API, which the Codex CLI, newer OpenAI SDK code and VS Code's custom endpoint use instead of chat completions. It is passed through to targets that speak the OpenAI API, streamed or not, with usage, limits, access per route and fallback as for chat:
curl http://localhost:8080/v1/responses \
  -H "Authorization: Bearer $TRANSPONDER_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model": "gpt-5", "input": "Say hello."}'
Every caller of a route shares the provider account, so nothing is stored there: store is always sent as false, and previous_response_id, conversation and stored items are refused. Send the whole conversation in input, as the Codex CLI does.
- The request goes to a target that speaks the OpenAI API (
openaiand the OpenAI-compatible provider types) as it came, withmodelchanged to the target's model andstoreset tofalse, and the answer comes back as the provider sent it, streamed or not. Tools, reasoning, structured output and whatever else the provider supports work without transponder knowing about them. - Anthropic, Gemini and
echotargets are skipped, since this API is not translated yet. So is a server that has no/responsesendpoint and answers 404, 405 or 501. When no target of the route can serve the call, the caller gets a 400unsupportedthat says why. - Usage is read from the final body, or from the
response.completed,response.incompleteorresponse.failedevent of a stream, with cached input and reasoning tokens counted apart. TheX-Usage-*headers (trailers on a stream), usage records, budgets, limits,allowon routes and fallback work as they do for chat.llm.max_output_tokensin a profile lowersmax_output_tokens, the one field besidesmodelandstorethat transponder may change. background: trueis refused with a 400, andGET,DELETEandcancelon/v1/responses/{id}are not served. The result of a background response, and its usage, would have to be fetched later, which the gateway cannot do.
transponder calls the provider with its own key, so every caller of a route shares one provider account. A response stored there could be continued, and read back, by any caller who learned its id. So transponder stores nothing and lets no call continue stored state:
storeis always sent asfalse, whatever the caller asked for. OpenAI treats a missingstoreastrue, so it is added when the caller leaves it out.- A call that sets
previous_response_idorconversation, or names a stored item ininput, gets a 400unsupportednaming the field, from any caller, before anything is sent. Anullvalue is fine. A stored item is anitem_reference, or an item with anidthat does not carry its own content: amessageneedsroleandcontent, areasoningitemencrypted_content, afunction_callcall_id,nameandarguments, a tool outputcall_idandoutput, and any other item something besides itsidandtype. An item without atypeis checked as a message. Null and empty values count as missing, and a key given twice in different cases makes the item count as stored. - Send the whole conversation in
inputon every call instead, the way stateless clients such as the Codex CLI already do. For reasoning models, ask forinclude: ["reasoning.encrypted_content"]and send the reasoning items back ininput. Each call then stands on its own and falls back to another target like chat does. Encrypted reasoning items can only be read by the provider that made them, and another provider's 400 for them is passed on. - Keeping stored responses, with each one tied to the caller and the target that made it, is planned; it needs a record of every response id in the store.
Input limits: llm.max_input_tokens is checked against an estimate of the request before it is sent. Content the gateway cannot measure before the call would get past it, so a caller whose profile sets llm.max_input_tokens gets a 400 input_not_countable for a stored prompt and for any input_file part, whether by file_id, by file_url or inline. Callers without that limit can send both; for the reservation against budgets and token allowances, each file counts as 1,000 tokens like an image, and the call settles at the usage the provider reports.
What a passthrough still cannot check:
- Prompts, files, vector stores and containers named by id live in the provider account every caller of the route shares. transponder serves no endpoint that creates them, so they are the operator's. Give each group its own provider key or project behind its own route with
allowif they must not share them. - Hosted tools add input during the call: web search results, file search results and code interpreter output count toward the usage the provider reports, not toward the estimate
llm.max_input_tokensis checked against. - Only tokens are priced. Hosted tools the provider bills per call, such as web search, code interpreter, file search and image generation, cost more at the provider than the usage record shows.
Sign-in and roles
API keys always work. To also let people call transponder with a token from your OpenID Connect provider (Okta, Entra ID, Keycloak, Zitadel, Google, Auth0 and others), name the issuer and the audience:
auth:
  oidc:
    issuer: "https://idp.example.com/realms/acme"   # the iss claim; keys are found through its discovery document
    audience: "transponder"                         # tokens issued for another service are refused
    # jwks_url: "https://idp.example.com/keys"      # only for an issuer without a discovery document
    user_claim: sub                                 # default sub; email or preferred_username also work
    teams_claim: groups                             # default groups
    roles_claim: realm_access.roles                 # a dotted name reads a nested claim
    role_mapping:                                   # claim value -> admin, viewer or member
      platform-admins: admin
      auditors: viewer
    clock_skew: 1m                                  # allowance on exp and nbf, default 1m
curl localhost:8080/v1/chat/completions -H "Authorization: Bearer $ID_TOKEN" \
  -d '{"model": "fast", "messages": [{"role": "user", "content": "hi"}]}'
- A bearer token or
x-api-keyvalue that is a JWT is checked against the issuer: signature,iss,aud,expandnbf. Anything else is looked up as an API key. Only asymmetric signatures (RS, PS, ES and EdDSA) are accepted. - The caller's user id comes from
user_claimand their teams fromteams_claim, so budgets and profiles foruser:andteam:subjects apply to people who sign in. A caller with a token has nokey:subject. - Every caller has a role. A token gets the highest role its
roles_claimvalues map to, andmemberwhen none does. An API key carries the role it was created with.viewermay read the admin API and/metrics,adminmay also write, and every role may call the gateway. - The signing keys are fetched when the first token arrives and kept for an hour. A token naming a key transponder has not seen makes it read the keys again, at most once every 10 seconds, so made-up key ids cannot flood the identity provider. When the provider cannot be reached, keys already fetched keep working; with none yet, calls with a token get 503
auth_unavailablewhile API keys keep working, and/readyzreportsoidc. - When
role_mappinggives someoneadmin, the first start does not print an admin key, since that person can sign in instead. - Each key can be set from the environment too, such as
TRANSPONDER_AUTH__OIDC__ISSUER.role_mappingis a map, so it is set in the file.
Access per route
A route can say who may call it. Leave allow out and every caller with a valid key or token may:
providers:
  - {name: claude, type: anthropic, api_key: "${ANTHROPIC_API_KEY}"}
  - {name: local, type: ollama}
routes:
  - match: "claude-*"
    allow: ["team:platform", "user:[email protected]", "key:ci", "role:admin"]
    targets:
      - provider: claude
  - match: "*"
    targets:
      - provider: local
user:<id>matches the user id from a token, and also an API key of that name, since a key counts asuser:<key name>. Usekey:<name>to let in only the key.team:<name>matches any of the caller's teams: the teams of a key, or theteams_claimof a token.role:<role>lets in that role and the ones above it, sorole:vieweralso lets in admins.- Any one matching entry is enough. A caller outside the list gets 403
route_forbidden, and the message names the route. Nothing is recorded or charged. Anthropic-dialect callers getpermission_errorwith the same code. GET /v1/modelslists only the routes the caller may use.--config-testchecks every entry.
Admin API
Everything a console needs is a JSON API under /admin/v1/, described in api/openapi.yaml and served at /admin/v1/openapi.yaml. It takes the same API keys and tokens as the gateway: viewer may call every GET, and every other method needs admin.
# make a key for a service; the secret is in the answer and is shown only this once
curl localhost:8080/admin/v1/keys -H "Authorization: Bearer $ADMIN_KEY" \
  -d '{"name": "logbook", "role": "member", "teams": ["platform"]}'

# add a provider and send gpt-* models to it, with no YAML and no restart
curl localhost:8080/admin/v1/providers -H "Authorization: Bearer $ADMIN_KEY" \
  -d '{"name": "openai", "type": "openai", "api_key": "sk-..."}'
curl localhost:8080/admin/v1/routes -H "Authorization: Bearer $ADMIN_KEY" \
  -d '{"match": "gpt-*", "targets": [{"provider": "openai"}]}'

# a monthly budget for every user
curl localhost:8080/admin/v1/budgets -H "Authorization: Bearer $ADMIN_KEY" \
  -d '{"subject": "user:*", "period": "monthly", "limit_usd": 20}'

# spend per user this month, and the last changes made through the API
curl "localhost:8080/admin/v1/usage?group_by=user" -H "Authorization: Bearer $ADMIN_KEY"
curl localhost:8080/admin/v1/audit -H "Authorization: Bearer $ADMIN_KEY"
| Endpoint | What it does |
|---|---|
GET /status |
Version, uptime, store health, the config version served and whether the last reload failed |
GET /keys, POST /keys, GET/PATCH/DELETE /keys/{name}, POST /keys/{name}/rotate |
API keys. A secret is returned once, when the key is made or rotated; the store keeps only its hash |
GET/POST /providers, GET/PATCH/DELETE /providers/{name} |
Providers. The API key is write-only: reads show "api_key": {"set": true, "last4": "..."}. Deleting one a route still uses is 409 in_use with the route ids |
GET/POST /routes, GET/PATCH/DELETE /routes/{id} |
Routes, tried by position, lowest first. A new route without one goes last |
GET/POST /budgets, GET/PATCH/DELETE /budgets/{id} |
Budgets: subject, period (daily or monthly) and limit_usd |
GET/POST /profiles, GET/PATCH/DELETE /profiles/{name} |
Limit profiles: limits in the shared profile format, the subjects bound to it, and whether it is the default |
GET /usage?group_by=user|team|key|project|model|provider|route|day&from=&to= |
Calls, tokens and cost per group, this month by default |
GET /requests |
Single usage records, newest first |
GET /audit?actor=&resource=&from=&to= |
Every write through the API: who, what, when, the request id, and the item before and after |
- Lists take
cursorandlimit(default 50, at most 500) and return{"items": [...], "next_cursor": "..."}, with nonext_cursoron the last page. - Errors are
{"error": {"code": "...", "message": "...", "field": "..."}}. A refused field is named infield. - Every item has a
version, also sent as theETag. Send it back inIf-MatchonPATCH,DELETEandrotate, and a write over someone else's change is refused with 409version_conflict. WithoutIf-Matchthe write applies to whatever is stored. - Items declared in the YAML file show
"managed_by_file": trueand cannot be changed through the API (409managed_by_file). - Every write and its audit record commit in one transaction that also raises the config version, so every replica picks the change up within 2 seconds, and the replica that took it before it answers.
- Before a write commits, the whole config is loaded as it would be after it. A change that would leave a config that does not load, such as a second default profile or a subject bound to two profiles, is refused with 400
invalid_configand nothing is written. - The providers, routes, budgets and profiles of the YAML file are stored at start with
"source": "file". Change them in the file and restart; one removed from the file is removed from the store. A file item with the name of one made through the API replaces it, and the log says so. File routes come first, at positions 1000, 2000 and so on, so a route made through the API can be put between or before them.
Provider keys at rest
A provider key sent to the admin API is sealed with AES-256-GCM before it is stored, and never returned. The 32-byte key for that is secrets_key (or TRANSPONDER_SECRETS_KEY), written as base64 or 64 hex digits:
openssl rand -base64 32
- With SQLite and no
secrets_key, transponder makes one at first start intransponder.keynext to the database, readable by its owner only. Back it up with the database: without it the stored provider keys cannot be read. - With Postgres, set the same
secrets_keyon every replica. Without one, a provider can be added without a key, and one with a key is refused with 400secrets_key_missing. - Changing a provider's
typeorbase_urlneeds itsapi_keysent again (ornullto drop it), so a stored key is never sent to a new host by someone who has not seen it. - Keys of providers declared in the YAML file stay in the file and are not stored.
To change secrets_key, keep the old one readable while the stored keys are sealed again:
- Set
secrets_keyto the new key andprevious_secrets_key(TRANSPONDER_PREVIOUS_SECRETS_KEY) to the old one on every replica, and restart them. They read keys sealed under either and seal new ones under the new key. With SQLite and a generated key, the old key is the content oftransponder.key. - Run
transponder secrets rotate --config transponder.yamlonce, with the same settings. It seals every stored provider key again under the new key in one write, with arotaterecord in the audit log per provider, and every replica reloads. - Remove
previous_secrets_key.
A replica whose key opens none of the stored provider keys keeps serving the config it has and reports the failed reload in /admin/v1/status; at start it exits with an error that names the provider.
Limits
Budgets cap what a user, a team or a key spends in USD, per UTC day or month. Profiles, in the same format as the other mothership projects, cap tokens and requests. A caller with an API key counts as user:<key name> as well as key:<key name>, so name keys after the people or services that hold them. A caller who signs in with a token counts as user: and team: from its claims.
budgets:
  - {subject: "user:*", period: monthly, limit_usd: 20}       # every user without a rule of their own
  - {subject: "user:[email protected]", period: monthly, limit_usd: 100}
  - {subject: "team:platform", period: daily, limit_usd: 50}
  - {subject: "key:ci", period: monthly, limit_usd: 10}

default_profile: free
profiles:
  - name: free
    limits:
      requests:   {rate: 60/m, concurrency: 4}
      llm.tokens: {rate: 20000/m, per_day: 100000, per_month: 2000000}
      llm.cost_usd: {per_month: 5}
      llm.max_input_tokens: 8192
      llm.max_output_tokens: 2048
      llm.max_reasoning_tokens: 4096
  - name: pro
    limits:
      llm.tokens: {per_day: 2000000}
profile_bindings:
  - {subject: "user:[email protected]", profile: pro}   # key:, user: or team:, in that order
# profiles_file: /etc/mothership/profiles.yaml          # or share one file with the other projects
A spent budget is 402 budget_exceeded, a spent token allowance 402 quota_exceeded, a rate 429 rate_limited with Retry-After, too many calls at once 429 concurrency_limited. GET /v1/usage shows a caller every budget and allowance that applies to them and what is left.
llm.tokenscounts input, output and reasoning tokens together. Reasoning tokens are counted apart where the provider reports them (OpenAI, Gemini) and come back inX-Usage-Reasoning-Tokens. Where a provider reports no usage, tokens are estimated on the high side: four characters a token for ASCII, one and a half tokens for every other character.- A call reserves its estimated input, its output limit (4096 tokens when it sets none and no profile cap applies) and their cost before it runs, and settles to the real usage after. A failed call gives the reservation back. A plain call the client abandons keeps its reservation, since the provider may still bill the work; an abandoned stream settles to what it streamed. A kept reservation lives in memory only and is not rebuilt after a restart.
- An exact
user:<id>budget replacesuser:*for its own period only, so a larger monthly budget for one user keeps the dailyuser:*cap. A budget of0refuses every paid call. llm.max_output_tokenslowersmax_tokensormax_completion_tokens, never raises them.llm.max_reasoning_tokenslowers Anthropic's thinking budget, which is also kept undermax_tokensand dropped when that leaves less than Anthropic's minimum of 1024. OpenAI and Gemini chat requests get no separate reasoning cap; for OpenAI,max_completion_tokensbounds reasoning and output together. A prompt overllm.max_input_tokensgets 400input_too_large.- OpenAI-dialect callers get refusals as
error.code; Anthropic-dialect callers get Anthropic'serror.type(billing_error,rate_limit_error,invalid_request_error) with the same code inerror.code. Responses carryRateLimit-PolicyandRateLimitheaders for the rates that apply. GET /v1/usageshows the limit, what is used (calls in flight count at what they reserved), what is left and when it resets.- With SQLite, counters live in memory and are rebuilt from the usage table at start, so a restart keeps this month's recorded spend. A limit can be passed only by calls already in flight whose real usage turns out larger than their reservation, and by kept reservations lost in a restart.
- With Postgres, counters live in the database and every replica shares them, so a budget, an allowance, a rate or a concurrency cap holds across all of them. See below.
Postgres and several replicas
SQLite serves one replica. To run more, point every replica at one Postgres database:
store:
  postgres: postgres://transponder:${PGPASSWORD}@db.internal:5432/transponder?sslmode=require
limits:
  store: sql             # the default with store.postgres; memory keeps counters in each process
  on_store_error: local  # or deny
TRANSPONDER_STORE__POSTGRES sets the same key. The value is a postgres:// URL or a key=value connection string, and takes pool settings such as pool_max_conns=20. Set only one of store.sqlite and store.postgres.
- The schema is created and migrated at start. Replicas that start together take a lock, so each migration runs once.
- API keys and usage records are shared: a key made on one replica works on all of them, and the first replica to start prints the one-time admin key.
- Migrations only add tables and columns, and removals come in a later release, so replicas on the old and the new version can run side by side during a rolling update.
- Budgets, token allowances, rates and concurrency caps are counted in Postgres, shared by every replica. Each reservation is one atomic statement, so two replicas cannot both take the last of a budget. The first replica to start fills the counters from this month's usage once. This adds a few short queries to each limited call;
limits.store: memorykeeps the counters in each process instead, for a single replica. - A change to the runtime config reaches every replica within 2 seconds, without a restart: each replica checks a version number in the database every 2 seconds and, when it moved, loads the whole config again and swaps it in. If the new config does not load, the old one keeps serving and the error is logged. Calls already running finish on the config they started with.
- A concurrency slot belongs to the replica that took it. If that replica dies, its slots free themselves within 30 seconds.
- If Postgres cannot be reached,
limits.on_store_error: local(the default) counts in each replica with its share of every limit, the limit divided by the number of replicas seen in the last 30 seconds.denyanswers 503overloadedwithRetry-After: 1instead.
Metrics
GET /metrics serves Prometheus metrics. On the gateway's port it needs a key or token with the viewer or admin role, because that port is the one callers reach, and the metrics name your providers, models and routes and total the spend. Prometheus sends the key as a bearer token:
# prometheus.yml
scrape_configs:
  - job_name: transponder
    authorization:
      credentials_file: /etc/prometheus/transponder.key
    static_configs:
      - targets: ["transponder:8080"]
To scrape without a key, set ops_listen_addr (or TRANSPONDER_OPS_LISTEN_ADDR). /healthz, /readyz and /metrics are then also served on that second port, where /metrics is open, so keep the port inside your network:
listen_addr: ":8080"
ops_listen_addr: ":9464"
| Metric | Labels | What it counts |
|---|---|---|
transponder_requests_total |
endpoint, route, provider, model, code |
Requests answered. endpoint is chat.completions, messages, messages.count_tokens, responses, embeddings, models, usage, or other for a path the gateway does not serve. provider and model are the target that answered, and are empty when the request ended before a provider was asked (a 401, a 404, a limit). |
transponder_request_duration_seconds |
endpoint, route |
Histogram of the time from the request arriving to the last byte of the answer, streams included. |
transponder_inflight_requests |
Requests being served now. | |
transponder_limited_total |
reason |
Requests refused by a limit or a budget: rate_limited, concurrency_limited, quota_exceeded, budget_exceeded, input_too_large. |
transponder_events_dropped_total |
sink |
Usage records that could not be written (sql) and spans that could not be exported (otlp). |
transponder_tokens_total |
direction, provider, model |
Tokens used. direction is input, output, cache_read, cache_write or reasoning. |
transponder_cost_usd_total |
provider, model |
Cost in US dollars. |
transponder_upstream_duration_seconds |
provider, model |
Histogram of the time one attempt on a provider took. |
transponder_fallbacks_total |
route, from, to, reason |
Moves to the next target of a route. reason is server_error, rate_limited, timeout, unreachable, auth, unsupported or error. |
transponder_unpriced_requests_total |
Calls on a model that has no price. | |
transponder_config_reloads_total |
result |
Reloads of the runtime config: ok for a new version swapped in, failed for one that could not be read or loaded, counted on every check while it stays that way. |
transponder_build_info |
version |
Always 1. |
No label carries a user, a team, a key or a request id, so the number of series follows your config and not your traffic. Spend per user is in the usage records and GET /v1/usage. A model name is a label when the config sets it. Behind a wildcard route whose target sets no model, the caller picks the name, so it becomes a label only once a provider has answered for it, for at most 200 names, and is counted as other otherwise. /healthz, /readyz and /metrics are not counted as requests.
Tracing
Set otel.endpoint to the base URL of an OTLP/HTTP collector and transponder exports a trace for every call, with a span for each provider it tried. It is off by default.
otel:
  endpoint: http://collector:4318   # spans are posted to /v1/traces
  headers:                          # optional, for a collector that needs a key
    Authorization: Bearer ${OTEL_KEY}
  sample_ratio: 0.1                 # optional, the share of traces that start here; default all
- Each call is one span, named after the endpoint, such as
POST /v1/chat/completions, with the status code, route, provider, model, tokens, cost and number of fallbacks. - Each attempt on a provider is a child span, such as
chat gpt-4o-mini(for chat,/v1/messagesand/v1/responses) orembeddings text-embedding-3-small, with the provider, the model, its tokens, and for a failed attempt the reason (server_error,rate_limited,timeoutand the others listed undertransponder_fallbacks_total) and the provider's status code. A route that fell back shows every target it tried, in order. - Spans never hold prompt or completion text, and never a provider's error message, since those can quote the prompt.
- Only calls from a caller with a valid key or token are traced. A request that fails to sign in, a probe and a scrape leave no span, so someone without a key cannot fill your collector.
traceparentandtracestatefrom the caller are kept. A call that arrives with atraceparentjoins that trace and follows its sampled flag, andsample_ratioonly decides for traces that start at the gateway. The provider is sent atraceparentthat names the attempt's span, andtracestateas it came. Atracestateover the 512 characters the standard asks for is still passed on but left off the exported spans. With tracing off both headers are passed on unchanged.- Spans are sent in batches every 5 seconds, over OTLP/HTTP with JSON bodies, which the OpenTelemetry Collector, Jaeger, Tempo and Grafana Alloy all accept on port 4318. OTLP over gRPC (port 4317) is not supported. A collector that is down or slow never holds up a call: spans that cannot be sent are dropped and counted in
transponder_events_dropped_total{sink="otlp"}. - The endpoint and the ratio can also come from the environment, as
TRANSPONDER_OTEL__ENDPOINTandTRANSPONDER_OTEL__SAMPLE_RATIO. Headers are set in the file, where${VAR}keeps a key out of it.
Updates
transponder never updates itself. To see what a newer release changes before you install it:
transponder --check-update --config transponder.yaml
It lists every release newer than the one running, says how urgent the update is (security fixes, breaking changes, bug fixes or new features) and puts first the changes that touch your config, such as a fix to a provider type you use. It only reads the public release list on GitHub.
Update news in the logsSet update_check: true (or TRANSPONDER_UPDATE_CHECK=true) and transponder checks at start and once a day, and logs one update available line with its urgency, how many releases behind it is and how many changes touch your config. It is off by default, and a failed check is only logged at debug level. You can also watch the repository for releases on GitHub, or let Dependabot or Renovate bump the image tag.
Documentation
| Page | What is in it |
|---|---|
| docs/configuration.md | Every config key with its default and environment variable, checked against the code by a test |
| docs/architecture.md | How the code is built and why, and how to add a provider or a dialect |
| docs/benchmarks.md | How fast it is, against v0.2.4, and how to measure it yourself |
| docs/failure-modes.md | What happens when a provider, the store, the caller or the config goes wrong, each with its test |
| docs/design.md | The design the project was built from |
| api/openapi.yaml | The admin API |
| demo/README.md | The demo, its services and its dashboard |
| CHANGELOG.md | Every change, by release |
Part of mothership
transponder works on its own. It is also one of four projects that fit together:
- airlock: an MCP gateway
- rosetta: serve one agent over MCP, A2A, ACP and AG-UI
- logbook: shared agent memory as an MCP server
- transponder: the model gateway they call
The same user token flows through all four, so an agent's tool calls, memories and model spend line up under one person. The shared rules are in the mothership contract.
Roadmap
Released:
- v0.1.0 config, SQLite, API keys, OpenAI and Ollama, streaming, embeddings
- v0.2.0 provider registry, split timeouts,
GET /v1/models - v0.2.2 the Anthropic API in and out, Gemini, translation between dialects, Claude Code
- v0.2.3 budgets, token limits and request limits
- v0.2.4 fallback with a cooldown,
GET /v1/usage - v0.3.0 OIDC and roles, access per route, the admin API with an audit log, Postgres and several replicas, metrics, tracing, the demo, images, the Responses API, and the speed work above
Next: translating the Responses API for Anthropic and Gemini targets, stored responses tied to their caller, organisations, Bedrock and Vertex, caching, and the mothership web console. The work is tracked in issues.
How to help
- No issue needed. Bug fixes, docs, tests and new providers can go straight to a pull request. For a bigger change, open a draft pull request or an issue with a few lines on the design first. CONTRIBUTING.md has the details.
- Add a provider. It is the easiest way to add something big: a package, one line in the registry and a row in the table above. The walkthrough shows each step, and the
adapterlabel lists the ones people asked for. - Pick an issue labeled
good first issue. Each one says which files to change and which tests to add. - Report a bug or ask for something with one of the issue forms. Questions and ideas are welcome too.
Star or watch the repository to follow along.
License
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi