Membrick
Health Gecti
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 11 GitHub stars
Code Uyari
- process.env — Environment variable access in .github/workflows/node-publish.yml
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Persistent memory layer for AI coding agents — current-state retrieval that knows what is still true. Claude Code, Codex, Gemini CLI.
Membrick
Open-source agent memory for coding agents.
AI memory that knows what is still true. Your agent doesn't just forget; it can confidently remember outdated decisions.
Membrick is an open-source persistent agent memory layer for Claude Code, Codex, Gemini CLI, Antigravity CLI (AGY), and Muse Code. It turns project history — sessions, documents, decisions, traces, notes, and code — into current, evidence-backed context when an agent needs it.
Search can find the right topic. Membrick helps an agent answer the harder question: is this information still true? It uses relevance, time, and semantic relationships to distinguish the latest truth from old-but-still-relevant history.
Agent memory guide · Quickstart · Reproducible demo · Agent integrations · Benchmarks · Documentation
Current benchmark: 500 questions · 86.37% fractional Recall@5 ·
96.8% any-hit Recall@10 · 2.58 ms mean search time · single CPU · no GPU
The stale-memory problem
Your project says one thing on Monday and something different on Friday. Both versions remain relevant to the same question.
Older — decision-a.md
# Gateway Retry Policy

Gateway timeout retry attempts: 5.
Newer — decision-b.md
# Gateway Retry Policy

Gateway timeout retry attempts: 2.
Now ask:
How many retry attempts should we use for gateway timeouts?
A normal retriever can return either document — or both — and leave the model to guess which value is current.
Membrick keeps 2 as the current answer and preserves 5 as superseded history.
That difference matters anywhere project truth changes over time: architecture decisions, API contracts, configuration values, runbooks, ownership, terminology, and implementation plans.
There is no required supersedes: frontmatter in this example. For simple configuration/value claims, Membrick can infer chronological replacement when the documents establish the same semantic domain. Inferred supersession is domain-scoped so unrelated settings such as two different services' timeout values do not suppress one another. Explicit supersession metadata remains authoritative when you provide it.
membrick --query \
  "How many retry attempts should we use for gateway timeouts?" \
  examples/demo-real-terminal
Current-state retrieval returns the newer decision with semantic_status: current, and --llm-context excludes the stale value.
Reproducible terminal demo
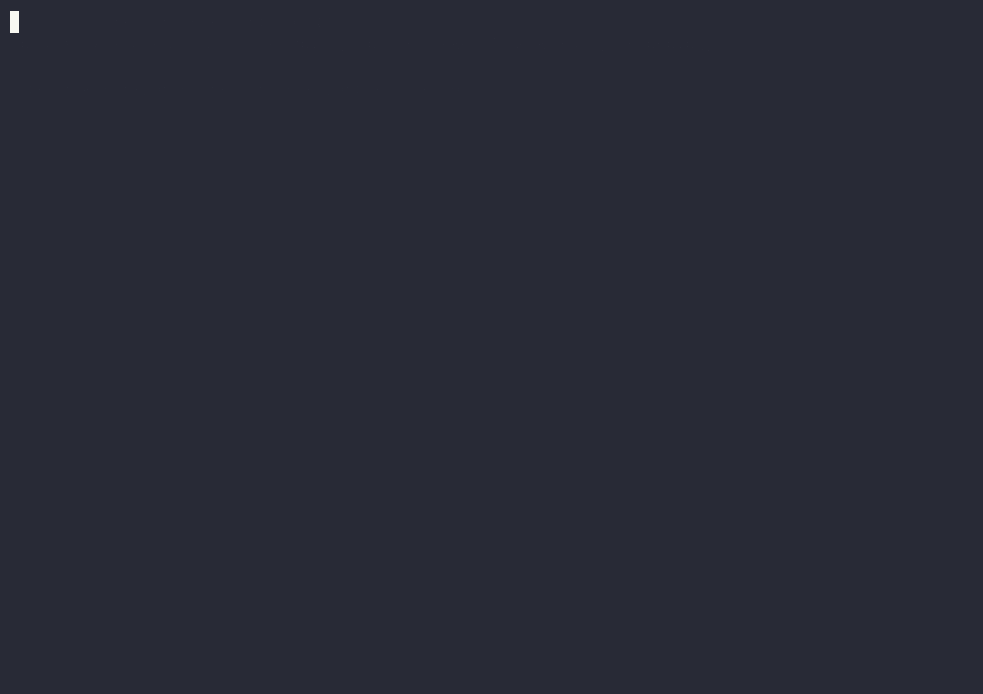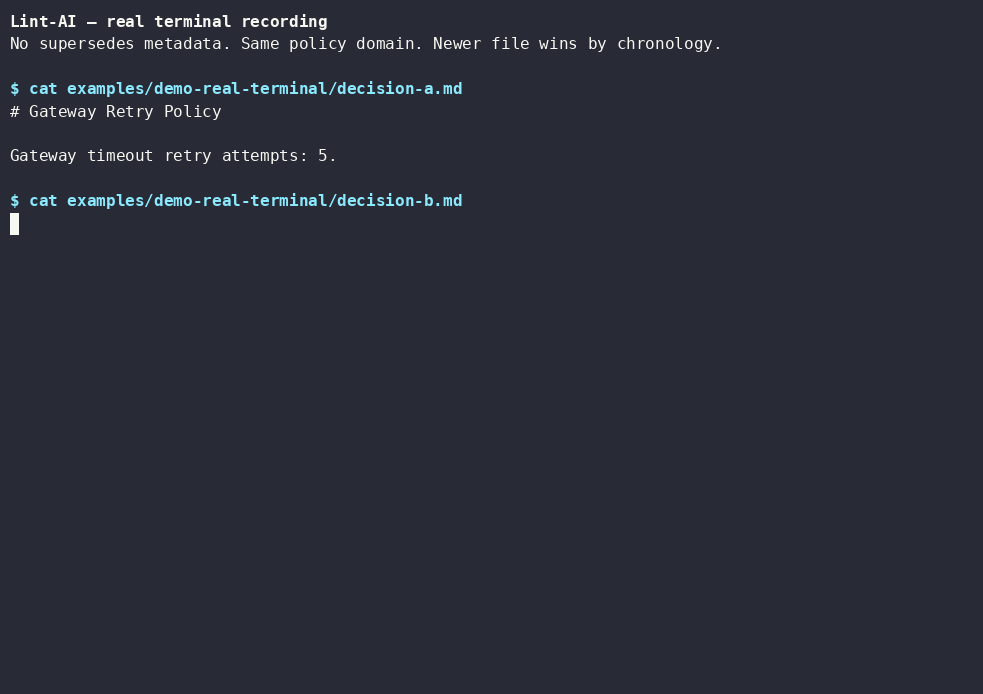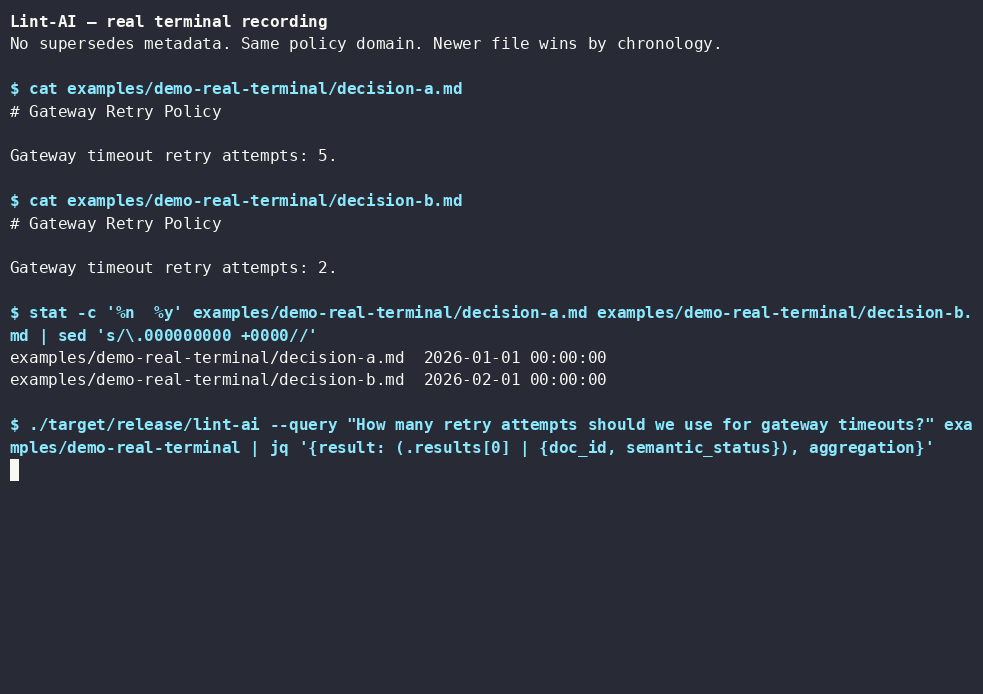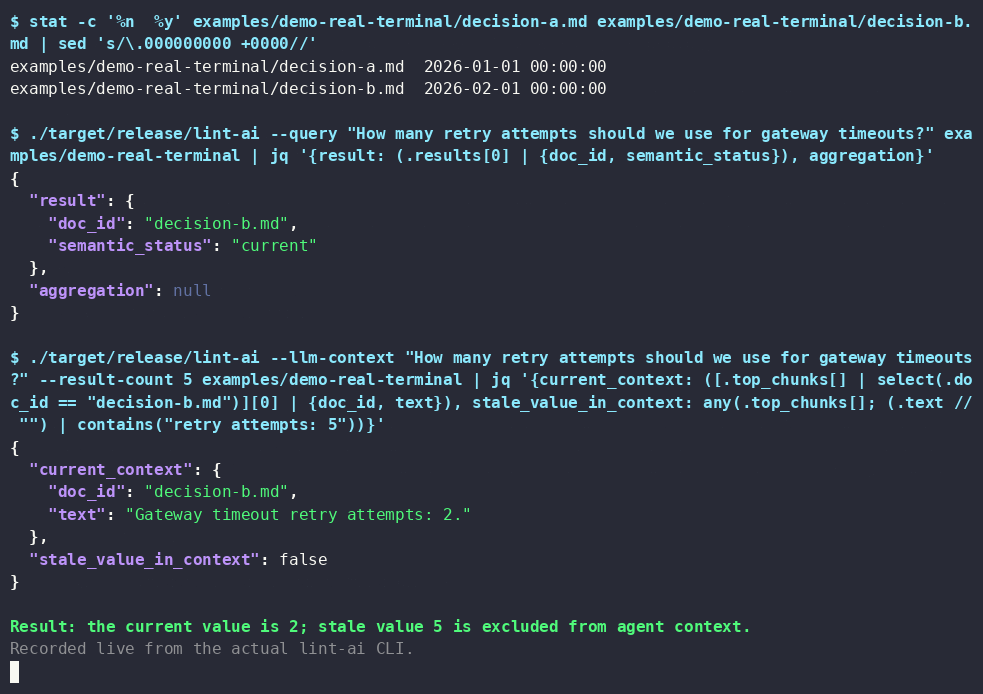
The repository includes a reproducible asciinema PTY recording that builds the actual membrick binary, sets deterministic file mtimes for a controlled stale-memory scenario, runs the neutral query above, verifies the result, and renders the captured terminal session.
bash scripts/run_real_terminal_demo.sh
See examples/demo-real-terminal/ and .github/workflows/demo-real-terminal.yml.
Why Membrick?
Agent memory is not only a retrieval problem. It is a state problem.
A useful memory layer has to answer:
- Relevance — is this about the question?
- Recency — when was this evidence true?
- Supersession — did something newer replace it?
- Temporal intent — is the user asking about now, last Tuesday, or a historical state?
- Evidence — where did the answer come from?
| Ordinary retrieval | Membrick |
|---|---|
| Finds topically similar text | Ranks relevant and current evidence |
| Can surface stale decisions as if they are current | Tracks time and supersession |
| Treats relative time as mostly query text | Resolves temporal intent against a reference clock |
| Returns passages | Returns context with source and relationship evidence |
| Treats documents mostly in isolation | Connects facts, entities, links, symbols, ownership, and time |
| Leaves corpus drift hidden | Surfaces contradictions, stale claims, terminology drift, orphan pages, and missing links |
Historical evidence is not deleted. A historical query can still retrieve superseded material as history rather than presenting it as current state.
Quickstart
Install directly from GitHub:
cargo install --git https://github.com/RooAGI/Membrick
Lint or index a local corpus:
membrick /path/to/repo
Query it:
membrick --query "what is the current retry policy?" /path/to/repo/docs
Get LLM-ready context:
membrick --llm-context "what is the current retry policy?" /path/to/repo/docs
For Docker, HTTP, Python, Rust, and MCP setup, see the full quickstart.
Agent integrations
Membrick provides opt-in integrations for major coding-agent clients.
| Integration | Project memory | Lifecycle capture | MCP tools | Replay / comparison |
|---|---|---|---|---|
| Claude Code | Yes | Yes | Yes | Yes |
| Codex | Yes | Yes | Yes | Yes |
| Gemini CLI | Yes | Yes | Yes | — |
| Antigravity CLI / AGY | Yes | Yes | Yes | — |
| Muse Code | Yes | Yes | Yes | — |
Build the Claude Code and Codex integrations:
cargo build --release --features claude-code,codex
./target/release/membrick --claude-code-install /path/to/project
./target/release/membrick --codex-install /path/to/project
All agents share one project-scoped memory store:
/path/to/project/.membrick/memory/
Upgrading from an older version? Legacy per-provider stores
(.membrick/claude-memory/, .membrick/codex-memory/,.membrick/gemini-cli-memory/, .membrick/agy-memory/,.membrick/muse-memory/) are migrated into .membrick/memory/ on first run
and removed once their migration succeeds.
The shared MCP controls include session recording, memory listing, and runtime enable/disable controls:
mcp__membrick__record_session       {"action":"start|stop|status"}
mcp__membrick__list_memories        {"limit":20}
mcp__membrick__enable_membrick       {}
mcp__membrick__disable_membrick      {}
mcp__membrick__membrick_status        {}
See agent integrations and the MCP guide for the complete setup.
Benchmark highlights
Membrick is evaluated on LongMemEval-S, a public benchmark for long-context agent-memory retrieval over multi-session conversations.
How to read the benchmark numbers
Every result has three independent labels:
- Scope: the 500-question aggregate evaluates the full scoped dataset;
the 133-question segmented comparison evaluates only the multi-session
slice. - Metric: fractional (regular) recall measures the fraction of all gold
sessions recovered; any-hit recall counts a question as successful when at
least one gold session is recovered. - Cutoff:
@5,@10, and@20mean the top 5, 10, or 20 returned
results. A Recall@5 value must not be compared with Recall@10 without
checking both the metric type and benchmark scope.
| Benchmark | Scope | Metric | Cutoffs |
|---|---|---|---|
| Aggregate headline | 500 questions | Fractional and any-hit recall | @5, @10, @20 |
| Segmented comparison | 133 multi-session questions | Any-hit recall (fractional also in raw report) | @5, @10 |
Why two benchmark tables?
The 500-question aggregate is the public overall headline. It runs the
heuristic global path across every LongMemEval-S question category. The
133-question segmented comparison isolates the multi-session category and
uses the same question subset for fixed segmented, adaptive segmented, and
single-index baselines. The single-index row is therefore the fair control for
segmented routing—not a second overall headline.
Because the scopes and query mix differ, their recall and latency values must
not be compared as a time series or combined into one score.
The current benchmark uses the repository's raw LongMemEval-S dataset, runs 500 question-scoped queries through the heuristic backend, and uses no embedding vectors. This latest result is a working-tree run with Tantivy 0.25.0, not a tagged-release measurement.
500 questions · heuristic backend · single CPU · no GPU
| Metric | Result |
|---|---|
| Fractional Recall@5 | 86.37% |
| Fractional Recall@10 | 91.89% |
| Fractional Recall@20 | 92.93% |
| Any-hit Recall@5 | 94.2% |
| Any-hit Recall@10 | 96.8% |
| Any-hit Recall@20 | 97.6% |
| MRR | 86.97% |
| NDCG@10 | 85.11% |
| Mean search latency | 2.58 ms |
Fractional Recall@k is the average fraction of all correct answer sessions recovered in the top k. Any-hit Recall@k counts a query as successful when any correct answer session appears in the top k.
Search latency measures the MemoryService::search call and excludes indexing
the question's haystack. The older published 13.0 ms figure used a different
timing scope and is not directly comparable. See the
latest 500-question report
and benchmark results for details.
The repository keeps the dataset downloader, production-style benchmark binary, shared AgentMemory scorer, comparison workflow, and temporal-reasoning experiment harnesses so results can be reproduced and changes can be evaluated without silently changing the query path.
See benchmark methodology, benchmark results, and comparison methodology.
Latest segmented-index comparison
The latest segmented comparison uses all 500 eligible LongMemEval-S questions
with Tantivy 0.25.0. It is an experimental working-tree result. Fixed routing
uses five segments; adaptive routing may expand the candidate set to 12. The
server and benchmark CLI default to fixed top-3.
| Mode | Any-hit Recall@5 | Any-hit Recall@10 | Fractional Recall@5 | MRR | Avg. query latency |
|---|---|---|---|---|---|
| Segmented (fixed top-5) | 94.20% | 94.20% | 86.77% | 0.880 | 2.49 ms |
| Segmented (enriched + reranked) | 94.20% | 94.20% | 86.77% | 0.881 | 3.85 ms |
| Adaptive (enriched + reranked) | 94.00% | 96.00% | 86.30% | 0.884 | 7.26 ms |
| Intent baseline | 94.20% | 96.20% | 85.54% | 0.863 | 0.71 ms |
| Fused adaptive + global | 95.40% | 97.20% | 87.11% | 0.880 | 61.84 ms |
| Fused temporal + global | 96.00% | 97.80% | 88.51% | 0.885 | 28.05 ms |
| Single-index control | 94.40% | 96.60% | 86.41% | 0.872 | 13.45 ms |
Fused temporal + global has the highest recall and MRR in this comparison, with
higher latency. These segmented timing numbers exclude question-haystack
indexing and are not comparable to the standalone MemoryService latency above.
See benchmark results and the
segmented-index design for conditions and
the full report:segment-longmemeval-500-2026-10-05-tantivy-0.25.0-control.json.gz.
An experimental model-backed POS/NER branch has also reached higher retrieval metrics, but it is intentionally kept separate from the audited heuristic release dependency graph. See the benchmark documentation for its results and conditions.
Integration smoke measurements
The repository also includes reproducible Claude Code and Codex replay/performance tests. These are diagnostic one-run measurements, not universal performance guarantees.
| Provider / arm | Continuation | Input tokens | Tool calls | Scenario recall | Hook time |
|---|---|---|---|---|---|
| Claude native memory | 22.47 s | 123,536 | 4 | 2/3 | 0 ms |
| Claude Membrick only | 7.05 s | 15,914 | 0 | 3/3 | 1.40 s |
| Codex native memory | 38.13 s | 151,000 | 5 | 2/3 | 0 ms |
| Codex Membrick only | 18.53 s | 62,478 | 2 | 2/3 | 1.33 s |
Read the full conditions and limitations:
What Membrick can do
- Recover the right past session or project note when an agent needs context
- Rank current evidence ahead of superseded guidance
- Infer simple chronological configuration updates inside an established semantic domain
- Preserve historical evidence for historical questions
- Resolve relative-time queries against an explicit reference date when one is available
- Catch contradictions before they spread
- Detect terminology drift across documents
- Find orphaned or weakly linked pages
- Query facts, entities, symbols, ownership, and time
- Build review packets from changed files and related semantic context
- Feed grounded context into an LLM instead of raw text blobs
- Keep agent memory inspectable and local to the project
How it works
Membrick treats project memory as more than a bag of text.
Sessions · docs · code · traces
            │
            ▼
        1. Ingest
            │
            ▼
 Facts · entities · symbols · time
            │
            ▼
      2. Understand
            │
            ▼
 Links · ownership · supersession
            │
            ▼
       3. Connect
            │
            ▼
 Ranked · sourced · current context
            │
            ▼
       4. Retrieve
Under the hood, Membrick builds a lexical index plus sparse entity/term tables and overlays graph structure for links, symbols, ownership, semantic relations, and time.
A single prepared-query path owns query analysis, augmented search text, temporal context, routing intent, reference-clock handling, semantic suppression, and provenance annotation. The CLI and IndexStore use the same semantic/temporal query policy so current-state behavior does not depend on which high-level entry point you call.
The same corpus model powers review-oriented checks such as missing cross-references, orphan pages, low-confidence claims, stale knowledge, and semantic drift.
For implementation details, see:
Use Membrick from your stack
CLI
membrick --query "what is the current retry policy?" /path/to/repo
Docker / HTTP
export SERVER_TOKEN=local-dev-token
docker compose up --build -d
curl http://127.0.0.1:8080/health
See the HTTP server guide.
Python
Install the PyPI package to get both the Python MemoryService API and the
Rust membrick CLI on supported platforms:
pipx install membrick
membrick --codex-install .
For development from this checkout, build the optional Python extension withuv and maturin:
uv venv --python 3.10
source .venv/bin/activate
uv pip install "maturin>=1.9.4,<2"
maturin develop --release --uv
To build a distributable wheel instead, run maturin build --release; the
wheel is written under target/wheels/.
import membrick

memory = membrick.Memory(path="./memory-index")
memory.add(
    "request-1",
    "user-1",
    "session-1",
    [{"role": "user", "content": "Docker runs on Ubuntu hosts"}],
)
print(memory.search("docker ubuntu", "user-1", 5))

# Use the same API against a running membrick server:
# NOTE: base_url must be passed by keyword. A positional first argument
# is `path` and would silently create a local index instead of connecting.
remote = membrick.Memory(base_url="http://127.0.0.1:8080", api_key="local-token")
print(remote.search("docker ubuntu", "user-1", 5))
Rust
MemoryService is the only public memory access API. Request, response, document,
and configuration types are public; stores, indexes, snapshots, builders, and
persistence modules are internal. See the API migration guide.
use membrick::{MemoryService, PipelineOptions, SourceDocument};

fn main() -> anyhow::Result<()> {
    let mut memory = MemoryService::in_memory(PipelineOptions::default());

    memory.upsert(SourceDocument::with_stable_doc_id_from_source(
        "docs/install.md".to_string(),
        "Docker install guide for Linux hosts".to_string(),
        "docker install".to_string(),
        None,
        vec!["Overview".to_string()],
        vec![],
        None,
        None,
    ));

    memory.refresh()?;
    let results = memory.search_with_filters("docker install", "workspace", None, 5, &Default::default())?;
    println!("{}", serde_json::to_string_pretty(&results)?);
    Ok(())
}
See docs/quickstart.md for complete examples.
When is Membrick a good fit?
Membrick is especially useful when you maintain:
- Long-running agent memory over conversations, notes, and decisions
- Markdown knowledge bases with many cross-links
- Internal documentation where terminology and decisions drift over time
- Codebases where symbols, ownership, usage, and review context matter
- Fast-changing corpora where freshness matters as much as relevance
If your only requirement is simple keyword search over a static set of documents, Membrick is probably more machinery than you need.
Project status
Membrick is under active development. The release query path uses the heuristic backend; experimental model-backed query semantics remain separate from the audited release dependency graph.
The security audit workflow runs cargo audit. Binary persistence usesoxicode, and the lexical index uses Tantivy 0.25 to preserve measured recall.
Current audits report only
transitive Tantivy warnings in lru and memmap2; these are tracked for
upstream fixes.
Issues, benchmark reproductions, integration feedback, and contributions are welcome.
License
Apache-2.0
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi