sprag
Health Uyari
- License — License: Apache-2.0
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 5 GitHub stars
Code Basarisiz
- process.env — Environment variable access in bin/cli.js
- spawnSync — Synchronous process spawning in bin/postinstall.js
- process.env — Environment variable access in bin/postinstall.js
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Model-delegation router for Claude Code and Codex: lookups, checks and test runs go to cheaper models; savings show in the statusline.
A model-delegation router for Claude Code and Codex: lookups, checks and test runs go to cheaper models, and the savings show up in your statusline.


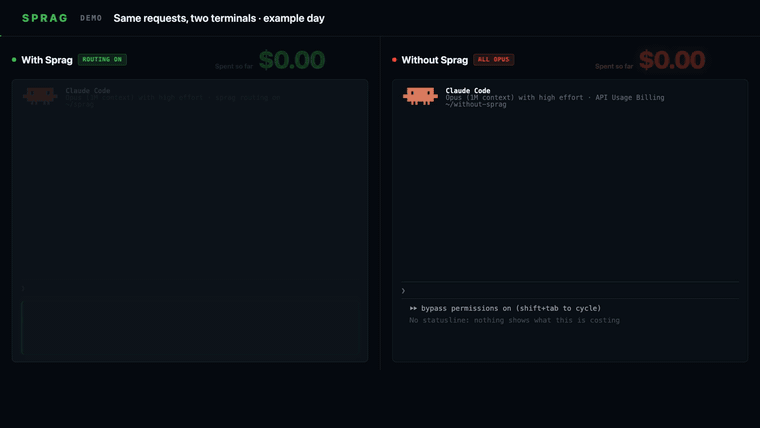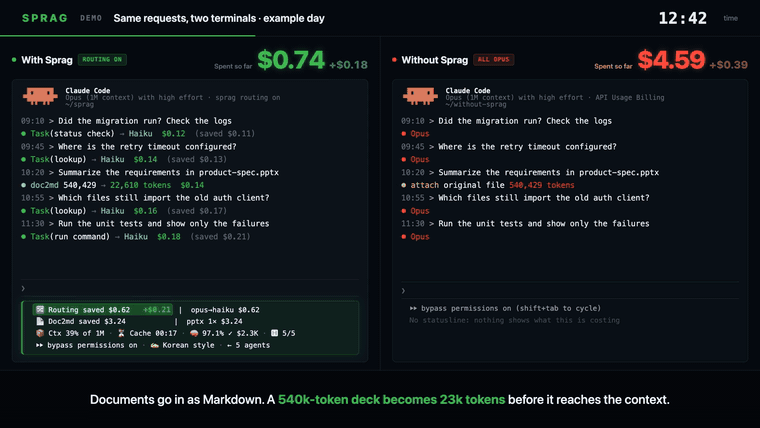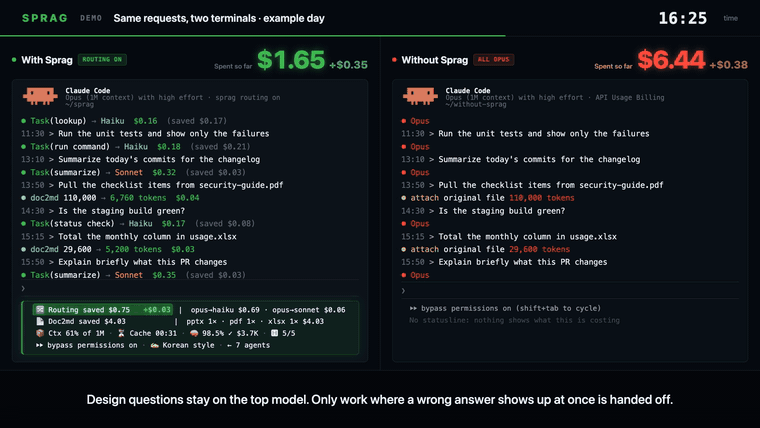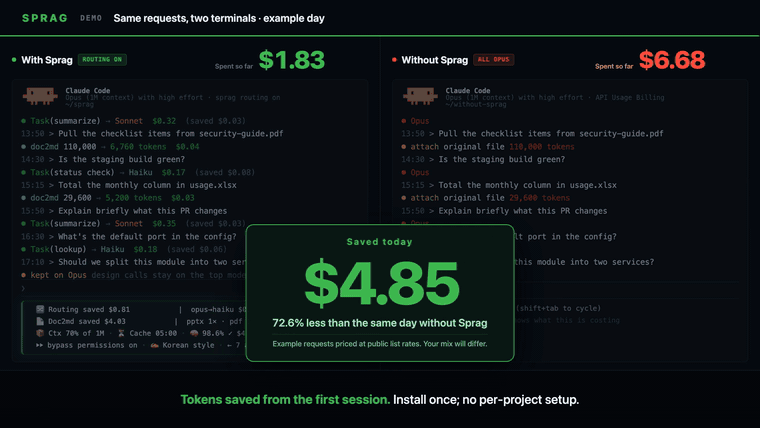
Same 12 requests, two terminals: $6.68 → $1.83 (−72.6%) with Sprag.
Example requests priced at public list rates. Full video (41s)
Sprag routes each piece of work to the cheapest model that has never got it
wrong. Claude Code and Codex cannot switch models per prompt, so Sprag does it
the one way that works: rules in the main session hand lookups, status checks,
build and test runs and batch edits to sub-agents pinned to a cheaper model. The
rules come from your own session logs, you approve each one, and every delegated
run writes its price difference to a ledger. npm i -g sprag-cli sets it all
up; nothing to configure per project.
Two more things ride along. Documents reach the context as compact Markdown (a
540k-token deck becomes 23k tokens), and the statusline shows what each session
spent and saved, with a warning chip in front when the cache, the context or a
rate limit needs attention.
The name is the sprag clutch: forward motion passes, backspin locks. Repeated
failures in your logs become rules loaded at session start, so the agent keeps
working and only the regressions get caught.
Session analysis runs locally on the logs Claude Code and Codex already write.
No extra model calls or API key are needed for analysis. Optional Codex gateway
budget and price lookups contact your configured LiteLLM endpoint using its
existing credentials. The CLI requires Node.js 20+ and one TOML parser dependency.
npm i -g sprag-cli # Claude Code, plus Codex when it is installed
If your package manager skips install scripts (pnpm, bun), run sprag install once after installing. The old claude-token-saver package stopped updating at 3.55.0, so move to sprag-cli.
After you install
- Run
npm i -g sprag-cli. Hooks, the statusline and the starter rules are set
up for every project; there is nothing to configure per project. If you
already have a statusline, the install asks whether to show both, replace
yours, or keep yours. - Open Claude Code in any project and work as usual.
- Watch the statusline. It shows what the session spent and saved, and a
warning chip leads the line when the cache, the context or a rate limit
needs attention:
🔀 Routing saved $188  |  opus→sonnet ×67 $93.4 · fable→sonnet ×26 $83.7 · opus→haiku ×25 $7.41 · fable→haiku ×6 $3.73
🧠 Cache hit 98.8% · ⏳ Cache expires 59:46 · 📦 Ctx 47% of 1M
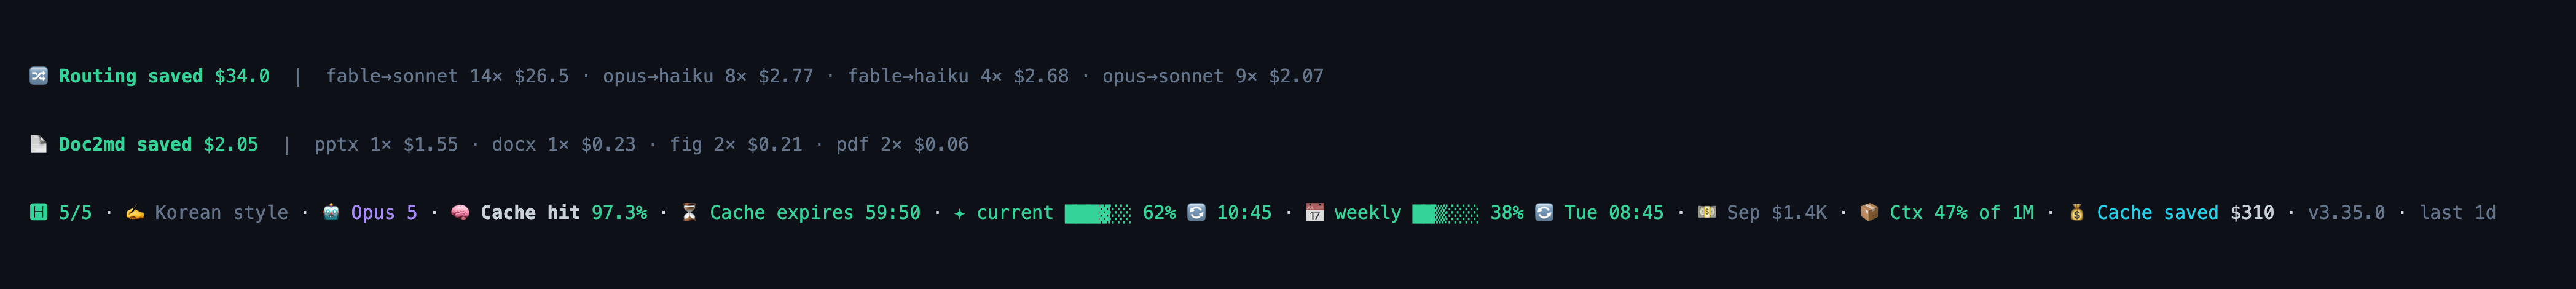
Sprag never swaps the model you picked. Analysis reads your local session
logs only, with no extra model calls and no API key. sprag uninstall removes
everything it added and restores a statusline it merged with.
Using Codex? See Codex below.
How it works
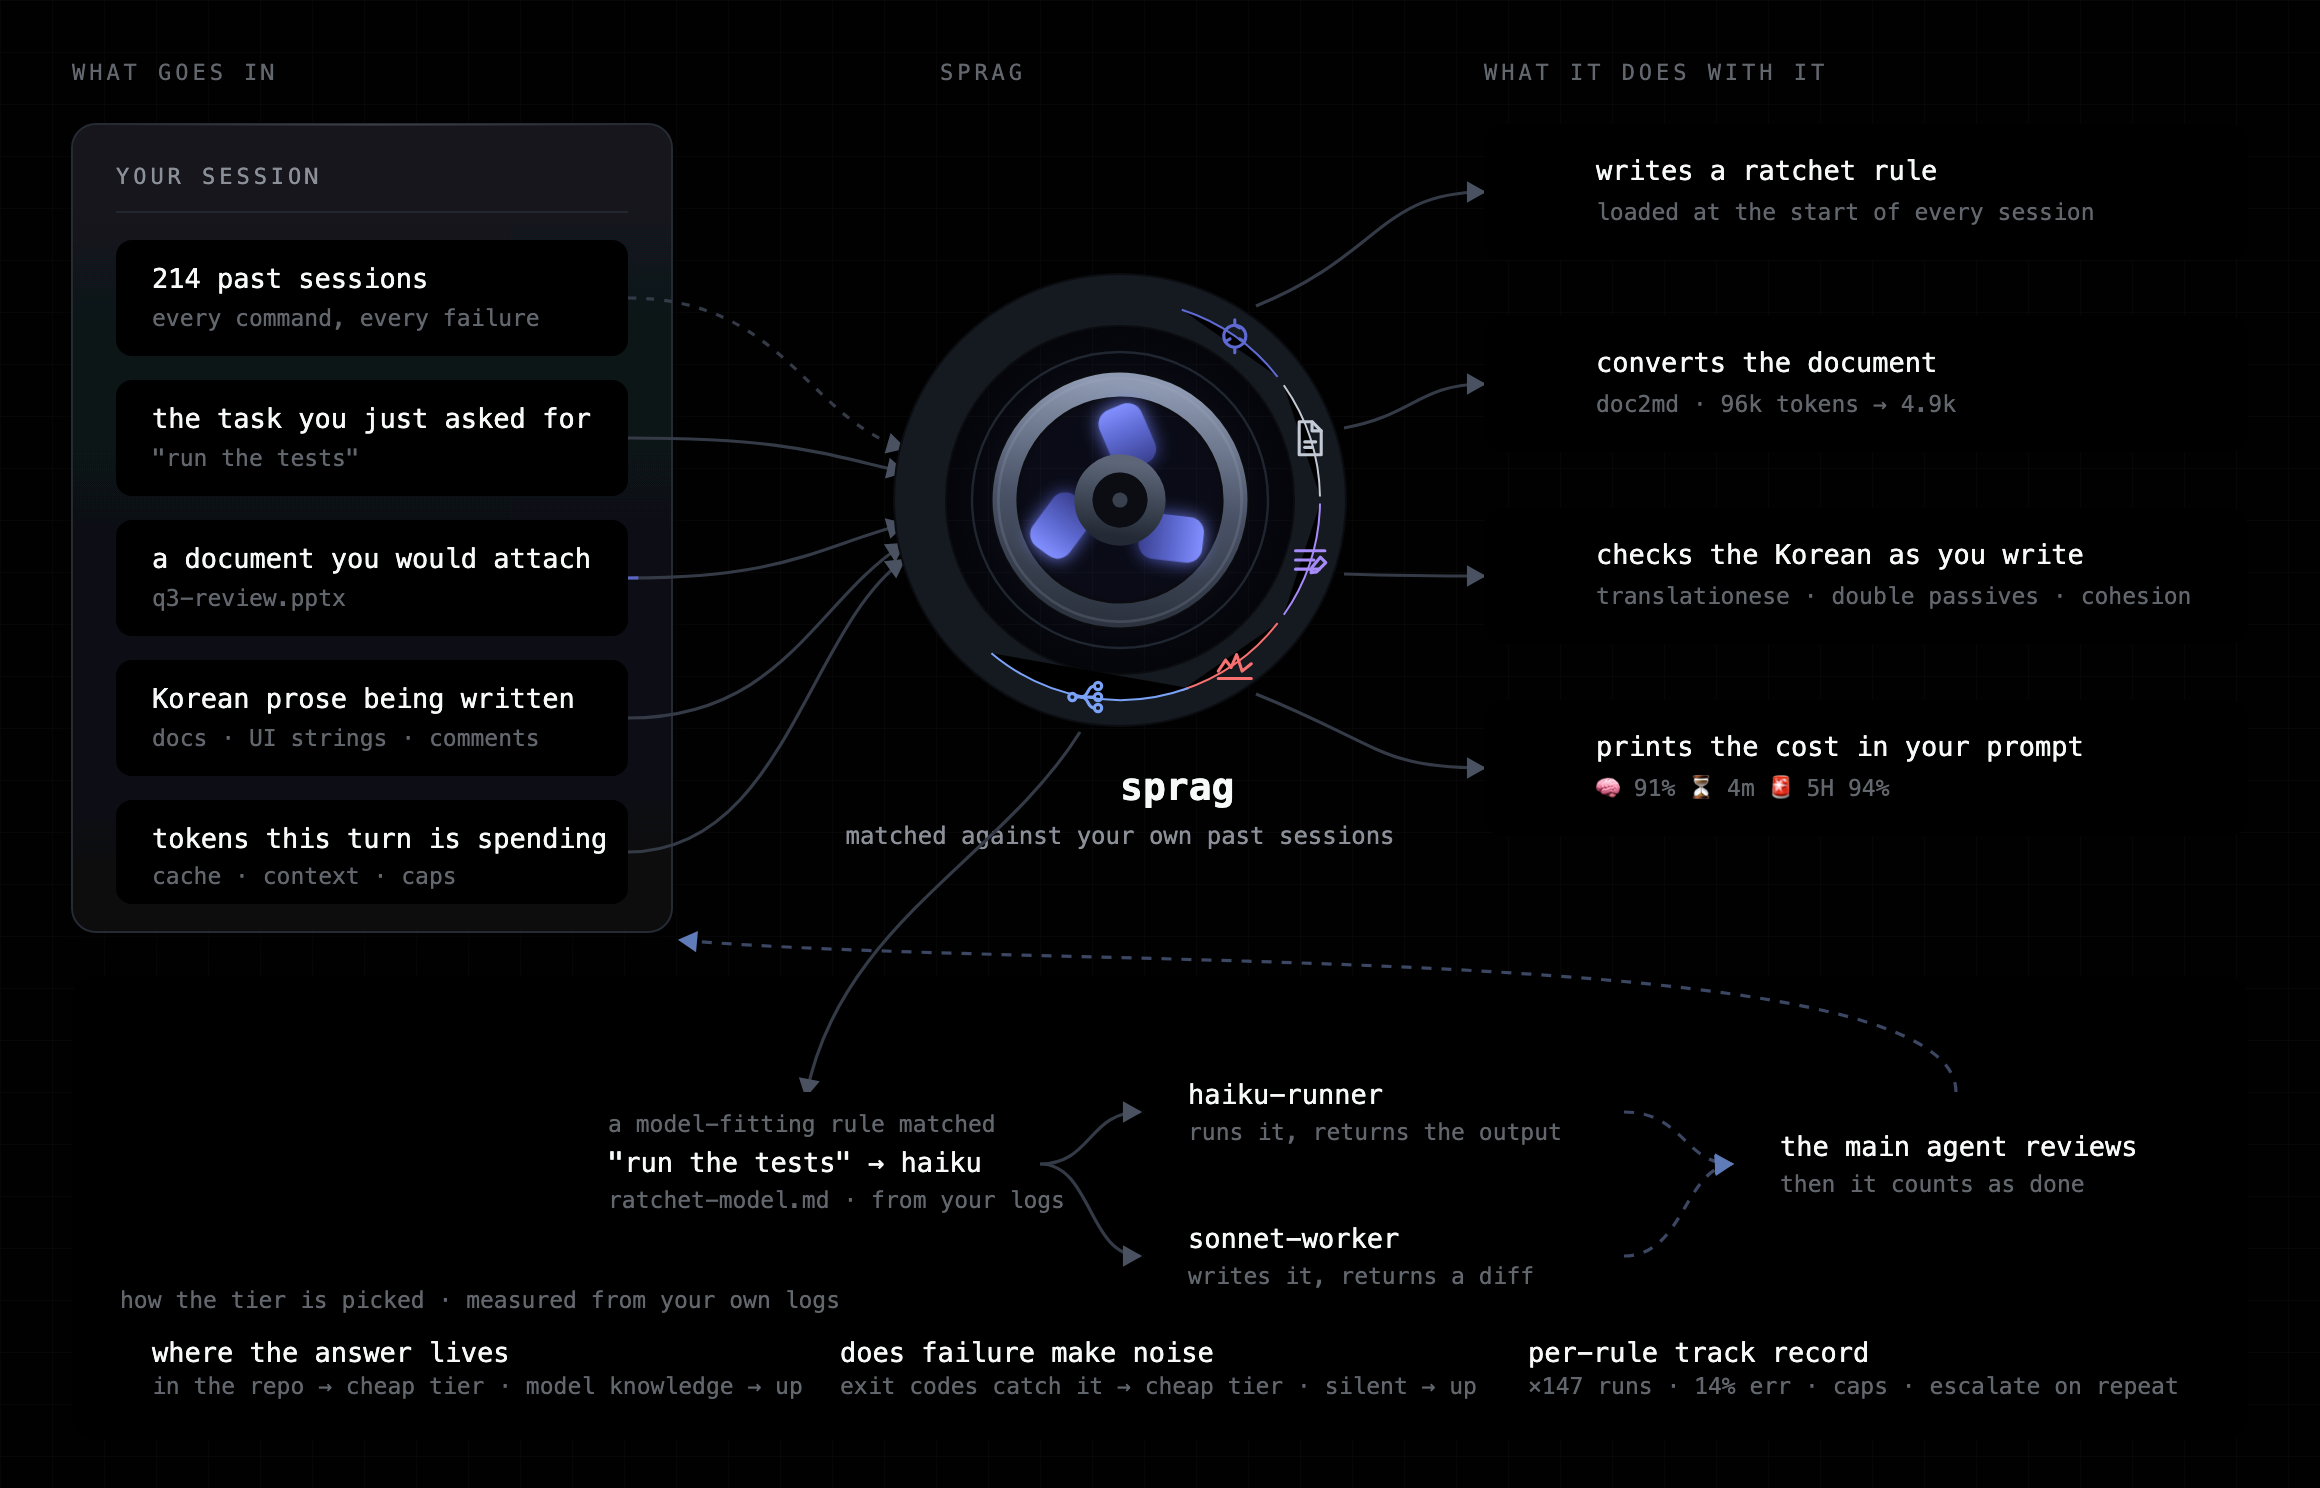
Everything on the left is something your session already produces. Nothing is
sent anywhere to read it. The tier decision at the bottom is the whole routing
argument in three tests: where the answer lives, whether a mistake surfaces, and
what error rate the rule was measured at.
Sprag does not swap the model you asked for. It reads what you have already run,
finds the kinds of task that never went wrong on a cheaper tier, and spawns a
sub-agent for exactly those. The main agent reviews what comes back before
anything counts as done, and the work returns to it the moment a rule stops
holding.
Measured results
| Metric | Result | Evidence | |
|---|---|---|---|
| Public benchmark accuracy | 59.1% vs 57.9% best single model | ▰▰▰▰▰▰▰▰▰▰▰▰ |
benchmark |
| Cost for the same queries | $268 vs gpt-5 $388, gemini-2.5-pro $734 | ▰▰▰▰▰▱▱▱▱▱▱▱ |
benchmark |
| Tokens for the same documents | −95.9%, 2,011,178 → 82,209 over 12 files | ▰▱▱▱▱▱▱▱▱▱▱▱ |
doc2md |
| Delegation savings, from the ledger | $188.27 over 124 delegated runs | ▰▰▰▰▰▰▰▰▰▰▰▱ |
sprag route-scan savings |
| Cheap tier on the same prompts | 24% of the cost, one answer worse out of eight | ▰▰▰▱▱▱▱▱▱▱▱▱ |
A/B run |
The first two rows answer the objection that comes up first: that moving work to
a cheaper model has to cost you accuracy. It did not. The same criteria, wired up
as a router, scored 1.2 points above the best single model at a third of the
cost. Nothing is best at everything, which is why choosing per task beats
choosing once.
Measured offline on LLMRouterBench (Findings of ACL 2026): 11,696 instances, 13
models whose answers, scores and costs ship with the dataset. No model was
called and nothing was spent. The router chose; the numbers were looked up. Run
it again and you get the same figures. It validates the criteria, not sprag's own
routing: the dataset has no Claude models, so deepseek-v3, qwen3-235b and gpt-5
stood in for cheap, mid and flagship.
The last three rows are ledgers on this machine. They grow as it runs. The
routing figures were read on 2026-10-09, the document figures on 2026-09-18.
Model names are the ones each run actually used.
Current, on one machine, last 30 days
🔀 Routing saved $188.27 total        (last 7d $13.31 · last 30d $150.64)

   fable-5 → sonnet-5      24 runs    $81.19   ▰▰▰▰▰▰▰▰▰▰▰▰
   opus-5  → sonnet-5      54 runs    $68.85   ▰▰▰▰▰▰▰▰▰▰▱▱
   opus-5  → sonnet-5.5    13 runs    $24.58   ▰▰▰▰▱▱▱▱▱▱▱▱
   opus-5  → haiku-4.5     25 runs     $7.41   ▰▱▱▱▱▱▱▱▱▱▱▱
   fable-5 → haiku-4.5      5 runs     $3.22   ▰▱▱▱▱▱▱▱▱▱▱▱
   fable-5 → sonnet-5.5     2 runs     $2.51   ▰▱▱▱▱▱▱▱▱▱▱▱
   fable-5 → haiku-5.5      1 run      $0.51   ▰▱▱▱▱▱▱▱▱▱▱▱
| Also measured | Over 30 days | |
|---|---|---|
| Documents converted | 12 files, 2,011,178 → 82,209 tokens | ▰▱▱▱▱▱▱▱▱▱▱▱ |
| Cache hit rate | 92.2% | ▰▰▰▰▰▰▰▰▰▰▰▱ |
| Volume behind both | 175 sessions · 14,682 API calls · 3.81B input tokens |
Real output, from sprag route-scan savings, sprag --days 30, and the doc2md
ledger. Nothing here is a projection.
Every delegated run records its own price difference, so sprag route-scan savings traces any amount back to the rule that caused it. What the ledger deliberately leaves out is written down in the command reference.
Research behind the tier rules
The tier criteria are not a hunch. Each one traces back to published routing
research, and the percentages quoted in the rules (28% vs 54% recall, a +63pp
gap on chained tool work) are sprag's own offline measurement on the datasets
below.
| Criterion | What the paper found | Paper |
|---|---|---|
| Delegate down, conservatively | As budgets grow, learned routers default to the most expensive model even when a cheaper one already suffices. | Lai & Ye, When Routing Collapses: On the Degenerate Convergence of LLM Routers (2026) |
| Judge difficulty by outcome | Every router on the board falls short of the oracle, mainly because it cannot tell when a smaller model is enough. Query difficulty is defined by how many of 42 models actually answered it. | Lu et al., RouterArena: An Open Platform for Comprehensive Comparison of LLM Routers (2025) |
| Thresholds from your own logs | Routing compares a predicted win rate against a cost threshold, and results are read by the share of calls sent to the strong model. sprag sets that threshold from your last 14 days at every scan. | Ong et al., RouteLLM: Learning to Route LLMs with Preference Data (2024) |
| Escalate on failure | A cascade tries the cheap model first and lets a check on the answer decide whether to go up. It matched GPT-4 with up to 98% lower cost. | Chen, Zaharia & Zou, FrugalGPT (2023) |
| Where the answer lives | Short-form factual recall measured on its own. The 28% vs 54% recall gap comes from this class of set. | Wei et al., Measuring short-form factuality in large language models (SimpleQA) (2024) |
| Tool orchestration stays up | Agents must coordinate tool calls with a user in a shared environment. The +63pp gap was measured here. | Barres et al., τ²-Bench (2025) |
| The public benchmark run | 400K instances, 21 datasets, 33 models. Several routers, commercial ones included, fail to beat a simple baseline. | Li et al., LLMRouterBench (Findings of ACL 2026) |
| Routing vs cascading | A taxonomy of when a routing decision is made, what it reads, and how it is computed. | Moslem & Kelleher, Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey (2026) |
Two criteria have no paper behind them. Batching tasks that read the same files
and splitting design from code writing come from sprag's own cost accounting:
on a sub-agent, loading context costs more than generating. The full reasoning,
in Korean, is in Tier criteria.
Everything ships in one install, working from day one
| What it does | More | |
|---|---|---|
| ⚙️ Ratchet rules | Repeated failures become one-line rules loaded every session. Candidates are detected from your logs, and you choose project or global scope. | harness |
| 🔀 Model fitting | Log-driven delegation rules carrying the error rate they were measured at and the savings they reported, written to ratchet-model.md. |
route-scan |
| 🅷 Harness score | Five operating principles checked live. Skip the verify step and 🅷 4/5 says so before you report done. |
harness |
| 📊 Token telemetry | Cache hit rate, TTL, context size, output spikes and both rate-limit windows, in the prompt every turn. | statusline |
| 📄 doc2md | pptx, xlsx, pdf, docx and fig converted on demand, so a document costs one read instead of your whole context. | doc2md |
| 🇰🇷 Style gates | Write-time prose lint enforced by hook. Shipping today for Korean technical writing: double passives, translationese, cohesion. | style |
The two savings figures are never added together. They measure different things:
the routing ledger records the price difference on delegated runs, and the
conversion ledger records tokens a document did not cost.
Neither one counts what the harness and the ratchet rules save. That saving
arrives as fewer round-trips rather than as cheaper ones.
The statusline in one line
🔀 Routing saved $188  |  opus→sonnet ×67 $93.4 · fable→sonnet ×26 $83.7 · opus→haiku ×25 $7.41 · fable→haiku ×6 $3.73
🚨 5H ▰▰▰▰▰▰▰▰▰▰▰▱ 94% 🔄 12:36 · 🤖 Opus 5.5 · 🧠 Cache hit 98.8% · ⏳ Cache expires 59:46 · 📅 weekly ▰▰▰▰▰▱▱▱▱▱▱▱ 38% · 💵 Sep $42 · 📦 Ctx 47% of 1M
When something is wrong the warning chip leads the line: 🚨 5H/7D NN%, ⚠ Ctx 500k+, ⚠ Cache miss, ⚠ Input spike, ⚠ Output heavy, ⚠ Call surge, ⚠ Rebuild churn, ⚠ 5m TTL. Paste the chip text into Claude and the Skill names the root-cause code and the fix. Every segment is explained in the statusline reference.
Inside a JetBrains IDE terminal the chips render as single-cell glyphs instead of emoji (◉ Cache hit 98.8% · ◧ Ctx 47% of 1M). The IDE's default font has no emoji glyphs, so emoji leave characters from the previous frame on screen, like Cache expires 4:545. Label modes covers the detail, plus sprag mode narrow and mode icon-force.
The cheap tier on the same prompts
The benchmark uses public data. This asks the same question of my own work: eight
prompts from real sessions in this repository, sent to both tiers, graded against
an answer written before the run (2026-09-17, raw data invideo/out/measure2.json).
| flagship (opus-5) | cheap tier (haiku-4.5) | |
|---|---|---|
| Cost for all eight | $2.5652 | $0.6132 (23.9%) |
| Graded correct | 7 / 8 | 6 / 8 |
| Gave the same answer | 6 / 8 |
The prompt both tiers missed is the useful one. It asked which files referenceprocess.env without saying whether subdirectories counted, and the two read it
differently. Adding that one condition made their answers identical. The question
was ambiguous, not hard.
The remaining miss is the cheap tier leaving entries out of a file listing. A
wrong listing is one you can see is wrong, which is the second criterion doing
its job.
So the cheap tier is not free. On this sample one lookup in eight comes back
worse, for a quarter of the price. That is why rules only send work whose failure
surfaces, and never send design or diagnosis.
What the method has produced here
| Measured | Value | Sample | Window |
|---|---|---|---|
| Documents converted | 2,011,178 → 82,209 tokens | 12 files (xlsx, pptx, pdf) | to 2026-09-18 |
| Delegated runs | $188.27 saved, $1.52 per run | 124 runs | to 2026-10-09 |
| Ratchet rules accumulated | 37 (30 global, 7 per-project) | 4 repositories | 2026-05-08 to 09-16 |
The two counts grow differently. Ratchet rules come from mistakes a person made,
so they keep coming. Delegation rules stop: the criteria recognize a fixed set of
work types, and once each has a rule there is nothing left to promote.
Codex
Codex gets native hooks, an AGENTS.md harness, scoped ratchet rules, Korean lint, document conversion, token reports and a session-bound companion panel. npm i -g sprag-cli sets Codex up too when it is installed, with the starter rules registered globally and nothing asked (sprag install --manual asks at each step). For a Codex-only install that leaves Claude Code alone, run npm i -g sprag-cli --ignore-scripts and then sprag install --agent codex.
Commands default to Claude Code; add --agent codex to pick Codex, for example sprag --agent codex --days 7 or sprag panel --agent codex. Review and trust the new hooks in Codex's /hooks menu, because Codex requires that step. The dollar figures in this README come from Claude Code sessions, not from a Codex benchmark.
The full command list, the Claude Code and Codex comparison, accounting limits and removal are in Codex support and limits (source), or run sprag capabilities --agent codex for the support matrix.
Presets
The ratchet presets, model-routing presets and delegation agents in presets/ are also published centrally from the Sprag console. Once a day the CLI asks the Sprag server whether a newer version exists, a read-only request that carries nothing about you, and applies it only when its signature verifies against a key built into the CLI. Offline, blocked or unverified, it keeps the copy bundled with the package. A new version takes effect at the next session start, and presets you already accepted with sprag seed pick up reworded text on their own; new presets are still offered one at a time.
sprag presets status shows which copy is in use and why, sprag presets sync checks now, sprag presets show prints the effective presets, and SPRAG_NO_PRESET_SYNC=1 turns the fetch off. The request is listed in the network table of the install guide.
Day-to-day commands
| Command | What it does |
|---|---|
sprag |
Last-30-day diagnostic report |
sprag handoff |
Back work up to markdown before a cap blocks you |
sprag route-scan |
Find delegation candidates in your own history (0 LLM calls) |
sprag route-scan savings |
The routing-savings ledger |
sprag harness check |
Current 🅷 harness score |
sprag doc2md <file> |
Convert one document to Markdown |
Every subcommand, flag and the output-language setting: command reference.
Documentation
| Doc | Covers |
|---|---|
| Codex | Installation, panel, native hooks, automatic candidates, presets, and accounting limits |
| Install | What the install turns on, what stays manual, how to turn each part off |
| Statusline | Segments, warning chips, spike issue codes, update notifications |
| Commands | Full CLI surface |
| Harness | The five principles, rule promotion, compact-window pinning, seed presets |
| route-scan (한국어) | Tier verdicts, rule-file mechanics, scan triggers, subagent setup |
| Tier criteria | Why T0/T1/T2 split where they do, with sources (Korean) |
| Benchmark | The 11,696-instance LLMRouterBench run |
| doc2md (한국어) | Supported formats, savings evidence, editing documents, DRM cases |
| Korean style | What gets injected, the write-time check, before/after |
| Not a router | Why realtime routing breaks the cache and costs more |
| Gateways & environment | Bedrock, Vertex, LiteLLM budgets, pricing table, FAQ, how it works |
| Reduce Claude Code tokens | Compact/clear timing, subagent exploration, document conversion, cache TTL |
| Claude Code usage limits | The 5-hour and 7-day windows, watching both, cutting per-turn cost |
| Codex token usage | Session scoping, native subagent delegation, document conversion for Codex |
| Compare | Sprag vs ccusage, claude-usage, and statusline tools like CCometixLine |
Release notes
Recent releases:
- v3.67.0: Tool-restricted delegation agents keep subagent requests light behind a gateway (the first request drops from 46,618 to about 20,000 tokens on a LiteLLM proxy), ratchet rules reach the Claude app's Cowork tab, and the design/implementation split ships as a bundled preset.
- v3.66.0: The Claude desktop app shows the sprag statusline, password-protected and DRM documents are refused with a clear notice, and model profiles are learned from the model a subagent actually ran on.
- v3.65.0: The routing headline shows what delegation cost next to what it saved (
Routing saved $15.1 · spent $9.78 since 10/9), and the session subagent chip shows what those runs spent.
Every release is on GitHub Releases, and the full history is in CHANGELOG.md (Korean; version headings and command names are language-neutral).
Feedback
Bugs and feature requests go in the issue tracker: https://github.com/rootstudioyaml/sprag/issues
With no browser or GitHub login at hand (corporate network, mid-session), submit straight from the terminal instead, or ask Claude to do it for you:
sprag feedback "the 5m TTL chip never clears on Bedrock"
It files a GitHub issue through the gh CLI when one is authenticated. Otherwise it submits anonymously, with no login, which works where github.com is blocked. Pass --anonymous to skip the gh path. Version and OS metadata are attached automatically.
For a bug, please include the tool version (sprag --version) and your OS. For a statusline or warning issue, add the statusline output or the sprag last result.
Teams
The CLI is free and works on its own on one machine. For organizations, Sprag Pro and Sprag Enterprise add a shared dashboard built from the same local session logs. To start, write to [email protected].
Pro: team dashboard
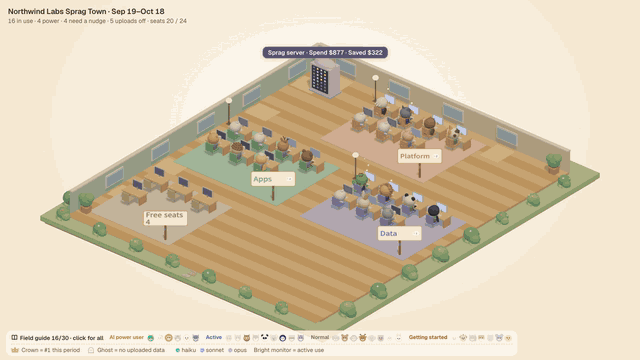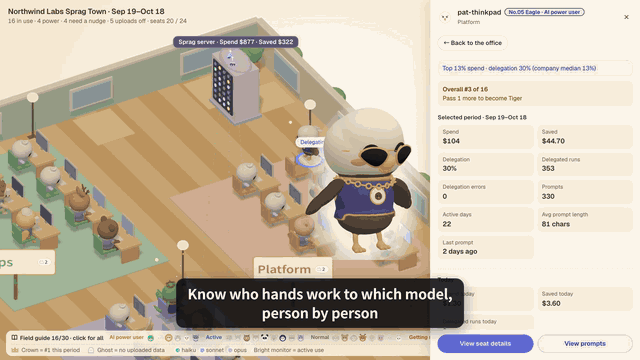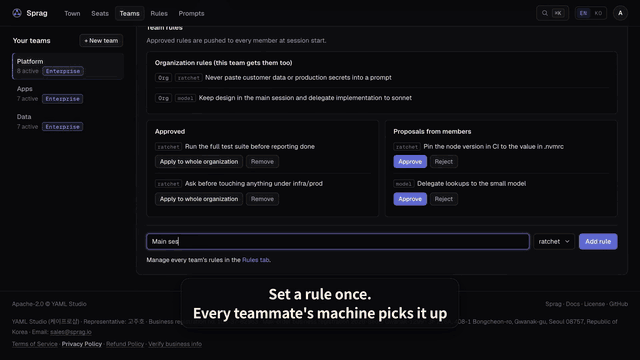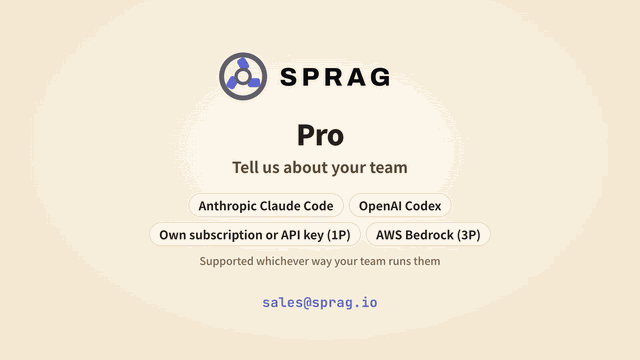
- Organization dashboard with a 30-day chart
- A virtual office with an animal for each person
- Seat roster with each machine's status
- Team-approved rules applied at session start
- Rollout with
sprag team join - Owner and admin roles, activity log
Enterprise: prompt monitoring
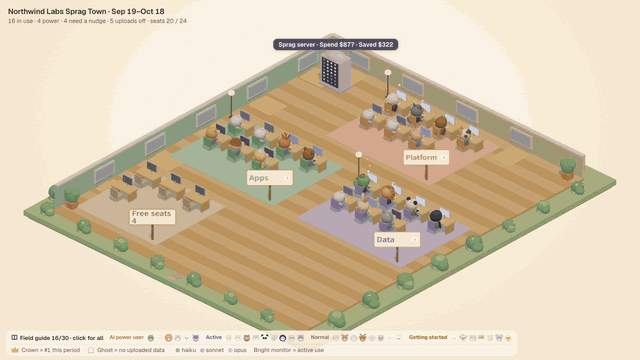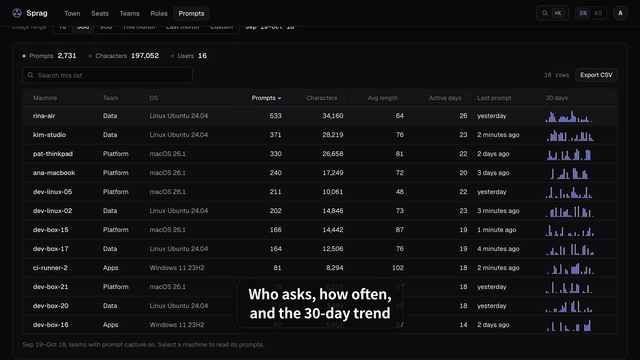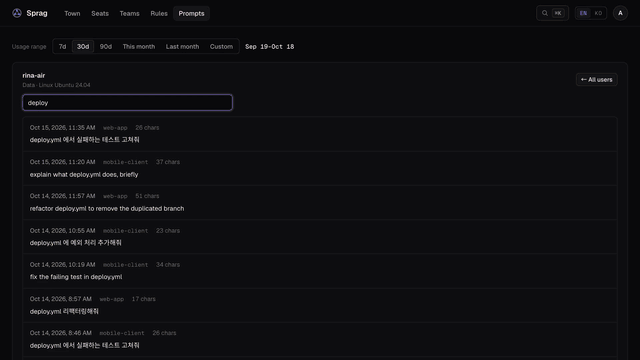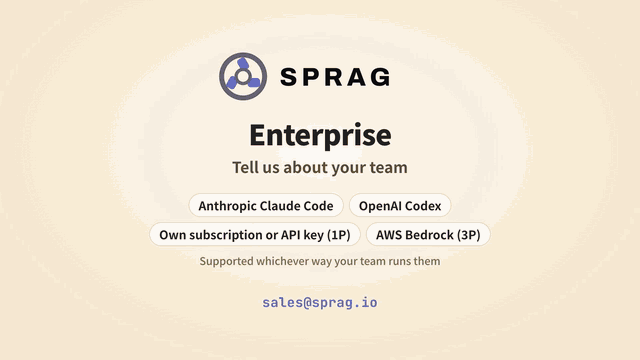
Everything in Pro, plus:
- Prompt capture per team, with secrets redacted
- Nothing from before the policy was turned on
- Per-user prompt usage and a 30-day trend
- Each user's prompt list with search
- A capture policy every member can see
Prompt capture is off unless an organization owner or admin turns it on.
Both videos are recorded from the demo dashboard with sample data. Full videos: Pro (30s) · Enterprise (30s)
What a machine sends
Sprag stays local unless you opt in. With sprag team join <token> (or SPRAG_TEAM_TOKEN for a whole organization), each machine uploads one row per day: spend, savings, delegated-run count and model-family share. Transcripts, file paths and project names are never sent. Prompts are not sent either, unless an Enterprise organization turns on prompt capture, and sprag team status --show-payload prints exactly what would go up. In return the team owner sees per-member totals in a dashboard and can approve ratchet rules that every member picks up automatically.
SPRAG_NO_TEAM_SYNC=1 turns all team traffic off, and sprag team leave removes the membership.
- Team layer guide
- Team console for owners and admins: https://sprag.io/team/
- Plans: https://sprag.io/license/
License
Apache License 2.0. The full text is in LICENSE, and the attributions
it requires are in NOTICE.
Releases up to and including v3.47.0 went out under the MIT License. A copy
received under those terms stays under them; the new license applies to
releases after that.
Running sprag inside a product or a paid service? The license already permits
that, so this is not a request for permission. We would like to hear about it
anyway, because the parts that get awkward at scale are the parts we would rather
fix than have you work around: shared ratchet rules across a team, gateway setups
where the model id is an opaque profile, and per-seat budget reporting. Open an
issue or reach us through the
channels below.
Who makes this
Built at DeepPulse, a channel about AI developer tooling, and used there every day. The launch Short (60s) covers where it came from and how it gets used.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi