litsurvey
Health Uyari
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 6 GitHub stars
Code Gecti
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Literature surveys with an LLM: cited state-of-the-art reports, prior-art checks, citation graphs, BibTeX export. OpenAlex + Semantic Scholar + arXiv + preprint portals. Zero dependencies.
litsurvey
A research assistant for the literature: ask a question, get a cited
state-of-the-art survey; state a claim, get a prior-art verdict; give a
paper title, get everything that cites it. It runs on your laptop and uses
the LLM you already have, whether that is a Claude, ChatGPT or Gemini
subscription, a local model, or an API key. One Python package, no runtime
dependencies, Python 3.10 or newer.
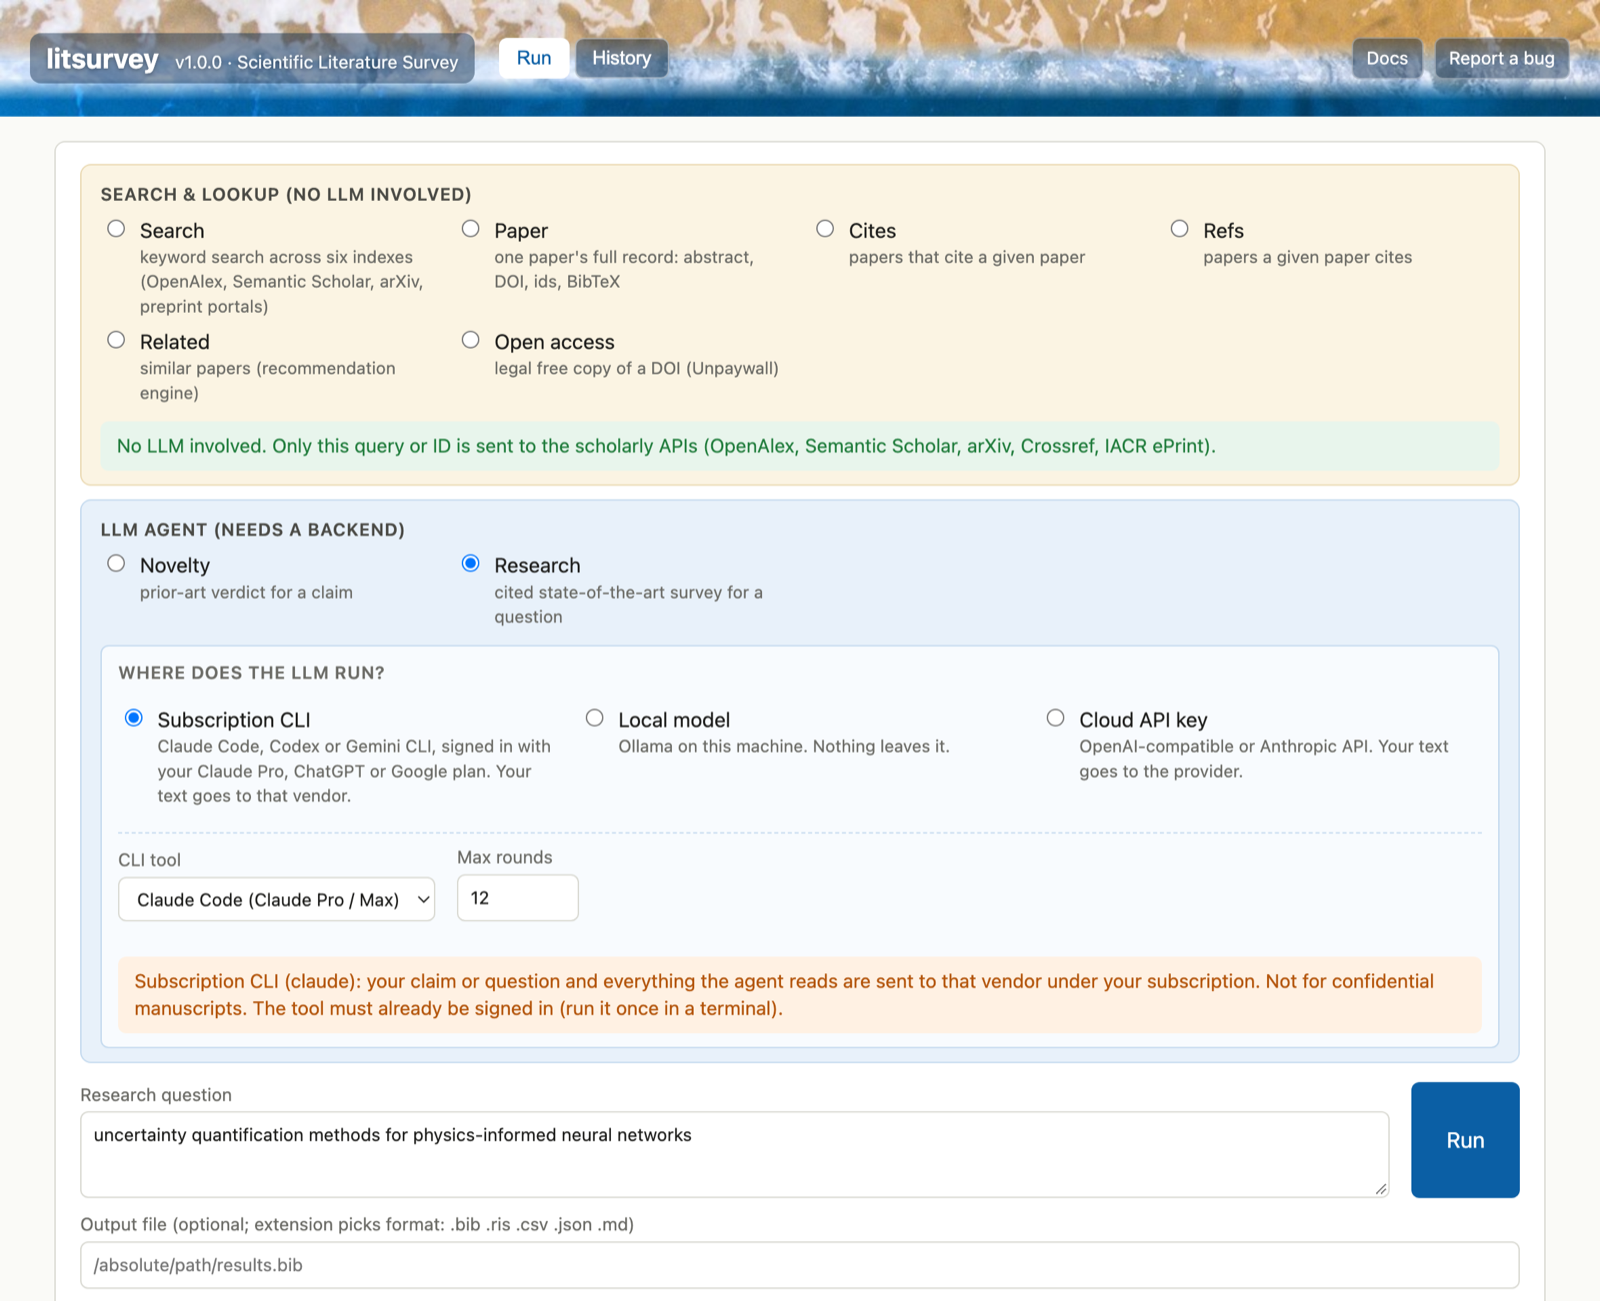
The easiest way to use litsurvey is the browser page. Install it, runlitsurvey web, and every mode below — search, lookups, the LLM agents and
the history — is a form on 127.0.0.1:8765, with buttons for sorting and
downloads and nothing to memorise. A few things stay on the command line:
choosing which indexes to query (--sources), --debug, init anddoctor, and anything you want to script.
What it does
LLM-driven (the main draw)
research "question": the model breaks the question into sub-questions,
runs searches across six scholarly indexes, walks the citation graph of
the central papers, reads one or two arXiv papers in full, and writes a
survey organised by theme with numbered citations, open problems, and an
honest coverage caveat. Every citation comes from a real search result,
and the report ends with a log of every query that was run.novelty "claim": the same machinery aimed at one claim: closest prior
work, what is new versus known, a verdict (clearly novel / incremental /
substantially anticipated / cannot determine) with confidence, and
citations a reviewer can use.- Runs on any of: your subscription's command-line agent (Claude Code,
Codex CLI, Antigravity CLI, Gemini CLI; no API key), a local model through Ollama
(nothing leaves the machine), or a cloud API key (OpenAI, OpenRouter,
Anthropic, any OpenAI-compatible server).
Search and lookup (no LLM)
- Fused search over OpenAlex, Semantic Scholar, arXiv, PubMed, TechRxiv,
Research Square and the IACR ePrint archive, de-duplicated, sortable by
relevance, citations or year. Europe PMC and all of Crossref can be added
with--sources. - For any paper, by title or id: who cites it (most-cited first), what it
cites, similar papers from a recommender, its full record and BibTeX, and
a legal open-access copy. - Export to BibTeX, RIS, CSV, JSON or Markdown for Zotero, Overleaf, Mendeley
or a spreadsheet. - A history of every completed run, shared by the command line and the
browser page, with the same downloads.
Install
pipx install litsurvey          # recommended: isolated install, gives the `litsurvey` command
# or
pip install litsurvey
# or the latest development version straight from GitHub
pip install git+https://github.com/udaykdk/litsurvey
Or clone and run without installing: python3 -m litsurvey --help.
Then start the browser page:
litsurvey web
It opens http://127.0.0.1:8765 in your browser, serves only to your own
machine, and needs no configuration to start searching. The rest of this
page shows the command-line equivalents.
The Semantic Scholar key (optional, recommended)
Only one of the seven default sources needs a key at all. Semantic Scholar works without
one too, but on a shared pool that is often rate-limited and at busy times
refuses every request. A free key gives you a dedicated one request per
second and makes the citation-graph and recommendation lookups reliable.
- Request it at https://www.semanticscholar.org/product/api (the API key
request form; name, email and a one-line purpose such as "literature
search for academic research"). Approval comes by email, usually within
a day or two. - Store it with
litsurvey init(writes~/.litsurvey/config.json), or
set the environment variableS2_API_KEY. The same step stores your
email, which gets you OpenAlex's and Crossref's faster polite pools.
Without the key: searches still return results from OpenAlex, arXiv,
Crossref and IACR in about ten seconds; cites, refs, related andpaper fall back to OpenAlex for any paper with a DOI; the LLM agents run
but see fewer results. litsurvey doctor reports the state and prints aRESULT: verdict. Details in
docs/api-keys.md.
Examples
A state-of-the-art survey, written by the model from live search results:
litsurvey research "uncertainty quantification methods for physics-informed neural networks" --out uq-survey.md
A prior-art check on a claim, phrased as a generic topic (never a sentence
from a confidential manuscript):
litsurvey novelty "adaptive sampling of collocation points in physics-informed neural networks" --out claim.md
Choosing where the model runs:
litsurvey research "..." --backend cli --model claude          # Claude Code, under your Claude Pro/Max plan
litsurvey research "..." --backend ollama --model qwen3:30b    # local; nothing leaves the machine
litsurvey research "..." --backend openai --base-url https://openrouter.ai/api --model anthropic/claude-sonnet-4.5
With a subscription CLI, litsurvey chooses the model and reasoning effort
rather than inheriting whatever that tool is configured to use — which, for
people who have turned it up for coding, is often the top model at the
highest effort. That is more model and more thinking time than running
searches and summarising results needs, and it comes out of the same
subscription quota. So litsurvey init asks the installed tool what it
supports and picks one model below the best, at an effort level in the middle
of the range: for Claude Code today, Opus at high. This is litsurvey's
policy, not a measured quality judgement — if you would rather have the top
model, set cli_model to -. litsurvey doctor prints what will be used.
See
docs/llm-integration.md.
Search and lookup, with titles instead of ids:
litsurvey web                                                            # the browser page: all of the below, as a form
litsurvey search "physics informed neural networks inverse problems" --year-from 2022 --sort citations
litsurvey cites "Superior thermal conductivity of single-layer graphene"   # picks the paper, lists the most-cited citers
litsurvey related "Embedding deep learning in inverse scattering problems"
litsurvey paper "KAN: Kolmogorov-Arnold Networks" --out ref.bib          # BibTeX for a paper you know by title
litsurvey oa "10.1016/j.cma.2022.114823"                                 # legal free PDF
When a title matches several papers, litsurvey shows the candidates and
asks; scripts and agents get the list and use --pick N.
Typical times: a search takes roughly ten to twenty seconds, since the
sources are queried one after another at the rate limits they ask for;novelty and research take two to fifteen minutes depending on the model.
What needs an LLM, and what leaves your machine
| Command | LLM | What is sent out, and to whom |
|---|---|---|
search, paper, cites, refs, related |
no | your query, or a paper id or title, to the scholarly APIs (OpenAlex, Semantic Scholar, arXiv, PubMed/NCBI, Crossref, eprint.iacr.org, and Europe PMC/EBI when asked for) |
oa |
no | one DOI to Unpaywall (a title is first resolved through the search APIs) |
history, init, doctor, web |
no | nothing (doctor makes one test query per source; actions on the web page follow the rows above) |
novelty, research, local model (Ollama, or an OpenAI-compatible server on localhost) |
yes, local | the keyword queries the model composes and the paper ids it looks up, to the scholarly APIs; your text stays on the machine |
novelty, research, subscription CLI (Claude Code, Codex, Antigravity, Gemini) |
yes, vendor cloud | your claim or question and everything the agent reads, to that vendor under your subscription (see the note on model and effort below) |
novelty, research, cloud API key |
yes, cloud | your claim or question and every search result, to that provider |
For confidential work (a manuscript under review, an unpublished result)
use a local model and phrase the input as generic topic terms. Completed
runs, including inputs and results, are stored under ~/.litsurvey/ on
your disk. LLM reports are aids, not verified reviews: check the cited
paper and DOI before using any claim. Details in
docs/confidentiality.md.
Documentation
- docs/cli.md: every command, option and output format, with sample output
- docs/web.md: the browser interface and the History tab
- docs/use-cases.md: seven scenarios with the exact commands, from student discovery to confidential peer review
- docs/llm-integration.md: LLM backends and models; using litsurvey as a tool from Claude Code, Codex and other agents
- docs/confidentiality.md: what leaves the machine, per mode and backend
- docs/api-keys.md: getting and storing the Semantic Scholar key; running without one
- CONTRIBUTING.md: reporting bugs, running tests, adding a source
Coverage, and Google Scholar
Seven sources are searched by default: OpenAlex (about 250 million works),
Semantic Scholar (about 220 million), arXiv, PubMed (more than 40 million
biomedical citations, through the NCBI E-utilities), and three preprint
portals: TechRxiv and Research Square (through Crossref, by their DOI
prefixes) and the IACR Cryptology ePrint Archive (which has no search API,
so litsurvey reads its search page; if that page changes, only that source
goes quiet).
Two more can be switched on with --sources, and are off by default because
each largely repeats a source already in the list: europepmc (Europe PMC —
PubMed's ground again, but with citation counts and the bioRxiv/medRxiv
preprints) and crossref (all DOI-registered works, overlapping OpenAlex).--sources also restricts the set, which is the way to make a search
faster: --sources openalex,s2,arxiv is the quick physics-and-engineering
set.
Together they cover most of what Google Scholar shows, except some grey
literature (technical reports, theses, standards). Google Scholar has no API
and its terms of service forbid automated access, so litsurvey does not
scrape it; litsurvey search --scholar prints the matching Google Scholar
URL for a manual comparison, and the web page has the same link.
DBLP is not included. Its search API sits behind a proof-of-work bot wall on
every mirror, which a client like this cannot pass without defeating the
check, so litsurvey does not try. Most DBLP-indexed computer science work
reaches you through OpenAlex and Semantic Scholar anyway.
Data attribution
Results come from OpenAlex (CC0),
Semantic Scholar (Semantic Scholar Open
Data Platform, Allen Institute for AI), arXiv (thank you
to arXiv for use of its open access interoperability),
Crossref,
PubMed and
Europe PMC, the
IACR Cryptology ePrint Archive and
Unpaywall. If you publish work that used these
results, please credit them.
Author
Designed by Uday Khankhoje, Department of Electrical Engineering, IIT
Madras; implemented with Anthropic Claude. Questions and bug reports: the
issue tracker.
Credits
The banner of the web page uses slivers of an aerial beach photograph by
Lance Asper on Unsplash.
Citing
See CITATION.cff.
GitHub shows a "Cite this repository" button on the project page.
License
MIT. See LICENSE.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi