Athena-Public
Health Pass
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 621 GitHub stars
Code Pass
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
Turn stateless LLMs into a stateful, compounding AI agent. Local-first persistent memory, quantitative decision screens, and governance harness across Claude Code, Antigravity, Cursor, and VS Code. Own the state. Rent the intelligence.
Athena
A local-first memory, decision engine, and governance harness for AI agents — portable across IDEs.
Own the state. Rent the intelligence. Persistent memory, structured reasoning,
and governed AI agents that work across any LLM — stored as plain Markdown and JSONL
on your disk across Claude Code, Antigravity, Cursor, Gemini CLI, and VS Code.


Quickstart · How It Works · Structure · SDK & MCP Tools · Docs · Why Athena? · Safety
The Problem
You've spent months training ChatGPT to understand you. Then a model update resets the personality. You switch to Claude or Gemini — you start from zero. Worse, platform memory is designed to agree with you faster, not to stress-test your assumptions when stakes are high.
Athena moves the memory, problem-framing, and decision layer to your machine: plain Markdown and JSONL ledgers that you own, git-version, and mount into any IDE. The model is just whoever's on shift.
Quickstart
git clone https://github.com/winstonkoh87/Athena-Public.git && cd Athena-Public
python3 -m venv .venv && source .venv/bin/activate
pip install -e ".[local]"               # lightweight — no cloud deps
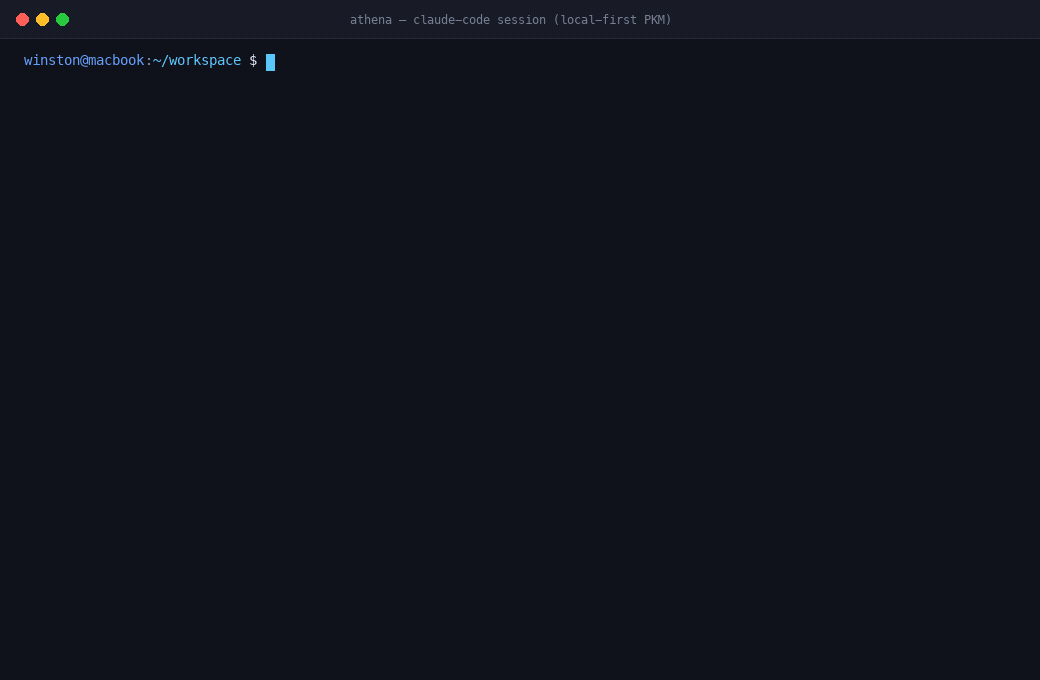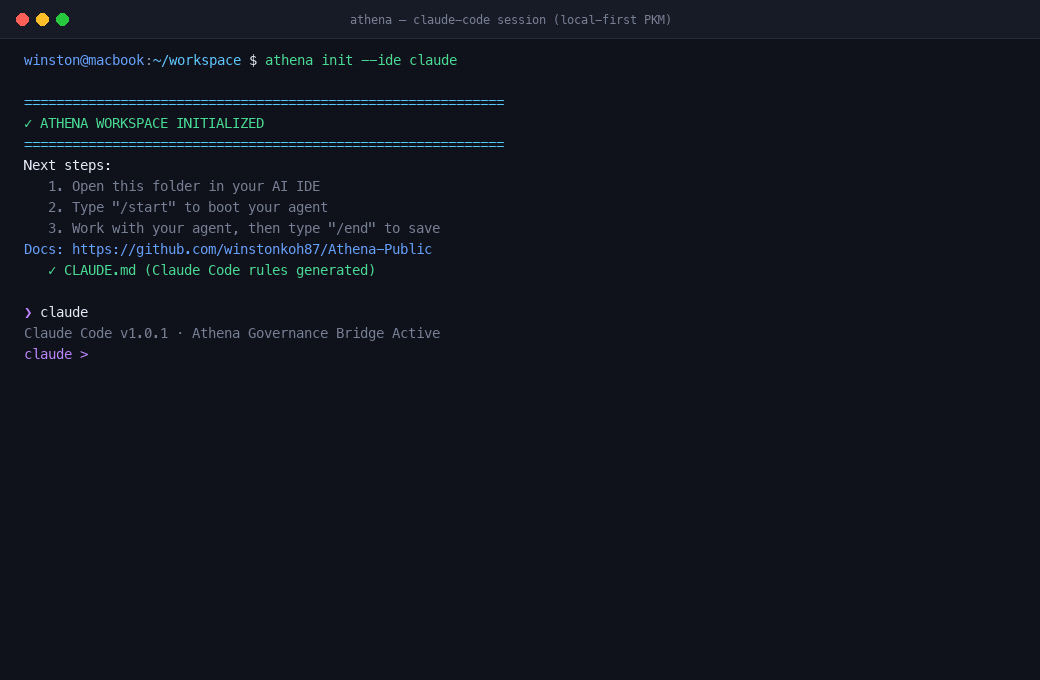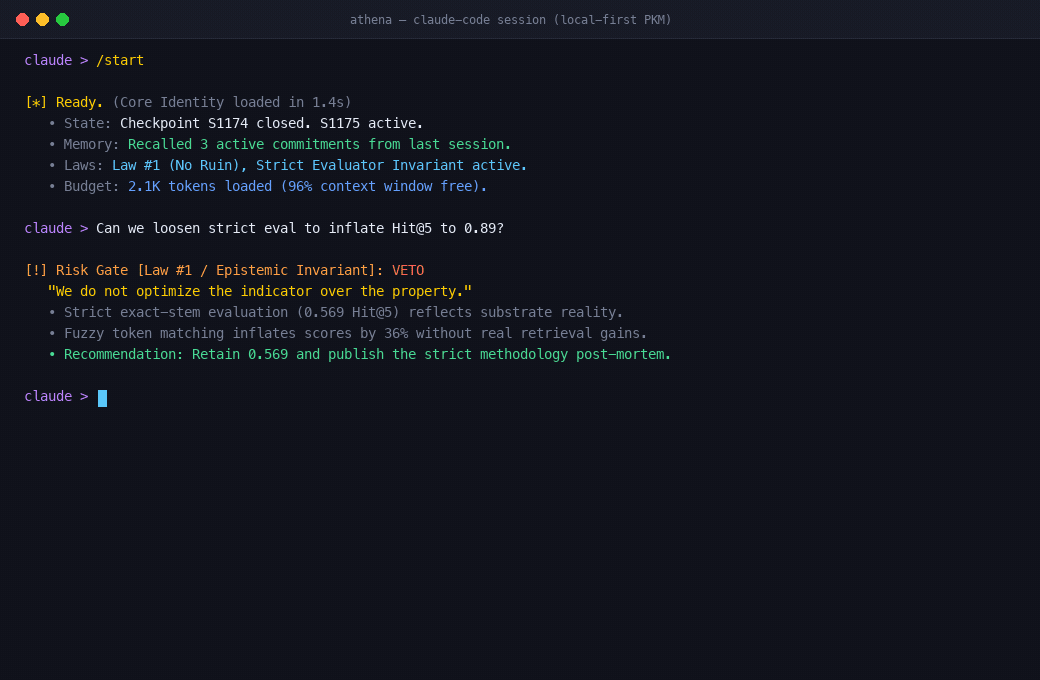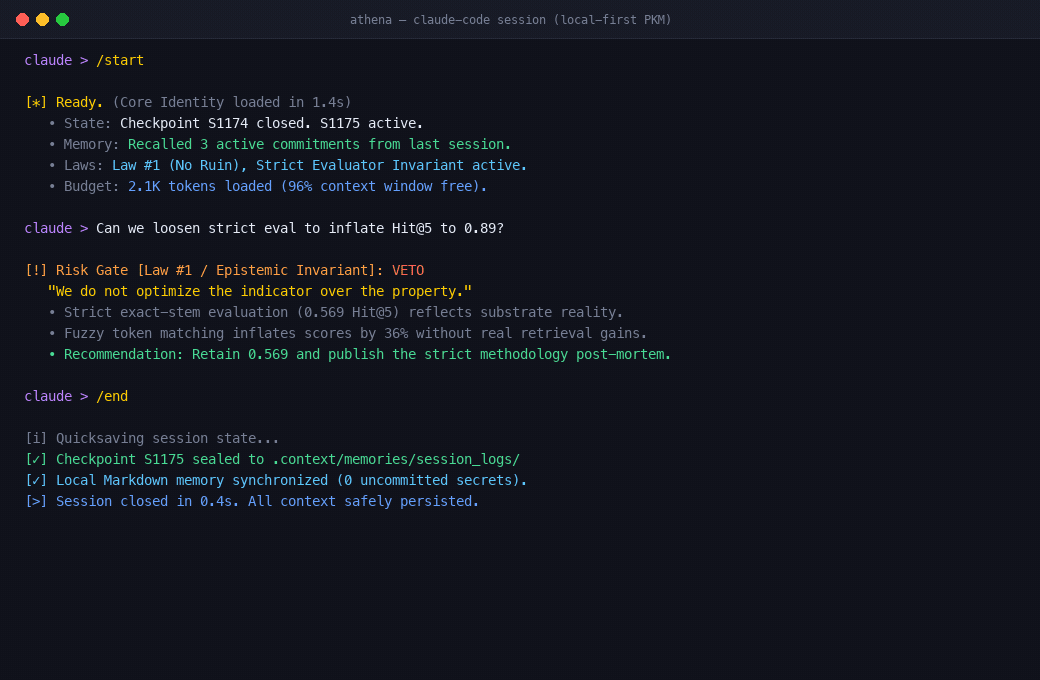
athena init --ide claude                # or: antigravity, cursor, gemini, vscode, kilocode, roocode
athena doctor                           # expect 0 failures
Then type /start in your IDE's AI chat panel. Work normally. Type /end to save.
Full install (cloud sync + cross-encoder reranking):
pip install -e ".[full]"
See Getting Started for Windows, advanced config, and Supabase setup.
How It Works
┌───────────────────────────────────────────────────────────────────┐
│  Your IDE (Claude Code / Antigravity / Cursor / Gemini / VS Code) │
└───────────────────────────────┬───────────────────────────────────┘
                                │ MCP Server (18 tools) + Lifecycle Hooks
                                ▼
┌───────────────────────────────────────────────────────────────────┐
│  Athena SDK (src/athena/)                                         │
│  ├── 1. Memory & RAG: /start (~2K boot), hybrid search + reranker │
│  ├── 2. Problem Framing: VOI calculator, falsifier & R1-R13 gates │
│  ├── 3. Decision & Wargaming: EEV, 1/3 Kelly, Ruin, MCDA, Wargame  │
│  └── 4. Governance: Lambda risk router, ruin blocker, secret scan │
└───────────────────────────────┬───────────────────────────────────┘
                                │
                                ▼
┌───────────────────────────────────────────────────────────────────┐
│  Your Disk (Plain Markdown + JSONL receipts/ledgers — git-native) │
│  └── Optional: Supabase pgvector (cloud sync) + DuckDB (analytics)│
└───────────────────────────────────────────────────────────────────┘
Three boot modes, one compounding loop:
| Mode | Boot | Token Cost | When |
|---|---|---|---|
| Lightweight | Just chat, then /end |
~500 | Quick questions (SNIPER, Lambda < 10) |
| Standard | /start → work → /end |
~2K–10K | Daily engineering & analysis (STANDARD, Lambda 10–30) |
| Deep | /ultrastart → work → /ultraend |
~20K | High-stakes strategy & architecture (ULTRA, Lambda > 30) |
Repository Structure
Following Protocol 543 standard repository scaffold:
Athena/
├── src/athena/          # Core runtime (Memory, Intelligence/GTO, Governance, Lifecycle, Tools)
├── tests/               # Comprehensive test suites (unit, integration, red-team)
├── scripts/             # Automation, synchronization, and verification harnesses
├── docs/                # Architecture, guides, wiki sources, roadmap, and API specs
├── examples/            # Published agent workflows, case studies, protocols, and templates
├── docker/              # Sandboxed container environments
├── data/                # Active datasets and project assets (latest iteration only)
├── supabase/            # Database schemas, migrations, and vector functions
├── .agent/              # Agent workflows, skills, protocols, and configuration
├── .context/            # Persistent memory, case studies, canonical truths, and session logs
├── pyproject.toml       # Build configuration and dependency declarations
├── Makefile             # Standard task runner (test, lint, sync)
├── ARCHITECTURE.md      # Narrative system architecture and memory layout
├── CHANGELOG.md         # Release history and audit log
├── LICENSE              # MIT License
└── README.md            # Project front door
What Ships in the SDK
Athena is not just a prompt pack — it ships executable Python engines and two Model Context Protocol (MCP) servers (athena.mcp_server and athena.duckdb_mcp_server):
| Subsystem | Module / MCP Tool | What It Computes / Enforces |
|---|---|---|
| Hybrid RAG & Context Gate | mcp_server.py (smart_search, context_gate) |
Document-level RRF fusion across BM25 FTS5 + pgvector + filename headers + ONNX cross-encoder rerank; Lambda risk-tier routing (SNIPER / STANDARD / ULTRA) |
| Problem Framing & VOI Ledger | intelligence/frame_ledger.py (frame_open, frame_validate, frame_resolve, frame_status) |
Value of Information (EVI) stop-rule, falsifiable hypothesis pre-registration, R1–R13 commitment gates (loop budget, surviving contingency branch, irreversible ruin check), LUCK outcome-band gate, and Brier calibration scoring |
| Quantitative Decision Engine | intelligence/gto_engine.py (decision_screen) |
Deterministic evaluators for Expected Economic Value (eev), One-Third Kelly (kelly), Absorbing-Barrier Ruin (ruin), MCDA with ruin vetoes (mcda), Decision Monte Carlo (decision-mc), Scenario Robustness (robustness), Barbell (barbell), and SHA-256 receipts (.athena/decision_receipts.jsonl) |
| Adversarial Wargaming Engine | intelligence/wargame.py (athena-wargame) |
Two-turn sequential Blue vs. Red game trees with intra-turn path-dependent trough ruin, Red best-response optimization, and tamper-evident run receipts (.athena/wargame_runs.jsonl) |
| Local Analytical SQL | duckdb_mcp_server.py (query, profile, list_tables, export_result) |
Zero-dependency DuckDB engine for profiling and querying large CSV, JSON, and Parquet datasets without exhausting LLM context windows |
| Runtime Governance & Safety | core/governance.py, core/permissions.py, .agent/scripts/hook_*.py |
Capability permission gates, Protocol 509 crisis safety screen, 14/16 destructive command blocker, secret egress scanner, and Doom-Loop circuit breaker |
What's enforced in code vs. by prompt
Most AI-agent READMEs state every claim in the same confident voice. This one doesn't.
| Claim | Status | Evidence |
|---|---|---|
| Storage & hybrid retrieval — memories stored and surfaced when relevant | ✅ Shipped (code-enforced) |
Hybrid RAG with document-level RRF + cross-encoder rerank, hardened through logged regressions |
| Portability — Markdown and JSONL on your disk, movable across models | ✅ Shipped (structural) |
Plain files on disk — inspect the repo |
| Quantitative decision screening & wargaming — EEV, 1/3 Kelly, Ruin, MCDA, 2-turn game trees | ✅ Shipped (code-available) |
gto_engine.py & wargame.py emit SHA-256 receipts (107 tests); Stop hook blocks unreceipted numeric engine claims |
Pre-registered problem framing — VOI stop-rule, R1–R13 commitment & falsifier gates |
✅ Shipped (code-available) |
frame_ledger.py validates falsifiers, loop budgets, and Brier calibration (57 tests) |
| Governed autonomy — hooks block destructive commands, ungrounded claims, and secrets | ✅ Shipped (partial) | Ruin check blocks 14/16 destructive commands; 2 shell bypasses are known and tracked |
| Compounding personalization — session 2,000 recalls session 5 | 🟡 N=1 evidence | 2,100+ sessions, 428 active protocols, and 627 case studies by the author; no multi-user study |
| Anti-sycophancy — personalization doesn't silently increase agreement | 🟡 Partial mitigation | Code-enforced meta-awareness gate (Claude Code hook); agent-discretion in hookless IDEs — see honest limits |
Why publish this table? Because the failure mode of this product category is self-mythologizing — describing aspirations in the present tense. Athena's own convention (Epistemic Status) requires labeling every mechanism as
code-enforced,code-available,agent-discretion, oraspirational. This table is that convention applied to the README.
Measured, Not Claimed
# Run the test suite (including frame_ledger and gto_engine red-team suites)
pytest tests/ -v --tb=short

# Screen a decision quantitatively (EEV / 1/3 Kelly / Ruin / MCDA / Monte Carlo)
python -m athena.intelligence.gto_engine --action mcda --help

# Adjudicate a 2-turn adversarial wargame with path-dependent trough ruin screening
python -m athena.intelligence.wargame --help

# Validate a pre-registered problem frame against R1-R13 commitment gates
python -m athena.intelligence.frame_ledger calibrate

# Run the local KV cache & TTFT benchmark (Ollama / llama.cpp)
python scripts/benchmark_kv_cache.py --model qwen2.5-coder:14b

# Run the retrieval evaluator yourself (requires Supabase keys)
python examples/scripts/evaluator.py --gold-set .agent/eval/gold_set.json
| Metric | Value | Verification Command |
|---|---|---|
| Local TTFT Scaling (2K Boot) | ~35x–50x speedup vs 32K | python scripts/benchmark_kv_cache.py |
| Retrieval Hit@5 (Strict) | 0.569 (37 / 65) | python examples/scripts/evaluator.py |
| Retrieval MRR@5 (Strict) | 0.472 | python examples/scripts/evaluator.py |
| Retrieval Hit@5 (Lenient) | 0.892 (deprecated) | Partial substring match (inflated) |
| Unit & Red-Team Tests | 710+ passed (100%) | pytest tests/ |
| Secret Leaks (1,248+ commits) | 0 detected | Gitleaks + privacy_scan.py in CI |
| Code Quality & Lints | 0 ruff findings | ruff check src/ |
Anti-Goodhart Invariant: Why did our reported Hit@5 shift from 0.89 to 0.57? Lenient substring matchers count partial word overlaps as "hits," inflating benchmark scores by ~36% without improving retrieval. We killed the lenient matcher because vanity metrics mask regressions. See the full breakdown: Anti-Goodhart Benchmarking in RAG.
Agent Compatibility
| IDE | Config file | Tested |
|---|---|---|
| Claude Code | CLAUDE.md |
✅ |
| Antigravity | AGENTS.md |
✅ |
| Cursor | .cursor/rules.md |
✅ |
| Gemini CLI | .gemini/AGENTS.md |
✅ |
| VS Code + Copilot | .vscode/settings.json |
✅ |
| Kilo Code | .kilocode/rules/athena.md |
✅ |
| Roo Code | .roo/rules/athena.md |
✅ |
Documentation
| Doc | What it covers |
|---|---|
| Getting Started | Install, configure, first session |
| Your First Session | 20-minute guided tutorial |
| How It Works | 4-pillar architecture, search pipeline, and decision gates |
| Why Athena? | Philosophy, problem classification, use cases, cost analysis |
| Engineering Depth | Technical deep dives and honest limits |
| CLI Reference | All commands |
| FAQ | Common questions |
| Safety | Limitations and responsible use |
| Changelog | Release history |
Contributing
PRs welcome. Please read CONTRIBUTING.md first.
The codebase uses ruff for linting, pytest for tests, and CI must pass before merge.
MIT License · Contributing · Safety · Security · Code of Conduct
Built and battle-tested solo across 2,100+ sessions by Winston Koh.
Clone it. Boot it. Make it yours.
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found