super-video-agent
Health Uyari
- License — License: NOASSERTION
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Low visibility — Only 8 GitHub stars
Code Basarisiz
- network request — Outbound network request in skills/super-video-agent/examples/3d-round-plush-cast/soft-body/wobble.js
- process.env — Environment variable access in skills/super-video-agent/scripts/assets.mjs
- fs.rmSync — Destructive file system operation in skills/super-video-agent/scripts/audio-edit.mjs
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Free, source-available Claude Code skill that draws narrated videos in code: YouTube Shorts, explainers, 3D flights. Install in two commands.
Super Video Agent
English | 한국어
Give Claude Opus 5.5 a PDF, an essay or a topic, and get back a narrated film in your own cloned
voice: a YouTube Short, a 16:9 explainer, a square feed post or a 3D flight. Every frame is drawn in
code, and after the render you can swap one voice line, one scene or one language without touching
the rest. Super Video Agent is a Claude Code plugin that works the way the code-drawn films Reddit
shared in September 2026 were made, plus what those films did not have: read-out rules and a
pronunciation dictionary for any language, edits after the render that leave the rest of the film
alone, any frame size and format, a four-session pipeline tuned for cost, and a sound-effect library
cued from the script.
Measured on a real job, three 10-page basketball scouting PDFs → an 88-second short:
script $4.05, script review $1.75, film $16.34. That's about $22 and one hour of model time. Voice
synthesis ran locally with no API cost.
Gallery
We use this skill to take on one hard challenge at a time, and each one upgrades the skill for
the films that come after it.
| Date | Challenge | Film | What the skill gained |
|---|---|---|---|
| 2026-09-29 | 3D flight. A 40-second YouTube Short: one continuous camera flight from a phone screen, over a night city, down an undersea cable, into a data center and a GPU chip, and back to the phone as the answer appears. Drawn entirely in code with Three.js/WebGL, no video or image model. | 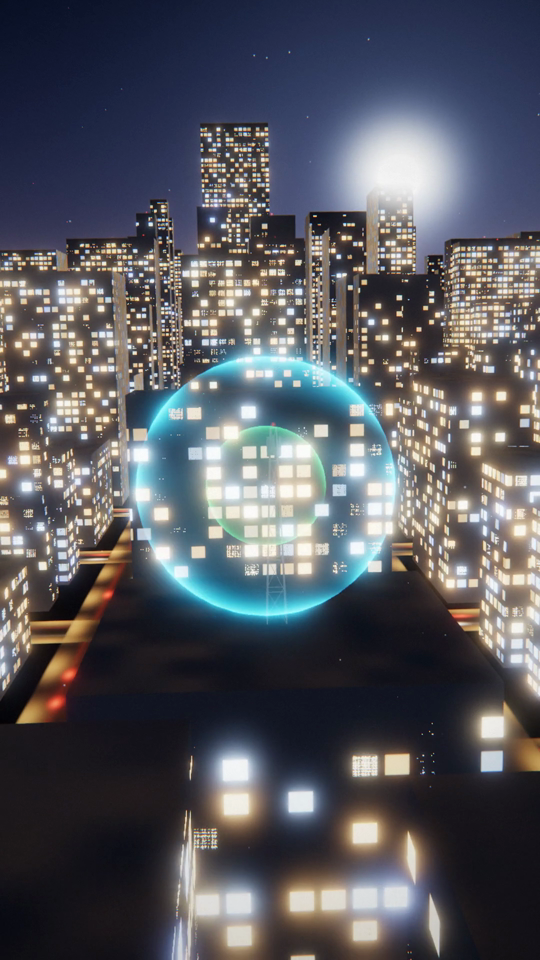 ▶ English (MP4, 7.5 MB) · Korean |
A --3d scaffold for WebGL films (references/3d.md). A byte-exact WebGL capture (gl.readPixels + putImageData), so the determinism check holds on a CPU-only headless renderer. One picture render shared by both languages (dub.mjs). Voice and caption fixes after the render. An opening and ending attached for upload (join.mjs). |
Use
Install it first (Install). Then, in Claude Code with Opus 5.5, run the skill and say what you want:
/super-video-agent Make a YouTube Short from this PDF. Use my voice from me.wav (transcript: "…").
Installed as a plugin, the command shows up as /super-video-agent:super-video-agent; type/super-video-agent and pick it from the list. You can also skip the command: asking for a video
in plain words starts the skill too.
The skill first asks whether to follow the Shorts formula (hook first, fast lines, a banded frame with a fixed hook title) or free style, plus the frame size and length if it can't infer them. If you hand it a finished
script or storyboard, it asks whether to use it as written or rework it.
3D films
Say "3D" and the skill takes the 3D path by itself:
/super-video-agent Show what happens after you press Enter on an AI prompt, in 3D like a video game
Already have Blender? The agent tests a small render and uses it for new 3D films if it works.
Otherwise, it uses the built-in Three.js workflow. You do not need to install Blender.
Three.js is not bundled; the agent installs it into your reel when that path is used.
An explicit renderer choice takes precedence, and existing films keep their renderer.
Details: references/3d.md.
Adding image and video models
The default needs no image or video model: every frame is drawn in code. When you want more on
screen — a photo-real background, a product shot, a few seconds of generated motion — name the tool
and the shot in the same message.
The request below is an example only. Swap in the tools and routes you use; the skill does not
ship with or default to any of them.
/super-video-agent Make a 60-second promo from this deck. Generate the opening background with
Codex image generation, and a 5-second product clip with Seedance through browser-use.
Say how to reach each tool (a CLI, an API key, or a browser you are logged in to), or generate the
files yourself and hand them over. Either way, generated media is material: the
skill composes each scene around it and records every file's source and license in FILM.md.
Why
In September 2026, Reddit filled up with films Claude Opus 5.5 made entirely in code, like a train
journey in risograph style, an SNES anime battle, and a stick-man YouTube Short. The prompts were short. The model picked its own tools and checked
its own renders.
We tried it for our own channel and hit the same three walls every time:
- Timing drifts. Scenes timed by estimate miss the narration by seconds once a real voice reads the script.
- Voices misread. Numbers, names and English words come out wrong, and you only notice after the render.
- Every fix is a full re-render. Changing one line meant regenerating the voice and the whole film.
So we built Super Video Agent: a skill that gets past those three walls and leaves the model free
to design each film.
Key features
Super Video Agent keeps the model's freedom (no templates for the look unless you bring one) and
adds five things the model cannot do by itself:
- Read-out rules for every language: the voice says numbers, names and English words right the first time.
- Fix only what changed, after the render: swap one line, one scene or one language; the rest stays.
- Any frame, any format, your own template: Shorts, 16:9, square, 3D, series episodes.
- Four stages, four sessions, tuned effort: about $22 for an 88-second film.
- Sound effects cued from the script: placed on the word, scored for fit.
1. Read-out rules for every language
A synthetic voice reads the spelling, and no language is spoken exactly as it is spelled.
Super Video Agent writes the spoken form into the script before any voice is made. It works in
any language the voice engine speaks: a common checklist covers numbers, units, names and
acronyms everywhere, and languages with their own rule file get the sounds their spelling hides.
A paid TTS service may not need this. But with these rules, a low-cost or local TTS library
often gets it right too.
| Language | Written | Spoken (say) |
Rule |
|---|---|---|---|
| English | Opus 5.5, $16.34 |
Opus five point five, sixteen dollars thirty-four | versions and money said in words |
| Korean | 4.4, 6월 |
사쩜사, 유월 | decimal point said [쩜]; fixed month forms |
| Japanese | 3本, 6本 |
さんぼん, ろっぽん | counters change sound |
| Chinese | 2个, 27.3% |
两个, 百分之二十七点三 | 两 before counters; percent order flips |
A wrong reading quoted on purpose ("not X but Y") is spelled as it sounds too, because voice
models quietly correct common misreadings.
For words the spelling can't carry, a pronunciation dictionary in plan.json supports three
fixes: respell the word in the language's own script, give its IPA (International Phonetic Alphabet — the pronunciation symbols dictionaries use) to engines that read SSML (Speech Synthesis Markup Language)<phoneme> tags, or swap the word. One entry covers every line that uses the word; captions
keep the original spelling.
"pronounce": { "Nguyen": { "say": "Win", "ipa": "ˈŋwiən" } }
Every generated line is then transcribed back with speech-to-text. Only a gross miss is
regenerated — more than half of the line wrong, or a take under 70% or over 140% of the line's
length — because STT has its own error on names and homophones. A pronunciation fix keeps the
line's time slot, so the film does not re-render.
(references/readout.md, scripts/lib/pronounce.mjs, scripts/lib/stt-compare.mjs, scripts/voice.mjs --lines)
2. Fix only what changed, after the render
A rendered film is not locked. Each piece of it can be swapped on its own: a narration line, a
caption, a scene, a language, the opening or the ending. Nothing else moves, so the parts you
already approved stay exactly as they were.
| You want to change | What runs | What stays |
|---|---|---|
| One narration line: a word, the tone, a misread | voice.mjs --lines <id> re-records it. Silence at both ends is trimmed and the take is fitted into the old slot, up to 1.2× speed |
the picture and every other line |
| Caption wording or where a line breaks | edit plan.json (a | sets the break), then run dub.mjs again on a picture-first film |
the picture |
| One scene | render.mjs --only <shot> renders that shot and splices it into the film |
every other shot |
| A second language | dub.mjs --lang <code> lays that language's voice and captions over the same picture |
the picture, rendered once |
| Room to breathe between a language's lines | dub.mjs --min-gap <sec> slows only the slots where a line runs into the next, picture and effects together, until the gap reaches <sec>; the voice keeps its speed |
the voice, the first and last frames, every other language |
| An opening and an ending for upload | join.mjs attaches them and reports loudness, click risk and frame match at each join |
the body film |
Measured on the 3D film in the gallery: one full render took 11–20 minutes. After review, eight
voice and caption fixes went in (a changed word, a question whose ending had to rise, a one-word
caption left alone on its line) without rendering the 3D picture again. A 2D film re-renders only
the changed shots, in minutes.
(scripts/voice.mjs, scripts/dub.mjs, scripts/render.mjs, scripts/join.mjs)
For existing recordings, follow the audio editing guide: adjust pauses and tempo locally, then replace narration without rendering the picture again.
3. Any frame, any format, your own template
- Any frame size. Four sizes come ready with one flag: 9:16 (Shorts, Reels, TikTok), 16:9
(YouTube, slides), 1:1 and 4:5 (feed posts). Any other size works too, because the renderer uses
the width and height the page declares. - Any look. Pick the Shorts formula (hook first, fast lines, a banded frame with a fixed
title), free style (the model designs the look for this film), or bring your own template:
a layout, brand colors and fonts, a series title card. The skill builds every scene inside it. - Any kind of film. A narrated explainer from a PDF or an article, a promo from a deck, a 3D
film in WebGL (new-reel.mjs --3d), a series episode with its own opening and ending, and
language versions that share one picture. - It keeps getting better. We pick a harder film on purpose each time and fold what it took
back into the skill. The 3D path, one render for two languages, and the edits after the render
above all came from the 3D challenge in the gallery.
4. Four stages, four sessions, tuned effort
Each stage reads only the files the previous one left, so each runs in a fresh session with its
own effort level. Measured on the 88-second film:
| Stage | Output | Effort | Cost |
|---|---|---|---|
| Script | plan.json, FILM.md (facts with sources) |
xhigh | $4.05 |
| Review | locked plan.json after six passes |
low | $1.75 |
| Voice | voice/ with measured timings.json |
low | $0 (local) |
| Film | reel.html, out/final-<timestamp>.mp4 |
xhigh | $16.34 |
"Effort" is Claude's setting for how long the model thinks before it answers, from low tomax. More effort costs more and takes longer, so it only pays where the work needs it.
To see where it matters, we wrote the script for the same film at every effort level and checked
every number in it against the source PDFs:
| Effort | Cost | Time | Number errors vs. source |
|---|---|---|---|
| low | $2.21 | 2m35s | 0 |
| medium | $2.13 | 1m57s | 0 |
| high | $3.40 | 6m11s | 0 |
| xhigh | $4.05 | 6m05s | 0 |
| max | $8.04 | 23m14s | 0 |
- Every level got the facts right, so a cheaper level is a safe choice for the script when cost
matters.maxcost about four timesmediumand took twelve times as long. - The review stage runs at
lowand still caught two things the script session missed: a line
that could be read two ways, and a unit that the voice would have said twice.
Details: the "Four stages, four sessions" section of SKILL.md.
5. Sound effects cued from the script
A "ding" as the list starts, a drum hit on the punchline: these small sounds keep a Short alive,
and placing them by hand in an editor is slow. Here the model places them while it writes the
script.
- You keep a sound library. A folder of your own effect files (and short reaction clips),
with acatalog.jsonthat says what each one is and whether you may use it commercially. - The model picks the sound for each line. It searches the library by keyword and pins each
sound to a moment in that line: its start, its end, or a specific word ("on the word right"). - The renderer mixes it in at exactly that moment. Each sound is trimmed to length, faded
out, and leveled so a loud file does not drown the voice. A short video clip plays frame by
frame on the same timeline.
Licenses are checked for you: a file not marked for commercial use is left out of a public film
unless you allow it. No sound files ship with this repo, since most sound packs carry their own
terms.
You don't need a library to have sound. The skill makes its own effects in code
(scripts/engine/reel-audio.js): click, type, thud, whoosh, pop, tick, ding and pluck, built
from noise and oscillators while the film renders. No files, no licenses to check, and the same
cue always makes the same sound, so a re-render matches.
(scripts/assets.mjs, references/pipeline.md, "Asset library")
Every effect is then scored for fit: does it match the size, material and speed of what happens
on screen, and does it belong to this film's world? Each sound is measured first (length, peak,
attack, brightness, pitch trend), then judged by TypeSafe AI's Jev when TYPESAFE_API_KEY is set
(pass at 0.8 of 1), or by the current model from a scoring sheet. A sound that fails is redesigned
for this film, up to three rounds.
(scripts/sfx-cards.mjs, references/sound.md §7)
Also in the box
Voice
- The voice comes first, and the picture follows it. The narration is made and measured
before any scene exists.voice/timings.jsonrecords when every line and word starts, and
every scene is timed from it, so a caption never runs ahead of the voice
(scripts/voice.mjs). - Your own voice, or any engine. Clone your voice from a 5–15 s recording with Qwen3-TTS on
your own computer, at no API cost. Or use Fish Audio, ElevenLabs, Typecast, MeloTTS, recordings you made
yourself. Fish Audio (S2) and ElevenLabs (v3/v4) also take delivery marks such as{confident}
or{pause}in a line's spoken text, translated into each model's own tags; the caption never shows them. - Every line is heard back. After the voice is made, speech-to-text listens to each line
and compares it with the script. A line that came out wrong, cut short, or clipped at the end is
flagged and made again. - Clean line endings. Local voice models often clip the last syllable. The skill has the
voice say a short word after each line, like a clapper between takes, and cuts in the pause
before it, so each line ends naturally. - Pick the tone by ear. Before the whole narration is made, the skill can record the opening
line in two to four tones (voice.mjs --takes) and show them side by side. The one you pick
(--pick) becomes the tone for every line.
Script
- Narration that flows. Each line gets its own pause: short when the next line continues the
thought, long at a scene change. Sentences end so they connect, and commas are kept for
emphasis, so the voice does not sound read off a page. - Five review passes before any voice. Facts against the source, story, spoken wording,
read-out, and a final read-through. The voice is made once, after the script is locked.
Picture
- The same frame every time. Each page draws a frame from the time alone (
seek(t)), so the
same moment always gives the same pixels. Previews, re-renders and checks all agree. - Text clear of the app buttons. Captions stay out of the areas where Shorts and TikTok put
their buttons and titles (x 80–888, y 200–1470 at 1080×1920). Pictures still fill the whole
frame. - Captions that break where you read. Captions split at punctuation first, then into rows of
even length, and a one-word leftover joins its neighbor. A|in the script sets a break by
hand; the voice never reads it.
Checks and output
- The film checks itself. After rendering,
scripts/review.mjsmakes a contact sheet and
checks for frozen frames, text that spills out of its box, loudness, sound effects that miss
their moment, and silent gaps. You get numbers, plus the timestamps worth listening to. - Every render is kept. Each render gets its own timestamped file, and
out/final.mp4
always points to the newest one. A player that has the film open is never broken by a new
render, and you can compare versions.
Install
Requires Node 22+, FFmpeg on PATH, and a Chromium for Playwright.
The skill
As a Claude Code plugin:
/plugin marketplace add ww-w-ai/marketplace
/plugin install super-video-agent@ww-w-ai
On first use the skill installs its Node dependency and Chromium into its own folder
(node scripts/setup.mjs), then checks FFmpeg.
As a Codex plugin:
codex plugin marketplace add ww-w-ai/marketplace
codex plugin add super-video-agent@ww-w-ai
To update, run codex plugin marketplace upgrade ww-w-ai, then the same add command again.
As a standalone skill (Claude Code or Codex):
git clone https://github.com/ww-w-ai/super-video-agent /tmp/super-video-agent
cp -R /tmp/super-video-agent/skills/super-video-agent ~/.claude/skills/super-video-agent   # Codex: ~/.codex/skills/super-video-agent
node ~/.claude/skills/super-video-agent/scripts/setup.mjs
Voice and the speech check
The voice runs on your own computer, and you pick the model. The default is Qwen3-TTS 1.7B
(Apache-2.0), which clones a voice from a 5–15 s recording with no API cost. Set it up once:
Make a Python environment (Python 3.12, as Qwen3-TTS recommends) and install the voice model
and the speech check:python3.12 -m venv ~/.venvs/sva ~/.venvs/sva/bin/pip install -U qwen-tts faster-whisperTell the skill where it is. Add these to
~/.zshenv(or your shell's profile):export SVA_QWEN3_PYTHON=~/.venvs/sva/bin/python export SVA_STT_PYTHON=~/.venvs/sva/bin/pythonThe first film downloads the weights from Hugging Face: about 4.2 GB for the 1.7B voice model
and 0.5 GB for the speech check (small).Record 5–15 s of your own voice that ends on a finished sentence, and write down exactly what
you said. The skill uses the two asmeta.voice.refAudioandrefText.
Pick the voice model:
| Model | Download | Choose it for |
|---|---|---|
Qwen/Qwen3-TTS-12Hz-1.7B-Base (default) |
about 4.2 GB | the recommended voice: clearer words, fewer slurred endings |
Qwen/Qwen3-TTS-12Hz-0.6B-Base |
about 2.3 GB | a smaller machine, or quicker drafts |
Set it for every film with SVA_QWEN3_MODEL, or for one film with meta.voice.model. On a
machine with an NVIDIA GPU, set SVA_QWEN3_DEVICE=cuda.
The speech check listens to each line after the voice is made and catches only the ones that
came out badly wrong, so the default small model (about 0.5 GB, downloaded once on first use)
is enough. Without SVA_STT_PYTHON the check is skipped with a notice.
Every variable the skill reads:
| Variable | Points to | Needed for |
|---|---|---|
SVA_QWEN3_PYTHON |
a Python where import qwen_tts works (Qwen3-TTS) |
voice cloning (default provider) |
SVA_STT_PYTHON |
a Python with faster-whisper installed |
the voice check (skipped with a notice if unset) |
SVA_MELO_PYTHON |
a Python with MeloTTS | optional provider |
SVA_FISH_DIR |
a folder holding fish-speech/ (the checkout) and .venv-tts/ (its Python) |
optional |
SVA_QWEN3_DEVICE, SVA_FISH_DEVICE |
mps (default), cuda or cpu |
non-Apple machines |
SVA_QWEN3_MODEL |
a Qwen3-TTS model id (default Qwen/Qwen3-TTS-12Hz-1.7B-Base) |
another voice model on every film; meta.voice.model in a plan still wins |
SVA_STT_MODEL |
a faster-whisper model name (default small) |
optional |
ELEVENLABS_API_KEY, ELEVENLABS_VOICE_ID |
your ElevenLabs key and voice | optional hosted provider |
TYPECAST_API_KEY, TYPECAST_VOICE_ID |
your Typecast API key and voice (tc_…) |
optional hosted provider |
FISH_AUDIO_API_KEY (or FISH_API_KEY), FISH_AUDIO_VOICE_ID |
your Fish Audio key and voice | optional hosted provider |
SAY_VOICE |
a macOS say voice name (default Yuna) |
macOS only, with --provider say |
Set up at least one voice provider above; with none, the voice step stops and lists what to set. Clone only your own voice, or one you have permission to use.
Where to set them — all of these are environment variables. Pick the one place that fits your setup:
| Setup | Where |
|---|---|
| Claude Code (any OS) | env in ~/.claude/settings.json: {"env": {"ELEVENLABS_API_KEY": "..."}} |
| macOS · Linux, zsh | export ELEVENLABS_API_KEY="..." in ~/.zshenv |
| Linux, bash | export ELEVENLABS_API_KEY="..." in ~/.bashrc |
| Windows (PowerShell) | run setx ELEVENLABS_API_KEY "...", then open a new terminal |
Which voice model
We made our films with three voice models. The default is Qwen3-TTS on your own computer,
because it costs nothing to run. Fish Audio and ElevenLabs are well-known paid services that run
on their servers; they return a line in seconds. With no --provider, voice.mjs tries Qwen3-TTS
first, then Fish Audio, then ElevenLabs, then Typecast, depending on what you set up, and prints which one ran.
| Model | Where it runs | Cost | Speed | Set up with |
|---|---|---|---|---|
| Qwen3-TTS 1.7B (default) | your computer | free | slowest | SVA_QWEN3_PYTHON + a 5–15 s recording of your voice |
| Fish Audio | Fish Audio servers | paid; the pro model is free until 2026-11-30 | seconds per line | FISH_AUDIO_API_KEY, FISH_AUDIO_VOICE_ID |
| ElevenLabs | ElevenLabs servers | paid per character | seconds per line | ELEVENLABS_API_KEY, ELEVENLABS_VOICE_ID |
| Typecast | Typecast servers | paid per character | seconds per line | TYPECAST_API_KEY, TYPECAST_VOICE_ID |
Qwen3-TTS (default, local)
- What it is. An open voice model from the Qwen team. It copies a voice from one short
recording, so the film speaks in your voice. - What you install. The repository holds only the code that calls it. You install the
qwen-ttspackage yourself (see Install above), and the model downloads from Hugging Face on
the first film: about 4.2 GB for 1.7B, about 2.3 GB for 0.6B. - Speed. 10 short lines (20 s of speech) took 2 min 54 s on an Apple Silicon Mac, including
loading the model and the speech-to-text check. Plan for minutes, not seconds. - The recording decides the result. Use 5–15 s of clean speech that ends on a finished
sentence, plus its exact transcript. A recording cut mid-word put that syllable onto the start
of 11 of 21 generated lines; cutting it on a sentence end fixed it. - 1.7B over 0.6B. 1.7B spoke clearer words with fewer slurred endings. Use 0.6B on a smaller
machine or for quick drafts. - Weak spots. Its delivery is even; it does not act out emotions. In our test it never raised
the end of a question (0 of 10).
Fish Audio
- What it is. A hosted voice service known for natural, lively delivery. Use one of its
library voices, or clone your own voice with an API key. - Price. The pro model is free until 2026-11-30 as
s2.1-pro-free, and the skill uses it by
default. - Delivery tags. It follows tone marks such as
{confident}or{excited}. Fish reads a
Short flat unless told otherwise, so 9:16 films on Fish get{confident}by default. - Weak spot. It rarely raised the end of a question: 3 of 23 measurable takes, and no tag we tried
changed that.
ElevenLabs
- What it is. A hosted voice service with many stock voices and instant cloning. The default
model iseleven_multilingual_v2;eleven_v3is more expressive. - Price. Billed per character, audio tags included. Library voices work through the API only
on a paid plan. - Key permissions. A restricted API key needs the text-to-speech permission. Listing voices
also needsvoices_read; without it, put a stock voice id inELEVENLABS_VOICE_ID. - Strengths. It raised question endings most often (below), and it returns its own word
timings. Its English stock voice "Sarah" can read Korean; we did not judge the accent by ear. - One read for the whole film.
voice.mjssends every line in one request and cuts it per
line, so the voice does not shift between lines. Sent one line at a time,eleven_v3cut off
the end of a Korean line in 9 of 18 takes; read in one request ending in[pause], 0 of 25.
Typecast
- What it is. A hosted voice service with many character voices. The model is
ssfm-v30. - Price. Billed per character.
- Emotion. Each line gets one emotion preset instead of inline tags. A line ending in
?or!getstoneup, which raises its end;meta.voice.emotionsets one preset for every line. - Word timings. It returns its own word times.
Question endings: what we measured
In English and Korean, a yes/no question usually sounds like a question only when its last
syllable goes up ("Is it ready?↗"). A voice model often reads it flat or falling, so it sounds
like a statement. We recorded two Korean questions, "다음 토큰은 뭘까?" and
"여기가 엔비디아 세상인가?", several times with each model and measured whether the last
syllable was more than 2 semitones higher than the one before it.
| Model | Takes whose last syllable went up |
|---|---|
ElevenLabs eleven_v3 |
5 of 10 |
ElevenLabs eleven_multilingual_v2 |
4 of 10 |
Fish Audio s2.1-pro-free |
3 of 23 measurable |
| Qwen3-TTS 1.7B | 0 of 10 |
A falling end is not always wrong: questions with what/where/why often fall. So the skill does not
judge it. Listen, and re-record only that line (voice.mjs --lines <id>) until one sounds right.
Full method, per-take numbers and limits: Question intonation and read-out accuracy in four TTS models.
Fonts
Every word in the film is drawn by the page itself, so the font travels with the film as a file.
Each new reel copies its font files into assets/fonts/, and the preview and the final render
use those same files.
- Default: Pretendard. Free under the SIL Open
Font License, with Korean and Latin in one family. Install it once on your computer; every new
reel then copies it in automatically. A Korean handwriting font you have installed is copied
too, for hand-written notes. - Any font you like. Tell the model which one ("titles in Noto Serif", "use my brand font").
It copies that font file into the reel and uses it. Pick a font whose license allows use in
videos. - No font installed. Text falls back to the system sans-serif. The film still renders, but
the look depends on the fonts of the machine it was made on.
Sound library (optional)
Put your own effect files and a catalog.json in library/ next to scripts/, or pointSVA_ASSET_LIB to a folder elsewhere (format: references/pipeline.md, "Asset library").
Without a library, the effects the skill makes in code still play.
Credits
Super Video Agent started from what these Reddit posts showed Claude Opus 5.5 can do when it is
given a premise and room to work. Thank you to their makers.
| Post | What it showed |
|---|---|
| Opus 5.5 is insane at making videos — u/Silver-Chipmunk7744, r/singularity | A full SNES-style anime battle rendered from code, from a one-page story prompt |
| I asked Opus 5.5 to create an animation on how LLMs work — u/cody-fifth-door, r/claude | A narrated parody explainer from a 23-word prompt |
| Opus 5.5 One Shot Video Generation — u/AzorAhai1TK, r/ClaudeAI | Picture and sound both programmed, tools left to the model |
| Opus 5.5 made six films, each one drawn under the rules of an old physical medium — u/datathe1st, r/ClaudeAI | A written notebook per film, kept between passes |
| I gave Claude Opus 5.5 an MP3 and a few lines of art direction. It built a 50-shot painted music video entirely in code, with no video or image model — u/DigitalDaydreamers1, r/singularity | A 50-shot music video steered by short notes |
| Opus 5.5 creates a train journey drawn entirely in JavaScript — u/mshort3, r/ClaudeAI | A film drawn as a pure function of time, reviewed on contact sheets |
| Opus 5.5 made this whole YouTube Short in one HTML file. No images, no video editor, just code — u/quitpornio, r/ClaudeCode | Voice first: measured line times drive the picture |
Runtime dependencies and their licenses are listed in THIRD-PARTY-NOTICES.md.
Built by DubDubDub Corp. · Super Video Agent License 1.0: use and modify it to make your own videos, commercial ones included. Reselling it, bundling it into paid courses or products, hosting it as a service, and redistributing it are not allowed. Versions 1.3.3 and earlier remain under Apache-2.0.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi