multi-model-orchestra
Health Gecti
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 22 GitHub stars
Code Gecti
- Code scan — Scanned 12 files during light audit, no dangerous patterns found
Permissions Gecti
- Permissions — No dangerous permissions requested
Bu listing icin henuz AI raporu yok.
Route coding work across Claude, GPT (Codex), Kimi and DeepSeek: one runner with hard status gates, worktree-only writes, a blind council and a benchmark.
multi-model-orchestra
English · Türkçe · Українська · 简体中文 · 繁體中文 · Deutsch · Français · Español · 日本語 · 한국어 · Azərbaycanca · Oʻzbekcha · Қазақша · Кыргызча · Türkmençe · Qırımtatarca · ئۇيغۇرچە · Português · Tiếng Việt
Let one expensive model conduct, cheaper models play, and check every answer before it's used.
Skills for Claude Code (or anything that reads SKILL.md files) that hand work to Claude Opus, Sonnet and Haiku, OpenAI GPT, Kimi and DeepSeek.
The main agent plans, writes the briefs and reviews; the other models do the work, and nothing they return is trusted until it passes a check.




Install · otomode · Council · Benchmark · FAQ
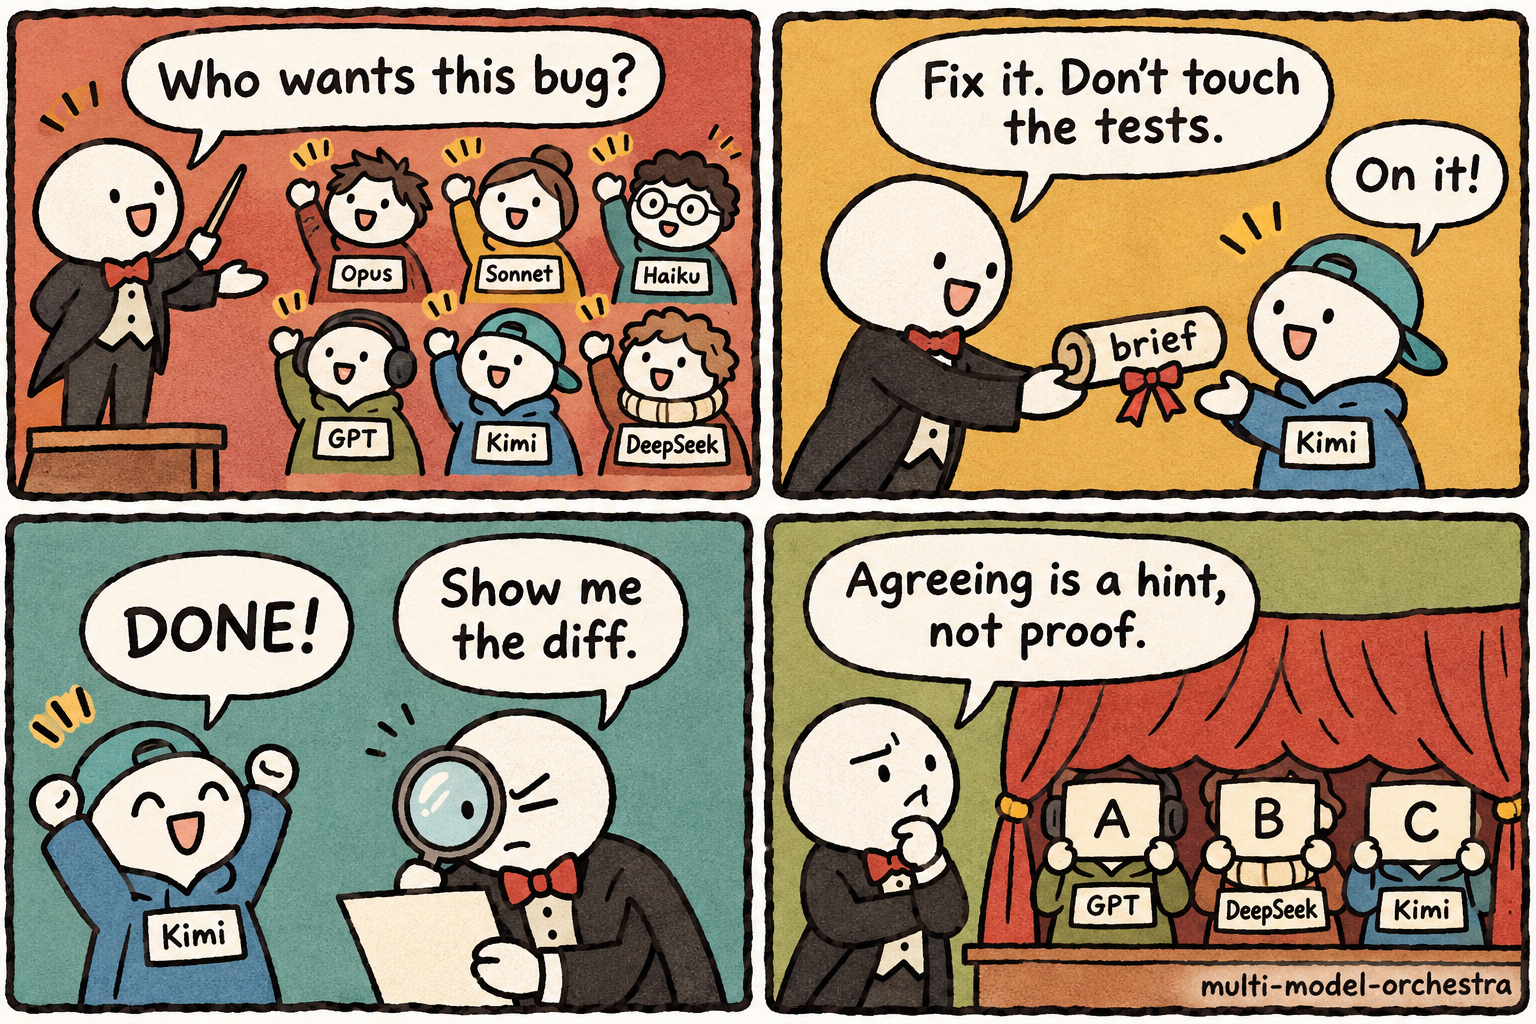
The conductor hands out the parts, asks for the diff, and calls a blind council when the answer is a judgment call.
|
Route Each job goes to the cheapest tier that can pass its check, by difficulty. A lane moves up only after it fails the check, not on a hunch. |
Brief Each tier gets the brief it works best with: goal and constraints for Opus, numbered steps and exact files for the cheaper lanes. A lane sees only the brief, so it is written for a stranger. |
Runmmo-run is the one runner for every provider, with hard status codes and a timeout on every call. Writing lanes run only in a git worktree, never in your main checkout.
|
Check The conductor runs the check itself and reads the whole diff. A lane's "done" is a claim, not a result. |
Real numbers
| What | Result | Details |
|---|---|---|
A/B: orchestra skill vs. plain "use subagents" (claude-fable-5-2, 2 runs per arm) |
Same quality: all four runs 36/36 hidden tests, visible tests intact (the task set is too easy to separate quality) | benchmark.md |
| A/B cost per run | Skill $1.88 vs $3.21 mean, about 40% less, ranges do not overlap. The saving comes from sub-agents running on Sonnet instead of inheriting Fable. No speed gain (3.2 vs 3.5 min) | RESULTS.md |
| A/B limits | A one-line "use Sonnet subagents" prompt was not tested and may capture most of the saving. total_cost_usd is a list-price proxy, not plan usage |
faq.md |
| Lane benchmark, 2026-11-21 (bugfix with hidden tests, exact-answer reasoning, 60-line bulk labeling) | Kimi k3.1-pro, DeepSeek v4-pro, DeepSeek flash and gpt-5.6-terra: 6/6, 3/3, 60/60. gpt-6-luna: 6/6, 0/3, 58/60. gpt-6.1-sol and gpt-6-astra: ~6/6, ~3/3, ~60/60 (estimated: not served on that plan, scores from the 2026-11-11 run) | benchmark.md |
| otomode, one 5-hour unattended run | 13 tasks, one commit each; weekly limit went from 25% to 31%; 6 prompts denied and logged. One run, not a benchmark | otomode.md |
[!WARNING]
Briefs leave your machine: every lane sends its brief to that model's vendor. Never put secrets, tokens or
personal data in a brief. otomode's hook denies prompts and refuses delete, deploy, push and send commands,
but it matches patterns: it is a guard rail, not a sandbox.
Quick start
Paste this into your agent and let it install the skills:
Install multi-model-orchestra: clone https://github.com/yatuk/multi-model-orchestra,
run ./install.sh --link in it, then run ~/.claude/skills/orchestra/scripts/mmo-preflight
and tell me which lanes are ready.
Or yourself. Needs bash, git, timeout and Python 3; on Windows, use Git Bash.
git clone https://github.com/yatuk/multi-model-orchestra
cd multi-model-orchestra
./install.sh --link          # into ~/.claude/skills; --dir PATH for a project
~/.claude/skills/orchestra/scripts/mmo-preflight
mmo-preflight never calls a model. It tells you which lanes exist on this machine, so the conductor routes around the missing ones.
For otomode, run python ~/.claude/skills/otomode/scripts/otomode.py install once to register its hook.
Then ask, for example:
- "Fix the failing tests in
internal/auth. Follow the orchestra skill." - "Get a second opinion from GPT on this migration plan before I merge it."
- "Ask the council: should we split this service or keep one process?"
- "otomode 6h: these four tasks, each checked with
go test ./...."
Works with
| Tool | Used for | Needs |
|---|---|---|
| Claude Code | The skills, and the Claude Opus / Sonnet / Haiku tiers as sub-agents | Skills installed in ~/.claude/skills (or a project's .claude/skills); nothing else |
| Codex CLI | GPT lanes | codex on PATH, signed in with ChatGPT |
| Kimi Code CLI | Kimi and DeepSeek lanes | kimi on PATH, signed in; for DeepSeek, a deepseek/* model in Kimi Code's config.toml |
GPT model ids: on some ChatGPT plans the Codex CLI now serves different ids (for example gpt-5.6-terra or gpt-6-luna)
and rejects others. The skill files name the defaults; smoke-test the ids your plan accepts before routing work there
(mmo-preflight to see the CLIs, then a one-line mmo-run brief per id). See Model ids.
More
- How it works: routing table, runner, status codes, safety model, council.
- otomode: unattended runs while you are away.
- Benchmark: lane benchmark and the A/B test, with how to run both.
- FAQ: including how this compares to similar projects.
- Write-up (Turkish): Fable 5.2 ile orkestra ve otomode, on running an expensive main-loop model as the conductor and leaving it to work unattended.
Layout
skills/
  orchestra/   SKILL.md, scripts/ (mmo-run, mmo-council, mmo-preflight, mmo_extract.py), templates/
  council/     chatgpt-lane/  kimi-lane/  deepseek-lane/
  otomode/     SKILL.md, scripts/ (otomode.py: switch, hook, usage gate; statusline.py)
bench/         run.sh, grade.py, tasks/, results/; ab/ for the A/B test
docs/          how-it-works, otomode, benchmark, faq, translations
License
MIT, see LICENSE. The README illustration was generated with gpt-image-2 through the Codex CLI.
Yorumlar (0)
Yorum birakmak icin giris yap.
Yorum birakSonuc bulunamadi