tokenminning
Health Pass
- License — License: MIT
- Description — Repository has a description
- Active repo — Last push 0 days ago
- Community trust — 36 GitHub stars
Code Fail
- child_process — Shell command execution capability in tools/doc-convert/convert.js
- execSync — Synchronous shell command execution in tools/doc-convert/convert.js
- exec() — Shell command execution in tools/doc-convert/convert.js
- fs module — File system access in tools/doc-convert/convert.js
Permissions Pass
- Permissions — No dangerous permissions requested
No AI report is available for this listing yet.
A context engineering philosophy for maximizing intelligence per token in AI systems.
Tokenminning
Maximize intelligence per token
Not by minimizing tokens, but by delivering the right context at the right time


Case Studies • Principles • Techniques • Results • Contributing • Articles
🆕 What's New: v0.9.3 — a smaller README (case studies as one table), an Evidence column on every results table, and a runnable Quick Start. Previously: v0.9.2; full changelog.
Why Tokenminning?
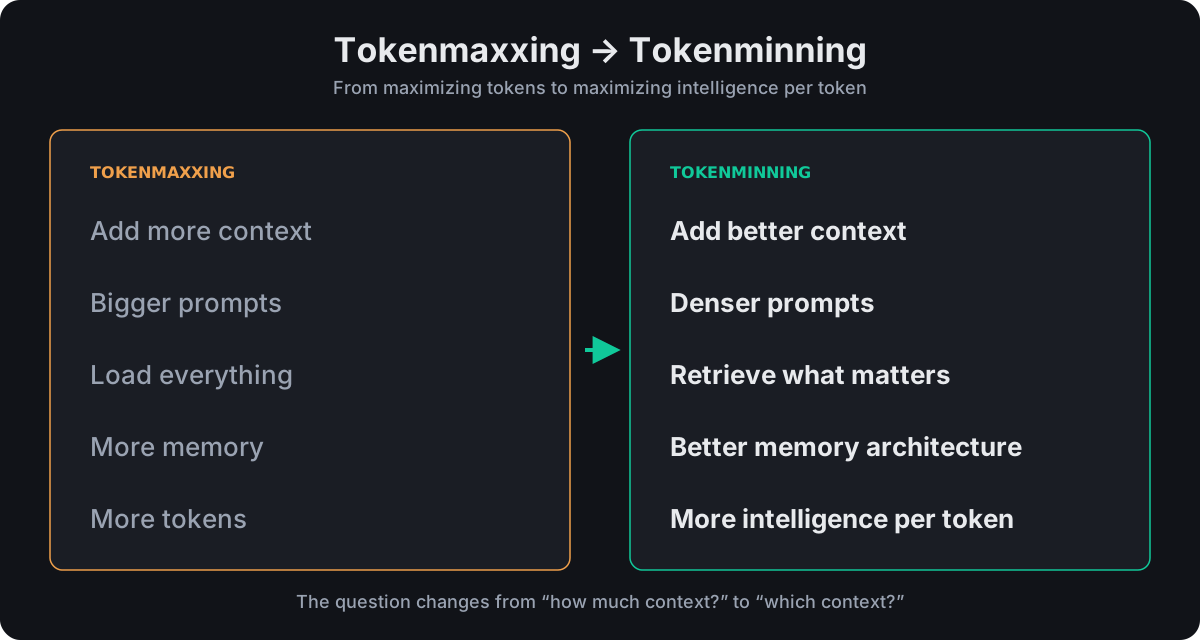
| Tokenmaxxing | Tokenminning |
|---|---|
| "How do I give the model more context?" | "How do I give the model the right context?" |
| Add more context | Add better context |
| Bigger prompts | Denser prompts |
| Load everything | Retrieve what matters |
| More memory | Better memory architecture |
| More tokens | More intelligence per token |
Tokenminning is not: minimizing tokens to cut costs, aggressively shortening prompts, removing useful context, or avoiding large context windows.
Tokenminning is: improving information density, eliminating context debt, and designing systems where the right context arrives at the right time.
Quick Start
Tokenminning is a design philosophy; the tools here measure it on your own setup. Three steps, about five minutes:
git clone https://github.com/zwolf25/tokenminning && cd tokenminning

# 1. Audit what loads every session (stdlib Python, read-only, never writes)
python3 tools/lint/claude-md-lint.py

# 2. Read the output: resident size in chars and ~tokens, dangling @imports, duplicated blocks.
# 3. Apply one trim (delete a duplicate or an @import you never use), then re-run step 1.
Then: read the Principles, pick a Case Study, and apply one technique.
Principles
| # | Principle | One-Liner |
|---|---|---|
| 1 | 🔍 Retrieve, don't preload | Supply relevance on demand |
| 2 | 🗜️ Compress, don't repeat | Cut redundant instructions & history |
| 3 | 📋 Structure, don't narrate | Prefer structured data over prose |
| 4 | 🎯 Spend tokens where reasoning matters | Allocate budget to high-value thinking |
| 5 | 🏗️ Design systems, not prompts | Architecture (retrieval, tools, memory) drives savings |
| 6 | ⚙️ Optimize context, not complexity | "What does the model need right now?" |
| 7 | 🧹 Eliminate context debt continuously | Audit memories, routing, config like production code |
flowchart TD
    Q{"Need this information?"}
    Q -- NO --> N["Don't load it."]
    Q -- YES --> Y["Read the live source."]
    Q -- MAYBE --> G{"Grep first"}
    G -- Found --> F["Read only matches."]
    G -- "Not found" --> A["Ask the human or fail fast."]
    classDef ok fill:#12241F,stroke:#10C99A,color:#E8EAED
    classDef bad fill:#2A1E14,stroke:#F0A04B,color:#E8EAED
    class F,Y ok
    class N,A bad
Default: don't load unless justified.
[!NOTE]
These principles emerged from production Second Brain workflows at ServiceChannel, not theoretical speculation.
Techniques
| Technique | Description | Case Study |
|---|---|---|
| Stub Pattern | Replace full clones with summary + source-path pointers |
Second Brain |
| Grep-before-read | Never read a folder wholesale; search first | Config Audit |
| Escalation Ladder | Level 1: local cache → Level 2: stub lookup → Level 3: on-demand read | [All] |
| Compaction | Keep active context ≤ 15K tokens | Wiki Pipeline |
| Thin Routers | Startup instructions = behavior/routing only; retrieve details on demand | Config Audit |
| Trim Resident Context | Remove always-loaded text that is injected elsewhere, duplicated, or rarely needed | CLAUDE.md Trim · Try it |
| Single Source of Truth | Store durable knowledge once, reference everywhere | [All] |
| Deterministic Pre-filter | Run a zero-dep script first; model only judges flagged items | Wiki Lint · Try it · Visual Validation · Try it |
| Zero-Token Content Processing | Convert binary (PDF/DOCX/VTT) locally via subprocess; model only sees file path | Doc Pipeline · Try it |
| Schema-Enforced Extraction | Rigid output schema (7 categories) forces structured data; no prose summaries | Doc Pipeline |
| Failure-Mode Driven Escalation | Each ladder level has documented failure mode → next level; no guessing | Web Ladder |
| Contract-Driven Tool Discipline | Versioned SKILL.md contracts enforce token rules, routing, composition by design | Skill System |
Real-World Results
Evidence column: measured = counted from real data; estimated = derived with stated assumptions; single run = one observation. The data behind these is private; each case study states its method and caveats, and B-002 in the backlog tracks making them re-checkable.
| Metric | Before | After | Change | Evidence |
|---|---|---|---|---|
| Second Brain wiki words | 211K | 28K | 87% ↓ | measured |
| Wiki pipeline cost/run | $50+ (11 agents) | $15–25 (2–3 agents) | ~70% ↓ cost, 80% ↓ agents | single run |
| CLAUDE.md size | ~48.6 KB | 34.4 KB | 29% ↓ (~3,500 tokens/session) | measured (bytes); tokens estimated |
| Stale sync clones | 66% | 0% | 100% eliminated | measured |
| RTK adoption gap | 94% commands bypassed | → upstream fix | 1.5M tokens/30d recovered | estimated |
| Wiki lint pre-filter (this repo) | 8.5M tokens/run | ~1.2M est. | ~86% ↓ | estimated |
| Long-session cost per turn | 2.1x at 250k context, 4–5x at 500k+ | /compact at ~250k |
59% of one model's spend was above the knee | measured (rate ratios assumed) |
| Always-loaded CLAUDE.md context | 32,157 B (~8K tokens) | 25,365 B | ~21% ↓ (~1.7K tokens/session, chars/4 est.) | measured (bytes); tokens estimated |
| Untracked spend | 44% of spend in sessions with no task id | /todos <id> at session start |
Cost now has an owner | measured |
[!NOTE]
These come from production Second Brain workflows, not synthetic benchmarks, except Case Study 10, which is labeled synthetic.
Tooling Measured Results
Production skill stack figures (from Case Studies 6–8). Token counts for these are author estimates; the case studies do not state a sample size.
| Workflow | Before (Prompt-Based) | After (Skill System) | Improvement | Evidence |
|---|---|---|---|---|
| 50-page PDF → Wiki | ~80K tokens, manual | ~500 tokens, automated | 99.4% ↓ | estimated |
| 2-hr VTT → Decisions | ~45K tokens, error-prone | ~300 tokens, schema-enforced | 99.3% ↓ | estimated |
| Competitor research (10 sites) | ~500K tokens, ad-hoc | ~5K tokens, ladder + cache | 99% ↓ | estimated |
| Market research report | $50+, 11 agents, manual | $15-25, 2-3 agents, pipeline | ~70% cost ↓ | single run |
| Context debt (stale clones) | 66% of files | 0% (fingerprint dedup) | Eliminated | measured |
| Prompt drift / repeated instructions | Re-prompt every task | Contract loaded once | Observed, not measured | qualitative |
| Tool usage consistency | Varies by person | Set by the skill contract | Observed, not measured | qualitative |
| New capability onboarding | Hours (re-teach via prompt) | Minutes (install → auto-routes) | Observed, not timed | qualitative |
Case Studies
One row each; the full problem, fix, result and caveats live in the linked file.
| # | Case study | Result | Links |
|---|---|---|---|
| 1 | Second Brain | 87% fewer words (211K → 28K), 66% → 0% stale clones | Read |
| 2 | RTK & LLMLingua Evaluation | Found a 1.5M tokens/30d adoption gap; kept RTK, rejected LLMLingua | Read |
| 3 | Config & Memory Audit | 29% smaller CLAUDE.md, ~3,500 tokens/session | Read · Try it |
| 4 | Wiki Pipeline | $50 → $15/run, 11 → 2–3 agents | Read |
| 5 | Wiki Lint | 90 → 13 mechanical findings, ~86% fewer tokens (estimated) | Read · Try it |
| 6 | Document Processing Pipeline | ~99% fewer tokens via local subprocesses (estimated) | Read |
| 7 | Web Scraping Escalation Ladder | 7-level fallback from API credits to free local tools | Read |
| 8 | Skill Tooling Pattern | Skills as versioned contracts; qualitative, not measured | Read |
| 9 | Honey/eso CCR Evaluation | 92% array compression; two reversals | Read |
| 10 | Pixel-Diff Screenshot Validation | 74–99% fewer tokens on 30 synthetic cases | Read |
| 11 | Derived-Document Staleness | 6 false flags silenced (~516K tokens), 2 lossy refreshes blocked | Read · Try it |
| 12 | Context-Length Threshold | ~2.1x cost per turn at 250k, ~4–5x at 500k+ | Read · Try it · Status line |
| 13 | Cost Attribution to Tasks | 44% of spend had no task id | Read · Try it |
| 14 | Trimming Always-Loaded Context | ~21% less resident context (32,157 → 25,365 B) | Read · Try it |
| 15 | Incremental Wiki Refresh | Hash gate + diff-first folding; 14 of 21 pages were noise | Read |
Technique Guides
Practical applications of tokenminning to specific systems:
| Guide | Focus |
|---|---|
Claude Code & CLAUDE.md |
Keep config focused; retrieve on demand |
| Context-Length Threshold · Try it | Measure cost per turn vs context size; compact at the knee (~250k here) |
| Skill Usage · Try it | Log skill calls; find installed skills that load every session but are never used |
| Evaluate Before Adopting · Try it | Count real retrieval misses in your transcripts before installing a search tool; ours was 0 in 3,306 messages |
| Cost Attribution to Tasks · Try it | Join transcript cost to task ids; 44% of spend was untracked |
| Context Debt | Stale, duplicated, or always-loaded context that costs tokens without paying back |
| MCP / Tool Scoping | Load capabilities only when workflow needs them |
| Memory Systems · Try it | Preserve decisions/constraints, not transcripts |
| RAG Pipelines | Rank → filter → focus; quality over quantity |
| Local Document Pipeline | Zero-token binary→markdown→structured extraction |
| Web Scraping Escalation | 7-level ladder: credits → cache → free local → browser |
| Skill System as DSNP | Versioned contracts, thin router, composable |
| All Examples Index | Quick reference for all patterns |
These are technique guides — not measured case studies. Case studies in
examples/(second-brain-system.md, etc.) show before/after metrics.
How It Works
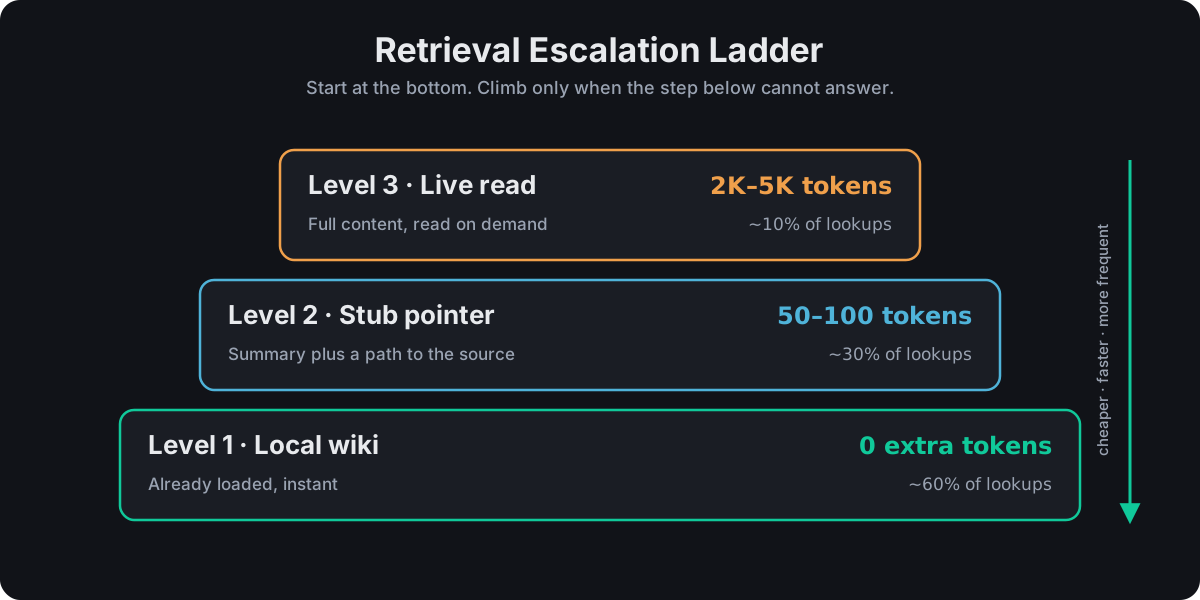
Tokenminning operates on a simple escalation ladder — the model only sees what it needs, when it needs it:
┌─────────────────────────────────────────────────────────────┐
│  LEVEL 1: LOCAL CACHE                                       │
│  Hot context, recent decisions, active task state           │
│  → Always loaded, ≤ 2K tokens                               │
├─────────────────────────────────────────────────────────────┤
│  LEVEL 2: STUB LOOKUP                                       │
│  Summary + source-path pointers to durable knowledge        │
│  → Loaded on reference, ~500 tokens each                    │
├─────────────────────────────────────────────────────────────┤
│  LEVEL 3: ON-DEMAND READ                                    │
│  Full source content retrieved only when explicitly needed  │
│  → Lazy, precise, unbounded depth                           │
└─────────────────────────────────────────────────────────────┘
The key insight: Most systems preload Level 3. Tokenminning makes Level 1 the default, Level 2 the bridge, Level 3 the exception.
flowchart LR
    subgraph B["Before: 211K words, full-body clones, high token cost"]
        direction TB
        b1["AI session"] --> b2["Read wiki 1"] --> b3["Read wiki 2"] --> b4["... Read wiki 68"] --> b5["Answer"]
    end
    subgraph A["After: 28K words, stub-first, on-demand retrieval"]
        direction TB
        a1["AI session"] --> a2["Read stub"] --> a3{"Relevant?"}
        a3 -- Yes --> a4["Read live source"] --> a5["Answer"]
        a3 -- No --> a6["Skip"] --> a5
    end
    B ~~~ A
    classDef bad fill:#2A1E14,stroke:#F0716A,color:#E8EAED
    classDef ok fill:#12241F,stroke:#10C99A,color:#E8EAED
    class b1,b2,b3,b4,b5 bad
    class a1,a2,a3,a4,a5,a6 ok
Related Projects
| Project | Description | Relation |
|---|---|---|
| RTK | Rust CLI proxy for tool-output compression (60-90% savings) | Complementary — handles command output; tokenminning handles context architecture |
| Caveman | Terse communication mode (65% fewer output tokens) | Sibling — reduces prompt verbosity; tokenminning reduces context surface |
| Ponytail | YAGNI code generation philosophy (~54% less code) | Sibling — reduces implementation bloat; tokenminning reduces context bloat |
| GPTCache | Semantic caching for LLM APIs | Different layer — caches model responses; tokenminning optimizes what reaches the model |
| Firecrawl | Web search/scrape API — search, scrape, crawl, monitor, interact | Levels 1–3 of the escalation ladder (credits, cache, scheduled monitors) |
| Scrapling | Free local HTTP + stealth browser (Cloudflare bypass) | Levels 4–5 of the ladder (credits exhausted, anti-bot pages) |
| markitdown | Universal document converter (PDF, DOCX, XLSX, PPTX, HTML, images) | doc-convert fallback engine for scanned/image-heavy formats |
| Headroom | Open-source context compression layer for AI agents (60-95% fewer tokens for JSON, 15-20% coding agents) | Complementary — compresses context that reaches the model; tokenminning selects/retrieves better context |
| Honey (honey-for-devs) | Cross-tool coding skill merging YAGNI/terse-prose modes with 3 novel pieces (ESON, CCR, honey-usage) | Sibling — CCR's array-compression idea was evaluated and partially adopted; RTK/caveman/ponytail already covered the rest (case study) |
| base (basemode) | Rust CLI — tree-sitter code graph + Claude Code hooks injecting context at session-start/prompt/tool-use | Different mechanism — graph-derived injection via hooks instead of stub pointers; no published token deltas, unverified against tokenminning's own measured-savings bar |
Contributing
We welcome real-world examples, counterexamples, benchmarks, and tool-specific patterns.
- Case studies — Add to
examples/as<kebab-name>.md - Techniques — Document patterns in
examples/too - Counterexamples — Where tokenminning doesn't apply (valuable!)
- Tool patterns — Claude Code, Cursor, Codex, Continue, etc.
See CONTRIBUTING.md for details, and BACKLOG.md for planned work.
Star History
Visual Reference
More diagrams- Context Surface: optimize what crosses the boundary into the model
- Grep Before Read: 402 files filtered to 31 reads
- Knowledge Bloat Cascade: how full clones drift into stale copies
- Second Brain cover: dormant notes versus selective retrieval
License
MIT — see LICENSE for details.
Origin
The term "tokenminning" was introduced in July 2026 as a way to describe an emerging optimization philosophy centered on maximizing intelligence per token.
Inspired by the emerging concept of tokenmaxxing: intentionally using larger context windows and more tokens to improve AI performance. Tokenminning asks the opposite question: what's the minimum context that still produces maximum reasoning?
Reviews (0)
Sign in to leave a review.
Leave a reviewNo results found